tt-rl
community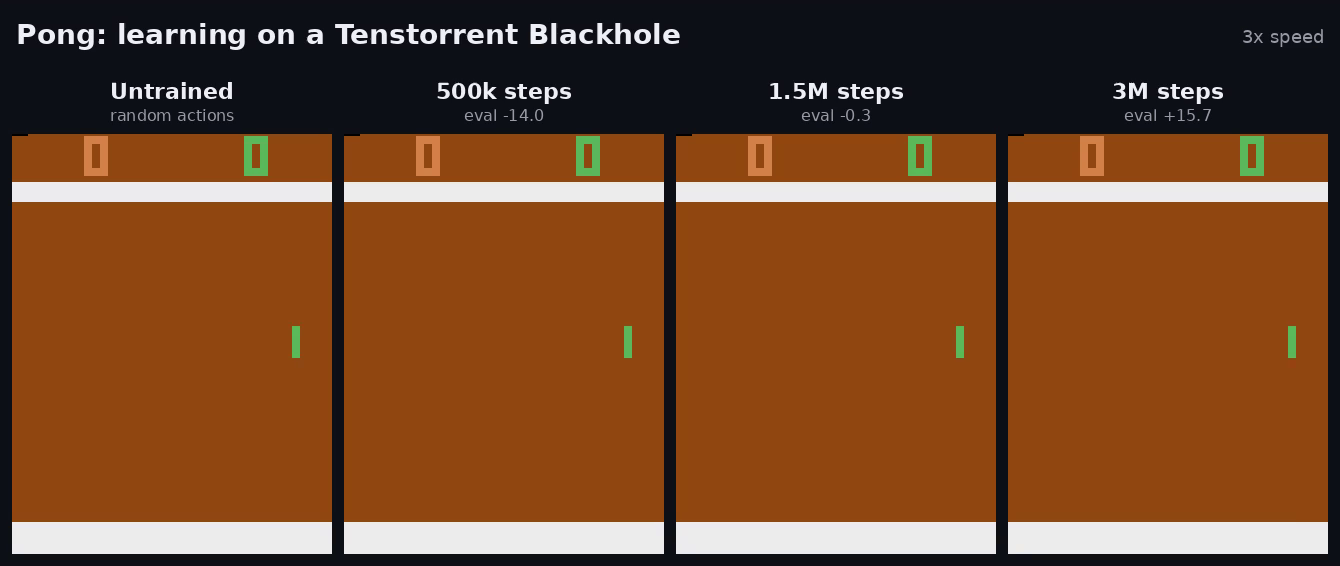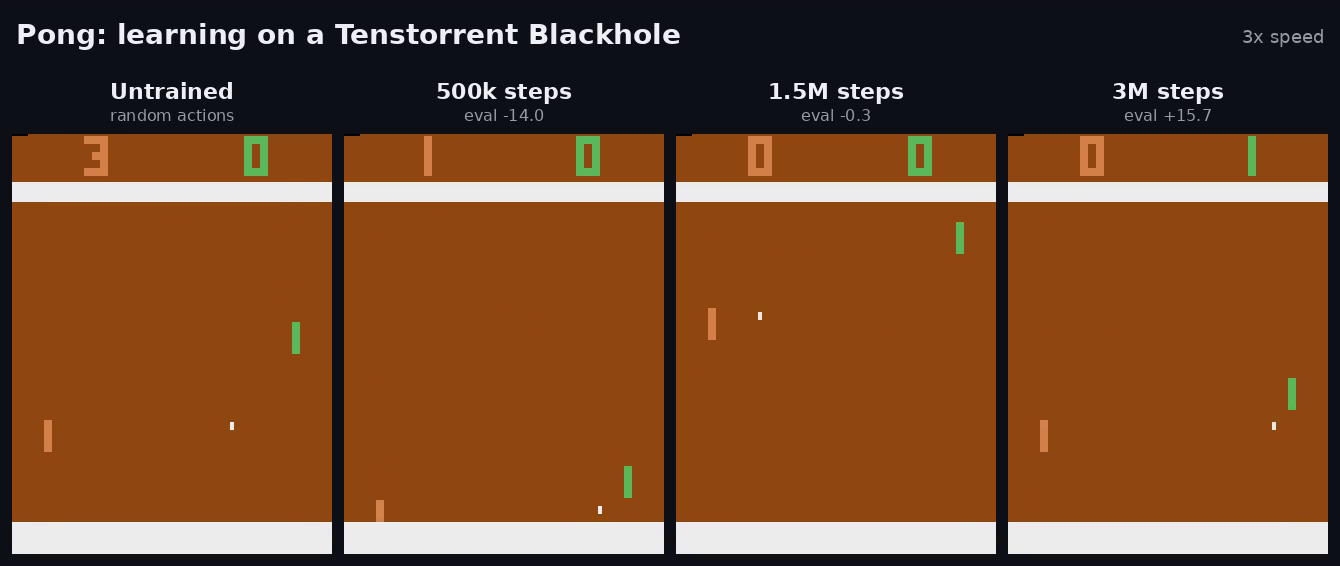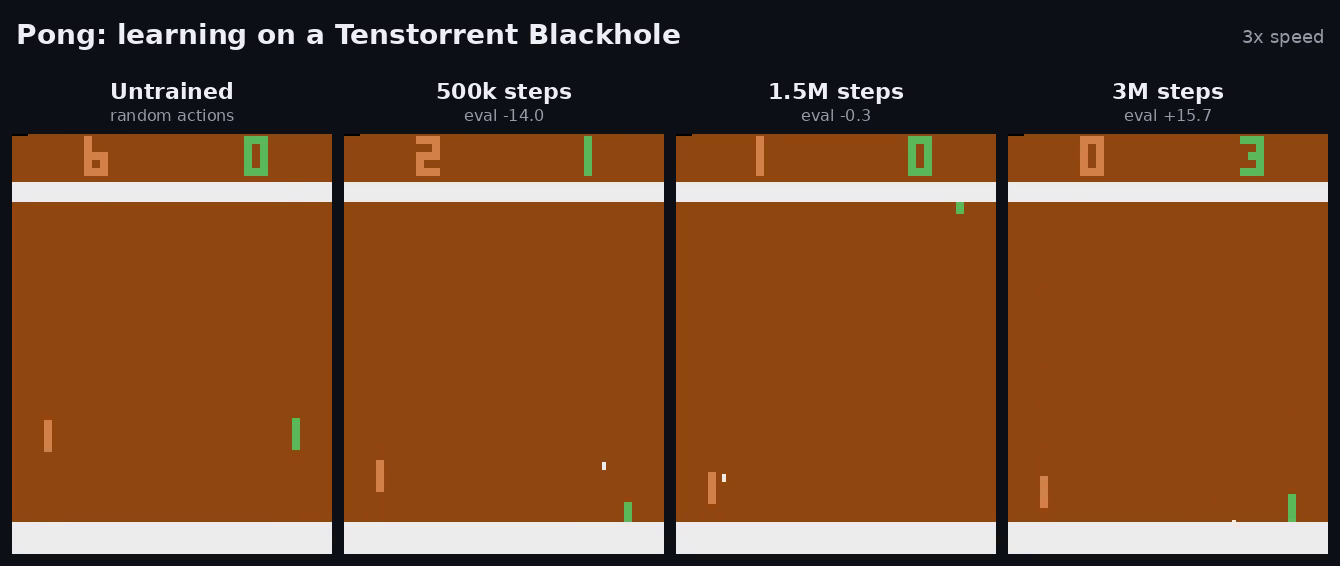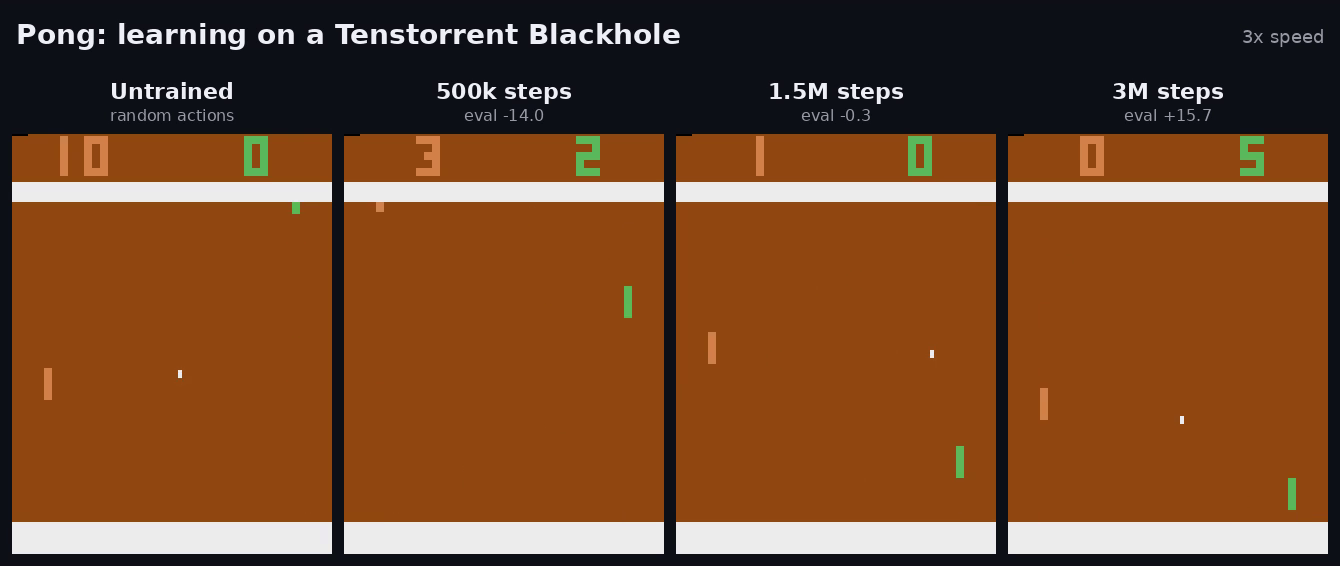
Reinforcement learning trained natively on TT-NN: the networks, gradients, Adam step and device trace all run on the chip, while environments and replay buffers stay on the host. Ships DQN, PPO and SAC with Atari and MuJoCo configs, measured Blackhole results (Pong 17.8, Breakout 144.8, Hopper 3604), data-parallel training with one replica per chip, and export of trained policies to numpy or ONNX so they run on any CPU. Developed on a TT-QuietBox with four Blackhole chips; trained weights are published on Hugging Face.
Works on
blackhole
quietbox