vllm.cpp
community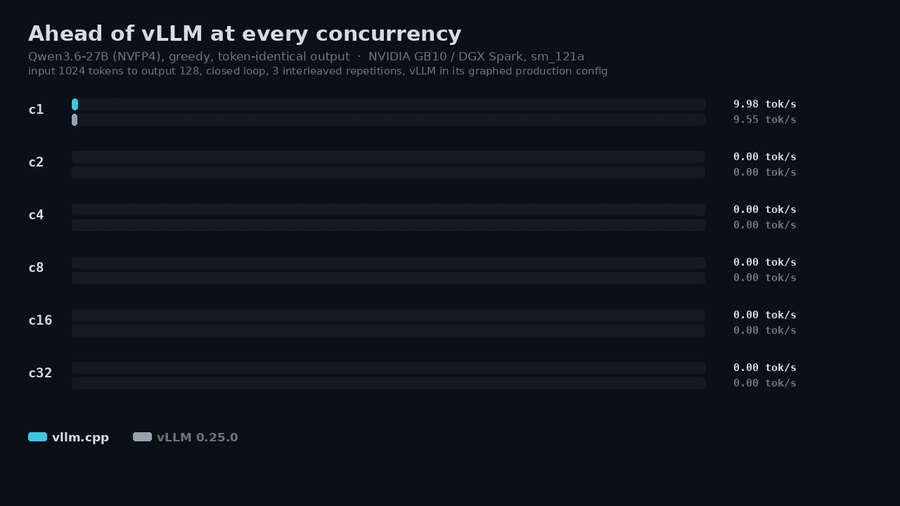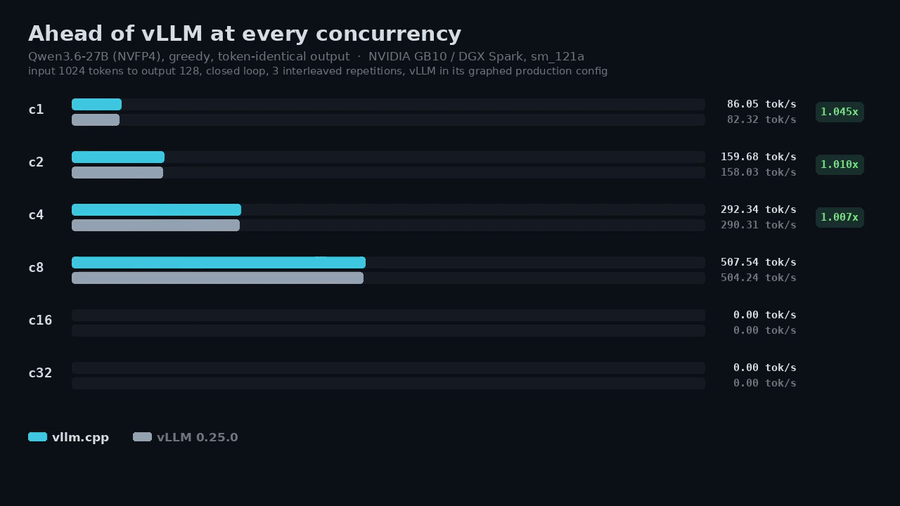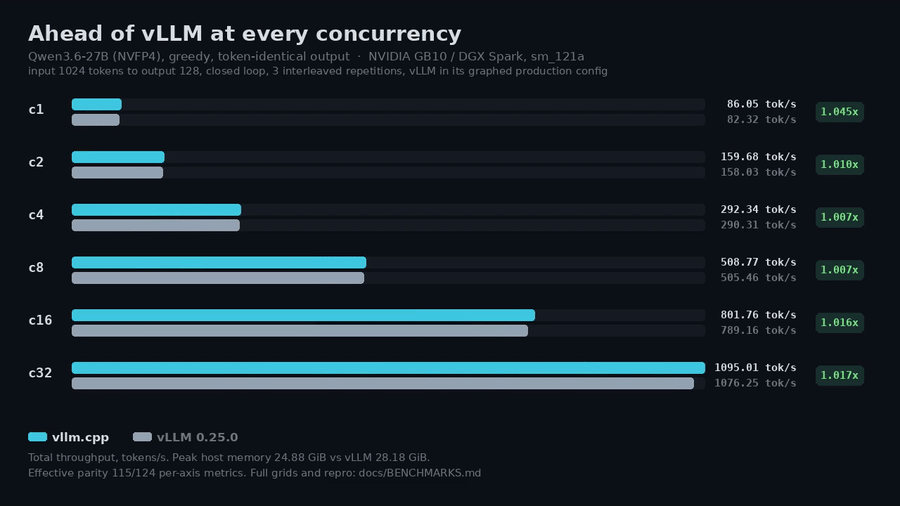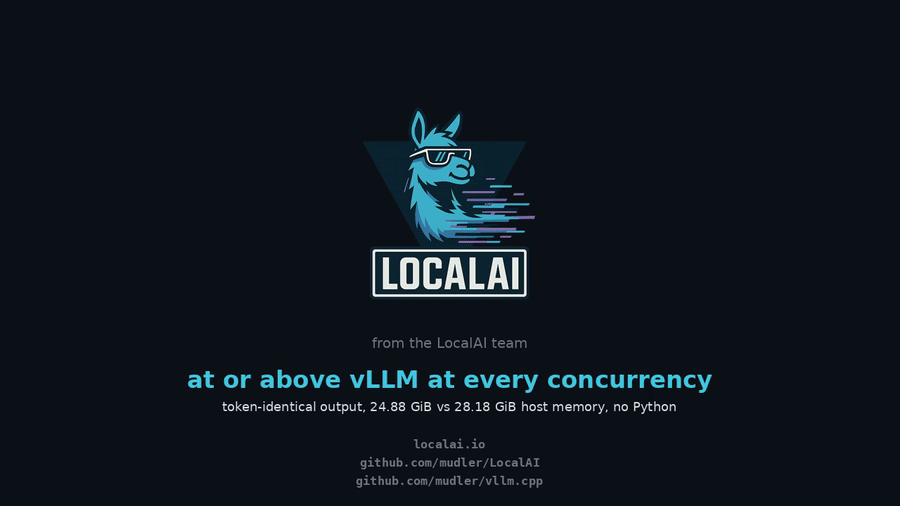
A C++ reimplementation of the vLLM engine (continuous batching, paged KV cache, GGUF loading) with CUDA, CPU, Metal, Vulkan and ROCm backends plus an opt-in Tenstorrent backend under `src/vt/tenstorrent`. The TT backend is a thin adapter over TTNN and TT-Metalium built with `-DVLLM_CPP_TENSTORRENT=ON`, adding paged attention, Qwen3.5 gated-delta-net, trace capture and quant-preserving (`keepquant`) matmul paths. Status is correctness-first on Blackhole: OPT-125m passes a strict token-exact gate, Qwen3-0.6B has committed goldens with a full rerun pending, and 27B GGUF decode is in smoke-measurement stage.
Releases
📦
vllm.cpp-0.0.2-linux-aarch64-glibc-cpu.tar.gz
📦
vllm.cpp-0.0.2-linux-aarch64-glibc-cuda-fat.tar.gz
📦
vllm.cpp-0.0.2-linux-x86_64-glibc-cpu.tar.gz
📦
vllm.cpp-0.0.2-linux-x86_64-glibc-cuda-fat.tar.gz
+4 more
+4 more
3 previous releases
v0.0.2-alpha1-ci-test
2026-08-09T08:58:19Z
v0.0.2-alpha
2026-08-05T14:22:51Z
v0.0.1-m03-parity-27b-35b
2026-07-19T22:47:24Z
Works on
blackhole