Cross-track lesson · Tinker
Your First TTNN Program
Talk to a Blackhole chip directly from Python inside the tt-metalium container: open a device, run an operation, close it.
This is the hands-on path that sits underneath tt serve: no server, no API, just your Python
talking to a chip through TTNN. Stop any model you are serving first (tt model ps, then
tt model stop <name>), because opening a device needs the chips to be free.
Open a device
This lesson pulls a tiny model, Qwen/Qwen3-0.6B, and talks to the chip directly. It is about 1.5 GB with no license gate.
First, get into the TTNN environment. On a factory QB2 there is no ~/tt-metal
checkout on the host — TT-Metalium ships as a container, and the QB2 provides a
wrapper command that starts it:
tt-metaliumThat drops you into a shell inside the container with your home directory mounted. TTNN is already on the default interpreter, so there is no venv to activate. Check it:
which python3
# → /opt/venv/bin/python3tt-metalium pulls a multi-GB
container the first time you run it. Later runs start immediately.
Now do the handshake — open a device, confirm it responds, close it:
python3 -c "
import ttnn
device = ttnn.open_device(device_id=0)
print('Device open:', device)
ttnn.close_device(device)
print('Done.')
"
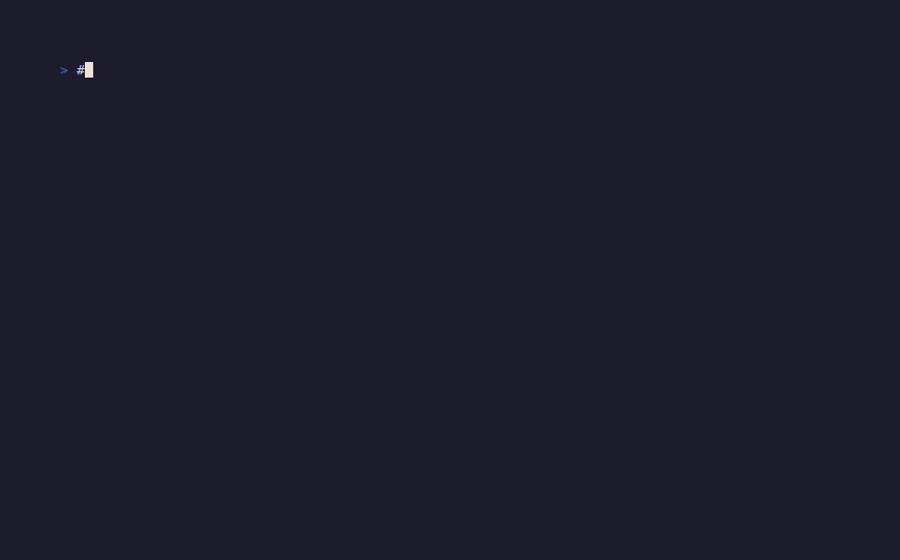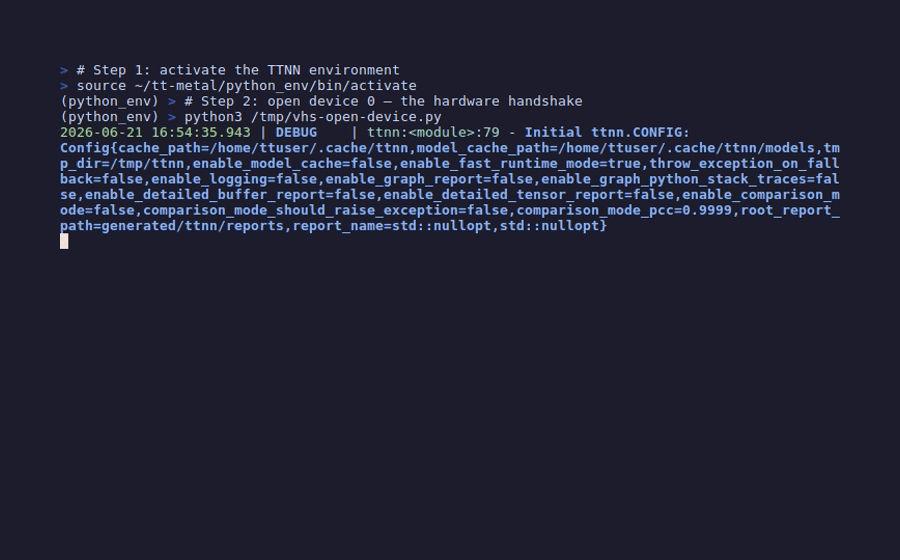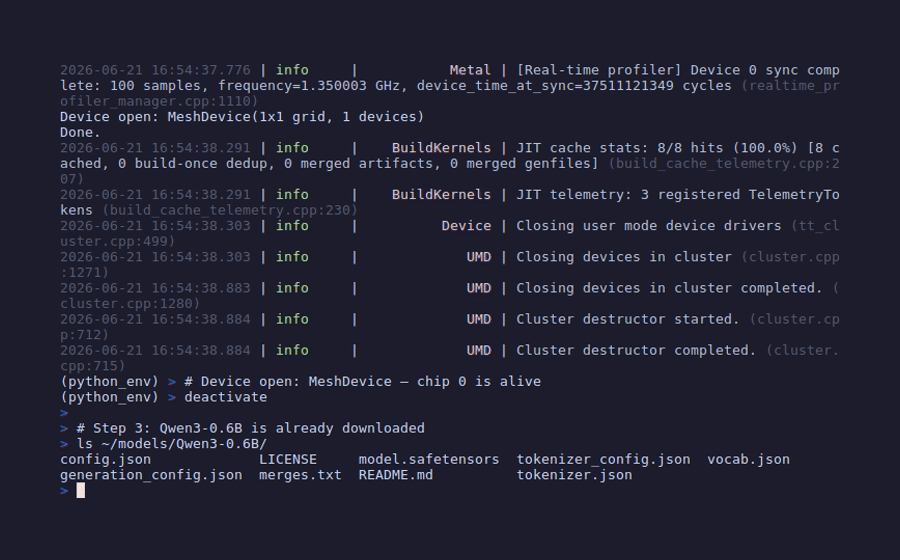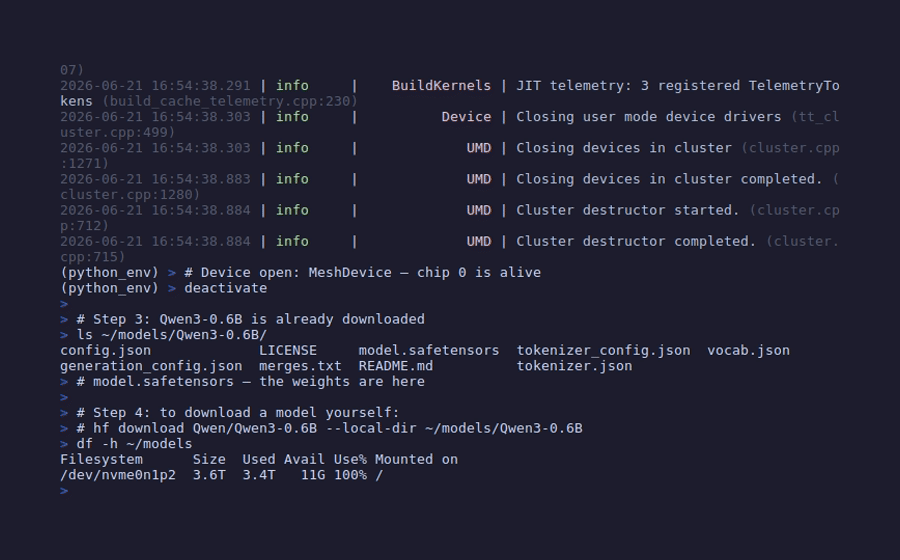
If you see Device open: without errors, chip 0 is alive and responding. Repeat with device_id=1, 2, 3 to verify all four.
ttnn.CreateDevices({0, 1, 2, 3}) — not four separate open_device() calls. Opening and closing devices individually can cause dispatch core errors on multi-chip configs.
Expected NOC address: 0x1000000000000000, but got
0x1000000040000000
. That is contention, not broken hardware — stop the deployed
model (or docker ps and stop the inference container) and try again.
Download a model
Downloading weights by hand needs the hf CLI, which is not part of the QB2’s
preinstalled stack — huggingface_hub isn’t in any environment the installer creates, so
hf isn’t on your PATH. Install it first, and install it somewhere other than
~/.tenstorrent-venv: that venv holds tt-smi and tt-flash, a factory QB2 activates it
for you in every shell, and a bad dependency resolution in there costs you the tooling you
diagnose the machine with. uv tool and pipx each give the CLI its own environment, which
is exactly what you want:
uv tool install huggingface_hub # or: pipx install huggingface_hubUbuntu 24.04 is an externally-managed Python, so a plain pip install on the host will
refuse — that refusal is the system protecting itself, not an error to force past with
--break-system-packages.
Then pull the weights (run this on the host, not inside tt-metalium):
# hf — not huggingface-cli. The command is hf.
hf download Qwen/Qwen3-0.6B --local-dir ~/models/Qwen3-0.6B
This creates ~/models/Qwen3-0.6B/ with the HuggingFace-format weights (~1.5 GB). Check your disk first:
df -h ~You need at least 3 GB free for this model alone. Larger models (Llama-3.1-8B) need 16+ GB.