Your First Model
Everything up to now was preparation. This is the part where the machine does something interesting. Four chips, waiting. One small model, about to arrive.
Running Your First Model
tt-studio, pick Qwen3-32B from the Deploy Model dropdown, click Run. The first deploy takes a few minutes (no multi-GB download — the weights are already there). You enter a Hugging Face token once — the tooling asks for one up front, not because Qwen3-32B is gated (it is Apache-2.0 and ungated). Prefer the command line? Those same weights are reachable from tt-inference-server and from plain vllm serve — see Use the Model That's Already on Your Box in the vLLM chapter.
This chapter takes the other path — the hands-on one, where you talk to a chip directly in Python and pull a tiny model down yourself. The starter is Qwen/Qwen3-0.6B — no license gate, 1.5 GB, runs on any Tenstorrent hardware.
First, get into the TTNN environment. On a factory QB2 there is no ~/tt-metal
checkout on the host — TT-Metalium ships as a container, and the QB2 provides a
wrapper command that starts it:
tt-metaliumThat drops you into a shell inside the container with your home directory mounted. TTNN is already on the default interpreter, so there is no venv to activate. Check it:
which python3
# → /opt/venv/bin/python3tt-metalium pulls a multi-GB
container the first time you run it. Later runs start immediately.
Now do the handshake — open a device, confirm it responds, close it:
python3 -c "
import ttnn
device = ttnn.open_device(device_id=0)
print('Device open:', device)
ttnn.close_device(device)
print('Done.')
"
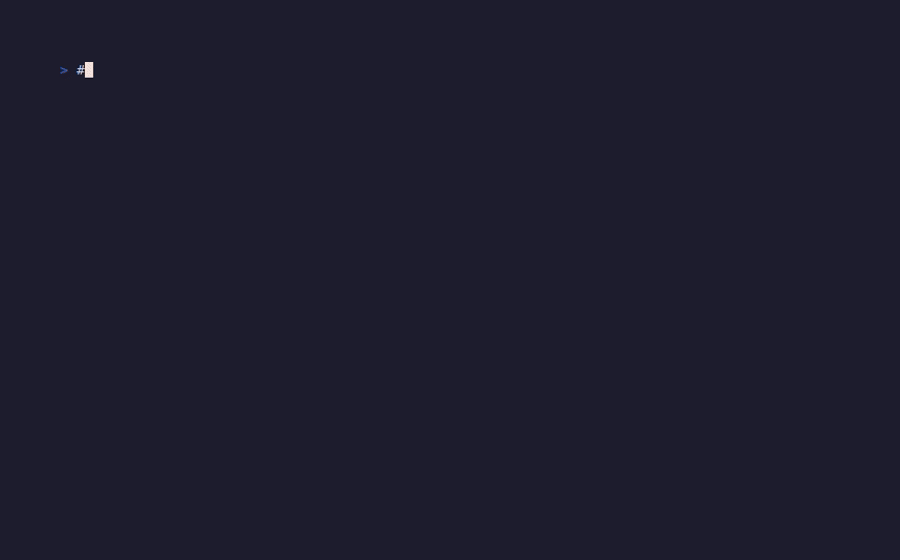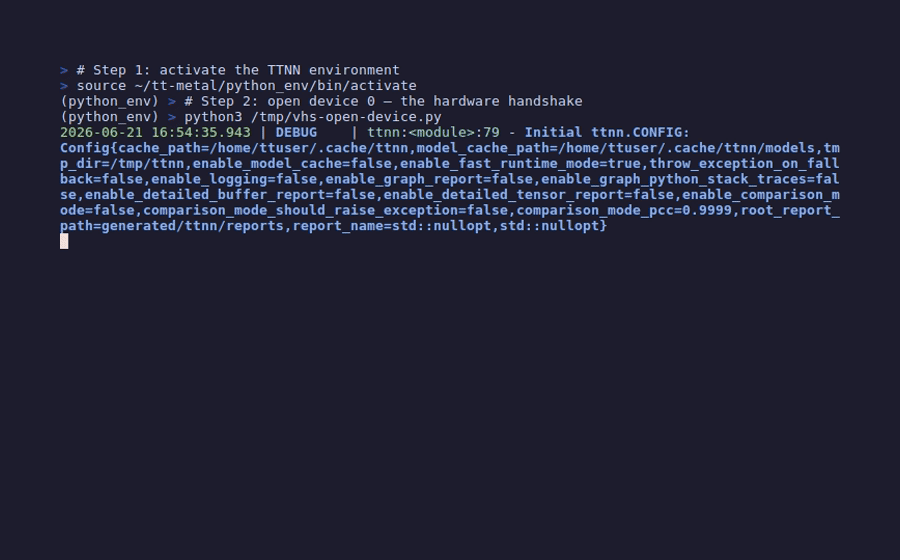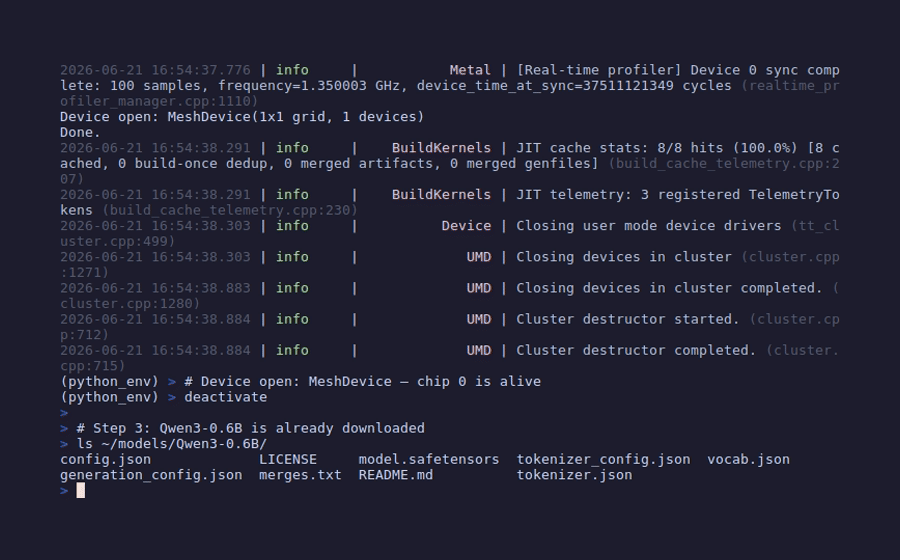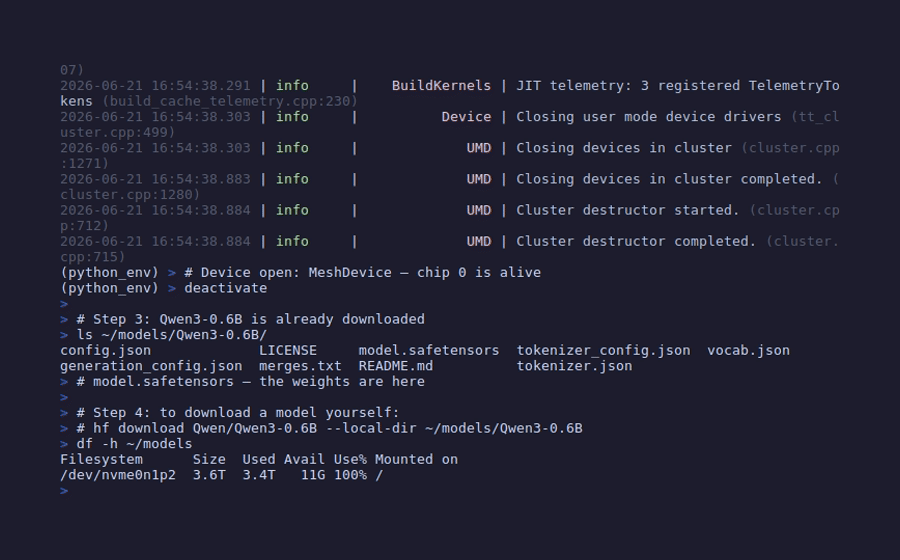
If you see Device open: without errors, chip 0 is alive and responding. Repeat with device_id=1, 2, 3 to verify all four.
ttnn.CreateDevices({0, 1, 2, 3}) — not four separate open_device() calls. Opening and closing devices individually can cause dispatch core errors on multi-chip configs.
Expected NOC address: 0x1000000000000000, but got
0x1000000040000000
. That is contention, not broken hardware — stop the deployed
model (or docker ps and stop the inference container) and try again.
Download a model
Downloading weights by hand needs the hf CLI, which is not part of the QB2’s
preinstalled stack — huggingface_hub isn’t in any environment the installer creates, so
hf isn’t on your PATH. Install it first, and install it somewhere other than
~/.tenstorrent-venv: that venv holds tt-smi and tt-flash, a factory QB2 activates it
for you in every shell, and a bad dependency resolution in there costs you the tooling you
diagnose the machine with. uv tool and pipx each give the CLI its own environment, which
is exactly what you want:
uv tool install huggingface_hub # or: pipx install huggingface_hubUbuntu 24.04 is an externally-managed Python, so a plain pip install on the host will
refuse — that refusal is the system protecting itself, not an error to force past with
--break-system-packages.
Then pull the weights (run this on the host, not inside tt-metalium):
# hf — not huggingface-cli. The command is hf.
hf download Qwen/Qwen3-0.6B --local-dir ~/models/Qwen3-0.6B
This creates ~/models/Qwen3-0.6B/ with the HuggingFace-format weights (~1.5 GB). Check your disk first:
df -h ~You need at least 3 GB free for this model alone. Larger models (Llama-3.1-8B) need 16+ GB.
What Just Happened
When that Python snippet ran without errors, the Blackhole chip opened a dispatch channel through the PCIe link, initialized its RISC-V cores, and confirmed it can receive work. Nothing computed yet. But the handshake — software to silicon — is the prerequisite for everything else.
ttnn.open_device(0) — what happens inside the chip.
Use the Model That’s Already on Your Box
Before you download another model, know what you already have. Your QB2 shipped with Qwen3-32B on disk — and not just the weights:
| What | Size | Can you re-download it? |
|---|---|---|
| The weights | ~62 GB | Yes, given time and disk |
| Compiled Blackhole kernels | ~30 GB | No |
The second row is the one to care about. Those are the model’s operations already compiled for a four-chip mesh — the work that otherwise happens the first time you serve a model, while you watch a quiet log and wonder whether it has hung. It cannot be fetched from Hugging Face because nobody publishes it; it is built against your topology. Tenstorrent pre-built it and shipped it to you.
So the case for using it isn’t that downloading is slow. It’s that a download can’t give you the kernel cache — pull the weights yourself and you still pay the compile, having thrown away the more valuable half of what shipped. You’d also be spending another ~62 GB on a disk that already holds this model once. And it is no compromise: Qwen3-32B runs a 131K context window across all four chips and serves up to 8 concurrent requests.
Confirm it arrived — the same check Tenstorrent’s ISO acceptance test runs:
du -sh ~/data/tt-cache/You want roughly 87G–91G. Much smaller or missing means the model didn’t make it onto
your box, and the rest of this section won’t work.
Give it a name you’ll remember
The weights are real Hugging Face model files, but they are not in a Hugging Face cache —
a factory QB2 has no ~/.cache/huggingface and no ~/models at all. They sit in
tt-inference-server’s storage layout, under a directory named for a build label. One symlink
puts them on the path the rest of this guide already uses, so you never type that name again:
mkdir -p ~/models
ln -s ~/data/tt-cache/volume_id_tt_transformers-Qwen3-32B-vqb2_launch/weights/Qwen3-32B \
      ~/models/Qwen3-32B
A symlink, not a copy — a copy would be another 62 GB for no benefit. Check it resolves:
ls ~/models/Qwen3-32B/config.jsonNow ~/models/Qwen3-32B sits beside the ~/models/Qwen3-0.6B you’d get from hf download,
and tools take it as an ordinary path:
This replaces the launch command near it — it is not a next step. One model owns the four
chips and port 8000 at a time, so if you already started something (the command above, or a
deploy from tt-studio), stop it before running this: Ctrl-C, or docker ps then
docker stop <id>. sudo lsof -w /dev/tenstorrent/* printing nothing means the chips are
free. Pick whichever launch you want; don’t run both.
# run.py requires HF_TOKEN whenever --docker-server is used, local weights or not.
# That is a workflow precondition, not a license gate: Qwen3-32B is Apache-2.0 and
# ungated. Omit it and you get "⛔ HF_TOKEN not set." before anything starts.
export HF_TOKEN=hf_...

python3 ~/.local/lib/tt-inference-server/run.py \
  --model Qwen3-32B \
  --tt-device p300x2 \
  --workflow server --docker-server \
  --host-weights-dir ~/models/Qwen3-32B
--host-weights-dir mounts that directory into the container read-only: your weights can’t
be modified by the server, and no second copy is made. Once it is up, the server reports the
model by its full Hugging Face repo id — query it as Qwen/Qwen3-32B, not Qwen3-32B, or
read the exact string from curl -s http://localhost:8000/v1/models. The same path works for a direct
vllm serve ~/models/Qwen3-32B with HF_MODEL=~/models/Qwen3-32B, if you have built that
environment.
Not --host-hf-cache. It’s the flag that sounds right. It reuses a Hugging Face cache —
resolving HOST_HF_HOME, then HF_HOME, then ~/.cache/huggingface — and on a factory QB2
none of those exist, so you get a fresh 62 GB download of a model you already own.
--host-hf-cache is for weights you pulled with hf download; --host-weights-dir is for
the ones that shipped. Leave HF_HOME alone too — it plays no part in reaching this model.
Serving a Model with vLLM
Already started Qwen3-32B above? Skip this section. It launches a second model on the same four chips and the same port 8000, and that will fail — the chips have one owner at a time. This section is the path for serving a model other than the one that shipped. If you took the pre-cached route, the examples below still apply with two different substitutions — they are easy to cross-wire:
run.py --modeltakes the short spec name:Qwen3-32B, never the repo id.- The
"model"field incurland the Python SDK takes the full id the server reports:Qwen/Qwen3-32B, where the examples saymeta-llama/Llama-3.1-8B-Instruct.
curl -s http://localhost:8000/v1/models settles the second one on your box.
The fastest path to actually generating text is vLLM. It handles model loading, tokenization, batching, and presents an OpenAI-compatible HTTP API.
On a QB2 you do not invoke vllm yourself, and it is not installed in
~/.tenstorrent-venv — that venv holds only the hardware tooling (tt-smi, tt-flash).
vLLM ships inside a container that tt-inference-server launches for you:
cd ~/.local/lib/tt-inference-server

export HF_TOKEN=hf_...   # required; gated repos need it even when weights are local

python3 run.py \
  --model Llama-3.1-8B-Instruct \
  --workflow server \
  --tt-device p300x2 \
  --docker-server
run.py selects the right container image, sets TT_METAL_ARCH_NAME, MESH_DEVICE and
the vLLM RPC timeout for you, and publishes the OpenAI-compatible API. Add
--print-docker-cmd to see the exact docker run it would issue before it launches.
--tt-device p300x2 is the whole QB2 — two P300 boards, four Blackhole chips. Passing
p300 uses a single board, so half the machine sits idle. Check what a given model
supports: not every model is built for every topology.
--host-hf-cache reuses weights you pulled yourself with hf download, mounting the
Hugging Face cache read-only instead of downloading a second copy into a Docker volume. It
resolves HOST_HF_HOME, then HF_HOME, then ~/.cache/huggingface — so it only helps once
you have actually downloaded something. It is not how you reach the Qwen3-32B that
shipped with the box: those weights live outside any Hugging Face cache, and
--host-weights-dir is the flag for them. See above.
Llama-3.1-8B is the safer first model here. Very small models like Qwen3-0.6B will load — the
plugin maps them by architecture — but they have no tuned implementation in tt-metal’s
tt_transformers, so output quality is not something to judge the hardware by. Note that
Qwen3-0.6B is not in tt-inference-server’s model list at all: it is fine for the direct
TTNN handshake above, but you cannot serve it with the command in this section.
You’ll see initialization messages as the model loads. This takes a minute or two on first run — the model weights are being compiled for the Blackhole architecture. Subsequent runs are faster.
Once you see INFO: Application startup complete, the server is ready. In a new terminal:
curl -s http://localhost:8000/v1/chat/completions \
  -H "Content-Type: application/json" \
  -d '{
    "model": "meta-llama/Llama-3.1-8B-Instruct",
    "messages": [{"role": "user", "content": "What makes the Tenstorrent Blackhole chip different?"}]
  }' | python3 -m json.tool
The response is JSON. The answer is in choices[0].message.content.
tt_transformers implementation and is not in tt-inference-server's model list, so the vLLM command above cannot serve it.
Using tt-studio (the Web UI)
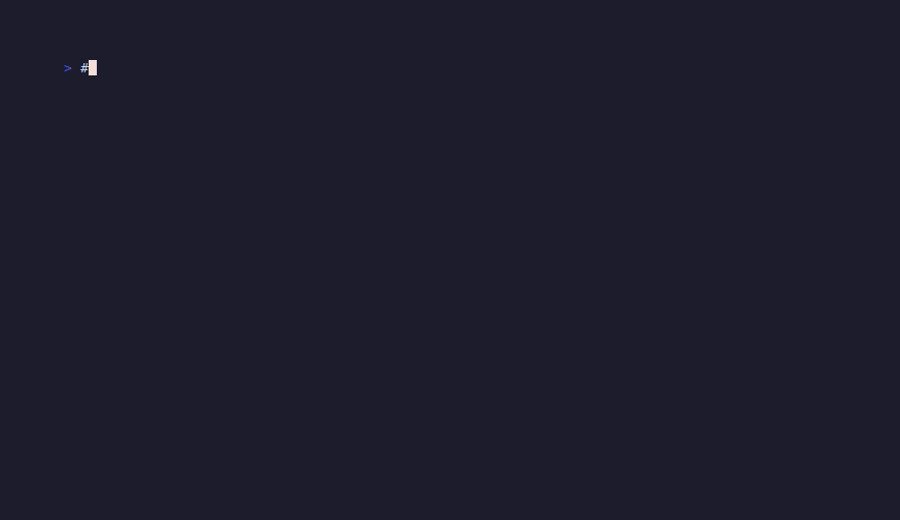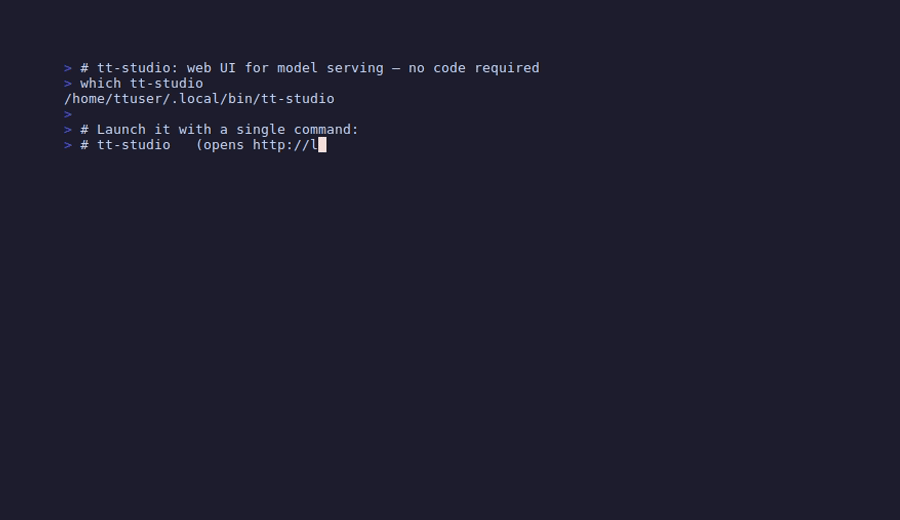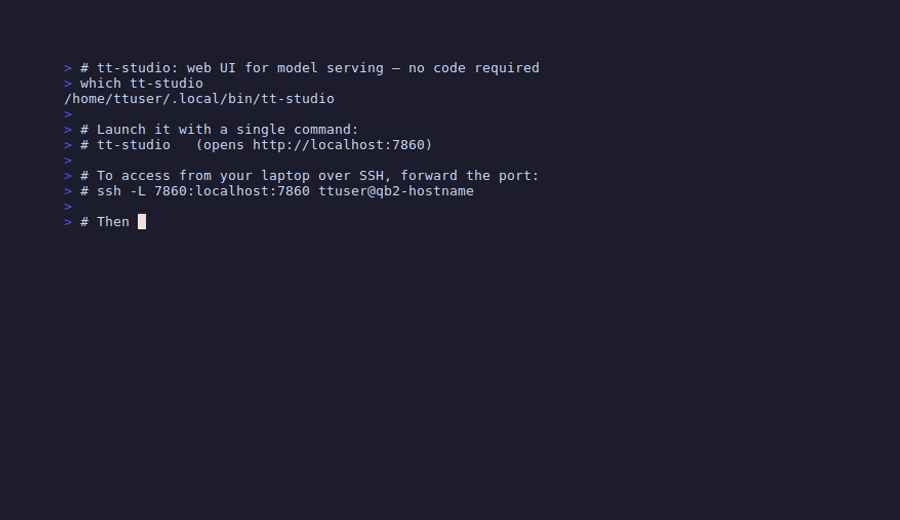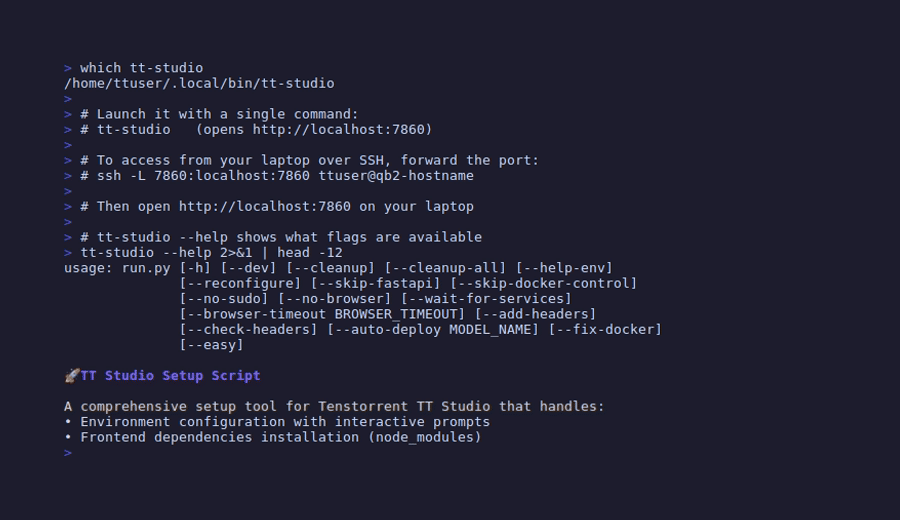
tt-studio
tt-studio is a web interface for running models on QB2 without writing a line of code. It handles model selection, container lifecycle, and inference end-to-end — open a browser, pick a model, get tokens back. It’s the lowest-effort path to your first token on a QB2.
Start it with the pre-installed wrapper command:
tt-studiott-studio: command not found? The wrapper lives in
~/.local/bin, which is not on PATH in every shell — zsh in
particular never reads ~/.profile, where Ubuntu's default
~/.local/bin rule lives. Fix it for this shell with
export PATH="$HOME/.local/bin:$PATH", and add that line to
~/.zshrc to make it stick. The same applies to tt-metalium,
tt-forge and tt-inference-server — the last of these is a wrapper
that runs run.py out of ~/.local/lib/tt-inference-server, so you can
call it either way.
Then open http://localhost:3000 in your browser, pick a model from the Deploy Model dropdown, and click Run. On a QB2, Qwen3-32B is already there with its weights pre-cached — its first deploy skips the multi-GB download and is ready in a few minutes. Other models download on first use; after that, every run loads fast from the on-disk cache. (tt-studio v2.8.0 also fixed the cold first-chat delay after an idle model, so that first token comes back quickly.)
tt-studio is at v2.10.0 as of this writing. Since v2.8.0 it’s added an OpenClaw general agent you can deploy like any model (v2.9.0), and an Apps Marketplace connecting deployed chat models to external tools plus hybrid RAG retrieval with reranking (v2.10.0).
tt-studio is a convenience command the QB2 ships. Under the hood it launches the same stack you'd get by cloning the repo and running python3 run.py — that sets up the submodule and .env, prompts for your Hugging Face token, selects the right Docker overlays for your hardware, and brings up the Django + React app plus the model containers, then serves the UI at localhost:3000. On any other machine, that clone-and-run.py flow is how you'd start it.
What’s happening under the hood: tt-studio is a UI sitting on top of tt-inference-server. When you select a model and click Run, tt-studio spins up a Docker container running the TT fork of vLLM on port 8000. Your browser talks to tt-studio; tt-studio talks to that container. tt-local-generator routes through the same container — both are UIs sitting on top of tt-inference-server, just with different front ends.
To access tt-studio from your laptop while the QB2 is on your network, forward the port over SSH:
ssh -L 3000:localhost:3000 user@qb2-hostnameThen open http://localhost:3000 on your local machine as if you were sitting in front of the QB2.
For a deeper look at how the inference server is wired up, the tt-vscode-toolkit lesson on tt-inference-server walks through the architecture interactively — Docker flags, model download, port mapping, and what logs to watch on first boot.
Multi-Device: Using All Four Chips
To spread a model across all four Blackhole chips, use CreateDevices instead of open_device:
tt-metalium

python3 -c "
import ttnn
devices = ttnn.CreateDevices({0, 1, 2, 3})
print('All devices:', devices)
ttnn.CloseDevices(devices)
print('Done.')
"
CreateDevices handles the mesh configuration that lets the chips coordinate. Models loaded this way can distribute layers across chips, increasing the effective memory pool and throughput. Large models (Llama-3.1-70B) require this — they don’t fit on one chip’s memory alone.
CreateDevices spans all four chips: a large model's layers spread across them for more memory and throughput. (A small model like Qwen3-0.6B runs happily on one chip.)
Next: One CLI to Run It →