-
v19.17.1 Oct 29, 2026
v19.17.1 patches a GDDR stability issue on Galaxy systems by disabling MRISC powerdown—a necessary tradeoff that raises idle power consumption by 1.6 kW. The underlying v19.17.0 release brings significant improvements across Blackhole and Grendel: Blackhole's Ethernet firmware now trains UBB retimer ports at 330G (when auto-train is enabled), fixes signal integrity on quad-SPI reads, and adds execution-stage visibility into the Ethernet pipeline via
eth_status.eth_fw_stage; Galaxy 2 DMC now handles missing PSU sense GPIOs gracefully; and Grendel gains a new QSR1.A1 board definition, I3C controller and target drivers for pre-D2D chiplet communication, and improved boot stability. See the 19.17 Migration Guide for upgrade details. -
v19.17.0 Oct 26, 2026
Blackhole Ethernet firmware now trains UBB retimer ports at 330G instead of 200G when auto-train is enabled, and a new execution-stage breadcrumb (
eth_status.eth_fw_stage) keeps tt-metal's NOC barriers in sync with firmware state—both critical for sustained high-throughput workloads. The SPI flash stack got a tuneup to eliminate false JEDEC ID mismatches at boot and resolve quad-SPI signal integrity issues on Blackhole, while new I3C and MCTP features in the DMC stack add target-mode interrupts and packet error correction for chiplet communication. On the Grendel side, QSR1.A1 is now supported with new Keraunos, Mimir, and Quasar chiplets, and the I3C controller and target drivers are ready for orchestrator-to-chiplet bring-up. See the migration guide for upgrade details.
A hidden dimension of Tenstorrent awesomeness
A curated directory of projects, tools, models, and research for Tenstorrent hardware — contributed by the community and our team. Browse by category or search across all entries.
Planet Tenstorrent is the ecosystem's live feed — new releases, articles, papers, talks, and community posts from across the Tenstorrent world, gathered in one place and updated daily. The latest five:
Orphaned cloud resources—instances and their attached volumes—are now automatically detected and optionally cleaned up across AWS, Azure, GCP, Nebius, and RunPod, addressing a rare but frustrating failure mode where server crashes or bugs leave provisioned infrastructure stranded. Detection runs in safe report-only mode by default, logging findings and emitting events you can query with dstack event; to enable automatic deletion, set DSTACK_SERVER_ORPHAN_CLEANUP_MODE=delete. The UI also learned to group GPU and CPU offers by availability and sort events by time, while the Dynamo inference example now runs etcd in a dedicated replica group for cleaner architecture.
-
v0.26.1 Oct 29, 2026
ESMFold2 workloads on long-running workers no longer crash with out-of-device-memory errors—a critical fix for production folding services like JapanFold that process mixed input lengths across many hours. The issue arose because compiled programs for each input shape persisted in device memory; when a worker accumulated ten hours of different sequence lengths, larger folds (722+ residues) would fail up to 65% of the time. Now, when a fold can't fit, the worker automatically clears cached programs and retries, keeping smaller folds unaffected while unblocking the large ones that were timing out on Wormhole chips.
-
v0.26.0 Oct 29, 2026
The token attention kernel in ESMFold2 and ESMFold2-Fast is now fused into a single program on Wormhole, cutting ~0.85 seconds off 512-residue folds while preserving accuracy at the precision level—and BoltzGen normal mode pre-conditions diffusion steps to shave 2.4 seconds from 514-token designs, again with negligible structural impact. If you're running protein folding or generative design workloads on Wormhole Galaxy, these are straightforward wins that compound across high-throughput screening campaigns without retuning your validation pipelines.
-
v0.25.0 Oct 28, 2026
BoltzGen's attention mechanism now pads to actual token counts instead of overshooting to 768, letting Blackhole fuse its attention into a single program — this cuts 1–2 seconds off a 514-token design depending on chip and mode, and the diffusion step replays from device traces by default for another ~2 second win on Precision 300. The changes are precision-aware and hold the 1831-residue ceiling, so existing designs stay put; you can restore eager stepping with
--no_diffusion_traceif needed. -
v0.24.0 Oct 27, 2026
RoseTTAFold3 and BoltzGen now run optimized triangle and transition kernels on Wormhole and Blackhole hardware, delivering 20–40% speedups on typical workloads while keeping structural predictions stable (pose shifts well within seed variation). Beyond per-model optimization, paired MSA searches against local databases now cache chains intelligently—folding one target against many binders drops from ~40 s to 2–12 s on repeat targets—and ESMFold2 replays diffusion steps from device traces for up to 1.6× faster short-chain folding. All changes are validated to preserve output fidelity: design confidence metrics and docking success hold, and paired MSA results match colabfold's byte-for-byte.
DFloat11 lossless LLM weight compression ported to Blackhole. Huffman-codes only the exponent field of BFloat16 weights, cutting them to about 70% of their size with bit-for-bit identical outputs, with a C++ extension built against tt-metal, a compressor and an on-device evaluation path.
Peter Cawley's eight-part reverse-engineering series on Wormhole: physical layout and disabled rows, NoC propagation delay, Ethernet, the insides of a Tensix tile, the vector instruction set, bits of the matmul unit and a closing reference. The companion repo is a functional description of the vector instructions.
This site is two old traditions sharing one orbit: an awesome list and a planet. Open source is an ecosystem the way space is — moonshot projects igniting into galaxies of forks and stars, and planet sites keeping the whole universe in view. (Around here the metaphor is load-bearing: we ship hardware called Galaxy.) Both traditions are gifts from decades of that culture, and both deserve some tribute.
🕶 The awesome list
Humans curating links for other humans is the oldest genre on the web —
Yahoo! began life in 1994 as "Jerry and David's Guide to the World
Wide Web", and the volunteer-run
DMOZ / Open Directory Project
kept hand-sorted order for two decades. In 2014, Sindre Sorhus distilled
that instinct into a GitHub-native microformat with
sindresorhus/awesome:
one README, a ruthless curation bar ("only awesome things"), and pull
requests as the editorial process. The
awesome manifesto
turned list-making into a commons — thousands of lists,
lists of lists,
and giants like
awesome-python,
awesome-selfhosted, and
awesome-go.
Synth heads are gloriously covered too:
awesome-musicdsp,
awesome-audio-dsp,
awesome-webaudio, and
awesome-supercollider.
Because the format is halfway to being a database, people have long
rendered lists into websites — tt-awesome just commits to the bit:
every entry is a JSON file, and the README, this site,
data.json, and the feeds are all built from the same source.
🪐 The planet
In the early 2000s, Jeff Waugh and Scott James Remnant wrote Planet, a little Python feed aggregator that river-merged a community's blogs into one page — and free software communities never looked back. Planet GNOME, Planet KDE, Planet Debian, Planet Gentoo, Planet Ubuntu, Planet Fedora (the Red Hat family), and Planet Mozilla are all still ticking decades later, many having passed through Sam Ruby's Planet Venus rewrite along the way. The lineage runs deeper still: before planets there were blogrolls, and before blogrolls, web rings — WebRing was built in 1995 by a teenaged Sage Weil, who grew up to create Ceph, which is about as open-source-full-circle as a story gets. Planet Tenstorrent carries that torch for this ecosystem.
⚡ Why we bother
Curated commons like these only exist because communities keep them alive in the open. That's not nostalgia to us — it's the plan. Open source is our past, present, and future.
No entries match the current filters.
Select an entry to see details
tt-metal
official
TT-NN operator library and TT-Metalium low-level kernel programming model. The primary SDK for developing on Tenstorrent hardware — from high-level tensor ops to bare-metal RISC-V kernels.
5 previous releases
tt-forge
official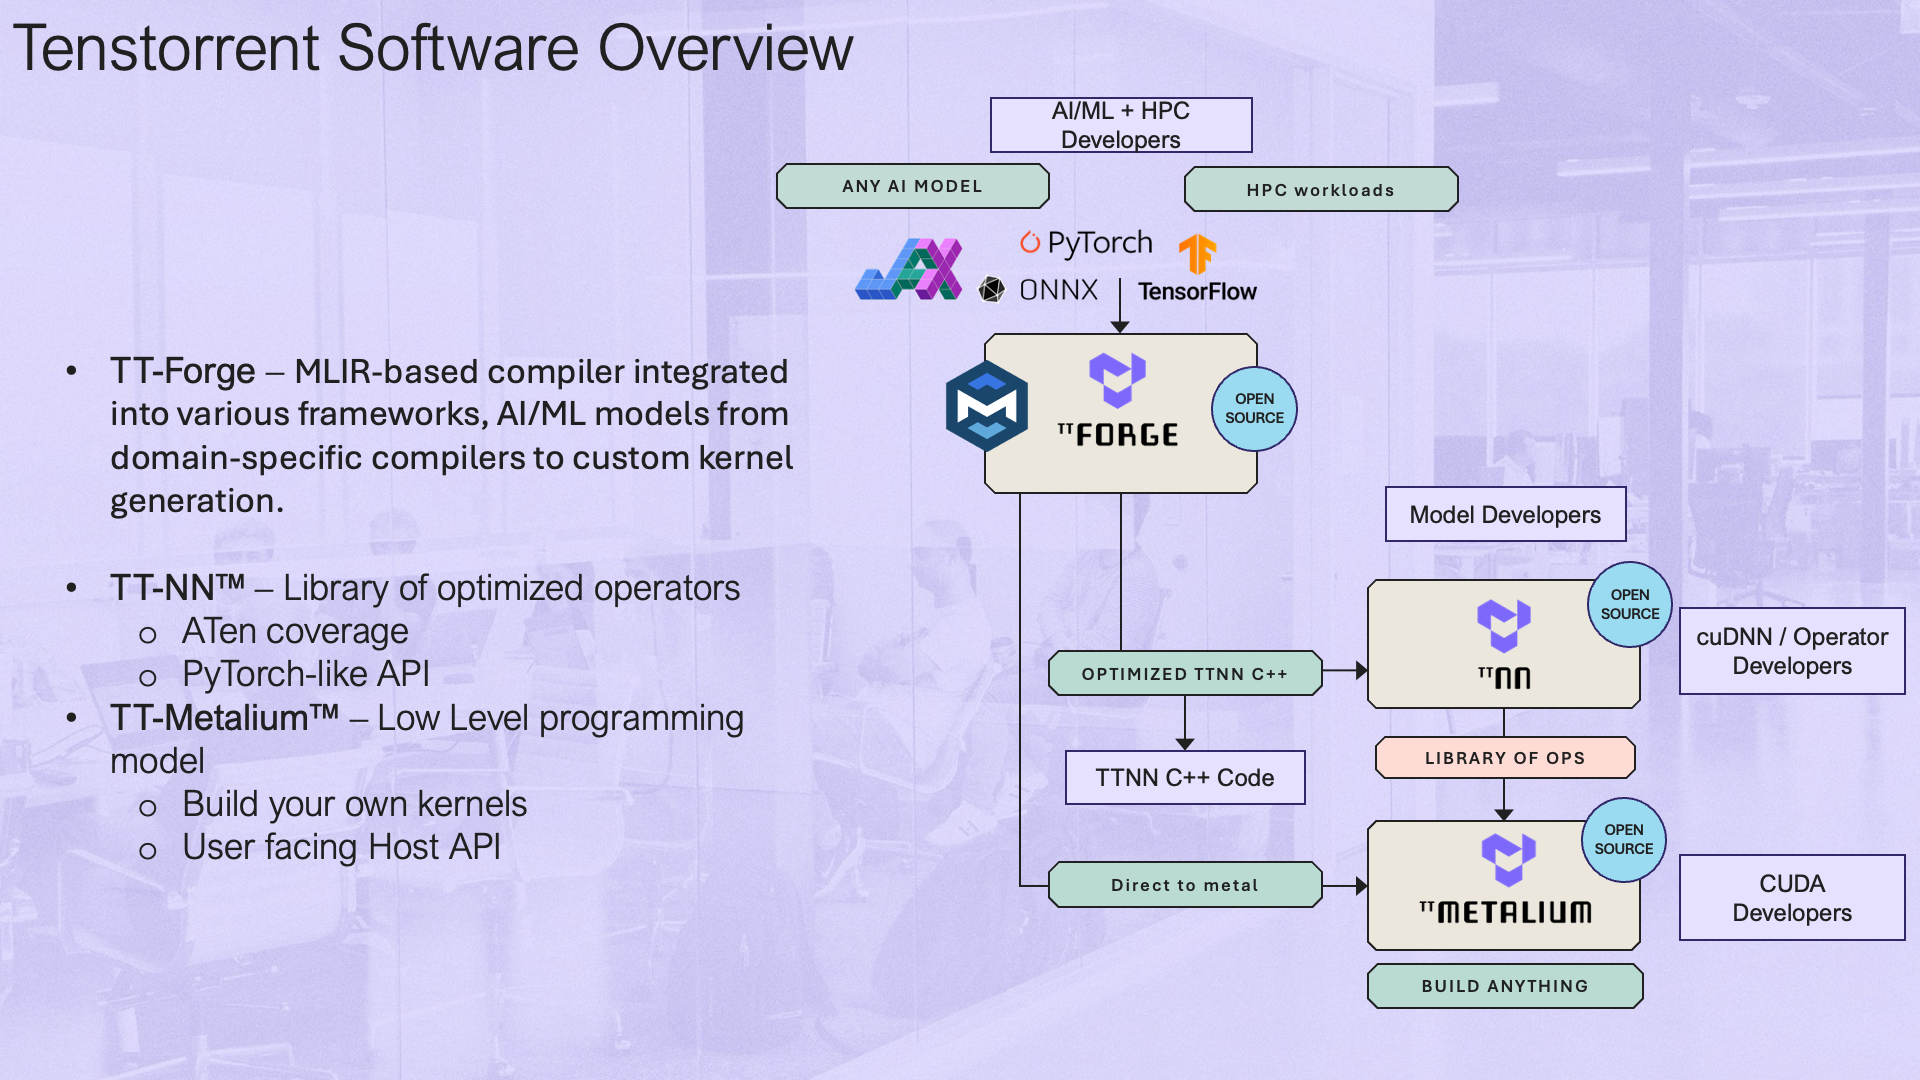
Tenstorrent's MLIR-based compiler frontend. Enables running AI workloads from PyTorch, ONNX, and other frameworks on all Tenstorrent hardware configurations through an open-source, general, and performant compiler.
5 previous releases
tt-mlir
officialTenstorrent MLIR compiler — the core compiler infrastructure shared by tt-forge and other frontends. Handles graph optimization, lowering, and code generation for Tensix hardware.
tt-buda
officialTT-BUDA: Tenstorrent's original Python compiler and runtime for AI workloads. Legacy stack — tt-forge is the recommended successor, but tt-buda has the largest model demo library.
4 previous releases
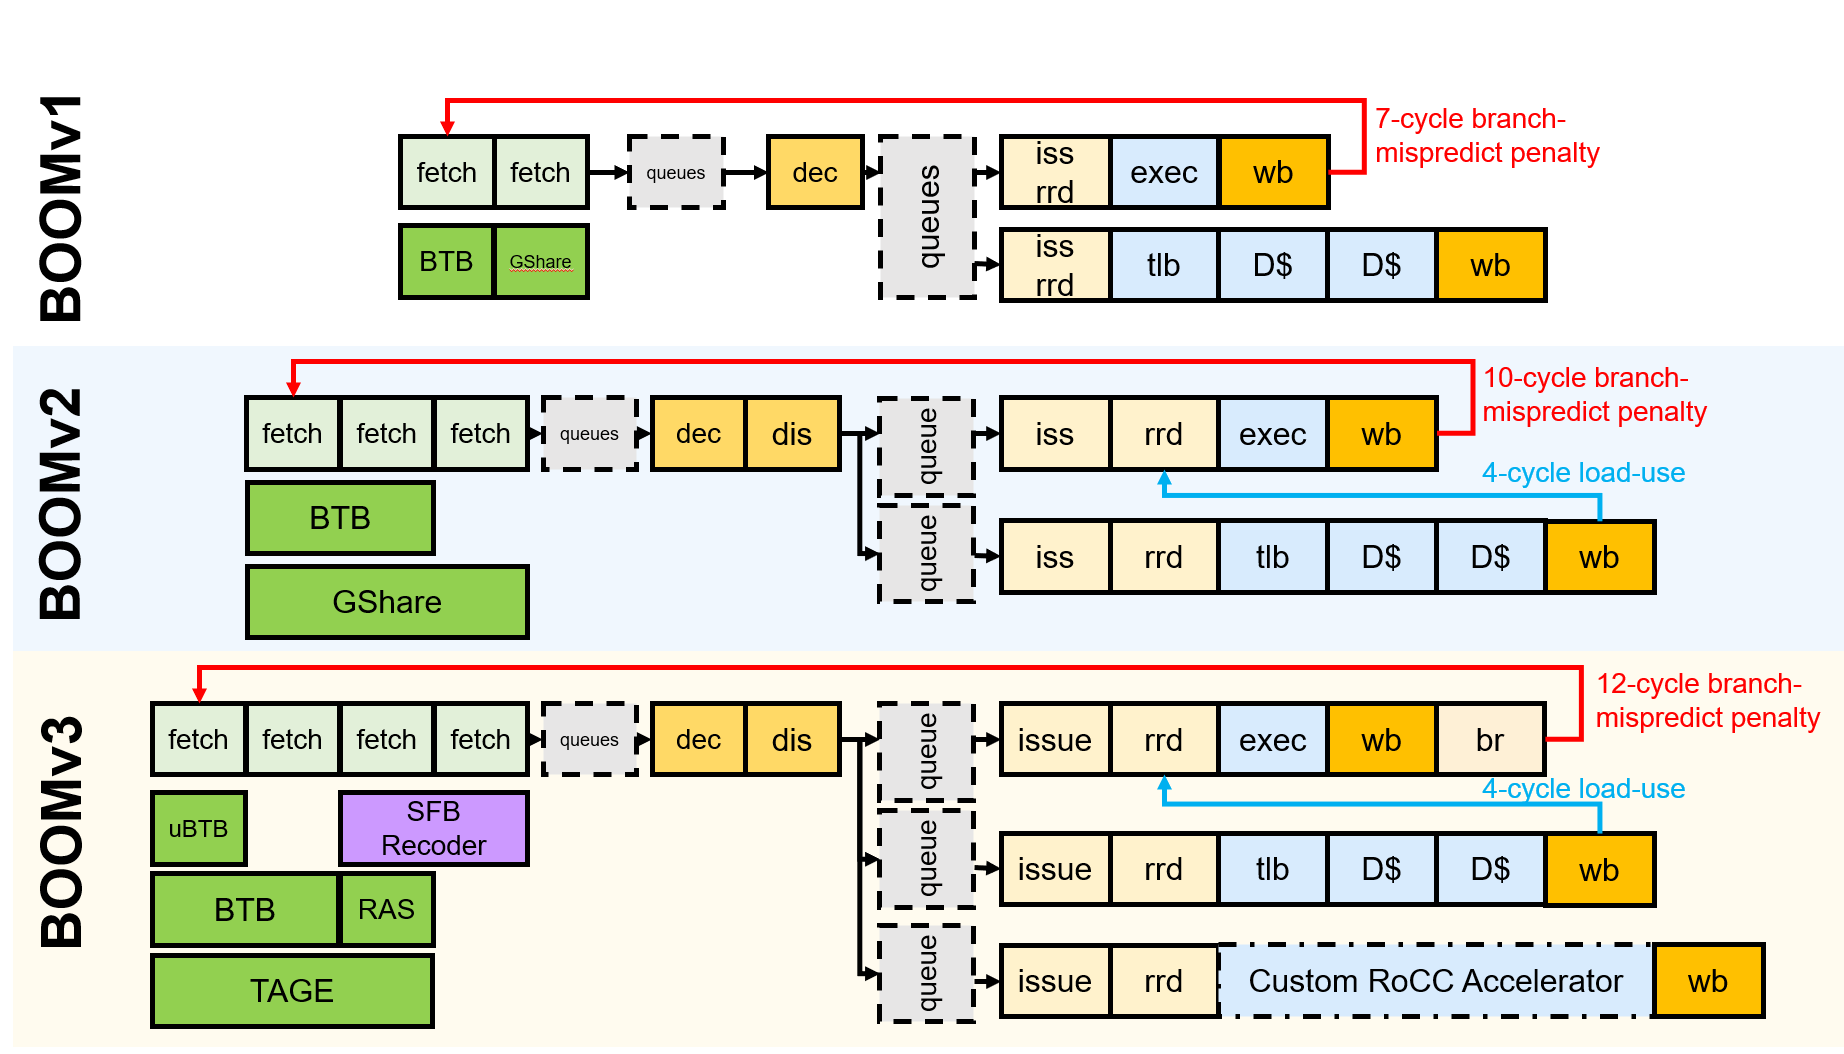
The Berkeley Out-of-Order Machine with V-EXT (RISC-V Vector Extension) support. Tenstorrent's research-grade out-of-order RISC-V core with vector extension.
ttsim
officialFast full-system simulator of Tenstorrent Wormhole and Blackhole hardware. Runs TT-Metalium workloads on any Linux/x86_64 system without physical silicon. Bit-exact results relative to hardware.
tt-isa-documentation
officialLow-level ISA and microarchitecture documentation for Tenstorrent AI architectures (Grayskull, Wormhole, Blackhole) — the authoritative hardware reference beneath the tt-forge / tt-metal software stack.
riscv_arch_tests
officialRISC-V architectural self-checking directed tests — randomly-generated register operands and data with low-level OS code for test scheduling and self-checking, runnable on a RISC-V design or an ISS such as Whisper or Spike. Generated by an internal Tenstorrent tool from the official RISC-V ISA spec.
RISC-V Instruction Set Simulator (ISS) used by Tenstorrent for processor verification. Powers the co-simulation architecture checker.
tt-inference-server
officialProduction-ready model serving for Tenstorrent hardware with OpenAI-compatible REST API. Supports continuous batching, multiple models, and all TT hardware configurations.
tt-xla
officialPJRT device plugin for Tenstorrent hardware. Enables JAX, PyTorch/XLA, and other XLA-based frameworks to target TT accelerators.
5 previous releases
tt-kmd
officialTenstorrent kernel module driver. The Linux kernel module required to interface with Tenstorrent PCIe accelerator cards.
4 previous releases
RiESCUE
officialRISC-V Directed Test Framework and Compliance Suite. Comprehensive test infrastructure for verifying RISC-V processor implementations against the specification.
tt-forge-onnx
official
ONNX graph compiler for Tenstorrent hardware. Optimizes and transforms ONNX model graphs for efficient execution on Tensix accelerators. Used as a backend by tt-forge for ONNX model ingestion.
5 releases
tt-smi
official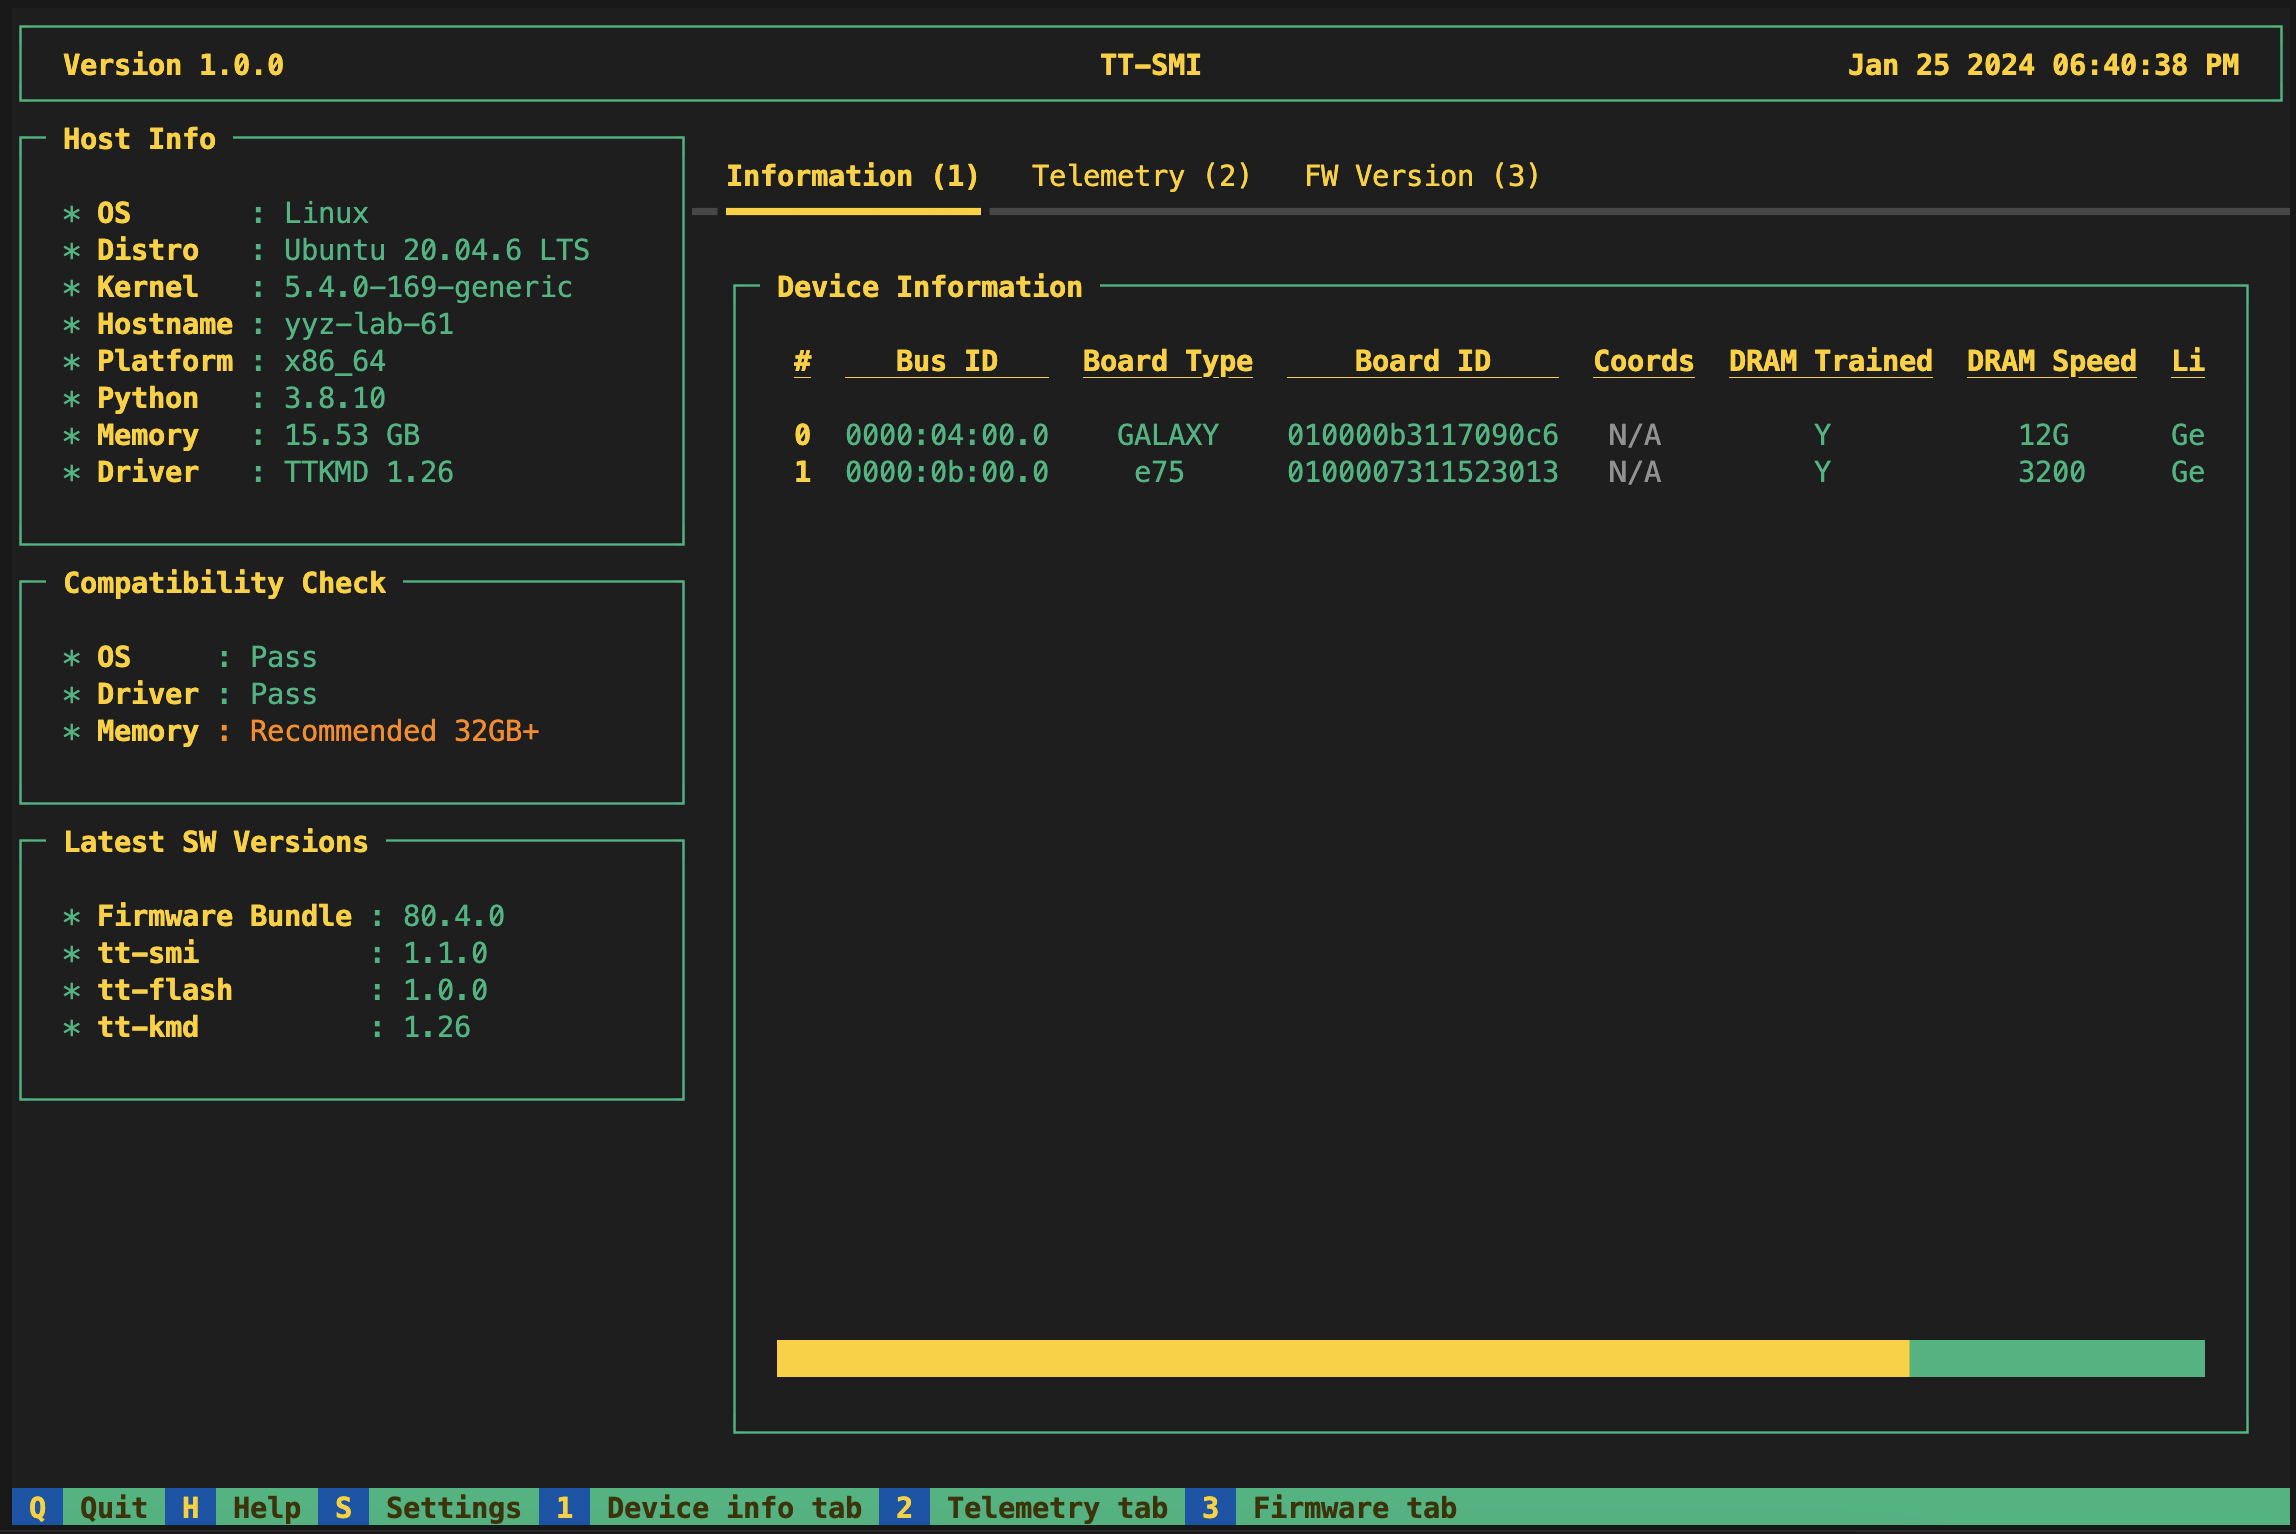
Tenstorrent System Management Interface — monitor device telemetry, issue board-level resets, and inspect hardware health. The nvidia-smi equivalent for Tenstorrent hardware.
📋 Changelog
# Changelog

All notable changes to this project will be documented in this file.

The format is based on [Keep a Changelog](https://keepachangelog.com/en/1.0.0/),
and this project adheres to [Semantic Versioning](https://semver.org/spec/v2.0.0.html).

## 3.0.26 - 29/07/25
- Added single tray galaxy reset option
- Bumped luwen from 0.7.5 -> 0.7.10
  - Chip detect now doesn't wait for eth to train for the 6U galaxy's, allowing multi tray resets to happen independently
- Updated readme with the new reset option

## 3.0.25 - 29/07/25
- Added packaging

## 3.0.24 - 04/07/25
- Now users have 2 galay reset modes available
  - glx_reset: resets the galaxy, informs users if there has been an eth failure
  - glx_reset_auto: resets the galaxy upto 3 times if eth failures are detected

## 3.0.23 - 03/07/25
- Bumped luwen 0.7.3 -> 0.7.5 to fix cargo lock compatibilty issue

## 3.0.22 - 02/07/25
- Bumped tt-tools-common 1.4.16 -> 1.4.17
- Bumped luwen 0.7.2 -> 0.7.3
- Bumped smi 3.0.21 -> 3.0.22

## 3.0.21 - 26/06/25

- Added option to not re-init chips after reset
- Updated galaxy 6u reset option from --ubb_reset to -glx_reset
- Removed the a3 arc message before doing a 6u reset, meaning we can reset even when chips are not pcie accessible
- Added eth link check and return failure if any of the eth links have a LINK_INACTIVE_FAIL_DUMMY_PACKET failure

## 3.0.20 - 04/06/25

- Chore - bumped tt-tools-common version to fix driver version check for compatability with tt-kmd 2.0.0

## 3.0.19 - 30/04/25

- Fixed an issue preventing the telemetry thread from being dispatched when the user clicked tab 2

## 3.0.18 - 22/05/25

- Added BH and WH UBB board type support
- Removed the dependency on tt-tools-common for this info

## 3.0.17 - 13/05/25

- Added proper telemetry heartbeat checks for Grayskull

## 3.0.16 - 12/05/25

- Used new ResetTypes from tools-common to simplify reset code
- Added a heartbeat spinner to the telemetry pane. We expect this spinner to update about twice per second. If the spinner is not moving, this indicates new telemetry is not being fetched.

## 3.0.15 - 24/04/25

- Patch for the ubb_reset to just discover local only post reset. Looks like eth port status 2 has been re-used to mean connected and pyluwen waits for it to clear, leading to eth timeout.

## 3.0.14 - 21/04/25

- Added wh ubb reset via command line `tt-smi --ubb_reset`. Intention is that this command line option will be removed and integrated into `tt-smi -r` after we update board detection with the correct external naming.
- Removed some unused imports and code - no functional changes

## 3.0.13 - 21/03/25

- Removed get\_sw\_versions

## 3.0.12 - 21/03/25

- Chore - bumped luwen version to include eth fw version check fix

## 3.0.11 - 13/03/25

- Chore - bumped luwen version to include enable chips with external connections but no routing

## 3.0.10 - 10/03/25

- Chore - bumped luwen version to include protoc lib detection check

## 3.0.9 - 07/03/25

- Chore - bumped luwen v
tt-lang
official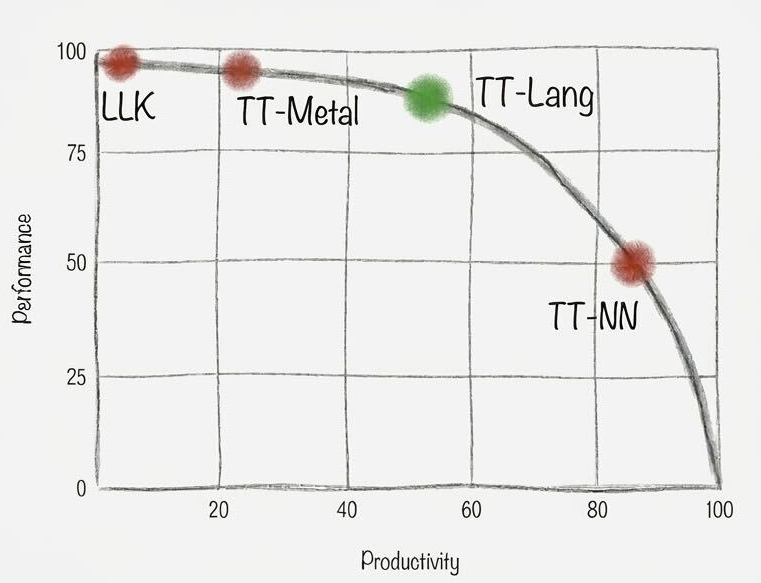
Python-based DSL that sits between TT-NN and TT-Metalium — expresses custom fused kernels with progressive disclosure, compiling directly to Tensix. Ships an integrated functional simulator (no hardware needed), line-by-line performance metrics, and AI-agent-friendly tooling. Two packages: tt-lang (compiler + hardware, requires ttnn) and tt-lang-sim (simulator only, works on Linux/macOS without Tenstorrent hardware).
📋 Changelog
# Changelog

All notable changes to TT-Lang will be documented in this file.

The format is based on [Keep a Changelog](https://keepachangelog.com/en/1.0.0/),
and this project adheres to [Semantic Versioning](https://semver.org/spec/v2.0.0.html).

## Version 1.1.1

### Compiler

- Fix for live-interval boundary computation (issue [#536](../../issues/536))
- Fix for all-zero results in FP32 reductions (issue # [#533](../../issues/533))
- Fix for inferred `pop` and `push` (issues [#536](../../issues/536), [#554](../../issues/554))
- Fix for write pointer tracking on pipe sender accross iterations (issue [#578](../../issues/578))
- Fix to report data type mismatch error
- Fix to report DFB over allocation error (issue [#511](../../issues/511))
- Support for pipenet predicates `is_src`, `is_dst` and `is_active` (issue [#541](../../issues/541))
- Support for `ttl.math.typecast`

### Simulator

- Support for inferred `pop`, `push` and `copy`'s transfer handle `wait`
- Support for pipenet predicates `is_src`, `is_dst` and `is_active`
- Support `all_gather`
- Support `bfloat8_b`
- Improved/actionable error messages
- Improved performance by simulating math in FP32

### Infrastructure

- TT-Lang installable with `pip install tt-lang` for full installation and `pip install tt-lang-sim` for simulator only
- [Matmul benchmarks](benchmarks/matmul/README.md)

## Version 1.0.0

### Compiler

- Support `+=` syntax in conjunction with dot product (`@`) lowered to packer L1 accumulation
- Support implicit temporary compute-kernel-local DFBs
- Support `ttl.Pipenet`
- Support implicit `ttl.Block.push` and `ttl.Block.pop`
- Support implicit `ttl.Transfer.wait`
- Support for `expm1`, `exp2`, `ceil`, `sign`, `gelu`, `silu`, `hardsigmoid`, `square`, `softsign`, `signbit`, `frac`, `trunc` in `ttl.math`

### Simulator

- Support for `ttl.GroupTransfer`
- SPMD and mesh device simulation support
- Support for `ttnn.all_reduce` CCLs
- Use tracing to report statistics with `tt-lang-sim-stats`
- Remote L1 reads/writes statistics

### Examples and documentation
- Matmul tutorial

## Version 0.1.8

### Compiler

- Support for dot product operator (`@`) with lowering to [`ckernel::matmul_block`](https://docs.tenstorrent.com/tt-metal/v0.55.0/tt-metalium/tt_metal/apis/kernel_apis/compute/matmul_block.html)
- Support for fusing matmul and certain elementwise operations
- Support lowering to `pack_tile_block`
- Support for `ttl.math.fill`, `ttl.math.reduce_sum`, `ttl.math.reduce_max`, and `ttl.math.transpose`
- Support for arbitrary sub-blocking including dot product K-dimension to allow maximizing L1 usage and reuse
- Support for `sin`, `cos`, `tan`, `asin`, `acos`, `atan` in `ttl.math`
- Support for L1 sharded tensors
- Support for tensors with BF8 data type
- SPMD support (`ttnn.open_mesh_device`)

### Simulator

- Track L1 space and number of DFBs usage and warn when exceeded
- Support for tensors with row-major layout
- Support for L1 sharded tensors

### Examples and documentat
tt-buda-demos
officialRepository of model demos using TT-Buda. The largest collection of pre-compiled model examples for Tenstorrent hardware — BERT, ResNet, YOLO, GPT-2, Whisper, and many more.
tt-bh-linux
official★ featured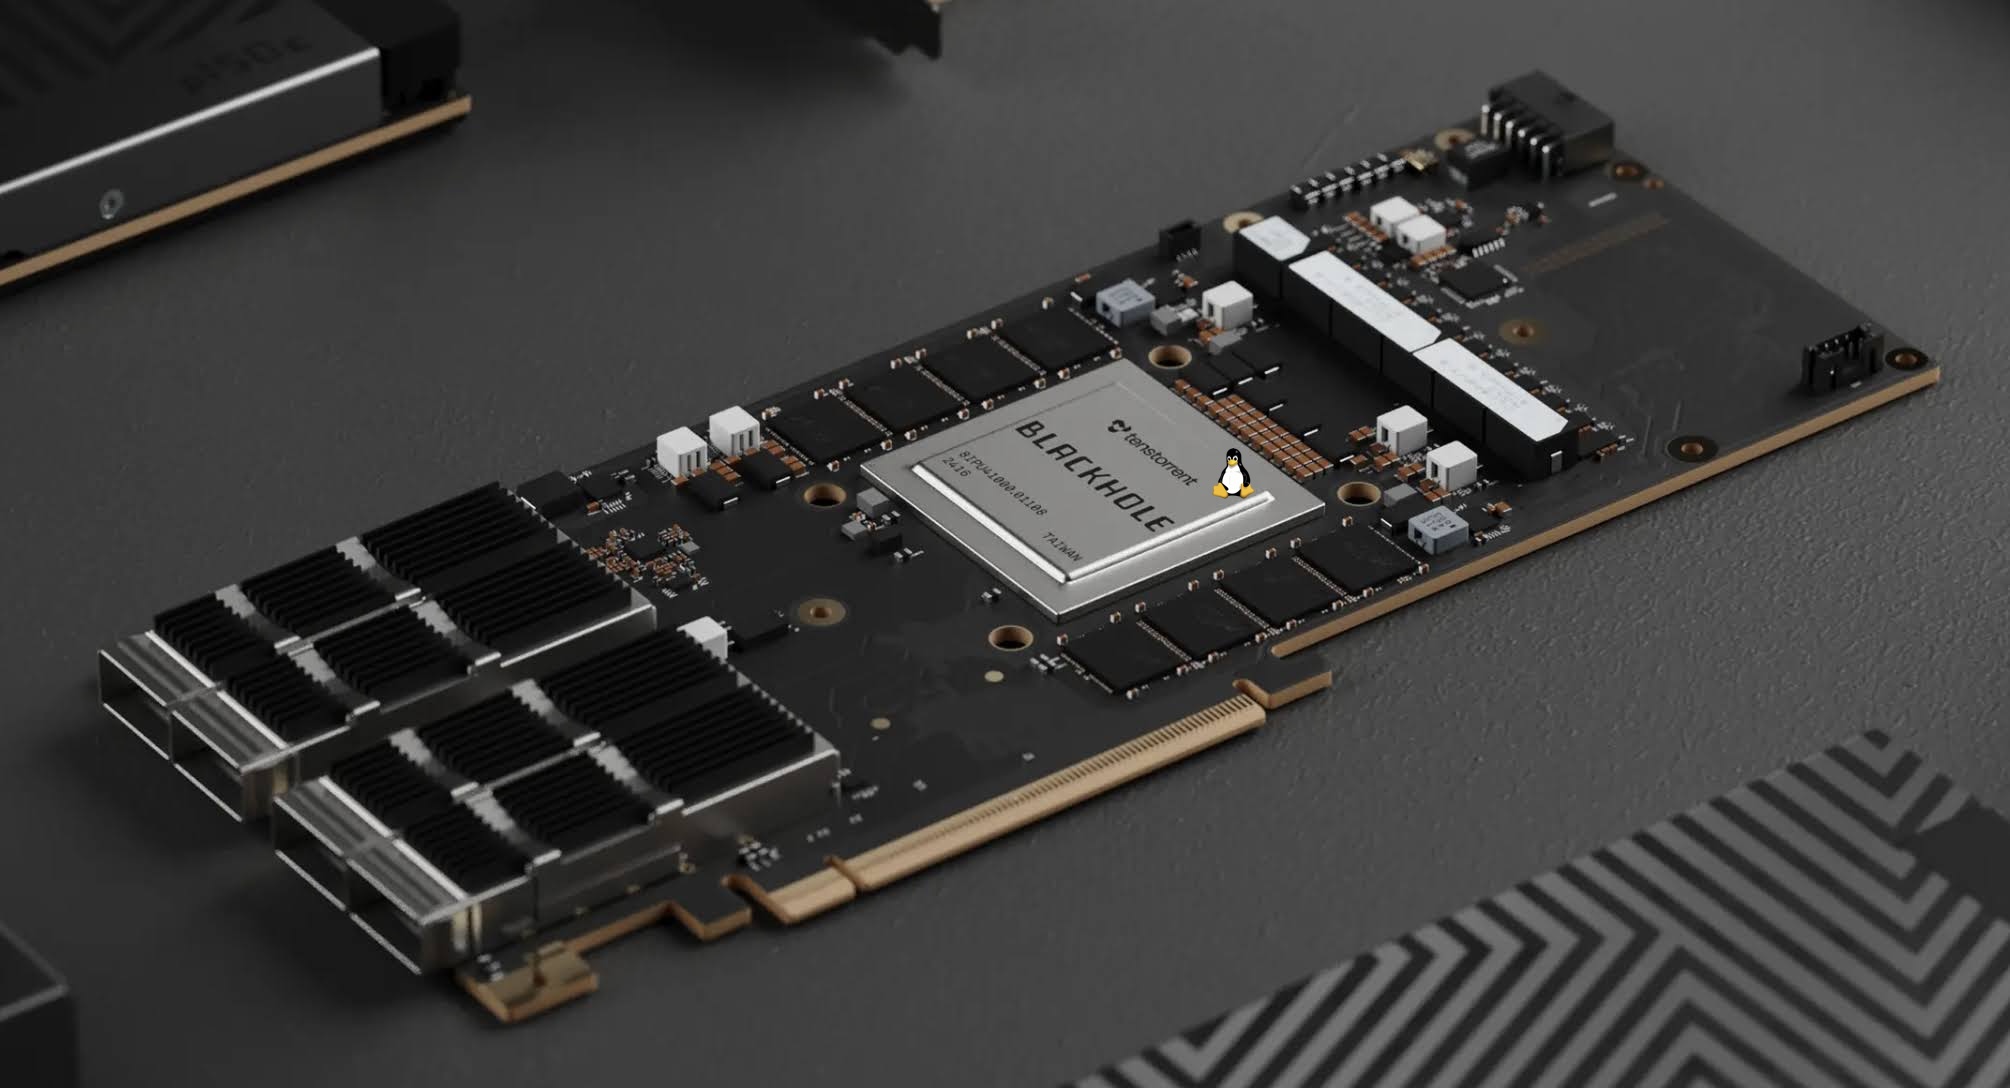
Linux demo for the Tenstorrent Blackhole P100/P150 card RISC-V cores. Boot a real Linux kernel on the 16 high-performance RISC-V cores built into the Blackhole chip.
ttnn-visualizer
official
Comprehensive tool for visualizing and analyzing model execution on Tenstorrent hardware. Interactive graphs, memory plots, tensor details, buffer overviews, operation flow graphs, and multi-instance support.
tt-llk
officialTenstorrent Low-Level Kernels: the C++ library that directly programs the RISC-V cores inside each Tensix compute engine. TRISC0 (unpack), TRISC1 (math/FPU/SFPU), and TRISC2 (pack) are all programmed through this layer — it is the interface between TT-Metal kernel code and bare silicon.
WallaBMC
official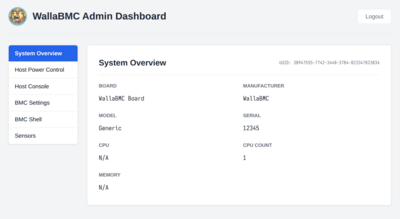
Lightweight BMC (Baseboard Management Controller) for STM32 and similar MCUs, with Web UI, Redfish API, and HTTPS support. Built on Zephyr RTOS. Used in Tenstorrent systems.
TT-Studio
officialWeb-based GUI for deploying and chatting with AI models on Tenstorrent hardware. Handles all technical setup automatically — deploy models, run inference, and explore capabilities through a simple browser interface.
tt-umd
officialUser-mode driver for Tenstorrent hardware. The userspace layer that sits between the kernel module and higher-level SDKs.
4 previous releases
📋 Changelog
# Changelog

## [0.9.13] - 2026-10-02

### Changed

RTL simulator IP partitioning: one simulator run serving several chips via ip_layout.yaml.
RiscReset component interface.
Host memory channels set automatically based on topology.
IPMI reset improvements.

## [0.9.12] - 2026-09-28

### Changed

Simulator topology discovered through the silicon path.
IoOrdering parameter on Cluster read and write.
Quasar ATT address map.
Simulation servers whose host is gone are no longer reported.

## [0.9.11] - 2026-09-21

### Changed

TLBManager removed in favor of IoWindow; per-arch silicon TTDevice subclasses deleted.
Runtime telemetry and clock queries served by DeviceFirmware.
Optional cluster_id in the cluster descriptor.
Latest supported CMFW raised to 19.14.

## [0.9.10] - 2026-09-09

### Changed

Base API alignment: TTDeviceModel, DeviceFirmware, DmaInterface, IoWindow, MutexInterface, SystemMemoryAllocator.
SysmemBuffer ownership and host copy APIs; dma-buf export for RDMA.
Locks backed by KMD resource locks; tt-kmd-lib extracted.
Stateless NOC across TTDevice and SocDescriptor; xy_pair overloads removed.
Shared simulation server (sim_server) with client/host mode over sockets.

## [0.9.9] - 2026-07-09

### Changed

Blackhole runtime telemetry buffer accessors.
Precise ETH_LIVE_STATUS based APIs and Blackhole harvesting utility.
TTSim cluster descriptor discovered from simulator directory.

## [0.9.8] - 2026-07-01

### Changed

Per-op MMIO timeout for TLB-mapped device access.
set_power_state renamed to set_clock_state in TTDevice.
Simulation client mode over SimulationClient.

## [0.9.7] - 2026-06-26

### Changed

Device health errors returned from TopologyDiscovery.
Dedicated EthernetBroadcast and noc_multicast for remote chips.
DeviceTimeoutError exception type.
DRAM retrain on BIST failure.

## [0.9.6] - 2026-06-03

### Changed

ARM (aarch64) builds and fixes.
TTSimChip and RtlSimulationChip merged into SimulationChip, with multichip support.
TensixSoftResetOptions removed.
Warm reset with remote IO failure recovery.

## [0.9.5] - 2026-05-12

### Changed

Hardware hang detection for NOC and PCIe.
Tracy profiler integration with instrumentation across TLB, PCIe and sysmem paths.
DeviceProtocol ported to TTDevice, including DMA migration.
SocDescriptor split into static (SocArchDescriptor) and runtime parts.
LITERAL coordinate system in CoreCoord.
Multicast to all TENSIX cores.
SMN support.
SWEmuleChip software emulation chip and Quasar simulation support (incl. 4GB TLB).
Unified UmdException/UMD_ASSERT/UMD_THROW error handling across the codebase.

## [0.9.4] - 2026-03-18

### Changed

TopologyDiscoveryOptions refactoring.
TopologyDiscoveryOption to retrain ETH links on 6u.
TLBs for TTsim.
DRAM retrain support.
DeviceProtocol changes.
Simulator in TTDevice changes.
ETH heartbeat check.

## [0.9.3] - 2026-02-24

### Changed

Sigbus safe read write API.
Remove 4U related code.
Implement BH SPI as well, so full SPI support.
P150 expects harvested core
polaris
officialA high-level AI simulator from Tenstorrent for modeling and exploring AI accelerator and workload performance.
tt-system-firmware
official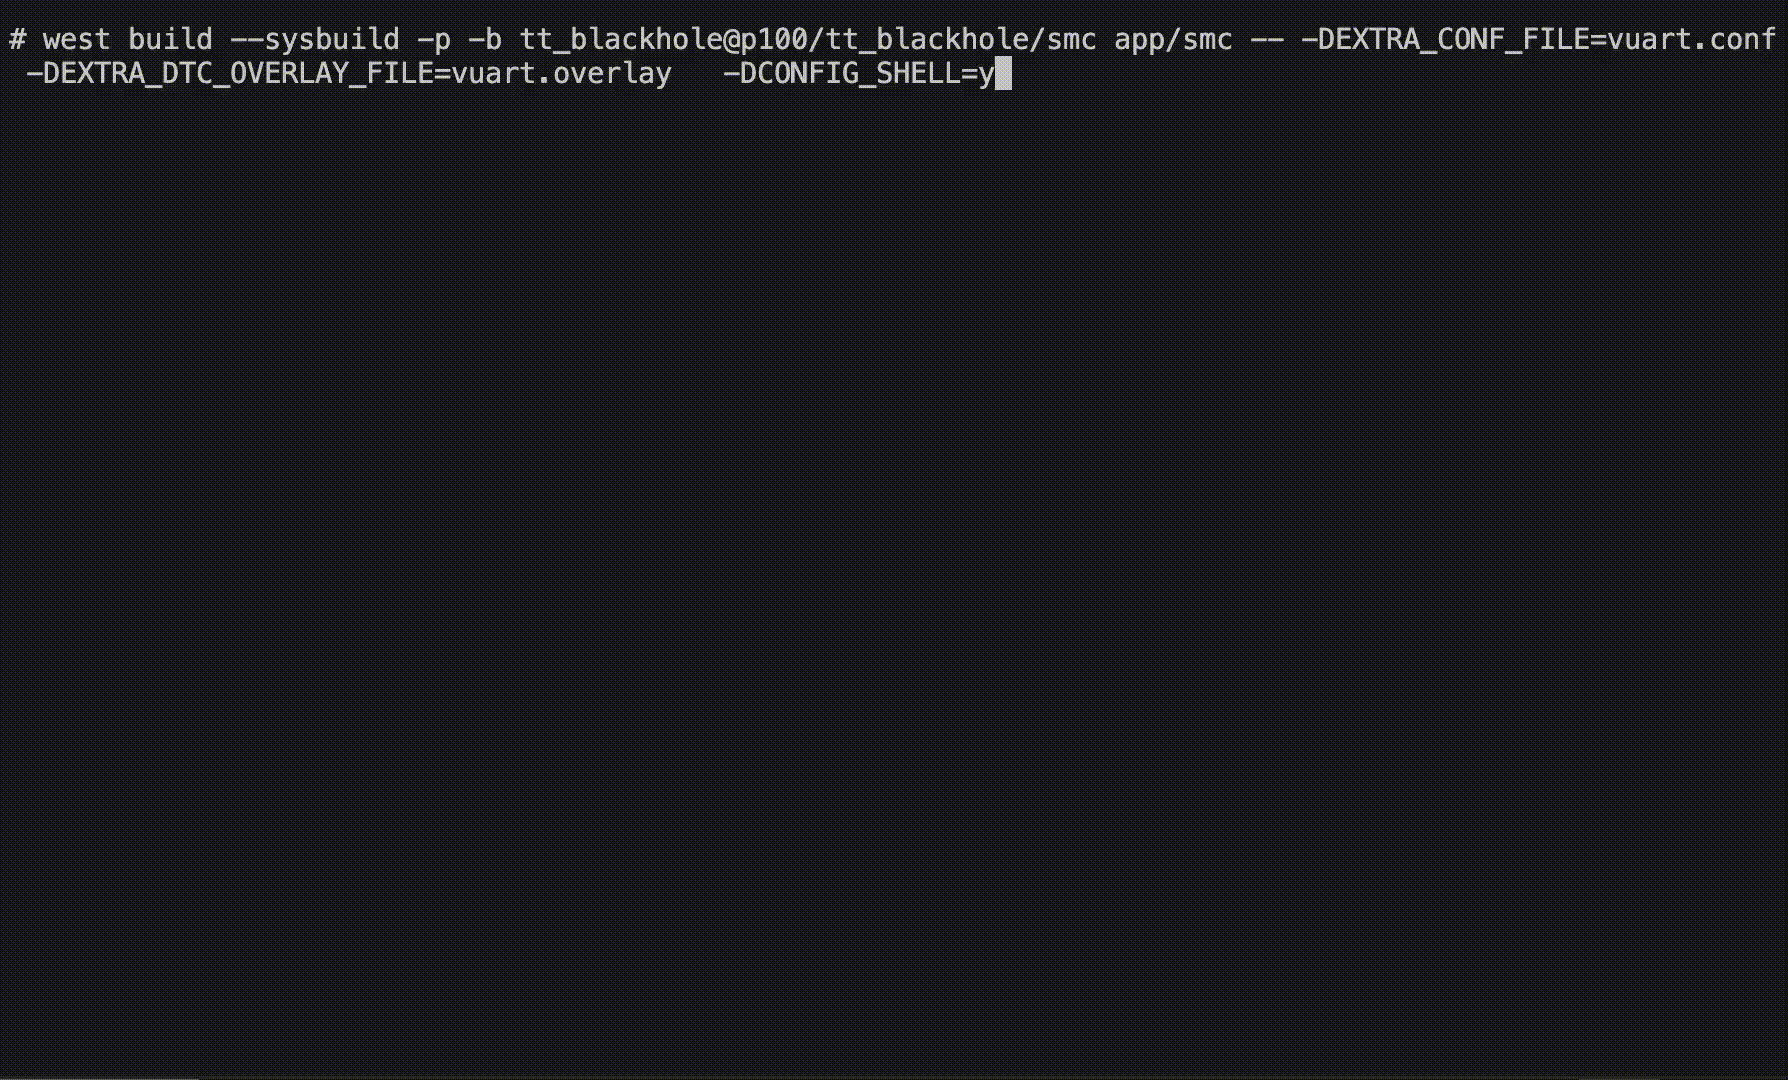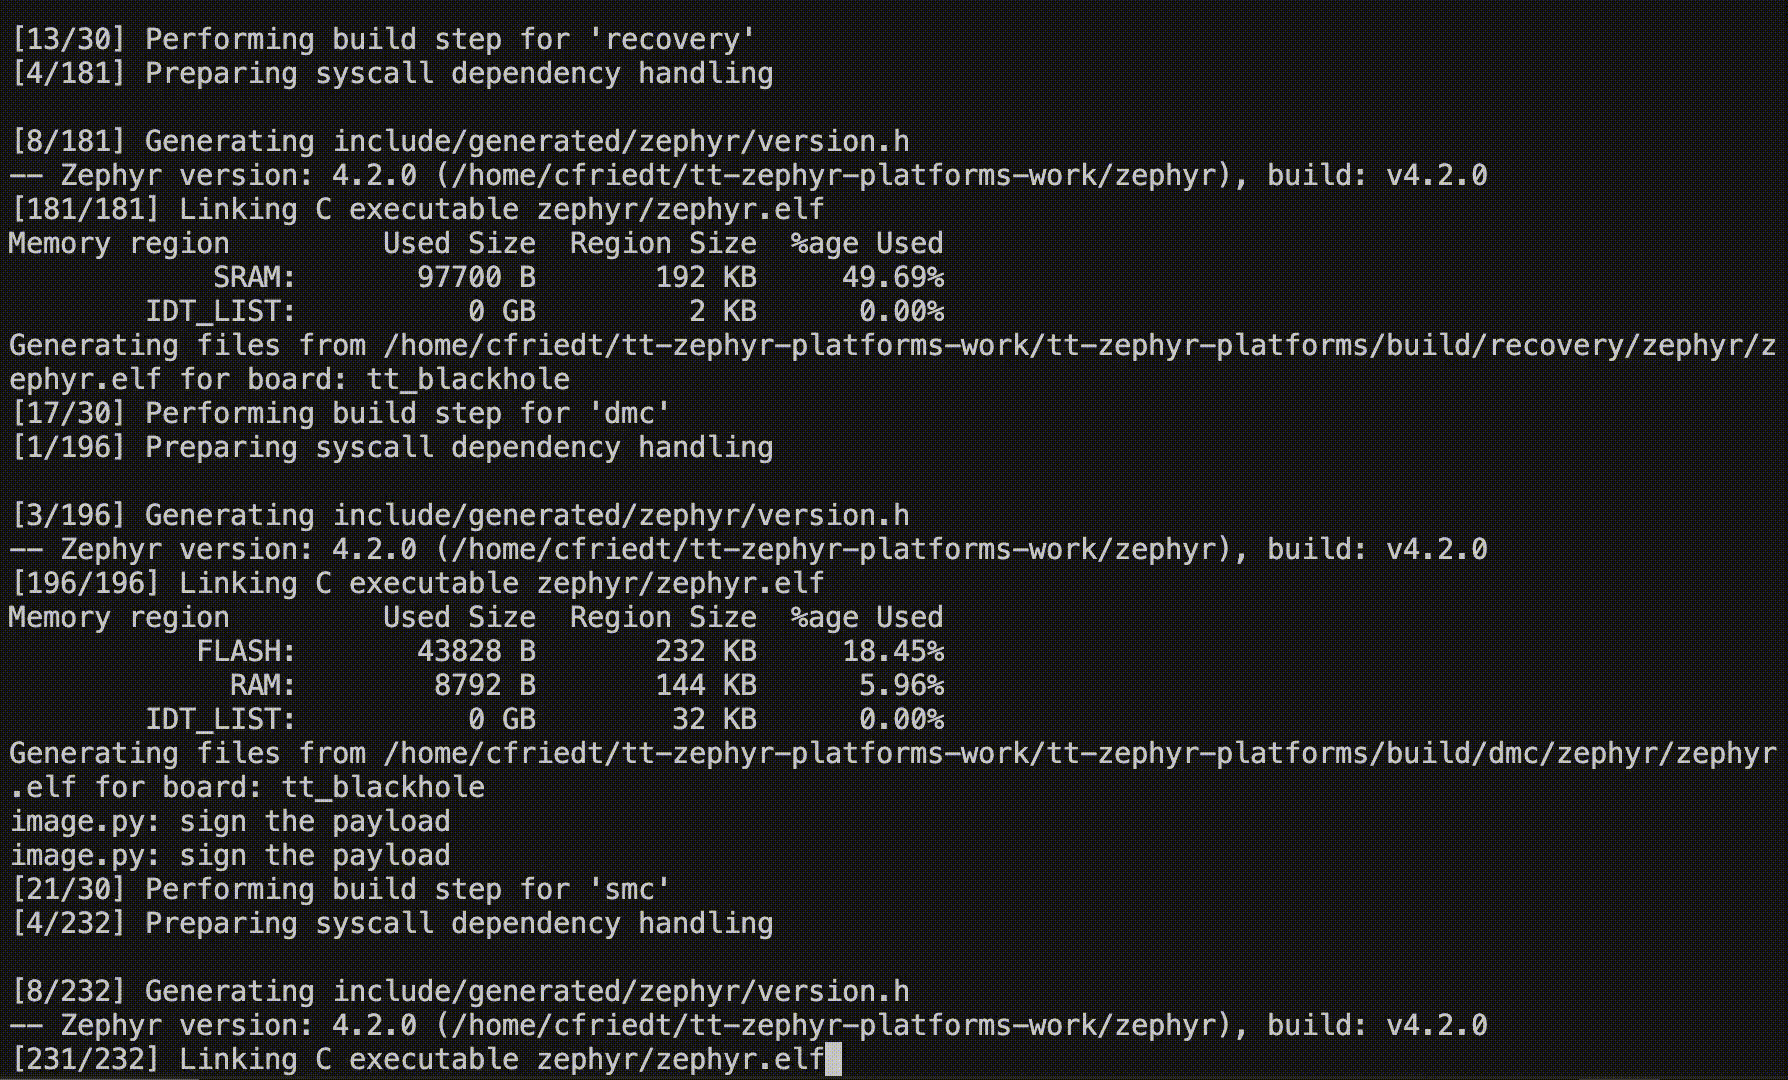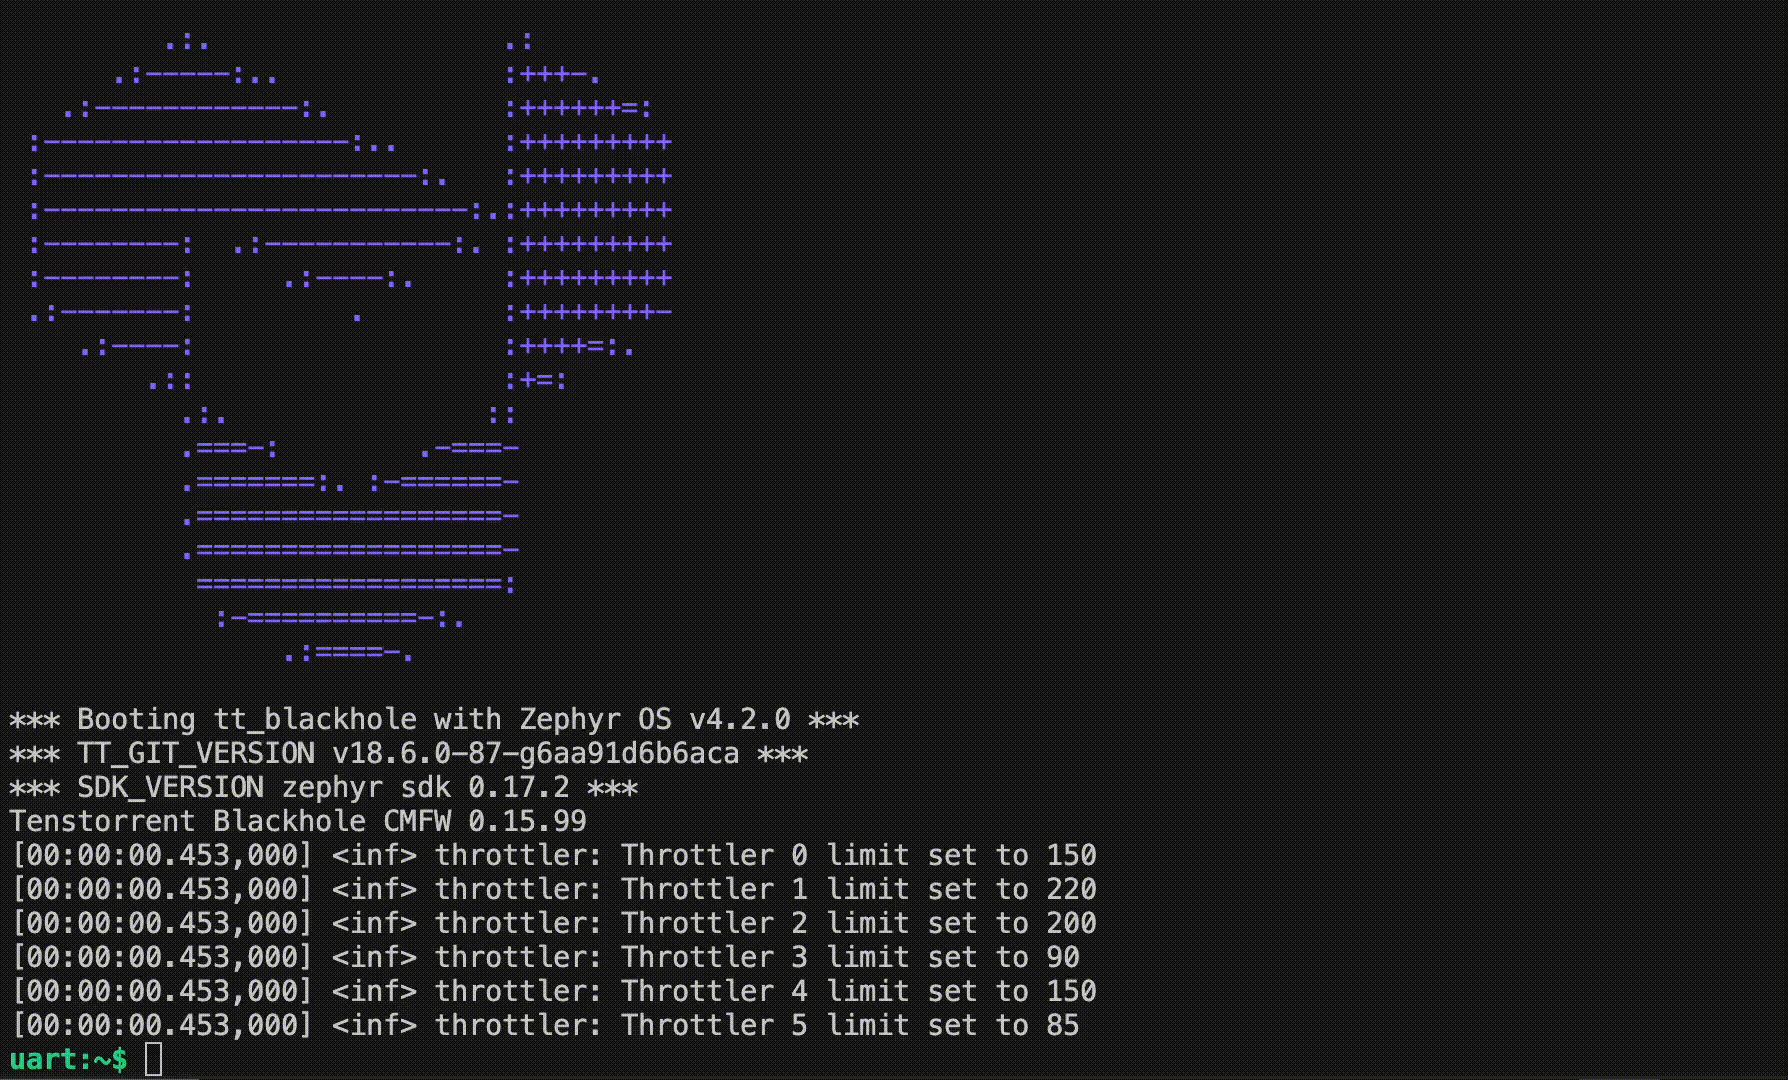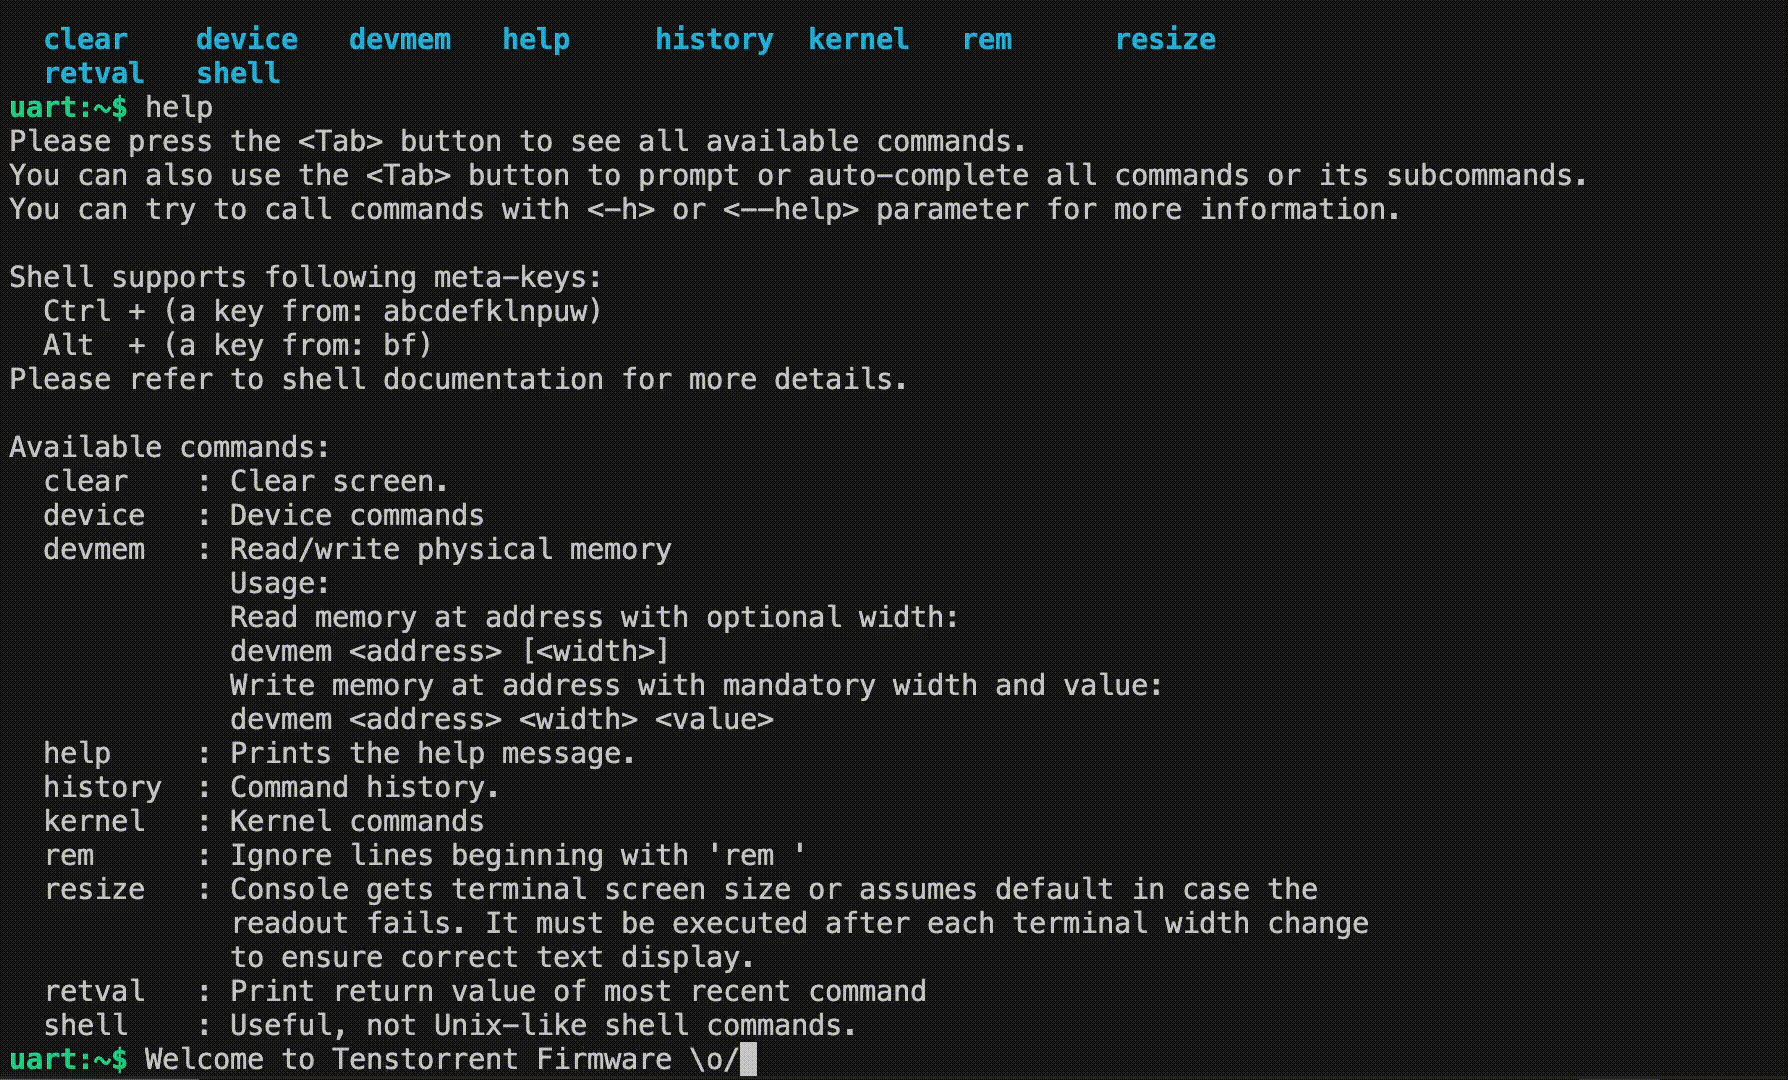
System firmware for Tenstorrent hardware. Low-level system initialization and control firmware that runs on-device.
luwen
officialTenstorrent system interface library written in Rust. Low-level Rust bindings for communicating with and managing TT hardware.
4 previous releases
tt-tvm
officialTVM for Tenstorrent ASICs. Brings the Apache TVM compiler stack to Tenstorrent hardware, enabling model compilation from TensorFlow, PyTorch, ONNX, and more.
tensix-isa-simulator
officialISA-level simulator for the Tensix compute engine. Simulates the matrix, vector, and scalar units inside each Tensix core.
tt-torch
officialFrontend integration for PyTorch with tt-mlir. Compile PyTorch models directly to Tenstorrent hardware via torch.compile integration.
tt-firmware
officialTenstorrent firmware repository. Board management and control firmware for Tenstorrent accelerator cards.
tt-installer
officialInstall the complete Tenstorrent software stack with one command. Handles drivers, firmware, Python environment, and SDK setup automatically.
tt-exalens
officialLow-level hardware debugger for Tenstorrent devices. Inspect register state, memory contents, and kernel execution at the hardware level.
4 previous releases
tt-blacksmith
officialOptimized training recipes for a variety of ML models on Tenstorrent hardware, powered by the TT-Forge compiler stack. Reference implementations for fine-tuning and training from scratch.
vllm-tt-plugin
officialTenstorrent backend for vLLM, built on vLLM's standard plugin mechanism — install it alongside vLLM and TT hardware registers itself as a platform whenever `ttnn` is importable. Self-contained: model registration, platform detection, scheduling, worker execution, model loading, async decode, and data-parallel/multi-lane execution all live in the plugin, so nothing Tenstorrent-specific has to land in vLLM core.
tt-npe
official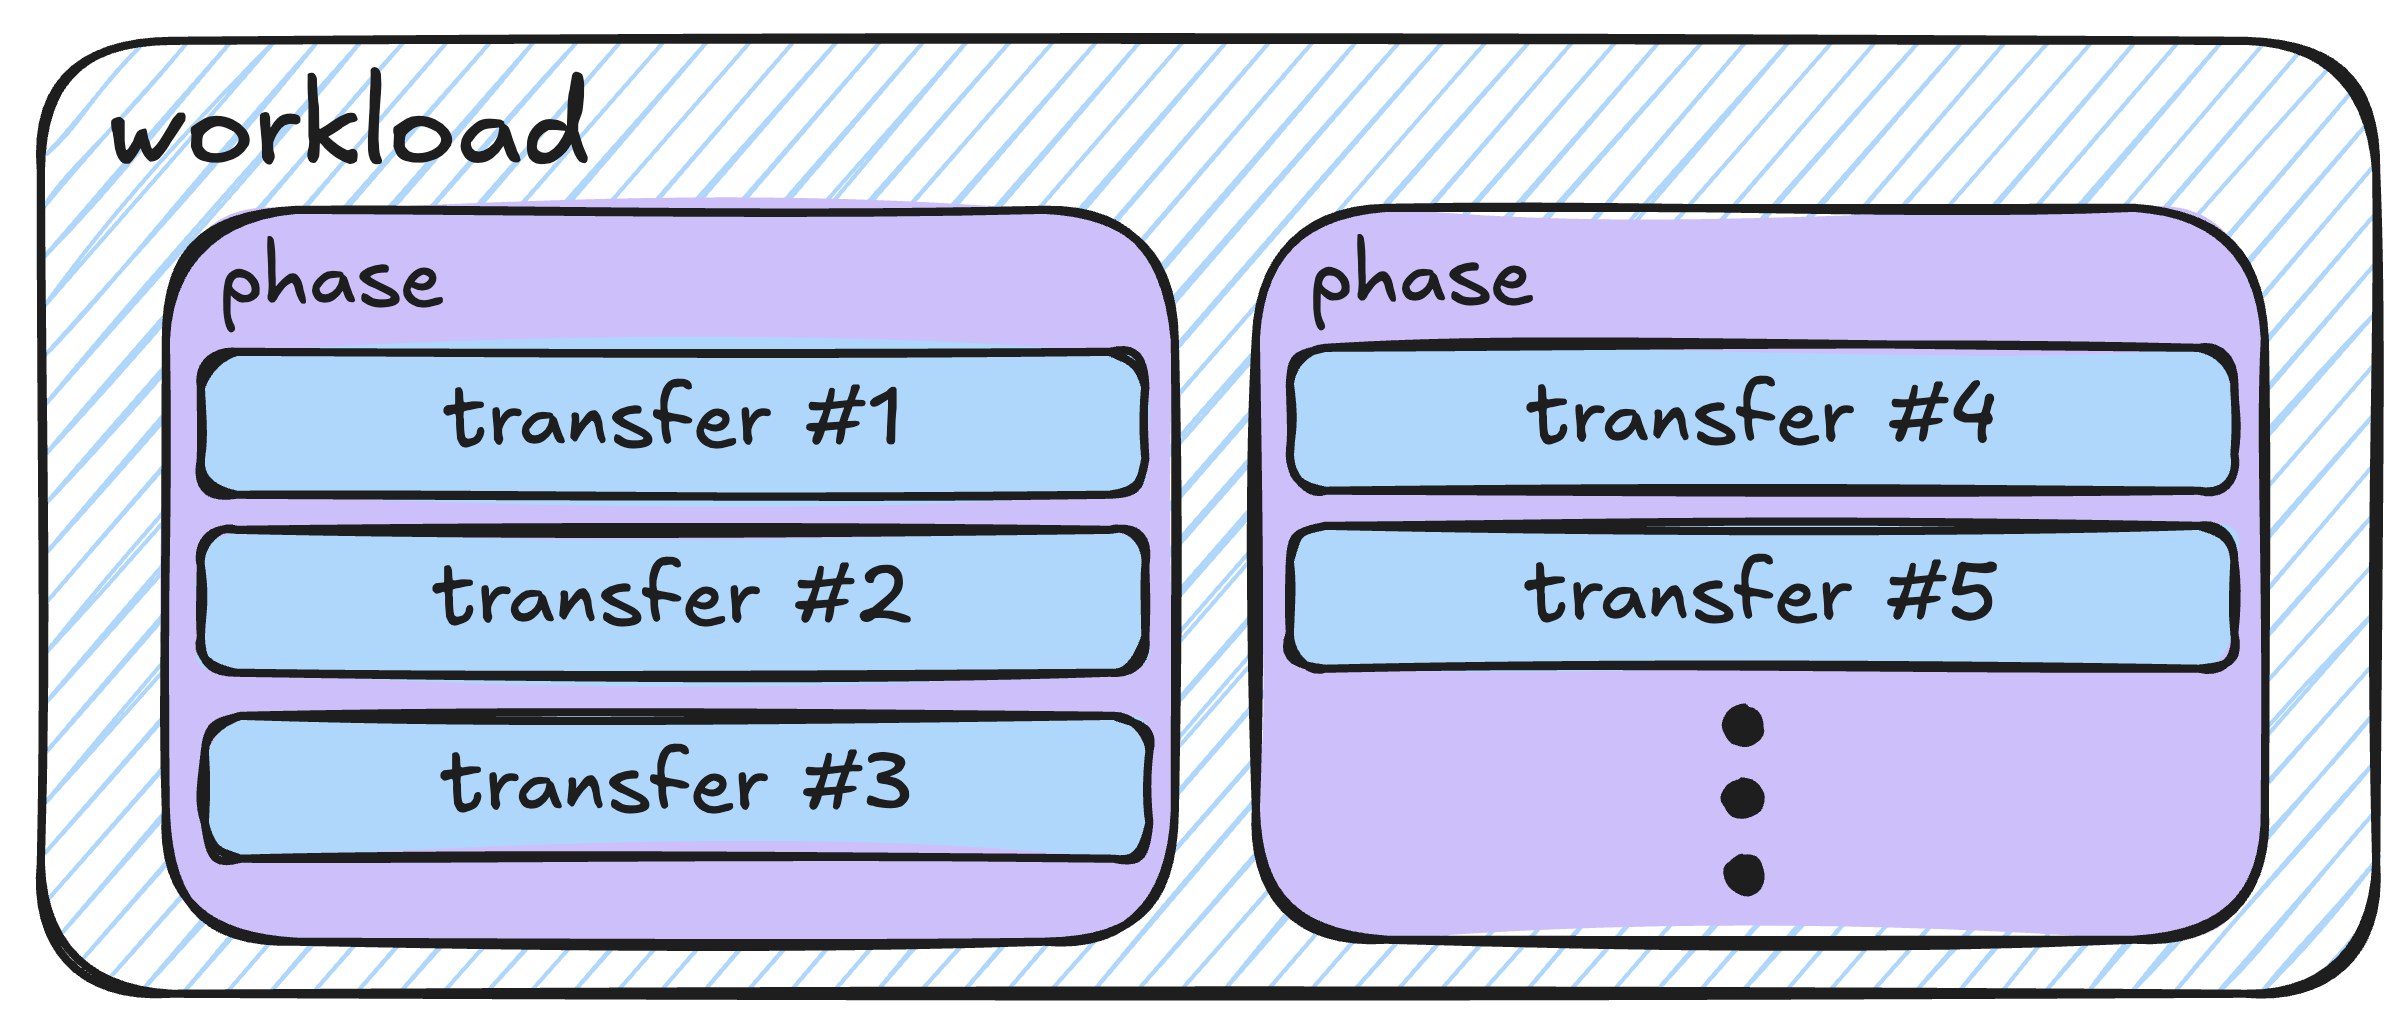
Network-on-chip Performance Estimator for Tenstorrent Tensix-based devices. Model and estimate NoC utilization before running kernels on hardware.
tt-topology
official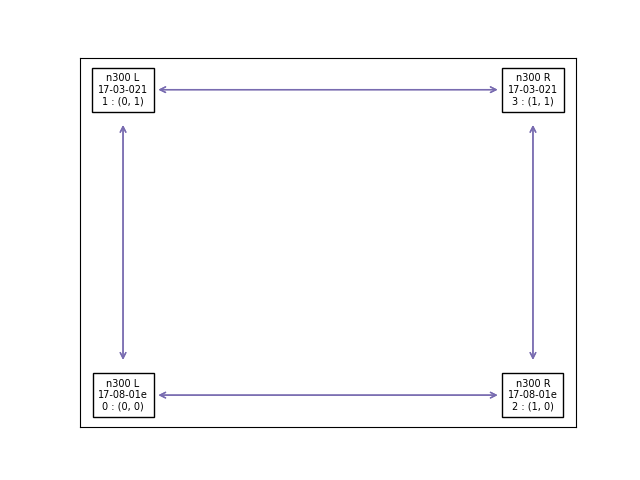
Configure Ethernet routing on multi-card Tenstorrent systems. Flash NB cards to use specific ETH routing configurations for scale-out deployments.
4 previous releases
📋 Changelog
# Changelog

All notable changes to this project will be documented in this file.

The format is based on [Keep a Changelog](https://keepachangelog.com/en/1.0.0/),
and this project adheres to [Semantic Versioning](https://semver.org/spec/v2.0.0.html).

## 1.2.11 - 17/06/2025

### Updated

- Updated mesh coord generation to be connection type agnostic
- Added failure and exit if mesh type detected, but not enough connections
- Added warning in README about lack of supoort for BH and 6U boards

## 1.2.10 - 05/06/2025

### Updated

- Bumped tt-tools-common version to fix driver version check for compatability with tt-kmd 2.0.0

## 1.2.9 - 30/05/2025

### Updated

- Bug fix for https://github.com/tenstorrent/tt-topology/issues/39. Now the tool will use a DFS longest path to determine a linear layout if its not a fully connected graph.
- Updated initial device detection - now it needs full noc access for octopus and list options

## 1.2.8 - 08/05/2025

### Updated

- Fixed issue where tool would fail when PCI interfaces don't start from ID 0
- Now using actual PCI interface IDs from devices instead of assuming sequential numbering

## 1.2.7 - 07/05/2025

### Updated

- Use tools-common 1.4.15
- Use type checking in octopus reset

## 1.2.6 - 05/05/2025

### Updated

- Bug fix: added "ignore-eth" flag to first chip detect to avoid eth training loops forever and truly detect pcie only chips
- Chore: bumped luwen

## 1.2.5 - 15/04/2025

### Updated

- When flashing to isolated mode, we now flash the WH ethernet ports to a disabled state,
  in order to prevent their use.

## 1.2.4 - 02/04/2025

### Updated

- You can now run `tt-topology -l isolated` to flash cards to the default (non-connected) state
- Users are now warned about missing or loose cables

## 1.2.3 - 21/03/2025

### Fixed

- Bumped luwen (0.6.2 -> 0.6.3) to include eth version check bug for TG setup

## 1.2.2 - 13/03/2025

### Fixed

- Bumped luwen version to make it more robust against eth fw updates

## 1.2.1 - 13/03/2025

### Fixed

- Moved the spi reads after the reset to increase stability during M3 L2R copy
- Bumped luwen version

## 1.2.0 - 06/03/2025

### Fixed

- Updated how local eth board info is calculated to make it agnostic to eth fw version
- bumped tt-tools-common version
- Added traceback printing when catching exceptions in main.

## 1.1.5 - 14/05/2024

### Updated

- Bumped luwen (0.3.8) and tt_tools_common (1.4.3) lib versions
- Removed unused python libraries

## 1.1.4 - 25/03/2024

### Fixed
- Changed detect_chips with detect_chips_with_callback to enable detailed debug info.

## 1.1.3 - 22/03/2024

### Fixed
- Bumped tt-tools-common version to avoid pip discrepancy.

## 1.1.2 - 22/03/2024

### Fixed
- Fixed command line bug when no args are provided.

## 1.1.1 - 21/03/2024

### Fixed
- Fixed reference to pyluwen lib

## 1.1.0 - 12/03/2024

### Added
- Octopus Configuration (4 n150s connected to 1 galaxy)


## 1.0.2 - 12/03/2024

### Fixed
- Dependency bug with tt_tools
SFPI
officialTenstorrent SFPU programming interface — TT-enhanced RISC-V GCC and binutils plus header files for programming the Tensix SFPU (vector engine) from kernel code. The compiler toolchain underneath TT-Metalium's SFPU ops.
4 previous releases
Tenstorrent Skills
officialOfficial agent-skill marketplace for Claude Code and Codex, aimed at tt-metal, TTNN, Metalium, and model work. A `tt-skills` finder plugin recommends and installs the rest with your approval: `tt-autodebug` (AutoDebug/AutoTriage investigate bugs and hangs, AutoFix repairs them), `tt-model-bringup` (an eleven-stage path from a Hugging Face decoder through TTNN to vLLM benchmarking), `tt-review-skills` (PR review for TTNN, Metalium, LLK, multi-chip, and L1 changes, also pinnable in gh-aw workflows), and `tt-debug-tools` (drives tt-triage, dprint, and watcher).
tt-toplike
official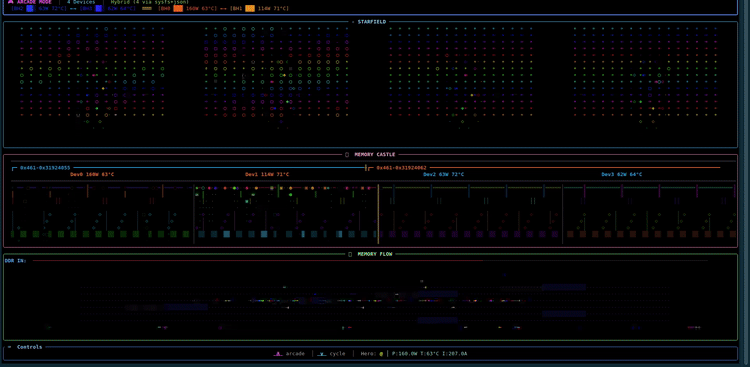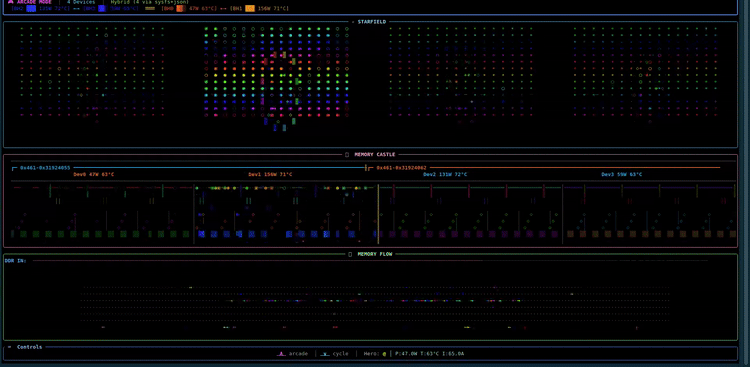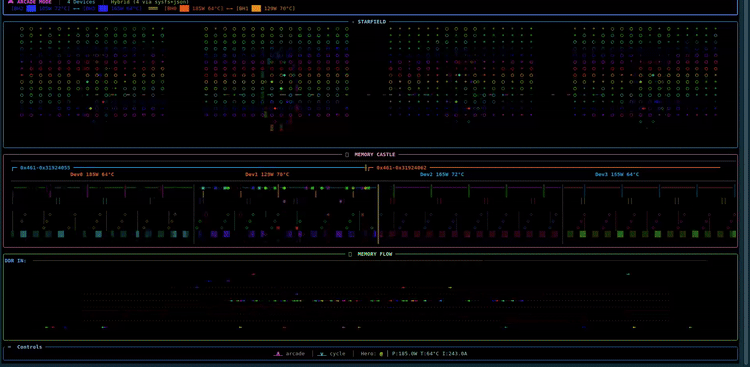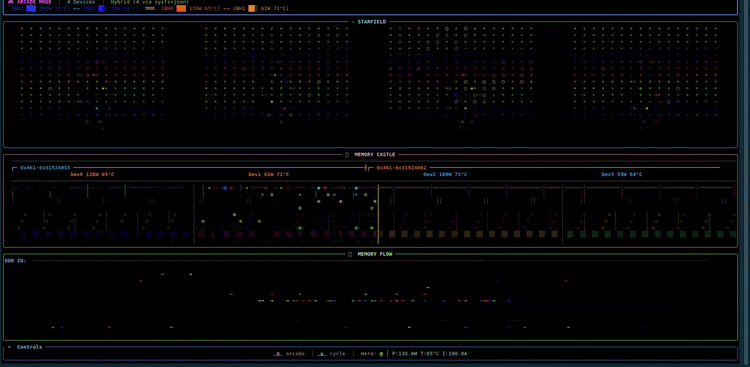
A vibrant htop-style visualizer for Tenstorrent hardware written in Rust. Real-time process and utilization view for TT accelerators.
4 previous releases
📋 Changelog
# Changelog

The **canonical, complete release log lives in [`debian/changelog`](debian/changelog)** —
that's the file the `.deb` packages are built from and where every release is
recorded in full. This file is a friendly pointer plus a summary of the most
recent releases; it deliberately does not duplicate the whole history.

To see everything:

```bash
less debian/changelog          # full history
git tag                        # released versions
```

## Recent releases

Releases 0.11.1 through 0.13.9 are recorded only in `debian/changelog`; this
list is a summary and is not kept for every release.

### 0.13.17
- **Fix**: review findings on the lanes and atmosphere. No false flares when stats drop
  out or lanes reorder, a fresh load clock after a reload, a forge that starts over
  per model, and trainer discovery moved off the render thread (with retries for
  a Python script that imports `ttml` late). The atmosphere's smoothed gauges
  restart when another model is featured, and a reused pid no longer keeps the
  previous training run attached or its cached `ttml` answer.

### 0.13.16
- **Change**: chips stay the ones a server holds open; `TT_METAL_VISIBLE_DEVICES`
  is not used to narrow them (it indexes the runtime's order, not the host's).
- **Add**: demo scenes `arcade-lanes` and `inference-music`.

### 0.13.14
- **Fix**: the MiniMax-Music3 audio server shows jobs in flight and finished
  requests (from `/v1/health`) and is labelled `MiniMax-Music3` (from
  `/v1/models`).

### 0.13.13
- **Fix**: a model server with no `/health` route (the MiniMax-Music3 audio
  server) shows as serving. The Inference view also asks `/v1/health`.

### 0.13.12
- **Add**: Arcade activity lanes. While a training run, a model load or a model
  serving is active, the top starfield rows show up to two lanes (name,
  progress, rate, `[t]`/`[i]` to open the full view); the stars tint by kind and
  flare per step or request.
- **Add**: an atmosphere behind the Inference view's snake: a forge while
  loading, a storm while a prompt is read, an aurora with comets, rain and a
  KV-cache tide while generating, a forming canvas for diffusion jobs.
- **Fix**: models launched from a weights path are labelled by their run
  (`rag-gate-27b`), not `model-dir` or `bundle`.

### 0.13.11
- **Fix**: on hosts that run the STIG or CIS audit rules, tt-toplike wrote
  4 to 6 GB of audit log per hour. The process scans opened `/proc/<pid>`
  files that only the owning user can read, and each refused open became an
  audit event. The scans now check ownership first and remember pids that
  refuse access. Thanks to Eugene Valkov, who reported it and wrote the first
  fix (issue 35).

### 0.13.10
- **Add**: Inference view (`i`) shows the port and chips each model runs on,
  for example `:8000 · chips 0,1`, on each roster row or in a header line for a
  single model.
- **Add**: `--tt-smi-reset-behavior` (`ignore`, `inform` default, `dazzle`,
  `demo`). A `tt-smi -r` in another terminal
tt-forge-models
officialA shared repository of model implementations used across TT-Forge frontends — a single source of truth for the models used in testing and benchmarking, rather than duplicating them across frontend repos.
tt-flash
officialTenstorrent firmware update utility. Flash new firmware onto Tenstorrent accelerator cards from the command line.
4 previous releases
📋 Changelog
# Changelog

All notable changes to this project will be documented in this file.

The format is based on [Keep a Changelog](https://keepachangelog.com/en/1.0.0/),
and this project adheres to [Semantic Versioning](https://semver.org/spec/v2.0.0.html).

## Unreleased

### Added

- `flash`: `--update-boot-images` writes the bundle's bootloader and recovery
  images even when the board already holds the same ones, for provisioning and
  board recovery.

### Changed

- `flash`: the boot-critical images (`cmfw`, `safeimg`, `safetail`, `failover`)
  and the ROM and failover descriptor tables are now left alone when the board
  already holds the same content, so a routine update no longer opens a
  power-loss window on the path by which a board boots at all. Whether an image
  is the same is decided by the SHA-256 and key hash that `imgtool` records in
  it, because signing is not reproducible: two builds of the same source differ
  only in the trailing signature. Pass `--update-boot-images` for the previous
  behaviour of writing them unconditionally.

### Fixed

- `flash`: a P300 chip running recovery firmware publishes no board id, so the
  pairing check filed it as not a P300, left its sibling alone in a group of
  one, and dropped both halves of the card from the flash list -- refusing the
  board because of the chip that most needed flashing. Such a chip is now
  identified by its PCI subsystem id, which carries the same UPI whatever the
  chip is running.
- `boot_fs`: `tt_boot_fs_fd.image_tag_str()` compared each `c_uint8` tag byte
  against the string `"\0"`, which never matched, so NUL padding was included in
  the decoded tag. Tags shorter than 8 bytes (e.g. `cmfw`) now compare correctly.
  This makes `read_tag` robust across the multi-table boot filesystem layout
  (ROM, failover, and mutable descriptor tables).

## 3.4.0 - 30/07/25

- Bump pyyaml 6.0.1 -> 6.0.2
- Improve error message formatting
- No longer have to use --force for flashing BH cards

## 3.3.5 - 03/07/25

- Bump luwen 0.7.3 -> 0.7.5

## 3.3.4 - 02/07/25

- Bump tt-tools-common 1.4.16 -> 1.4.17
- Bump luwen 0.6.4 -> 0.7.3

## 3.3.3 - 05/06/2025

- Bumped tt-tools-common version to fix driver version check for compatability with tt-kmd 2.0.0

## 3.3.2 - 14/05/2025

- Bump tt-tools-common version to latest

## 3.2.0 - 12/03/2025

### Updated

- luwen version bump to bring inline with tt-smi; provides stability fixes

## 3.1.3 - 06/03/2025

### Added

- luwen version bump to include bh arc init checks

## 3.1.2 - 28/02/2025

### Added

- Support for more BH cards: p100a, p150, and p150c

## 3.1.1 - 06/01/2025

### Updated

- Bumped luwen version to accomodate Maturin updates

## 3.1.0 - 29/10/2024

### Added

- Support for flashing the BH tt-boot-fs file format
- Bumped luwen version to 0.4.6 to allow resets when chip is inaccessible

## 3.0.2 - 17/10/2024

### Fixed
- Unbound variable when exception is thrown when getting current fw-version

## 3.0.1 - 16/10/2024

### Changed
- B
tt-example-apps
officialEnd-to-end AI applications running on Tenstorrent AI accelerators. Complete application examples from retrieval-augmented generation to image generation pipelines.
tt-perf-report
official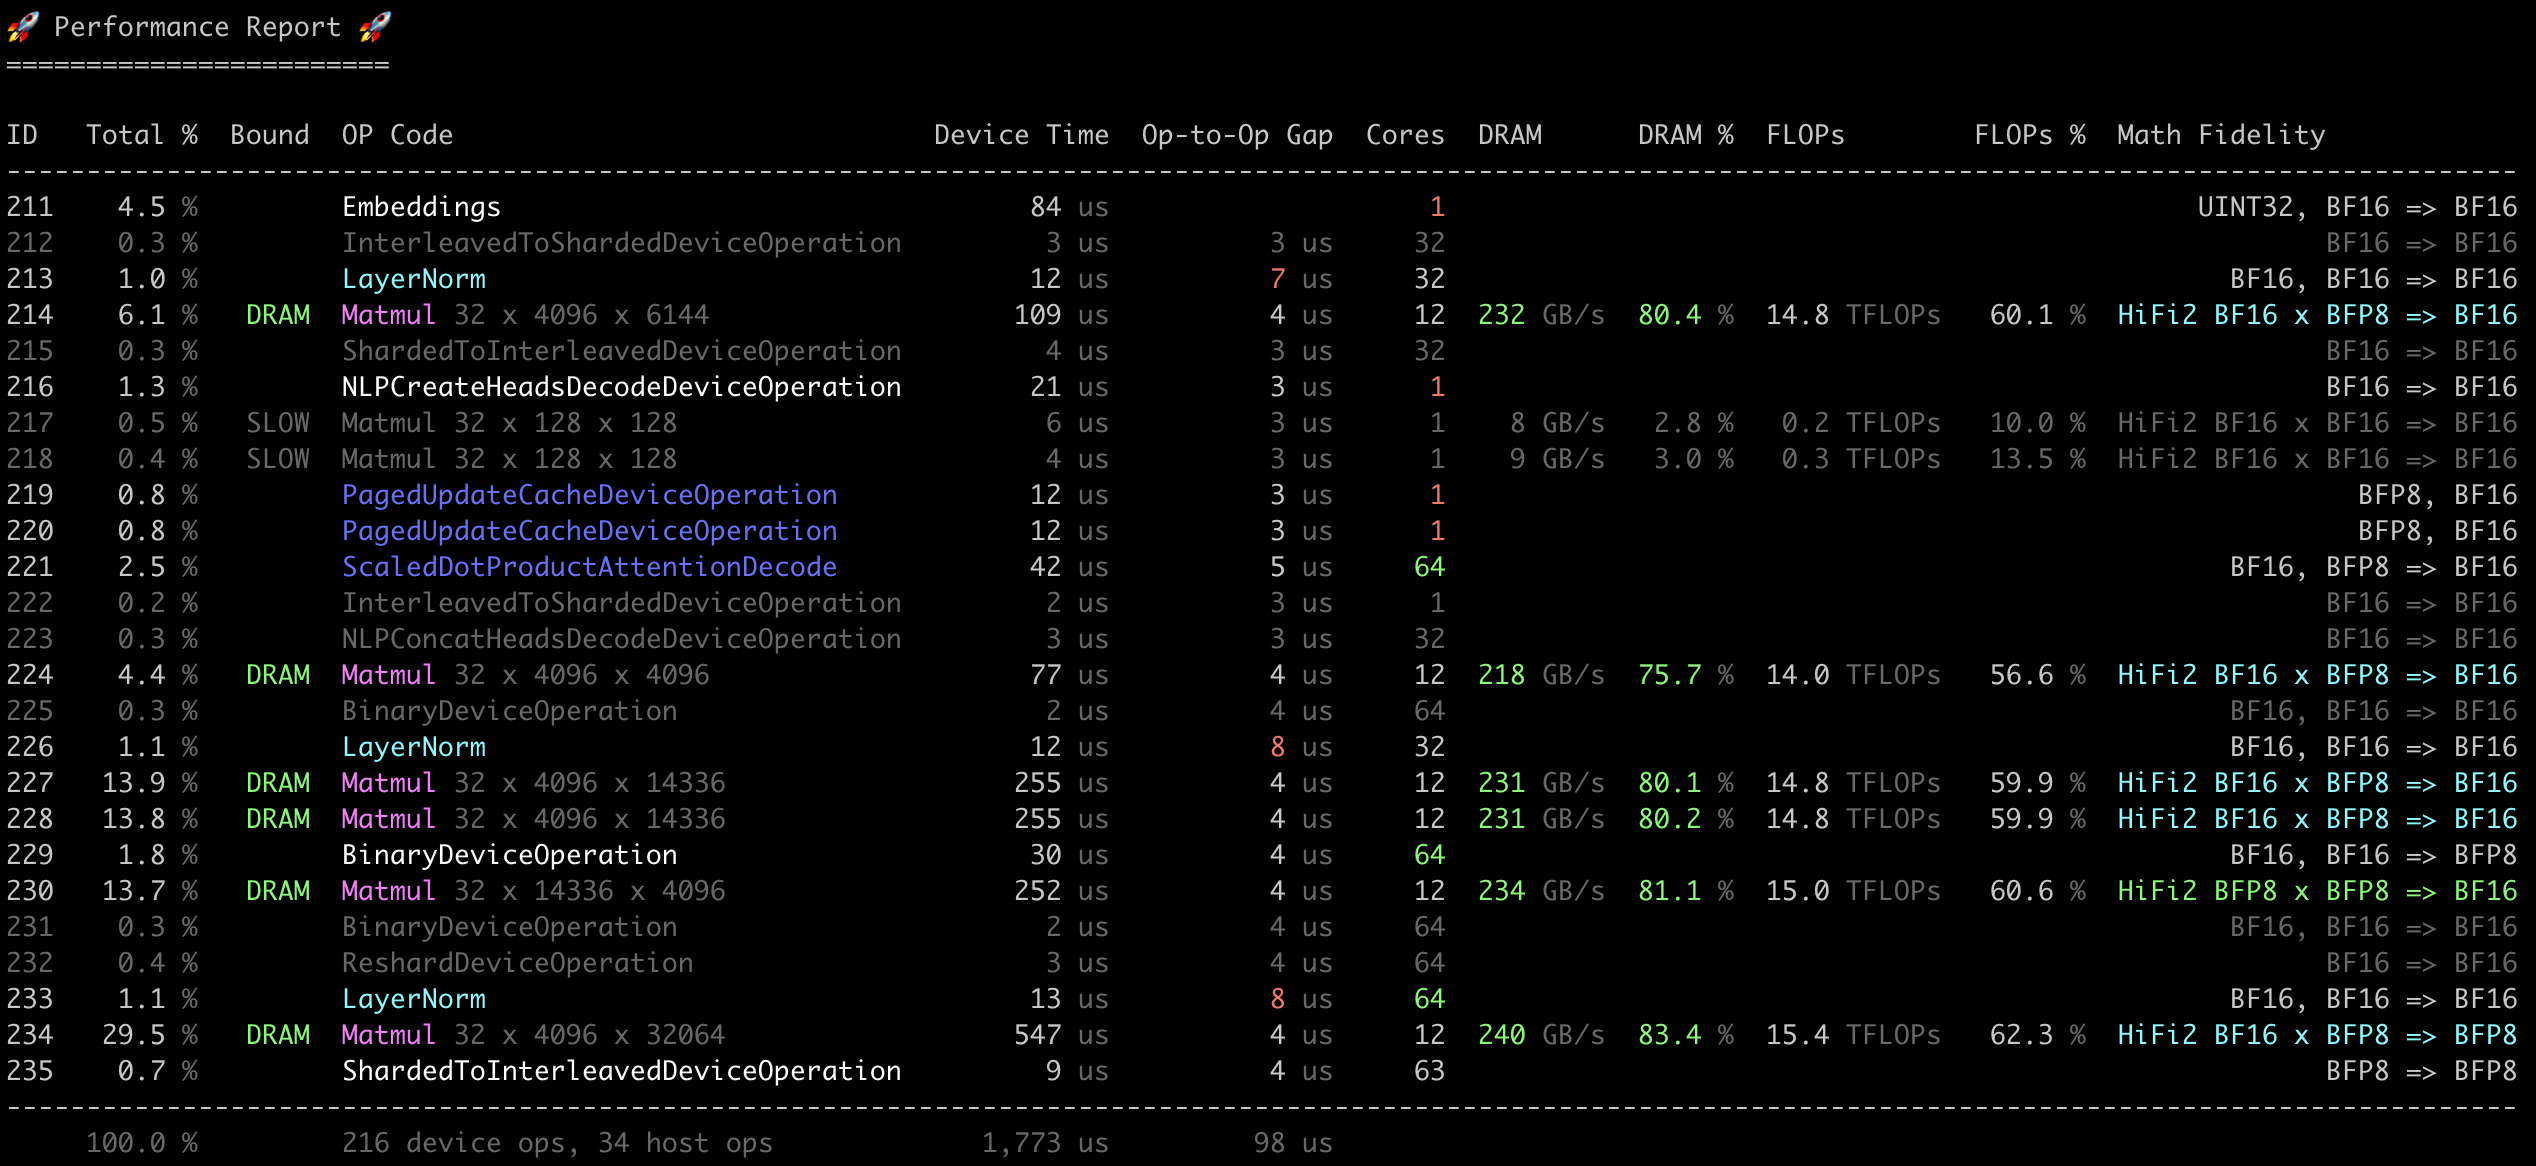
Performance report analysis tool for Tenstorrent Metal operations — analyzes perf traces to surface throughput, bottlenecks, and optimization opportunities.
tt-vscode-toolkit
official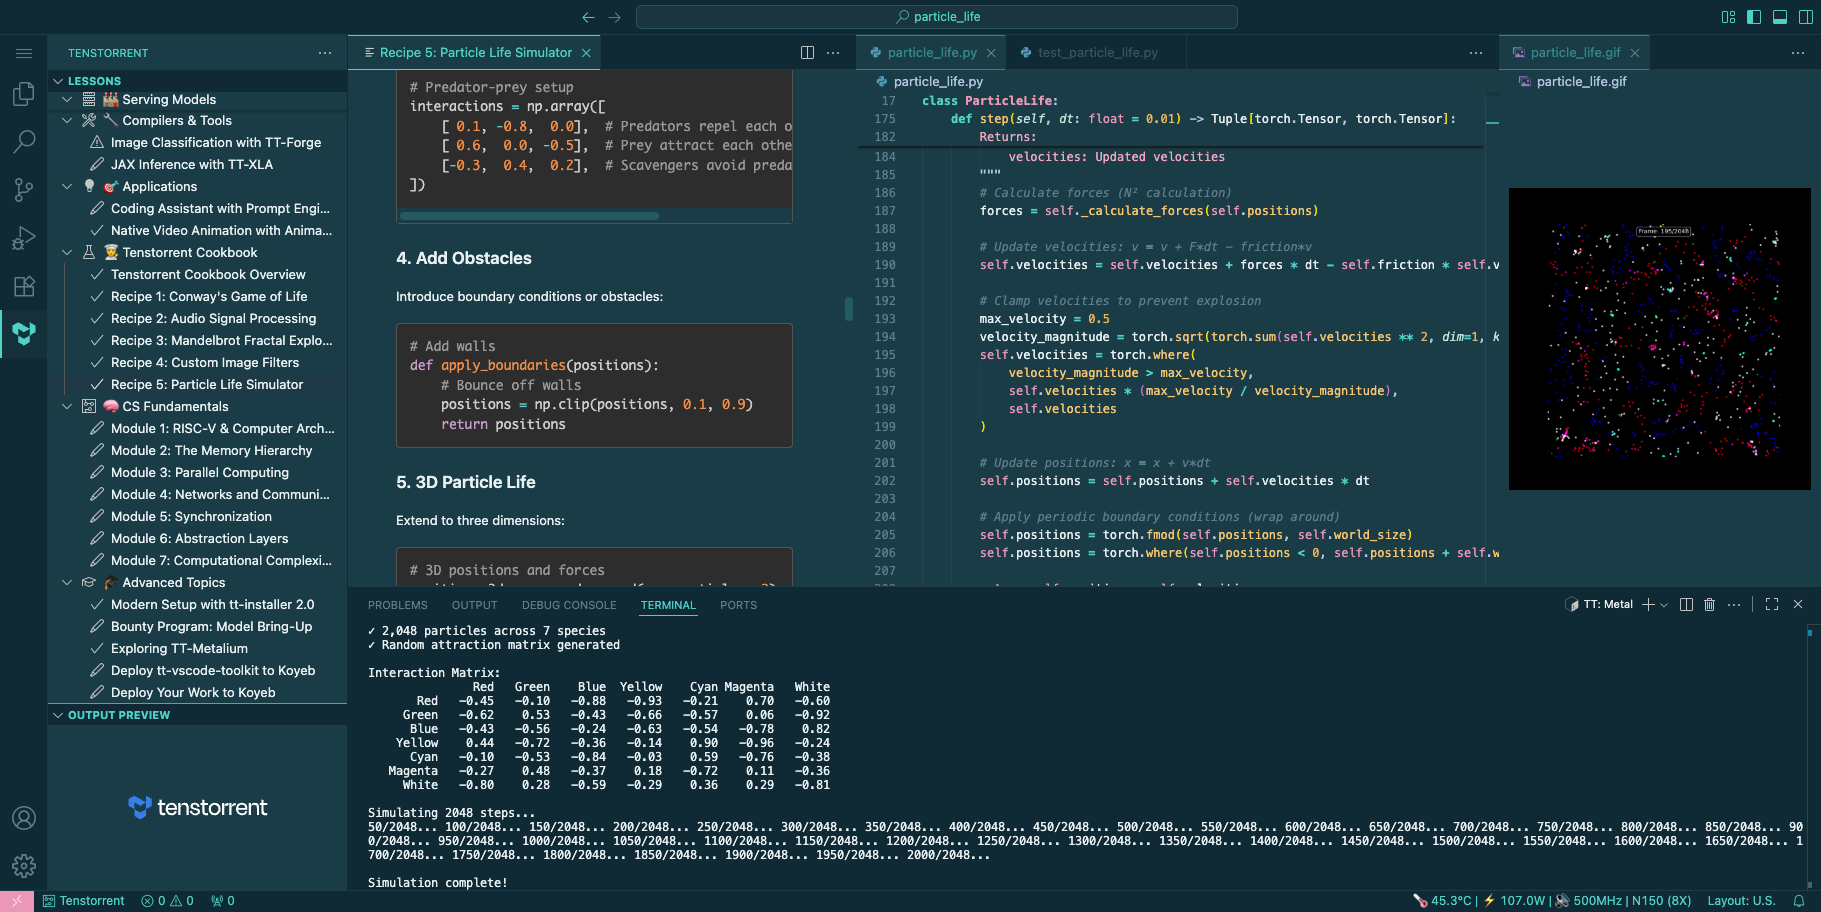
48 interactive lessons covering the full Tenstorrent developer path — from hardware detection to custom training — with click-to-run commands and hardware auto-detection. Available in VSCode and code-server.
📋 Changelog
# Changelog

All notable changes to the TT-VSCode-Toolkit will be documented in this file.

The format is based on [Keep a Changelog](https://keepachangelog.com/en/1.0.0/),
and this project adheres to [Semantic Versioning](https://semver.org/spec/v2.0.0.html).

---

## [0.1.29] - 2026-09-07

Correctness pass on what a TT-QuietBox 2 actually ships. The three-path venv
activation blocks added in 0.1.25 offered `~/.tenstorrent-venv` as the "QB2
pre-installed" environment for TT-NN and vLLM, and described a QB2 as "4
independent single-chip devices". Neither claim is true, and this release
corrects both everywhere they were found — including in this repo's own
`CLAUDE.md`, `llms.txt`, and two lessons outside the original diff
(`content/pages/FAQ.md`, `monkeypatch-ttnn.md`) that had never been touched
by the earlier topology/venv corrections this built on.

Verified against `tt-installer`'s `install.m4`, the published `tt-metalium`/
`tt-metalium-models` GHCR image configs, `tt-inference-server`'s `run.py`,
and tt-metal `main` — plus live end-to-end testing on a QB2-equivalent
board — rather than other Tenstorrent docs, which largely descend from the
same stale source note this release supersedes.

### Fixed

**`~/.tenstorrent-venv` is not a TT-NN or vLLM environment.** `tt-installer`
only ever installs `tt-smi`, `tt-flash` and (opt-in) `tt-topology` into it, so
`import ttnn` and `import vllm` both fail there. TT-NN lives **only** inside
the TT-Metalium container (`tt-metalium`, where `python3` is
`/opt/venv/bin/python3`); vLLM runs in a container `tt-inference-server`
launches. Corrected everywhere this was asserted or assumed:
- The "QB2 pre-installed image" activation line in all 11 TT-NN blocks across
  `explore-metalium`, `video-generation-ttmetal`, `animatediff-video-generation`,
  `cookbook-game-of-life`, `cookbook-mandelbrot`, `cookbook-particle-life`,
  `cookbook-image-filters`, `cookbook-audio-processor`, and the four lessons
  that used it as a premise (`lfs-00-intro`, `lfs-05-train-and-run`,
  `ct1-understanding-training`, `ct4-finetuning-basics` — their `ttml`-needs-a-
  source-tree conclusions were already correct; only the premise changed).
- `tt-installer`'s own "may not include the container wrapper" framing —
  backwards: a QB2 *has* the wrapper (it's the only way to reach TT-NN) and
  has no host-side TT-NN. Its "Test TT-Metalium" button and pytest demo
  example were also broken independent of this: missing `-c` (so `bash` tried
  to run the whole command string as a filename), a bare `ttnn.__version__`
  that doesn't exist on the built package (now `getattr(ttnn, "__version__",
  "import OK")`), and — for the demo — the wrong container and a Blackhole
  demo path that moved in tt-metal's January 2026 reorg (now
  `tt-metalium-models` + `models/demos/vision/segmentation/ufld_v2/blackhole`,
  with `--install-metalium-models-container` named as off-by-default).
- `vllm-production`'s new "On a QB2 — read this first" section (pointing a
tt-rpm
officialCycle-level, execution-driven RISC-V CPU performance model built on Sparta (MAP) with Whisper supplying functional execution, so it runs real ELF binaries — CoreMark, Dhrystone — to completion. The pipeline is YAML-configurable across in-order/out-of-order execution, issue policy, execute granularity, write-port arbitration, and bypass paths, with a modeled L1 I$/D$ plus optional unified L2, per-unit logging, stats reports, and Konata pipeline visualization.
tt-model
officialDistributes model bundles over the Hugging Face Hub and serves them on Tenstorrent cards — `tt-model serve <org>/<model>` pulls and installs a bundle, then launches the Tenstorrent vLLM plugin's OpenAI-compatible server. A bundle carries or pins its own serving stack, either as an OCI container image (v5.1, the supported path) or as a per-model venv built from pinned wheels (v6 thin, beta), and records the weights' upstream HF repo instead of shipping them, so the host needs only a card and its firmware. Formerly `tt-kernel` / tt-kernel-package-manager, when bundles were precompiled tt-metal kernel caches. Explicitly experimental — the bundle format and APIs may change without notice.
tt-cli
officialSingle entry point to the Tenstorrent software stack: `tt update` converges a machine onto the CI-tested "golden" version set, `tt device` covers status/info/reset, and `tt model`/`tt serve` pull weights and bring up tt-inference-server. Commands either run natively or delegate to tt-smi, tt-flash, and tt-installer behind a stable interface, with `--json` output and documented exit codes on every command. Beta software — breaking changes are expected — installed from PyPI as `tenstorrent` (`uv tool install tenstorrent`, or any pip-compatible tool). Usage telemetry is opt-in.
tt-tools-common
officialShared helper library of common utilities used across Tenstorrent system tools such as tt-smi, tt-flash, and tt-topology. A dependency rather than a standalone tool.
4 previous releases
📋 Changelog
# Changelog

All notable changes to this project will be documented in this file.

The format is based on [Keep a Changelog](https://keepachangelog.com/en/1.0.0/),
and this project adheres to [Semantic Versioning](https://semver.org/spec/v2.0.0.html).

## 1.4.17 - 02/07/2025

### Changed
- Loosened requirements on pyproject.toml to make it more compatible in different venvs

## 1.4.15 - 05/05/2025

### Changed
- parse\_reset\_json now returns a ResetInput with stricter typing

## 1.4.14 - 04/02/2025

### Added
- New flags in reset config file generation to disable sw\_version reporting

## 1.4.13 - 23/1/2025

- Removed nr\_hugepages count from compatibility, as hugepages allocation is tricky
  and deserves its own widget elsewhere.

## 1.4.12 - 16/1/2025

- Added TTHostCompatibilityMenu to replace Host Info and Compatibility boxes
- Added a count of nr\_hugepages to the TTHostCompatibilityMenu

## 1.4.11 - 30/12/2025

- Updated Luwen version to fix Maturin issue

## 1.4.10 - 16/12/2024

### Changed
- detect\_chips\_with\_callback now takes a print\_status arg

## 1.4.9 - 11/12/2024

### Changed
- A failed reset now results in a fail exit code on BH

## 1.4.8 - 11/10/2024

### Changed
- Updated reset completion logic to handle the case where the bmfw needs to upgrade itself

## 1.4.7 - 11/10/2024

### Added
- Implemented m3 reset option for Blackhole

### Fixed
- Fixed crash during driver version dection when the "extraversion" field is used
    - i.e. 1.28-bh

## 1.4.6 - 17/07/2024

### Added
- Reset support of Blackhole

## 1.4.5 - 11/07/2024

### Added
- Bump pyluwen library version (v0.3.8 -> v0.3.11)
- Moved pyluwen v0.3.11 to optional dependencies in pyproject.toml

## 1.4.4 - 21/06/2024

### Added
- Version bump of python dependencies in pyproject.toml (dependabot)
    - requests (2.31.0 -> 2.32.0)
    - tqdm (4.66.1 -> 4.66.3)
- Pydantic library version bump (1.* -> >=1.2) to resolve: [TT-SMI issue #27](https://github.com/tenstorrent/tt-smi/issues/27)

## 1.4.3 - 14/05/2024

### Added
- Arm platform check and warning for WH device resets in compatibility menu
- Added check for WH device init after reset and prompt user to reboot host if chips are still non recoverable
- Bumped textual (0.59.0) and luwen (0.3.8) lib versions

## 1.4.2 - 04/04/2024

### Added
- Added "silent" flag to WH and GS resets to make them more versatile for use in other tools

## 1.4.1 - 22/03/2024

### Fixed
- removed pyluwen version to avoid dependency issues in other repos

## 1.4.0 - 19/03/2024

### Added
- detect_device_fallible that will provide feedback about chip state during init

### Fixed
- Update min driver version to 1.26 to perform lds reset
- Reset config file uses dev/tenstorrent id
- Catch JSON errors in reset config parsing
- Make nested dirs when initializing reset config path

## 1.3.0 - 06/03/2024

### Added
- Migrated GS Tensix reset to tools_common
- Migrated all related GS data files
- Functions to fetch arc and eth fw versions from telemetry
tt-low-level-documentation
officialDocumentation for the low-level layer of tt-metal: compute LLK APIs and data movement APIs. The data movement side covers the NOC and overlay on Wormhole and Blackhole; the compute side covers Tensix hardware and expected usage of the LLK APIs. Aimed at op and model writers who need to know what the APIs do and how the hardware behaves underneath them.
tt-operator
officialThe official umbrella Helm chart for running Tenstorrent workloads on Kubernetes. One `helm install` from the OCI registry (`oci://ghcr.io/tenstorrent/helm/tt-operator`) brings up the whole stack as subcharts: Node Feature Discovery to label nodes that carry a Tenstorrent PCI device, `tt-k8s-driver-manager` to own the lifecycle of `tt-kmd`, firmware and `tt-smi` on every node, `tt-fabric-manager` for inter-card and inter-host topology, a Dynamic Resource Allocation driver that publishes cards as `ResourceSlices` (Kubernetes 1.33+), `tt-telemetry` with a Prometheus endpoint, and JobSet plus a PMIx-injecting webhook for multi-node training. Every subchart can be switched off independently, image pins forward to each component, and a `kind` dev loop with fake-labelled nodes lets you work on the controllers without hardware. Releases ship a component version matrix; v0.3.0 (Sep 2026) added a fail-fast check for DRA on older clusters.
tt-emule
officialA C++ software emulator of the Tenstorrent device-level kernel and host APIs. Run tt-metal kernel and host code on a standard x86-64 Linux machine — no Tenstorrent hardware required.
tt-system-tools
officialSystem setup and support utilities for Tenstorrent hardware — hugepages-setup configures the 1GB hugepages TT ASICs need, and tt-oops collects diagnostic data for troubleshooting. Ships as the tenstorrent-tools deb/rpm.
4 previous releases
tt-local-generator
official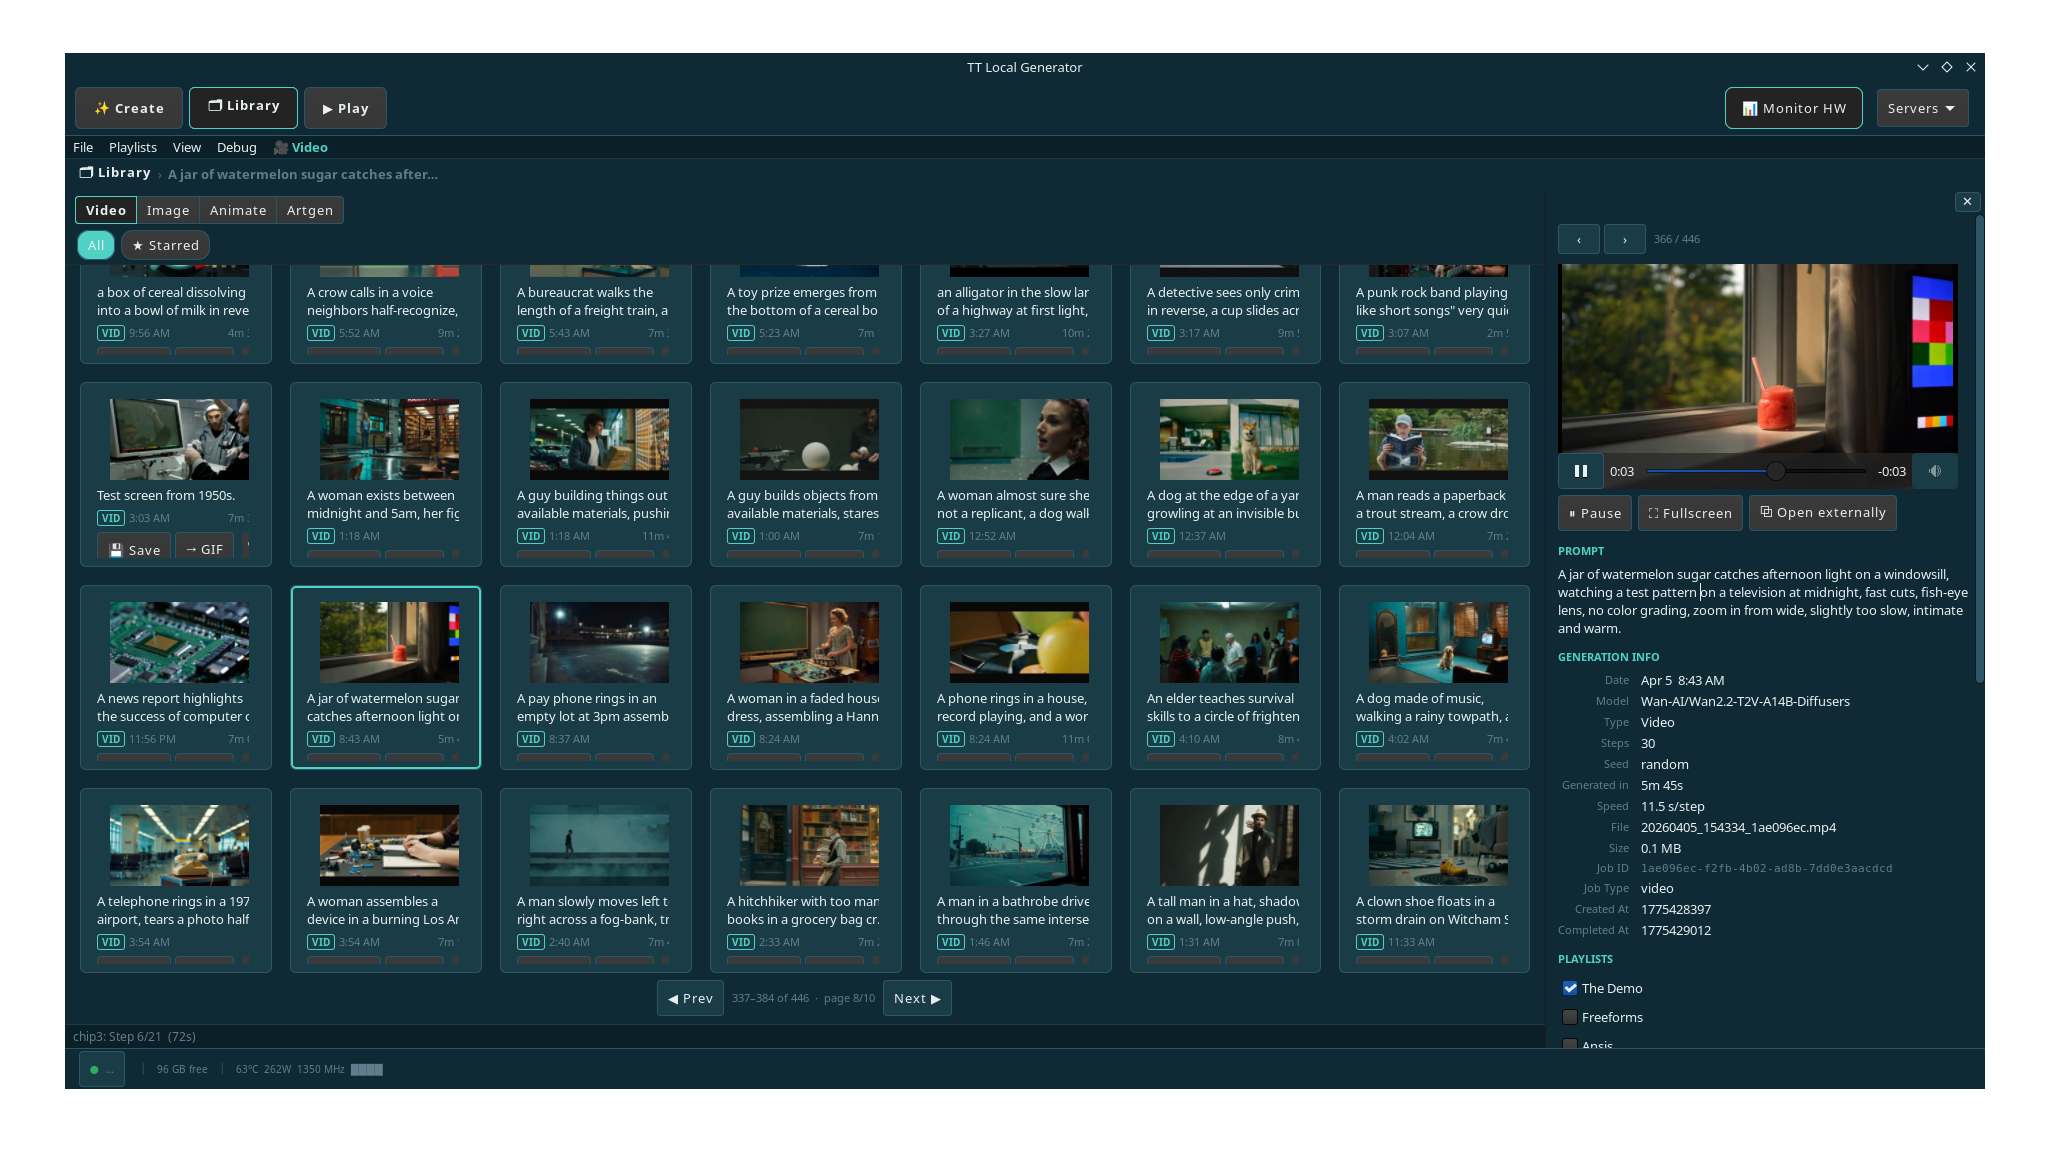
GTK4 desktop app for generating video, images, and generative art locally on Tenstorrent hardware — Wan2.2 text-to-video and character animation, SkyReels-V2, Mochi-1, FLUX.1 text-to-image, and AnimateDiff, plus a three-tier prompt generator (algorithmic, Markov, Qwen3-0.6B) to inspire them. Installs from the Tenstorrent PPA; model weights ship as separate tt-model-* packages, and an MCP server exposes every generator as a tool to Claude Code and other clients.
4 previous releases
tt-burnin
officialCommand-line utility that runs a high power-consumption workload on Tenstorrent devices — used for chip testing, burn-in, and validating a system's power delivery and cooling under sustained load.
4 previous releases
📋 Changelog
# Changelog

All notable changes to this project will be documented in this file.

The format is based on [Keep a Changelog](https://keepachangelog.com/en/1.0.0/),
and this project adheres to [Semantic Versioning](https://semver.org/spec/v2.0.0.html).

## 0.2.2 - 31/07/2024

### Added
- Added glx reset support
- Threaded start and end of burnin to increase burnin speed
- Added prints to indicate which chip we are currently running on
- Added support for bh harvesting

## 0.2.1 - 16/01/2024

### Bug fix
- Fix for https://github.com/tenstorrent/tt-burnin/issues/6
- BH reports asic temperature as a signed 16_16 int unlike GS and WH
- Added missing support to report BH asic temperatre

## 0.2.0 - 29/10/2024

### Added
- BH burnin support

## 0.1.1 - 14/05/2024

### Updated

- Bumped luwen (0.3.8) and tt_tools_common (1.4.3) lib versions

## 0.1.0 - 04/04/2024

First release of opensource tt-burnin

### Added
- GS and WH burnin support
tt-CableGen
official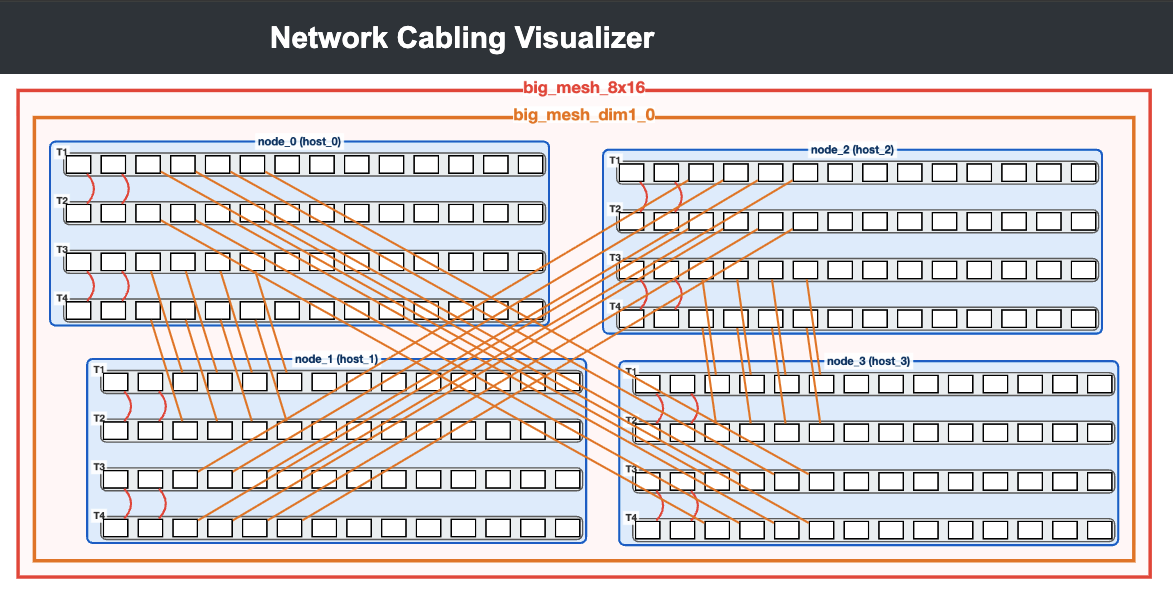
Network cabling visualizer for Tenstorrent scale-out deployments: describe a target topology and it generates and renders how to physically cable multiple Wormhole or Blackhole systems together. Works in a physical-deployment mode with racking information and a logical-hierarchy mode for clustering/pod groupings, with topology import/export and a Docker deployment path.
tt-lab
official★ featuredA whole LLM inference stack you can read end to end: gpt-oss-20b and gpt-oss-120b running on Blackhole with **no TTNN, no TT-Metalium, no vLLM** — the same MXFP4 GGUF file an Ollama user already has, loaded straight into hand-written C++20 BRISC firmware over the kernel driver. Attention, expert matvecs, RMSNorm and SwiGLU all run inside the Tensix tiles, with four-chip runs (120b on a QuietBox 2) exchanging activations over direct PCIe peer-to-peer DMA rather than through the host. Around it sits a self-contained laboratory: a Python-shaped DSL that compiles to SFPU vector kernels, a bit-exact host-side device proxy that simulator and silicon must match logit-for-logit (`--check`), CPU reference inference, `--profile` per-stage device cycles, tensor dumps, and a `ttsim` path so kernel work needs no hardware at all. Roughly 12,000 lines of C++ from prompt to Tensix instruction; the README reports 3.83 ms of device time per 20b token across 32 tiles. One sequence, greedy decoding, no serving endpoint — this is a laboratory for understanding the silicon, not a serving framework, and it takes exclusive ownership of its chips.
tt-animatediff
official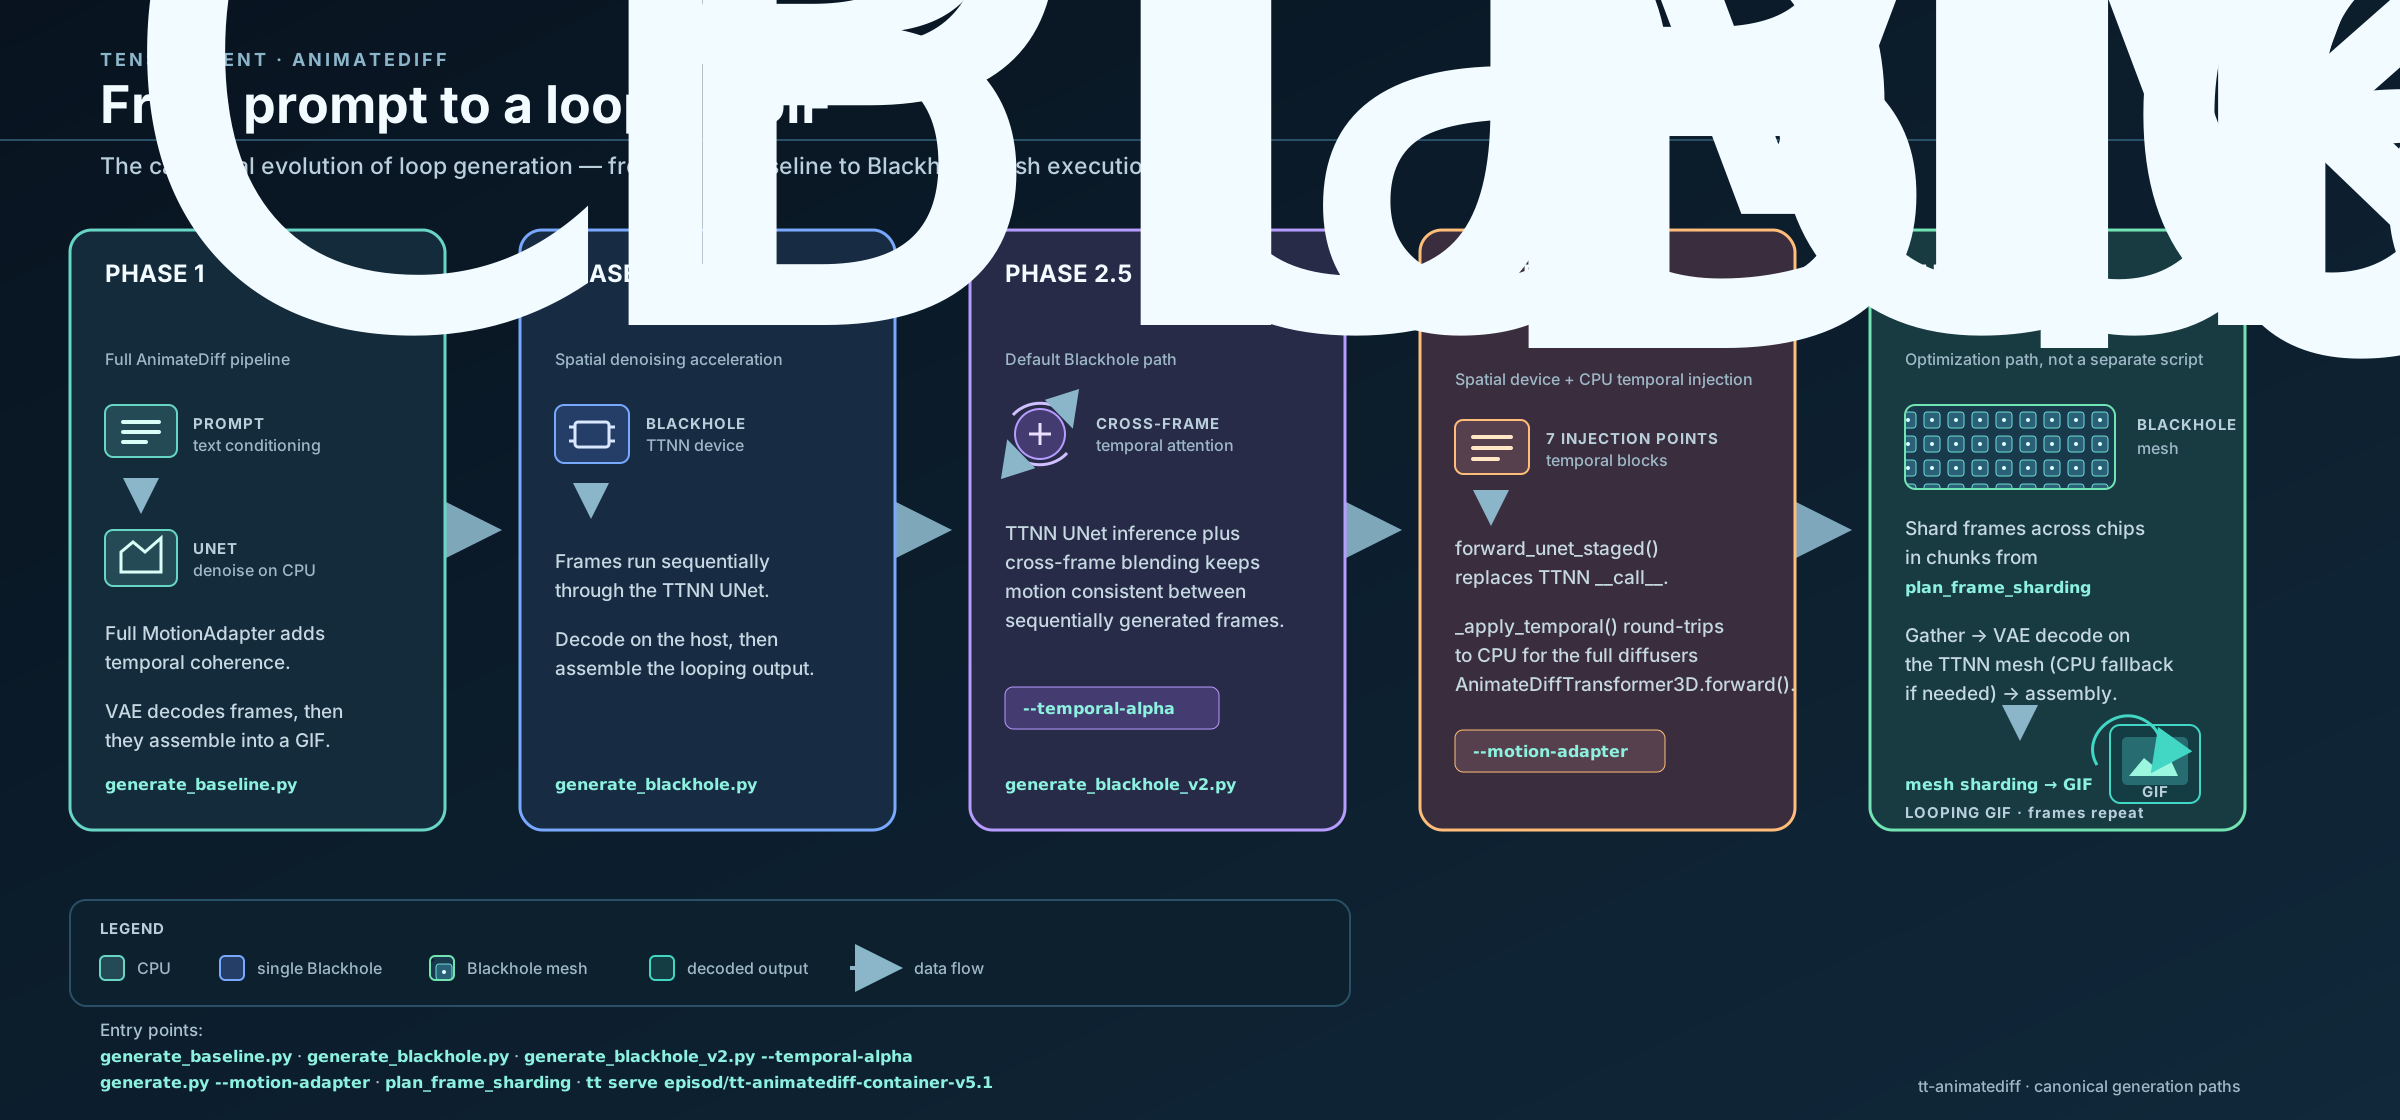
Generates short, temporally coherent animated GIFs using the AnimateDiff model on Tenstorrent hardware. Phase 1 runs the correct SD 1.4 + MotionAdapter architecture on CPU; Phase 2 accelerates spatial denoising on Blackhole using the TTNN UNet. Produces vibrant 8-frame animations in ~15 s/frame on a P300C.
tt-transformers
officialStandalone library of reusable TTNN transformer building blocks (MLP, attention, RMSNorm, RoPE, embedding, LM head, sampling), a model-neutral LLM runtime, and HF-style `from_pretrained()` → `generate()` model implementations, extracted from tt-metal into its own repo. Ships Llama 3.x (1B–70B), Qwen2/2.5/3, Mistral 7B, Phi-4, and DeepSeek R1 Distill across N150, N300, T3K, and Blackhole P150/P150x4. It's a developer preview: every model is marked experimental and pinned to `ttnn==0.77.0`.
📋 Changelog
# Changelog

All notable changes to this project will be documented here.

## 2.0.0.dev0

- `get_device_name` gives a Quasar device the Blackhole names (`P150`, `P300`,
  `P150x4`, `P150x8`, `BHGLX`), so code keyed on those names runs on Quasar.
- Establish `tt-transformers` as the standalone package for TTTv2 modules,
  runtime components, sampling, and twelve experimental model families.
- Add reproducible package builds and CPython 3.10/3.12 host validation.
- Add serialized Wormhole and Blackhole hardware qualification policy.
- Require `ttnn==0.79.0`. Trace capture now acknowledges its allocations to
  ttnn's trace allocation tracker (tenstorrent/tt-metal#53735).
- Rename the warmup override `trace_prefill_warmup_seq_lens` to
  `prefill_warmup_seq_lens`.
- Remove the TTTv1 sampler surface from `tt_transformers.sampling`
  (`generator`, `tt_sampling`, `tt_penalties`). Use
  `tt_transformers.modules.sampling`.
- With any trace mode, a prefill bucket that has no captured trace is served
  eager instead of failing. The first eager request per bucket logs one
  warning, and the load logs which buckets are traced.
- A traced configuration whose warmup lengths leave a servable prefill bucket
  uncompiled is refused at load with a `ValueError`.
- A `max_seq_len` that isn't a prefill bucket boundary now warms the bucket it
  pads to.
- Warmup compiles the prefix-cached variant of every prefill bucket a cached
  prompt can reach, including the top one. A configuration whose `max_seq_len`
  is itself the top bucket gains one such case per sampling path, captured as a
  trace where that bucket is traced; the Llama-3.1-8B N300 trace region grows
  to 70 MB for it.
  The Qwen3-32B T3K trace region grows from 120 MB to 150 MB: its batch-32
  cases gain three prefix-cached 1024 traces and need up to 125 MB.
- Default KV-cache sizing leaves room for the decode page table. A paged KV
  cache narrower than the decode page table is refused at load with a
  `ValueError`, instead of failing on the first decode step.
- On-device greedy sampling breaks an exact logit tie by the lowest token id,
  as host argmax does. Before, the pick depended on the batch slot and could
  vary between runs.
- vLLM serving of Qwen2.5-72B (T3K) and Qwen2.5-7B (N300) prefills prompts in
  the 128-token bucket in fixed waves of four rows, padding a partial wave, and
  warms exactly that shape. Under many concurrent short prompts, time to first
  token falls by more than half against one prompt per pass; a lone short
  prompt waits 85–106 ms longer. Greedy output on these prompts is
  deterministic but is the four-row pass's text, so it differs from one-row
  prefill and from TTTv1: pinned greedy texts for these two models move once.

This is a developer preview. No model is promoted beyond the support status in
`SUPPORT.md` and its example manifest.
TT-QuietBox 2 Guide
officialOfficial setup and onboarding guide for the TT-QuietBox 2 — a compact, liquid-cooled AI workstation with four Blackhole accelerators, an AMD Ryzen CPU, 256GB RAM, and 4TB NVMe. Covers hardware specs, first-boot setup, and hands-on learning paths for running pre-loaded models like Qwen3-32B and serving text, image, video, and speech models via tt-inference-server.
Tenstorrent Developer Blog
official★ featuredTenstorrent's official developer blog at tenstorrent.com/developers. Engineering write-ups from the teams building the stack: serving models with tt-cli and community bundles, prefill and decode disaggregation for agentic workloads, running AnimateDiff on Blackhole, and agentic coding from a Mac backed by a QuietBox. New posts also appear on the Planet.
Cloud-Native Support
officialOfficial documentation hub for running Tenstorrent accelerators on Kubernetes. Centers on tt-operator (the umbrella Helm chart) and covers Node Feature Discovery, kernel-mode driver (tt-kmd) management, firmware flashing, Prometheus telemetry, Fabric Manager topology resolution, Dynamic Resource Allocation, and multi-node scheduling via JobSet and PMIx.
TT Console
official★ featuredBrowser-based cloud console for exploring AI on Tenstorrent hardware. Run LLM inference, image and video generation, and browse the supported model catalog in-browser — backed by Tenstorrent accelerators. Cloud hardware access and advanced workflows (deployments, agents) available in staged rollout.
TenGEMM
officialTensix GEMM performance estimator and visualizer. A React app that models matrix-multiplication workloads on a Tensix core, estimates the resulting performance, and shows how the work maps onto the hardware — useful for reasoning about a matmul's shape and fidelity choices before writing the kernel.
Tenstorrent's fork of QEMU that provides the full-system emulation layer behind ttsim. Models the RISC-V cores and system devices of Wormhole and Blackhole so TT-Metalium workloads can boot and run without physical silicon.
tt-bio
affiliated★ featuredBoltz-2 biomolecular model for drug discovery on Tenstorrent Blackhole. Supports single-card and multi-card configurations — QuietBox (4×) and Galaxy (32×). Approaches physics-based FEP accuracy at 1000× the speed.
📋 Changelog
# Changelog

All notable changes to TT-Bio are recorded here. Versioning is [SemVer](https://semver.org);
releases are cut from a commit that has passed the on-hardware test suite (see `RELEASING.md`).

## [Unreleased]

## [0.26.1] - 2026-10-29

### Fixed
- **ESMFold2 no longer runs out of device memory on a worker that has folded many different inputs.** A worker keeps
  its chip open across jobs, and the compiled programs for every input shape it has folded stay in device memory.
  After about ten hours of mixed lengths a Wormhole chip had too little room left for a 722-residue fold, and JapanFold
  failed up to 65 % of such tasks with "Ran out of device memory". A fold that is refused memory while programs are
  cached now drops them and runs again; folds that fit are unchanged. Seen on JapanFold with 0.25.0 and 0.26.0.

## [0.26.0] - 2026-10-29

### Changed
- **ESMFold2 and ESMFold2-Fast normal mode on Wormhole run the token attention as one fused program.** A 512-residue
  fold on a Wormhole Galaxy chip drops about 0.85 s (ESMFold2 25.9 -> 25.0 s, ESMFold2-Fast 16.0 -> 15.1 s). Structures
  change at the precision level: graded over 44 paired folds per model in normal mode, accuracy and docking success
  unchanged. Blackhole and `--fast` already ran it.
- **BoltzGen normal mode on Wormhole conditions its diffusion steps ahead of time.** A 514-token design on a
  Galaxy chip at 1000 MHz drops from 43.3 to 40.9 s. Designs change at the precision level: graded over 64 paired
  designs, design pTM, ipTM and complex pLDDT unchanged within the seed-to-seed spread.

## [0.25.0] - 2026-10-28

### Changed
- **BoltzGen's token diffusion transformer does less attention work.** In normal mode its pair bias was padded to
  768 tokens for a 544-token design; it now pads to 576, and on Blackhole the attention runs as one fused program
  in both modes. A 514-token design drops about 1.2 s on a Wormhole Galaxy chip (46 -> 45 s) and on a Blackhole
  chip about 2 s in normal mode (22.9 -> 21 s) and 1.5 s with `--fast`. Designs change at the precision level:
  graded over 64 paired designs per arch in normal mode and 32 with `--fast`, confidence metrics and filter pass
  counts unchanged. Other models keep their padding.
- **BoltzGen normal mode on Blackhole replays the diffusion step from a device trace by default.** Output is
  identical, the 1831-residue size ceiling holds, and with the triangle-multiplication change above a 514-token
  design on a p300 chip drops from 25.2 to 23.0 s. `--no_diffusion_trace` restores the eager step. `--fast` replays it too, and
  computes each step's conditioning inside the trace instead of several steps ahead: a 514-token fast design on a
  p300 chip drops from 32.4 to 23.3 s on a host-bound machine.

## [0.24.0] - 2026-10-27

### Changed
- **RoseTTAFold3 on Wormhole runs the fast triangle and transition kernels in normal mode.** A 512-residue fold
  on a Galaxy chip drops from 55.2 to 38.1 s. Structures change at the precis
grayskull-attention
affiliatedFlashAttention-style attention kernel implemented entirely in on-chip SRAM on the Tenstorrent Grayskull chip using TT-Metalium. Pioneering work in low-level attention on TT hardware.
tt-atom
affiliated
Meta's UMA interatomic potential running on Tenstorrent Blackhole — energy, forces, and stress for molecules and periodic materials behind an ASE calculator. Its per-edge Wigner rotation runs as a custom tt-metal kernel for a highest-performance uma-s build.
📋 Changelog
# Changelog

All notable changes to TT-Atom are recorded here. Versioning is [SemVer](https://semver.org);
releases are cut only from a commit that has passed the on-hardware release gate — accuracy
parity, no OOM across the supported size range, no perf or UX regression, and a clean install
smoke (see `RELEASING.md`).

## [Unreleased]

Behaviour changes are all in the knobs and the caches, not in the models: every numeric path is
byte-identical to 0.3.0.

### Fixed
- The release gate's perf leg no longer decides by luck. It took one measurement per model against
  a fixed 15% threshold, and on a p150a the throughput spread between runs reaches that threshold
  on its own: in the gate run that closed this entry, `uma-s-1-omol-batch` drew 88.9, 104.4 and
  104.8 sys/s, and the first of those alone is a 20% shortfall against the baseline. The leg now
  waits for every other process to let go of a card and gates the median of three independent
  runs, printing all three. With no quiet window it measures anyway and reports a shortfall as
  `GAP`, since a contended run is not evidence of a regression.
- `benchmarks/_harness.host_quiet()` reported the host busy forever. It grepped process command
  lines for `tt_bio`, which matches any agent whose own arguments merely mention it; it asks the
  kernel who holds a `/dev/tenstorrent` node now. The three benchmarks that wait for a quiet host
  used to burn their full 40-minute budget and stop without measuring.
- The edge-bucketing speedup in the README and `docs/orb-port.md` is re-measured and now names the
  environment it was taken in. It said 1.4x cold wall-clock on a 20-system screening stream; two
  draws on the pinned tt-metal source build give **1.11x and 1.14x** (235.1 / 236.5 s unbucketed
  against 210.9 / 207.6 s bucketed). What bucketing saves is compiles, and that is unchanged and
  exact: 20 distinct edge shapes collapse to 7 buckets and 2350 fewer kernel files are built,
  identical to the file across both draws. The wall-clock ratio fell because a compile costs about
  half what it did in whatever environment produced the earlier number — which that log does not
  record, so the three subprocess benchmarks now stamp `ttnn_version` next to `git_sha`.
- `benchmarks/_harness.sandbox_env` resolves the sandbox `$HOME`. A relative `--workdir` reached
  the child as a relative `$HOME`, and tt-metal resolves that against the child's own working
  directory: it died deep in the JIT build with "Failed to open compile failure log file" and a
  path that reads as correct. `bench_compile_pain.py` also defaulted to `--card 3`, a card that
  does not exist on the host this repo is routed to.
- `TT_ATOM_SCATTER_THRESHOLD` is documented. It is the node count above which UMA's dense one-hot
  scatter gives way to the linear path, and therefore what bounds DRAM on a large cell, but it
  appeared in no doc.
- The release gate reads `OVERALL: PASS` again. Both Orb perf rows were seeded on a stock `ttnn`
  0.68.
tt-lang-models
affiliated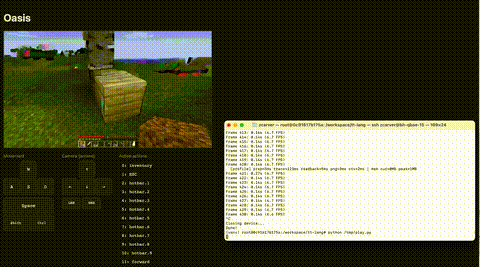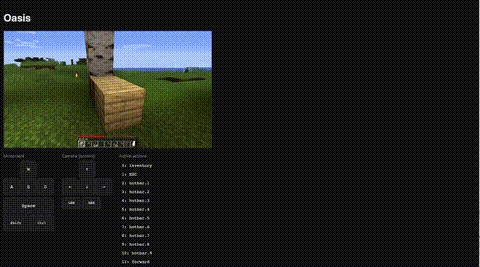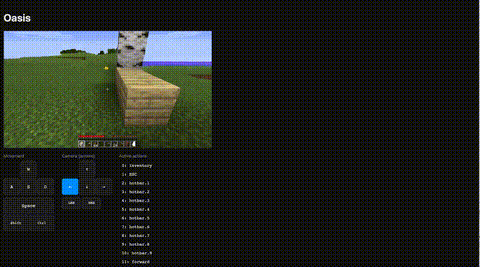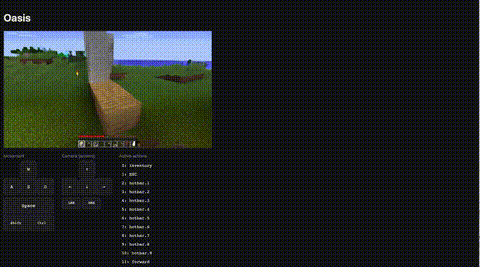
A growing collection of models that use tt-lang for some or all of their implementation. Reference implementations for bringing modern models to the tt-lang DSL.
Cache Me If You Can
affiliatedHands-on LLM inference tutorial given at ML in PL 2026 in Warsaw by Tenstorrent's Maciek Draguła and Nathan Maurice. Jupyter notebooks run GPT-2 and DeepSeek-R1-Distill-Qwen-1.5B on an n150: prefill versus decode, building a KV cache by hand, and what tt_transformers does under the hood. A setup script installs dependencies and downloads the weights.
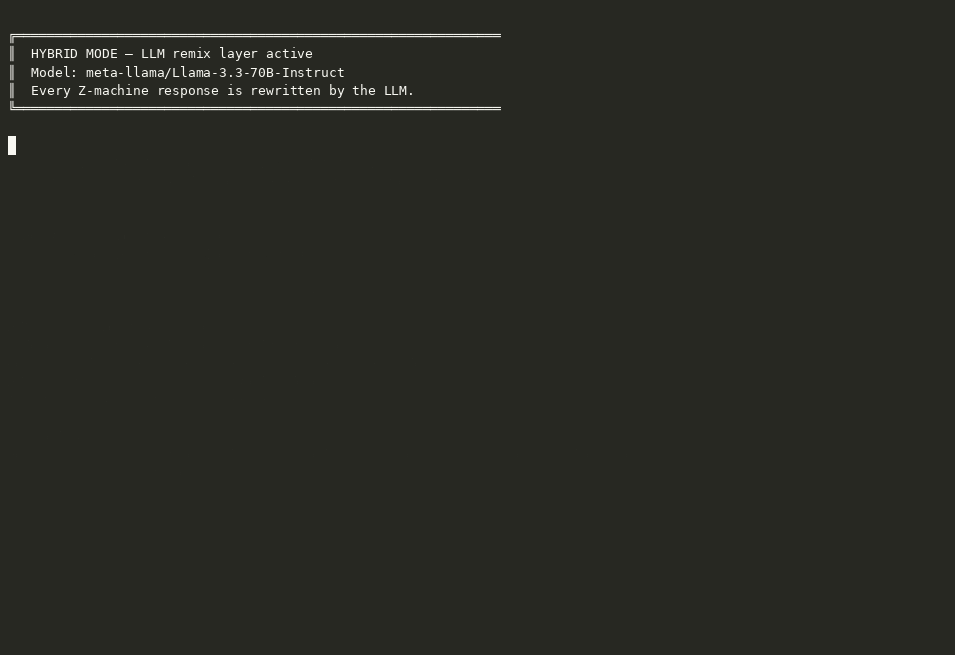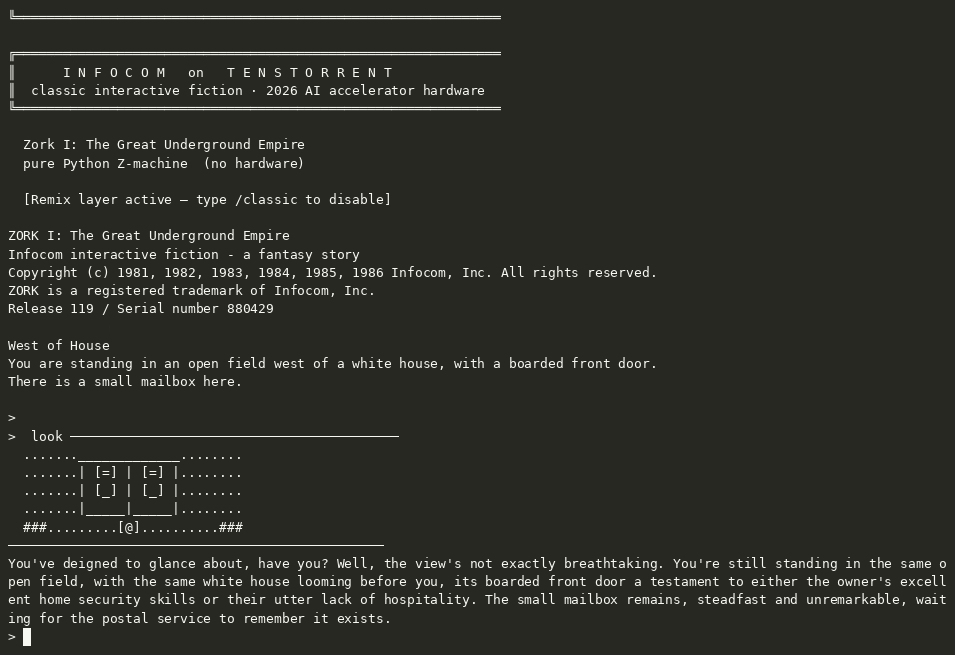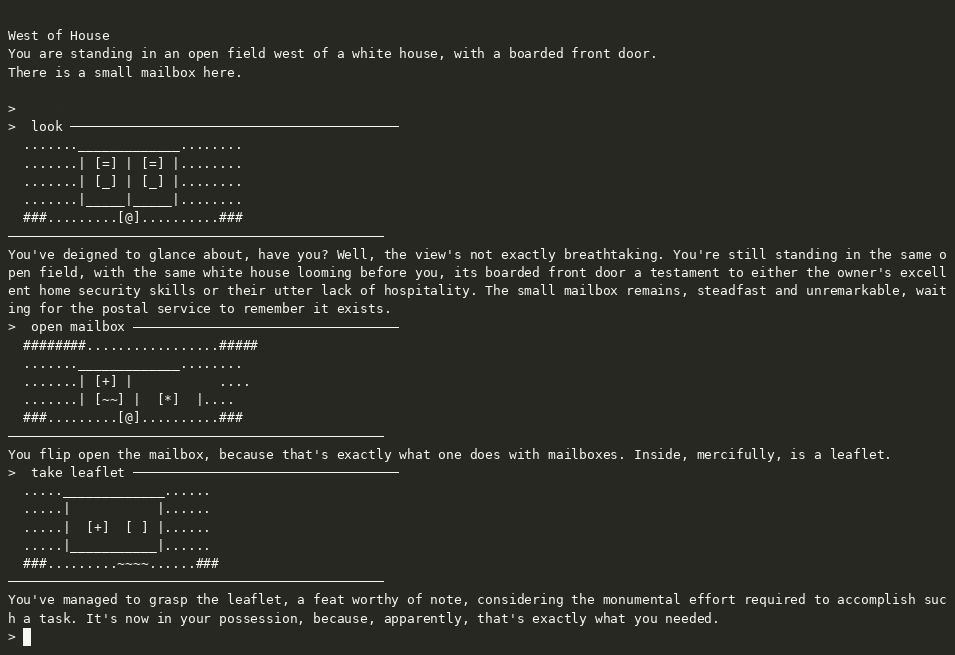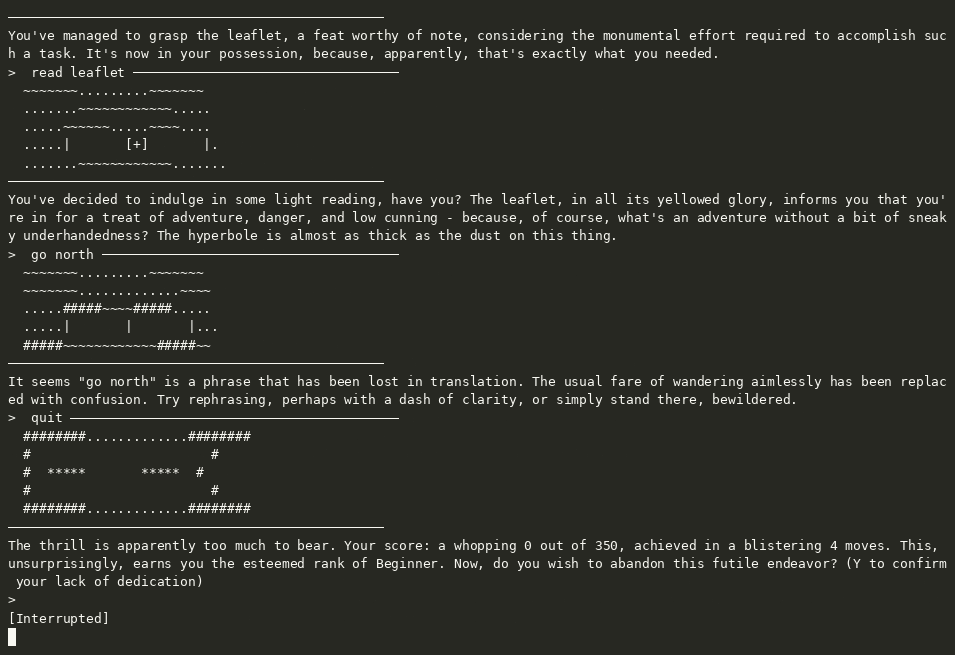
A Tenstorrent fork of Infocom's Zork I (and more!), running a Z-machine interpreter at least four different ways on TT hardware. The most fun you can have with an AI accelerator.
tt-qb-lights
affiliatedSync your Tenstorrent Quietbox's RGB lighting to accelerator utilization status. Visual feedback for hardware activity in real time.
DIAMOND: Atari game-playing agent implemented on Tenstorrent hardware via tt-lang. Diffusion-based world model for reinforcement learning.
gemma4
affiliatedGemma 4 language model implemented in tt-lang (e4b variant) for direct execution on Tenstorrent hardware.
tt-lang inference script for Oasis 500M — an interactive video world model running on Tenstorrent hardware via the tt-lang DSL.
tt-model-runner
affiliatedDiscover, load, and benchmark models with a GUI and TUI for tt-inference-server. Makes exploring available models on Tenstorrent hardware as easy as browsing a catalog.
tt-bio-demo
affiliated★ featured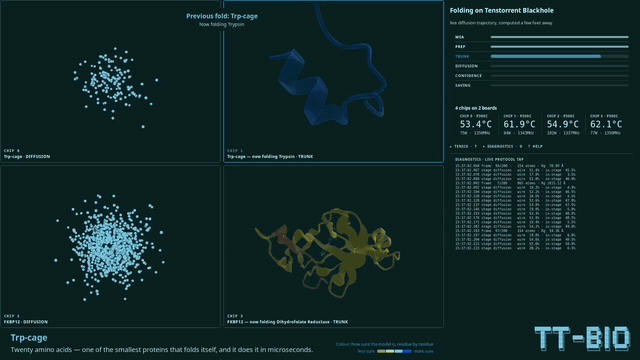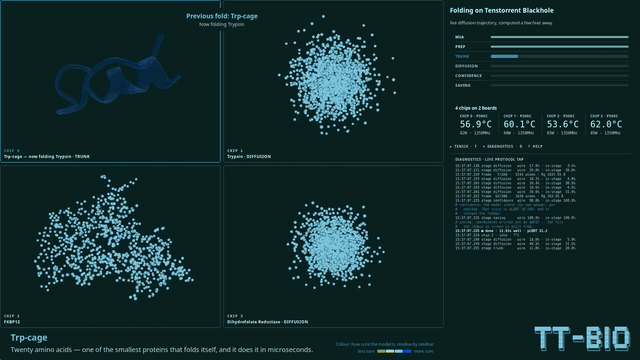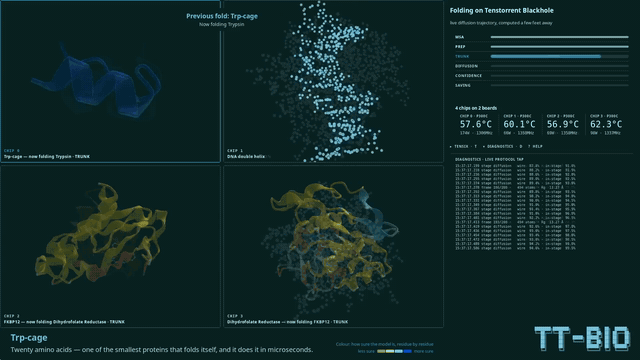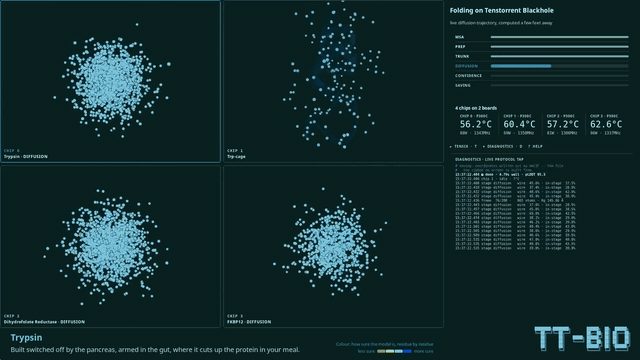
A turnkey conference-booth demo for tt-bio: watch a protein condense out of noise into its folded structure in real time, computed on the Blackhole chips a few feet away. Native GTK4 and OpenGL, with a cartoon renderer, live per-residue confidence colouring, a Tensix core grid, and a 2×2 quad view running four independent folds on four chips at once.
4 previous releases
tt-bio-bringup
affiliatedA Claude Code skill that ports a PyTorch biomolecular model to Tenstorrent hardware inside a tt-bio fork: parity-verified against a CPU golden, optimized against a measured roofline, then packaged and gated like the models already shipped. Needs only a PyTorch reference implementation and Tenstorrent cards; no GPU is used at any point.
tt-claw
affiliatedA Tenstorrent-powered claw machine that rewards players with real prizes. The QuietBox 2 runs local AI inference to act as an agent controlling the claw hardware — the OpenClaw AI assistant lesson builds directly on this project.
Local AI Agents on Tenstorrent
affiliated★ featuredThree agentic projects running fully on-device: local AI agents on QuietBox 2, a coding assistant powered by Aider against a local inference server, and the OpenClaw AI assistant on QuietBox 2. No cloud APIs — all inference runs on TT hardware.
DFlash: Block Diffusion for Flash Speculative Decoding on Tenstorrent hardware using tt-lang. Combines block diffusion with speculative decoding for faster inference.
A Tenstorrent port of the DeepSeek Engram model using tt-lang. Brings DeepSeek's memory-efficient architecture to TT hardware.
gsplat_tt
affiliatedPort of Gaussian Splatting (3D scene reconstruction from 2D images) to Tenstorrent hardware.
openjev on P300x2
affiliatedServes AlexWortega/openjev, a Qwen3.5-4B NLI cross-encoder, as a vLLM pooling model on four Blackhole chips with 4-way tensor parallelism. The repo holds tt-metal and vllm-tt-plugin patches (classifier head, pooled prefill traces, pooling support), a tt-inference-server catalog entry, eval scripts and results: MNLI-500 accuracy 0.892 on TT vs 0.896 on CPU bf16, and about 32 ms per input up to 128 tokens. Includes a zero-shot Flappy Bird demo driven by /classify calls, with videos and a browser replay viewer. Weights are not duplicated; they load from the upstream checkpoint.
tt_symbiote
affiliatedA pip-installable library whose public API mirrors Hugging Face transformers' `Auto*` loaders, with model recipes that replace supported modules with TTNN implementations and fall back to CPU `nn.Module`s for the rest; the only added line is `set_device(model, mesh)`. Verified recipes include Ling-mini-2.0 on T3K, ResNet-50, Gemma 4 E2B/E4B and Qwen3-VL-2B on N150, with `compatibility.report(model)` showing which modules actually ran on device. `ttnn` must be built from source at the pinned tt-metal commit. It is the standalone packaging of the framework that started in tt-metal's `models/experimental/tt_symbiote`.
Stable Diffusion XL on Tenstorrent
affiliatedOn-device image generation with Stable Diffusion XL running entirely on Tenstorrent hardware. Full inference pipeline with no cloud dependency.
Video Generation on Tenstorrent
affiliated★ featuredThree lesson-projects covering on-device video synthesis: frame-by-frame diffusion with tt-local-generator, native AnimateDiff video animation, and video generation on QuietBox 2. All run entirely on TT hardware with no cloud dependency.
dev.to/mando222 — Tenstorrent & AI Blog
affiliatedEric Zietlow's blog covering Tenstorrent hardware, Metalium programming, and AI topics, sharing practical experience with Blackhole and the broader TT ecosystem from our developer relations team.
tt-forge-compiletron
affiliated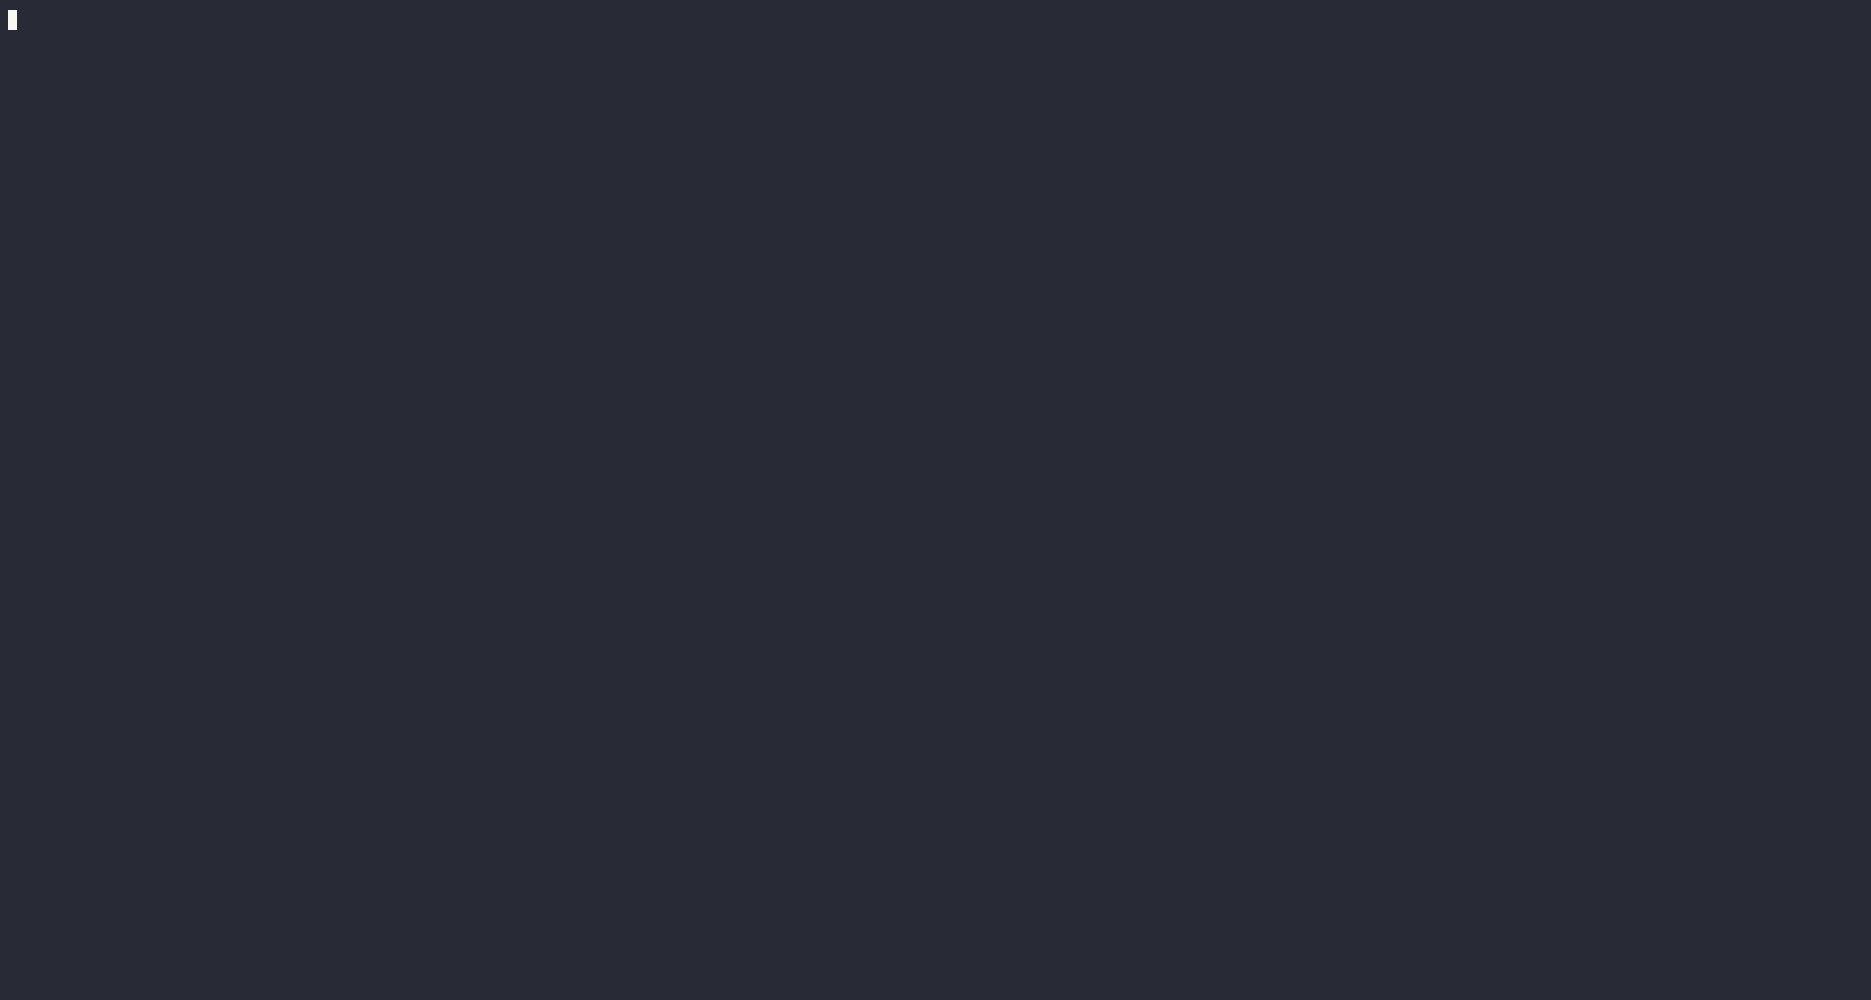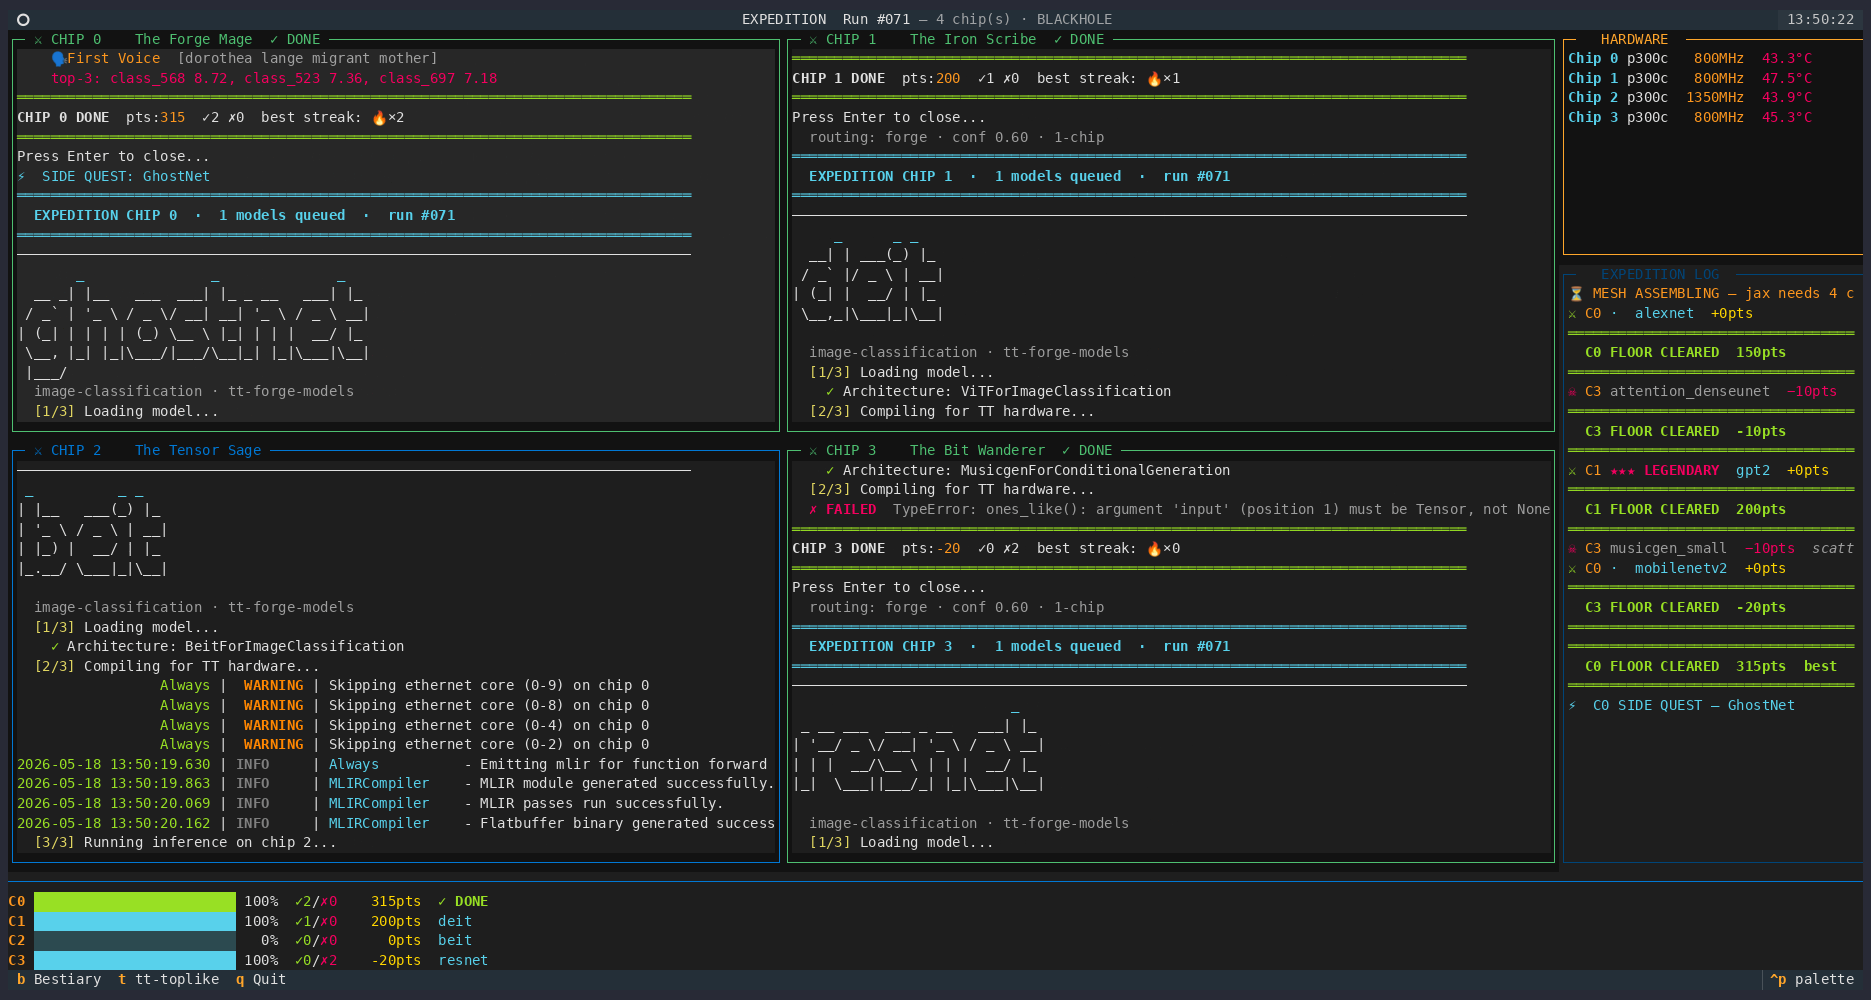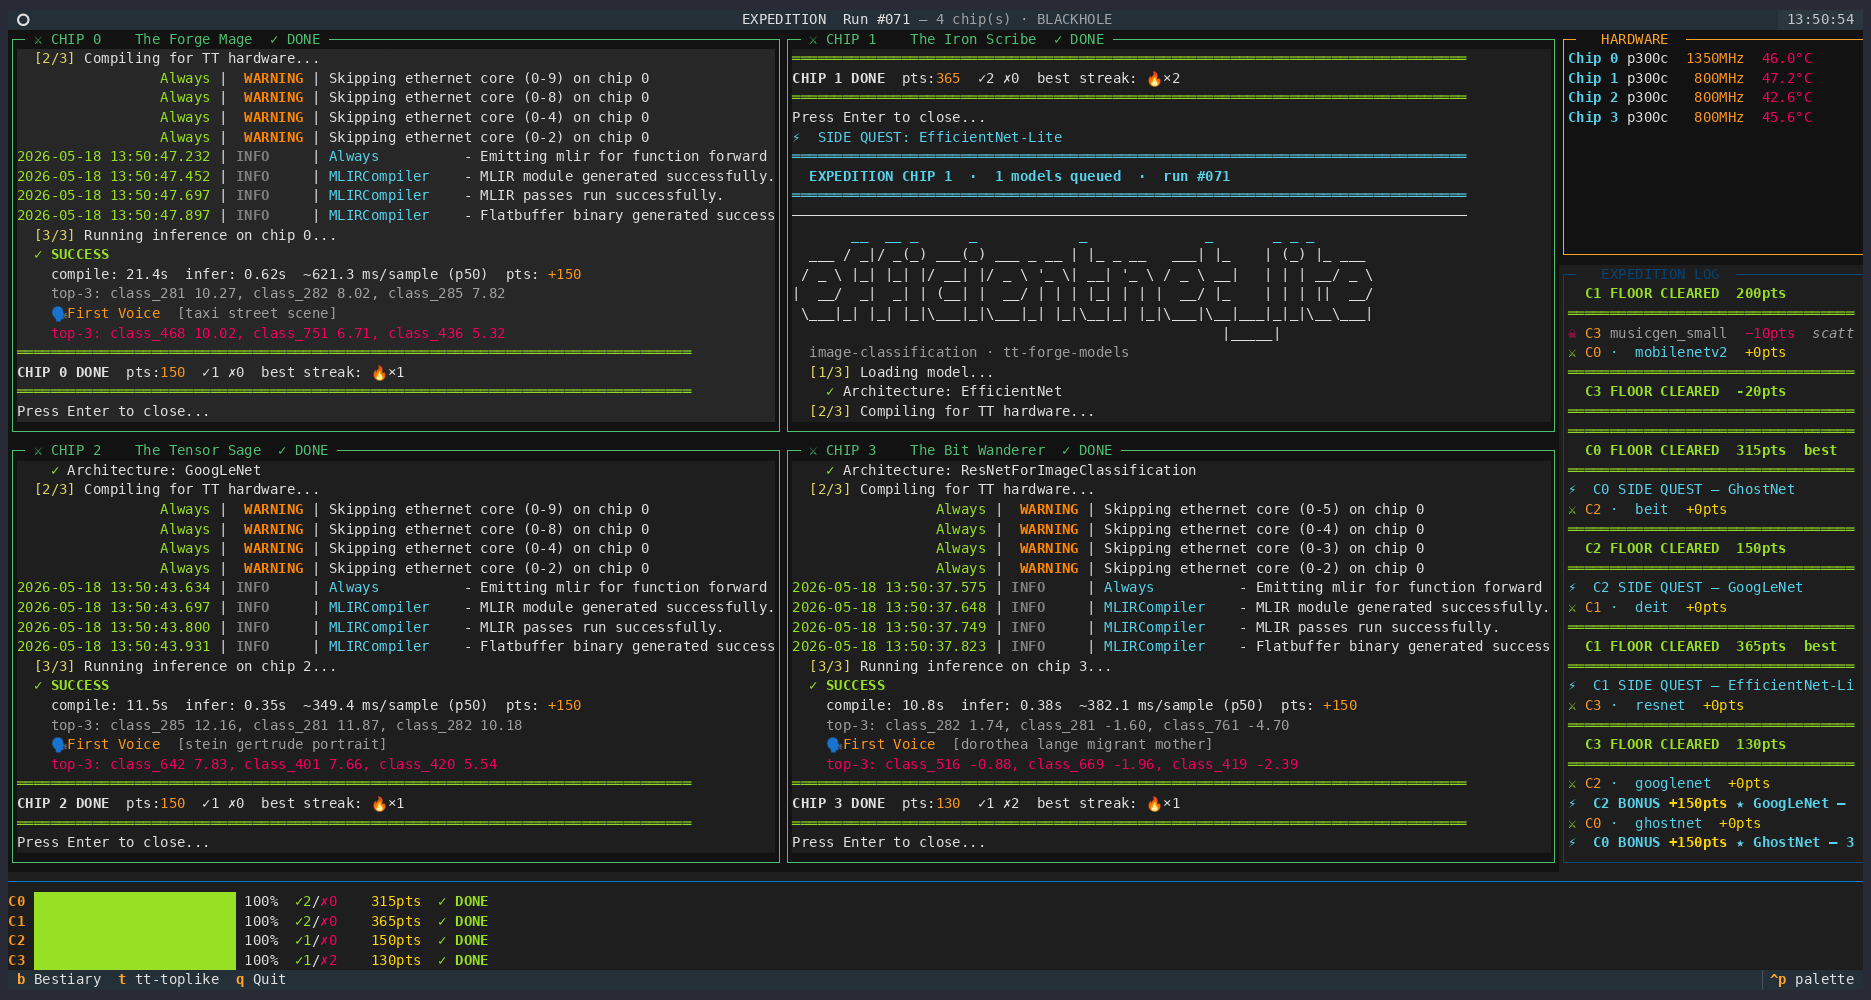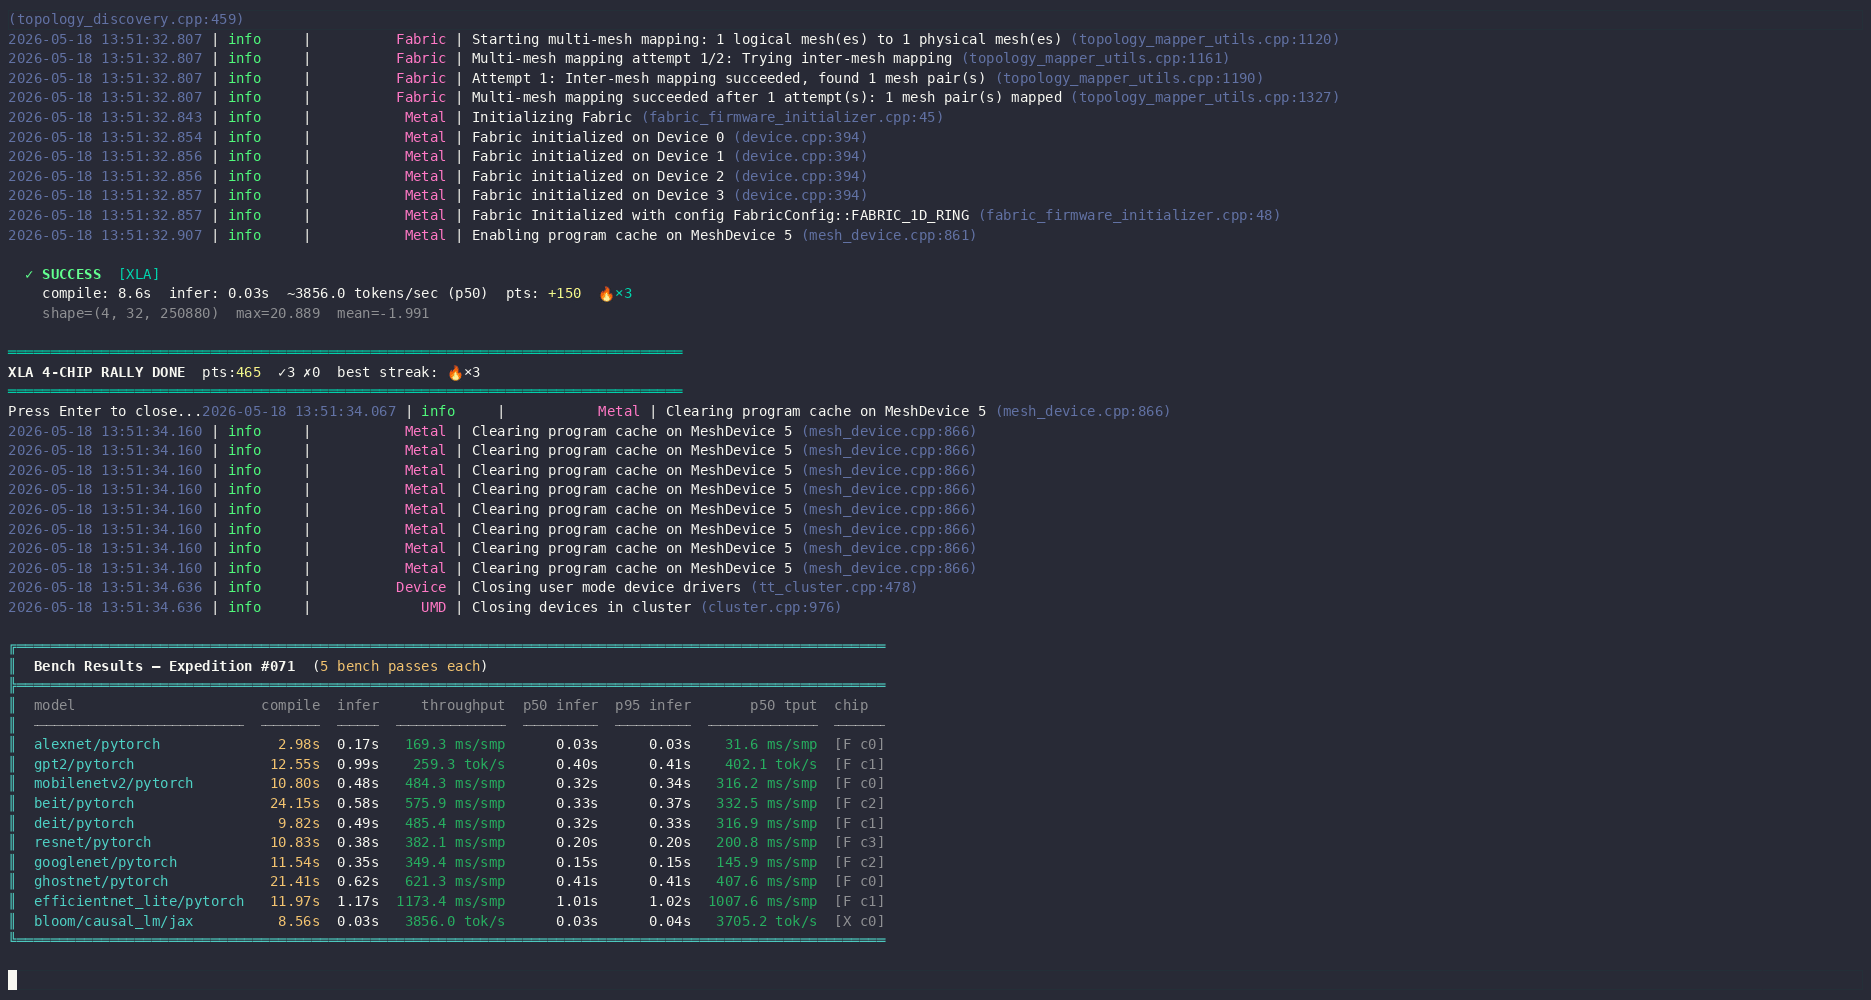
Compile more than 100 models on tt-forge in a display format suitable for demos. Comprehensive showcase of tt-forge model compatibility.
📋 Changelog
# Changelog

All notable changes to tt-forge-compiletron are documented here.

## [Unreleased]

### Added
- `docs/kv-cache-bench.md` — teaching companion for the StaticCache KV cache
  benchmark, explaining the two-graph pattern and why static shapes matter

---

## [1.6.0] — 2026-06-30

### Added
- **StaticCache KV cache decode benchmarking** — `bench_decode.py` now compiles
  a second forge graph for the decode step using `transformers.StaticCache`.
  The StaticCache is embedded in `KVDecodeWrapper` as a submodule so forge
  traces K/V tensors as model state and emits `FillCache`/`UpdateCache` ops.
  Falls back to full-recompute for models that don't support `cache_position`.
- `_try_kv_decode()` function — detects model dtype to avoid bfloat16/float32
  mismatches, resolves tokenizer from loader or AutoTokenizer, pre-fills cache
  on CPU before forge compilation.
- Bestiary `decode_note` field now records the method used per model
  ("StaticCache KV cache" vs "no KV cache — full recompute per step").

### Changed
- Decode results updated for all 5 stages — GPT-2 2.30→5.52 tok/s, OPT
  3.98→5.05 tok/s, Phi-2 1.48 tok/s (new), Falcon 3.30 tok/s (new),
  LLaMA-LoRA 2.86 tok/s (new), Gemma-LoRA 2.40 tok/s (new), and more.

---

## [1.5.0] — 2026-06-30

### Added
- **`scripts/bench_decode.py`** — dedicated LLM decode benchmark measuring
  TTFT, prefill tok/s, and decode tok/s for all compiled causal LMs.
  Subprocess isolation + tt-smi health check prevent hardware lockups.
- **Leaderboard columns** — TTFT, Prefill tok/s, Decode tok/s, Params (M)
  replace the old Infer p50 / Throughput columns in `docs/leaderboard.html`.
- 5 benchmark stages: Stage 1 (GPT-2, OPT), Stage 2 (Phi-2, BLOOM, CodeGen),
  Stage 3 (Falcon, Allam, LLaMA-LoRA, Gemma-LoRA), Stage 4 (Qwen 2.5,
  Phi-1 LoRA), Stage 5 (DeepCogito, DeepSeek Coder, frontier models).
- `params_m` field added to all benchmarked bestiary entries.
- `hf:` loader prefix for frontier HuggingFace models loaded without a
  tt-forge-models seed loader.

### Changed
- Bestiary `throughput_unit` relabeled from generic `tok/s` → `prefill_tok/s`
  for all 54 causal LM entries to prevent confusion with decode throughput.

---

## [1.4.0] — 2026-06-29

### Added
- **`scripts/install.sh`** — turn-key smart installer: hardware pre-check,
  hugepages, disk space, forge venv, XLA venv, mesh descriptor probe,
  tt-forge-models clone, stale-shm cleanup. Outputs color-coded summary table.
- **RAM/DRAM budget calculator** — skips models whose weights exceed available
  system RAM + per-chip DRAM; prevents OOM crashes at load time.
- **`scripts/setup-venvs.sh`** — minimal venv setup script for clean Ubuntu
  24.04 installs on Tenstorrent Blackhole hardware.
- Self-contained patches directory — tt-forge-models fixes applied at
  expedition startup without modifying upstream.
- `--ephemeral` / `--evict-failures` flags — evict HF weight cache after
  each model to reclaim disk space on small-storage machines.

### Changed
Image Classification with TT-Forge
affiliatedEnd-to-end image classification project using TT-Forge — compile and run a PyTorch classification model on Tenstorrent hardware with no kernel authoring required.
tensix-viz
affiliated★ featured
Hardware topology visualizer for Tenstorrent chips — from individual chip to full cluster. Interactive JavaScript visualization of Tensix core layout and NoC connections.
📋 Changelog
# Changelog

All notable changes to tensix-viz are documented here.

## [1.3.2] - 2026-09-28

### Fixed

- **Cluster views no longer collapse to their caption's width**
  (`src/cluster.js`). Cluster tiles are empty divs with no width of their own,
  so a shrink-to-fit parent sized the whole widget to its one-line spec text —
  Galaxy SC's 128 chips rendered as 2.7px dots. The tile grid now gets a
  preferred width from its column count (32px tiles, or 10px dots above 64
  chips) and `max-width: 100%`, so it still shrinks on phones.
- **Zoomed cluster breadcrumb no longer covers the spec caption**
  (`tensix-viz.css`). `.tv-cluster.tv-zoomed-in` reserves room at the top for
  the "Cluster › Server N" breadcrumb.

### Docs site (landing page)

- Hero and two-column sections now stack at 1120px instead of 900px. Between
  those widths the QB2 hero chips were squeezed to ~120px and the Memory code
  block hid up to ~140px of each line; the hero now gets full 340px chips there.
- Code blocks wrap at ≤800px instead of hiding most of each line in a sideways
  scroll box (the Quick-start block hid ~400px per line on a phone).
- Phones: tighter padding around the hero system (chips 85px → 119px at
  375px wide), and `kernel_dispatch` may wrap so the mode table fits.

## [1.3.1] - 2026-09-28

### Fixed

- **Chips in a card/system no longer come out at different sizes**
  (`src/card.js`, `src/chip.js`). `TensixViz` caps its drawing size to its
  parent's `clientWidth` once, at construction. `CardViz` builds chips one at a
  time into a flex row, so each chip measured the room its predecessors had
  left — on the docs hero, QB2's second chip in each card rendered at roughly
  half the size of the first. Card chips now pass the new
  `fitContainer: false` option and keep their full logical size; CSS fits them
  (`.tv-chip-wrapper { flex: 0 1 auto; min-width: 0 }`).
- **Shrunk canvases are no longer squished.** The inline `style.height = Hpx`
  overrode `.tv-chip-wrapper canvas { height: auto }`, so whenever
  `max-width: 100%` narrowed a canvas its height stayed put (aspect ratio 0.8
  instead of 1.42). Canvases now get `max-width: 100%`, `height: auto` and an
  explicit `aspect-ratio`, so they scale cleanly after construction too.
- `.tv-card`, `.tv-system`, `.tv-card-wrapper` and `.tv-cluster` can shrink to
  their container (`max-width: 100%` / `min-width: 0`).

### Docs site

- Hero and "chip anatomy" grids use `minmax(0, 1fr)` tracks; a bare `1fr`
  couldn't shrink below the Memory section's `<pre>`, which pushed the page
  sideways even on desktop.
- The mode reference table scrolls inside its own box on phones.
- Hero theme buttons are grouped with the canvas they theme (they were a stray
  third grid cell under the hero text).
- Examples: demo cards can shrink below their canvas's preferred width, page
  padding scales down on phones, and the theme toolbar wraps.

## [1.3.0] - 2026-09-24

### Added

- **`setActivity(value)` and `setProgress(value)`**
tt-demo-maker
affiliated
A project-agnostic toolkit for authoring demo recordings and draft posts from inside any project. Describe scenes in a small YAML manifest and it drives the terminal ballet — tmux, asciinema, VHS, ffmpeg and agg — into asciicast/GIF/MP4 footage plus a first-draft Markdown post pairing each directive with the reaction it caused. Rust orchestrator over bash capture primitives, with idle trimming, readiness gating, and a /tt-demo Claude skill that writes the manifest for you.
tt-gozer
affiliatedCooperative chip leasing for Tenstorrent boxes, so several agents — Claude Code sessions, aider, shell scripts, cron jobs — can share one machine without corrupting each other's runs. A lease records who is using which chips and why; the kernel's view of the devices is the tiebreaker when the two disagree. Standard-library Python, board-grain leases by default, and it ships Claude Code skills that teach agents to lease before they run.
tt-warp
affiliatedWarp terminal plugin for Tenstorrent — integrates hardware status, model management, and developer workflows directly into the Warp terminal.
Tensix Grid Playground
affiliatedInteractive browser-based visualizer of the Tenstorrent Tensix grid architecture. Explore the NoC, core layout, and dataflow patterns without hardware — a great companion for learning kernel programming.
tensixinet
affiliated★ featured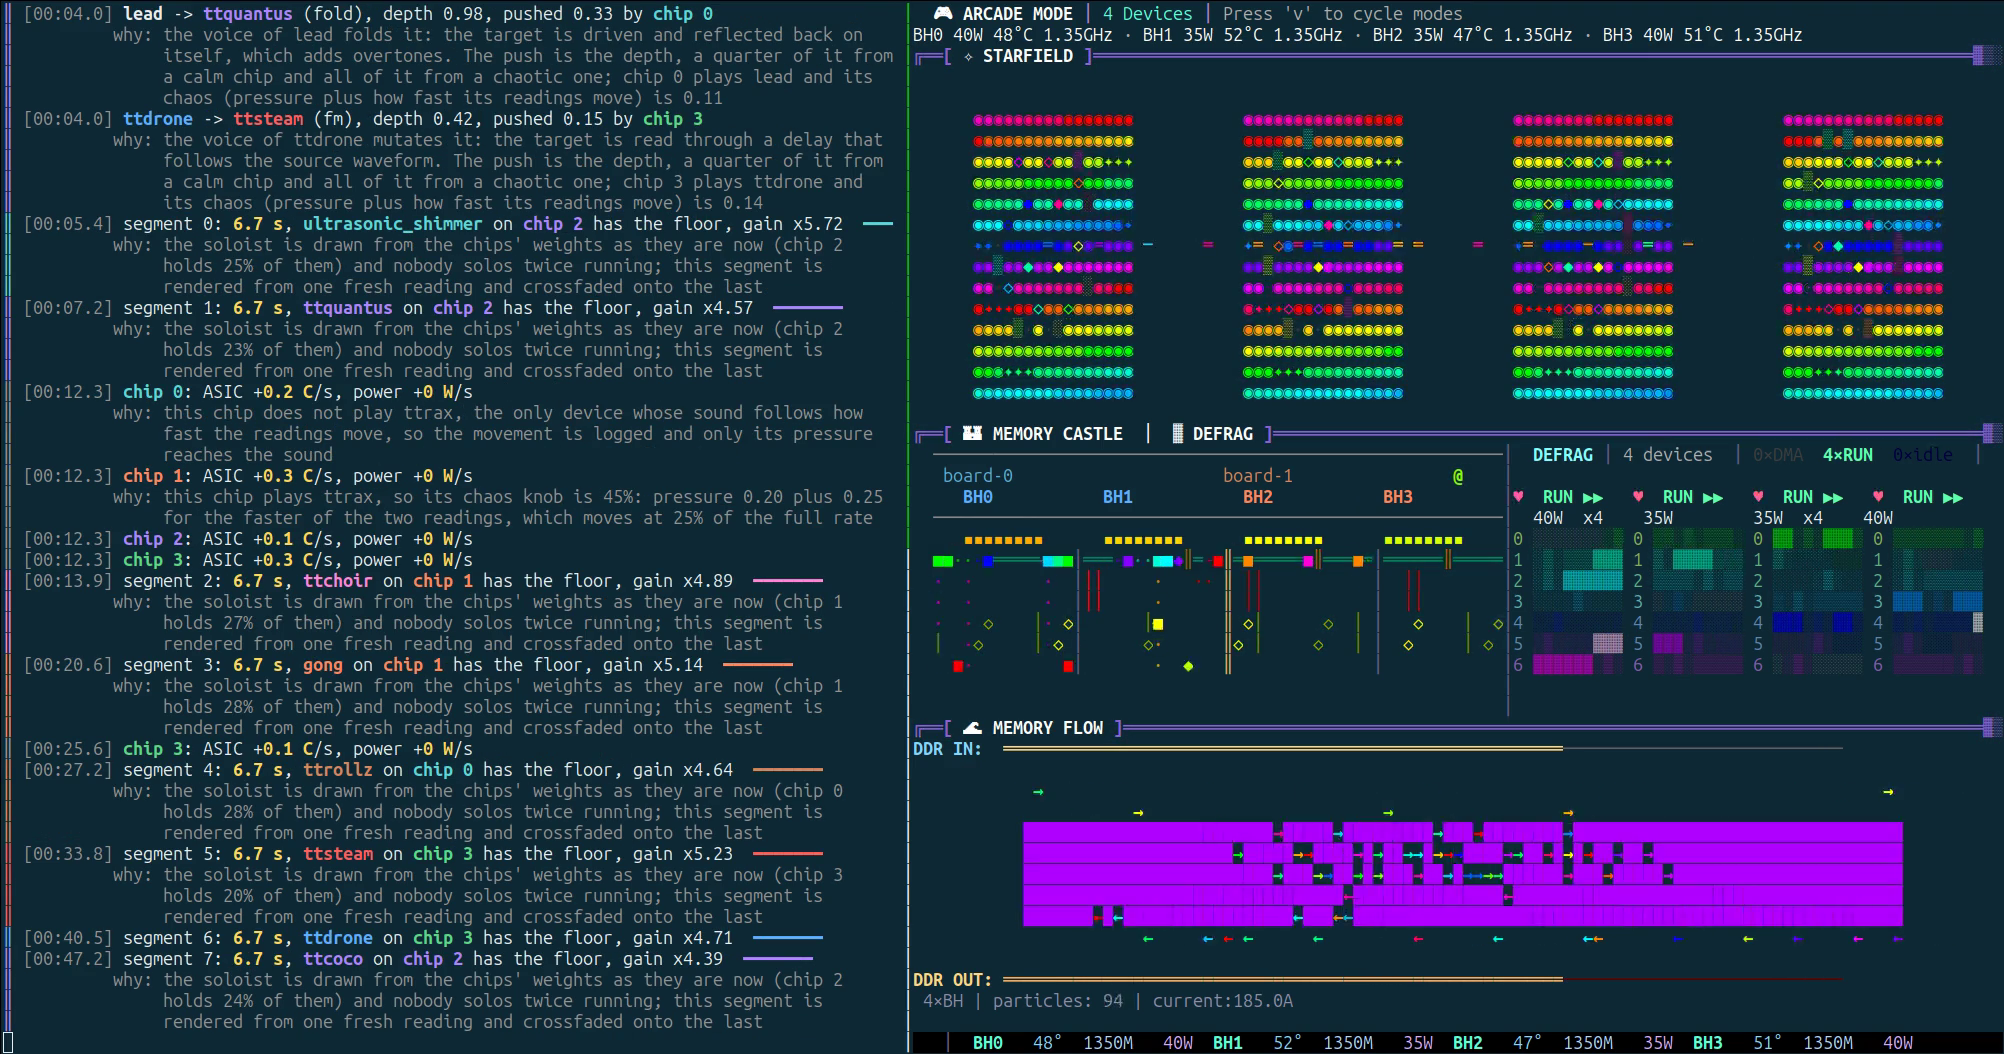
Your Tenstorrent chips, playing in a band: tensixinet reads each chip's telemetry with tt-smi (temperature, clock, power, current, memory temperatures, harvesting, link state, errors) and turns it into music from eleven synthesizers inspired by Ciat-Lonbarde instruments, so a hot chip and a cool chip sound different, a busy chip gets more solos, and uneven memory makes the melody wander. Every mapping is logged with its reason, each run draws a replayable patch, a live mode follows the chips as they heat under a prompted language model, some devices run as TT-Lang kernels on the chips themselves, and a Gradio page draws the band as it plays. Needs no hardware to try: it plays any number of synthetic chips.
Tenstorrent Cookbook: Conway's Game of Life
affiliatedTT-Metalium implementation of Conway's Game of Life as a cookbook recipe. Each generation is a full parallel kernel dispatch over the grid — a clean introduction to stateful compute on Tensix cores.
Tenstorrent Cookbook: Particle Life Simulator
affiliated★ featuredParticle Life simulation on Tenstorrent hardware — an emergent-behavior N-body system where simple attraction/repulsion rules between species produce complex lifelike patterns. Cookbook recipe demonstrating parallel N-body compute on Tensix.
Kernel Tutorials
affiliatedInteractive, presentation-style tutorials on tt-metal kernel programming, built as companions to the kernel_dojo exercises. The Circular Buffer Dojo steps through reserve, push, wait and pop, the DST handshake, and the classic deadlock and wrong-data bugs as live simulations of the exercise kernels; the Throughput Dojo covers multi-core scaling, the DRAM-bandwidth knee, batched NoC transactions, K-accumulation in DST, operand reuse and math fidelity. Each tutorial is one self-contained HTML file.
tt-sim Lab
affiliatedA university teaching lab for TT-Metalium kernel programming on a virtual Tenstorrent chip — one-click GitHub Codespace, no silicon and nothing installed locally. The primary track (labs 00-06) points tt-metal straight at libttsim via TT_METAL_SIMULATOR and walks from elementwise add through NoC multicast to multi-core and multicast matmul, backed by a source-level matmul guide. An optional advanced track (labs 10-16) boots an Ubuntu guest under ttsim-qemu, loads tt-kmd, surfaces /dev/tenstorrent/0, and runs tt-metal through the full PCIe path.
CS Fundamentals on Tenstorrent Hardware
affiliated★ featuredSeven-module computer science curriculum taught on real Tenstorrent hardware. Covers RISC-V architecture, memory hierarchy, parallel computing, networks and NoC, synchronization, abstraction layers, and computational complexity — all grounded in what is physically happening on the chip.
Custom Model Training on Tenstorrent
affiliatedEight-lesson series covering the full custom training workflow on TT hardware: dataset fundamentals, configuration patterns, fine-tuning, multi-device distributed training, experiment tracking, model architecture basics, and training from scratch.
Tenstorrent Cookbook: Core Recipes
affiliatedThree hands-on TT-Metalium kernel recipes: a Mandelbrot fractal explorer, real-time audio signal processing pipeline, and custom image filter stack. Each recipe is a complete kernel project with full source in the lesson.
ComfyUI-Tenstorrent
affiliatedComfyUI custom nodes for running Stable Diffusion XL, SD3.5, Wan 2.2, LTX-2.3 and MiniMax-H3 on Tenstorrent hardware. The nodes start and supervise a tt-metal FastAPI inference server that ships in the package, so CLIP, the UNet or DiT and the VAE all run on the device while ComfyUI keeps its own environment.
tt-fluid
affiliatedOpenFOAM's steady incompressible solver (simpleFoam with k-omega SST) running entirely on Blackhole and Wormhole chips. Reads an ordinary OpenFOAM case, keeps every SIMPLE iteration resident on the Tensix grid with halo exchange between cores, and writes OpenFOAM time directories back. On the HPC motorbike benchmark a QuietBox 2 comes in at 2.34x lower cost per case than an 8x H100 server, with drag within the reference uncertainty.
Exploring spectral element methods on the Tenstorrent RISC-V accelerator
affiliatedThe growing availability of commodity RISC-V hardware has sparked interest in its use for High Performance Computing (HPC), with PCIe accelerator cards offering a practical near-term pathway to adoption. The Tenstorrent Wormhole is one example, with dedicated vector and matrix units across 128 Tensix cores, and is widely available. In this paper, we explore porting the AX kernel of Nekbone, a widely used HPC mini-application derived from the Gordon Bell Prize-winning Nek5000 spectral element solver, onto the Wormhole accelerator.
nvtop
community★ featured
htop-style process monitor for GPUs and AI accelerators. Supports AMD, Apple, Huawei, Intel, NVIDIA, Qualcomm — and Tenstorrent. Real-time utilization, memory, and process info in a terminal UI.
dstack
community★ featured
Vendor-agnostic orchestration for training, inference, and agentic workloads across NVIDIA, AMD, TPU, and Tenstorrent on clouds, Kubernetes, and bare metal.
Booth
community★ featuredAn open-source CUDA, HIP, and Triton compiler with no LLVM anywhere in the path. Takes the same sources you would hand to nvcc, ROCm, or Triton's JIT and emits AMD RDNA 2/3/4 binaries, NVIDIA PTX, Tenstorrent Metalium C++, native RV32IM, or plain x86-64 — so a Triton matmul can run on a laptop that has never seen a GPU. Also reads a deliberate subset of MLIR (`func.func` plus the `arith` dialect) and Fortran `do concurrent` kernels via LFortran. Formerly BarraCUDA; renamed to honour Kathleen Booth.
📋 Changelog
Booth — Changelog
=================

## Booth 0.6.1

### Backends

- `--nvidia-cubin` puts every kernel of a module into the one cubin, so
  ggml-cuda files with several kernels no longer stop at E600
  (Zane Hambly, 2026-10-26)

- `--nvidia-cubin` lowers local loads and stores, half and bfloat16
  conversions, rounding, votes, membar, nanosleep, 16-bit parameters and
  constant divisors, and sizes each kernel's registers from its own counts
  (Zane Hambly, 2026-10-26)

- `--nvidia-cubin` holds a register only where its value is live, places join
  barriers by the blocks a region covers, and lowers wmma load, store and mma
  to scalar SASS, so topk-moe and lightning-indexer build (Zane Hambly,
  2026-10-26)

- `--nvidia-cubin` lowers cvta.local and cvta.global, so cumsum and quantize
  get as far as their vprintf call (Zane Hambly, 2026-10-26)

- `--nvidia-cubin` spills values to the local frame when a kernel needs more
  registers than SASS has, so mmvq gets past E603 (Zane Hambly, 2026-10-26)

- `--cuda-host` and `--cuda-exe` emit the host half of a CUDA compile, so kath
  builds a whole program the way nvcc does: the source back out with the device
  definitions removed, each launch through `__cudaPushCallConfiguration` and a
  stub calling `cudaLaunchKernel`, the kernels registered from a constructor out
  of a fatbin carrying both the cubin and the PTX, and the system C++ compiler
  driven to link it. Clean-room `cuda.h`, `cuda_runtime.h`, `cuda_fp16.h`,
  `cuda_bf16.h` and `cublas_v2.h` under `runtime/include` (Zane Hambly,
  2026-10-26)

- `--cuda-host` writes each kernel's stub where the kernel stood and keys a
  launch on the instantiation rather than its position, so a kernel launched
  from inside a host template or through a macro reaches the right one, and it
  spells enum, struct, vector and function template arguments, so ggml-cuda
  files get through the host pass (Zane Hambly, 2026-10-26)

- `--cuda-host` writes out a variadic template argument pack, spells a function
  template-id argument rather than the symbol it lowered to, keeps a launch
  whose callee ends in `>>`, registers up to 4096 kernels and refuses with E622
  above that instead of falling silent, and `kath cuda` finds Booth's own
  `runtime/include` from the binary rather than the working directory, so
  binbcast and cpy get through (Zane Hambly, 2026-10-26)
- `--cuda-host` carries const on the BIR type itself, so a kernel taking
  `const float *` registers the instantiation its launch actually names
  rather than one spelled without the qualifier (Zane Hambly, 2026-10-26)

- `kath cuda -c` compiles one `.cu` to one relocatable object rather than a
  whole program, with `-fPIC` for a shared library, each object carrying its
  own fatbin and registration constructor the way nvcc does, so many
  translation units link into one library (Zane Hambly, 2026-10-26)

- `kath cuda` takes `-Idir` written up against the flag as well as `-I dir`,
  rather than dropping it and c
vllm.cpp
community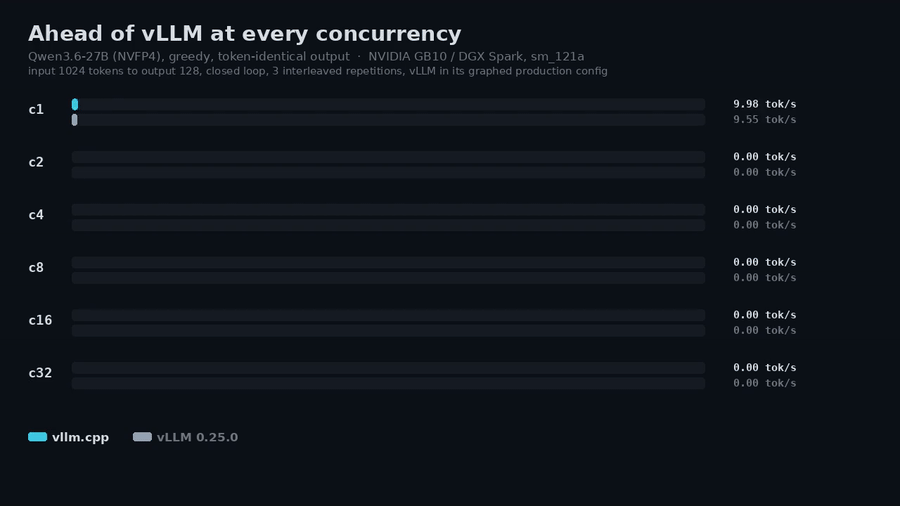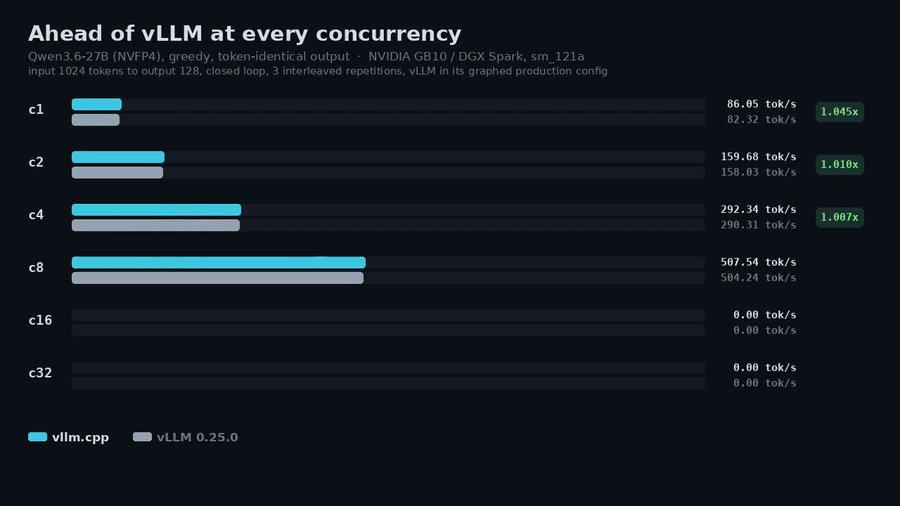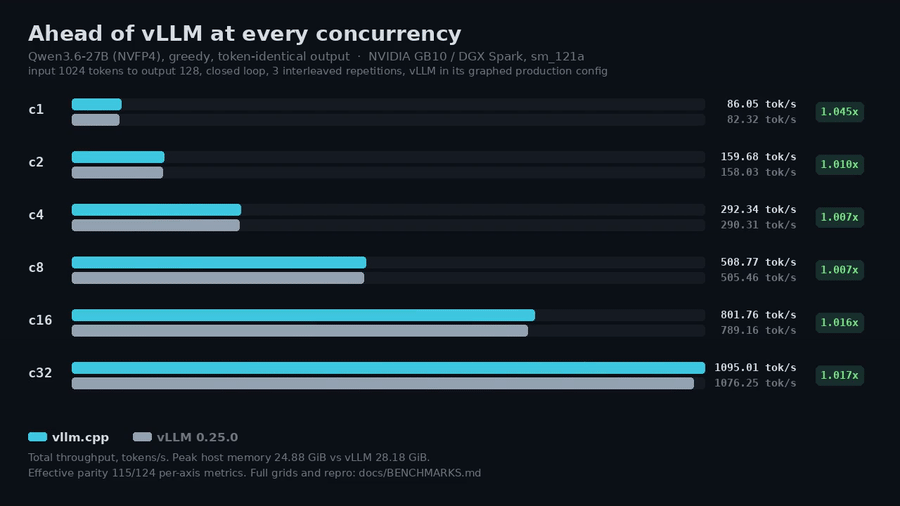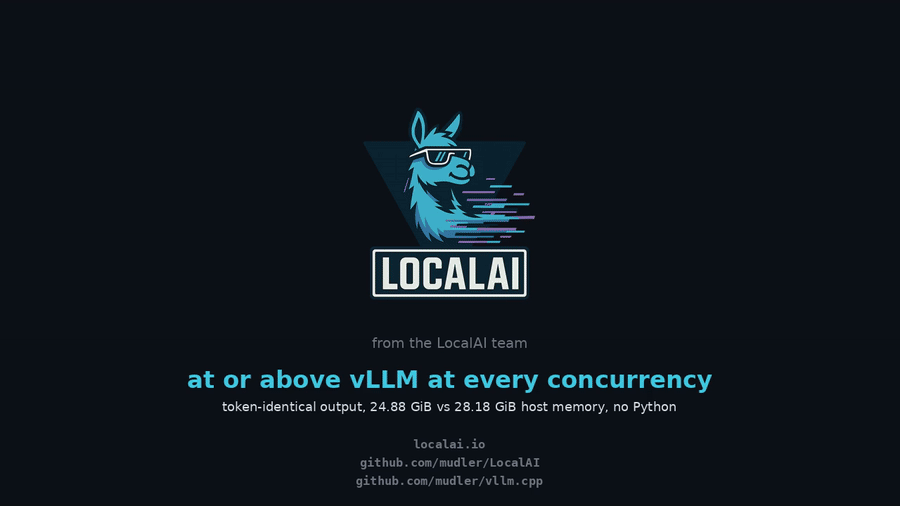
A C++ reimplementation of the vLLM engine (continuous batching, paged KV cache, GGUF loading) with CUDA, CPU, Metal, Vulkan and ROCm backends plus an opt-in Tenstorrent backend under `src/vt/tenstorrent`. The TT backend is a thin adapter over TTNN and TT-Metalium built with `-DVLLM_CPP_TENSTORRENT=ON`, adding paged attention, Qwen3.5 gated-delta-net, trace capture and quant-preserving (`keepquant`) matmul paths. Status is correctness-first on Blackhole: OPT-125m passes a strict token-exact gate, Qwen3-0.6B has committed goldens with a full rerun pending, and 27B GGUF decode is in smoke-measurement stage.
3 previous releases
zyx
community
A complete ML library and compiler in Rust — "from assembly to neural networks" — with a native Tenstorrent backend (src/backend/tenstorrent), autograd, custom kernels, multi-backend support, and Python bindings.
tt-tiny
community★ featuredMinimal Python code to access and program the Tenstorrent Blackhole chip directly — George Hotz's exploration of TT hardware programmability with pointed commentary on the architecture.
tt-twitch
communityA Tenstorrent Grayskull kernel written live on Twitch by George Hotz. 120-core grid demonstration of live kernel programming.
blackhole-py
communityPure Python driver for Tenstorrent Blackhole cards providing direct low-level hardware access without going through the full TT-Metal stack.
koyeb/tenstorrent-examples
communityExample applications and deployment configurations for running AI workloads on Tenstorrent hardware via Koyeb's cloud platform.
Tenstorrent Console Skill
communityAn agent skill (SKILL.md) that teaches Claude Code, Codex, and the Agent SDK how to drive the console.tenstorrent.com inference API: OpenAI-compatible chat with DeepSeek-R1 and Qwen3, async image jobs, and Wan 2.2 text-to-video. Ships runnable curl examples and a mock-curl test harness; documentation is bilingual Korean/English.
triton-tenstorrent
community★ featuredOpenAI Triton compiler plugin for Tenstorrent hardware. Write Triton kernels and target Tensix cores — brings the Triton ML kernel ecosystem to TT devices.
tt-iree
community★ featuredIREE (Intermediate Representation Execution Environment) ML compiler ported to Tenstorrent AI accelerators. Brings the IREE compiler ecosystem to TT hardware.
tenstorrent-tiny-examples
communitySimple C++ kernel experiments on a GraySkull e75 chip. Hands-on examples for learning the TT-Metal programming model at the metal level.
ttnn-helloworld-cpp
communityMinimal working example of using Tenstorrent TTNN in C++. The simplest possible starting point for C++ developers targeting TT hardware with TTNN.
Wolfpine
community★ featuredA pure-Python framework for building cycle-approximate simulators of AI accelerators, with Wormhole and Blackhole backends written from the public Tenstorrent ISA documentation. Runs real tt-metal programs unmodified on the full worker grid (72 cores on Wormhole, 130 on Blackhole) with no hardware, and because it is Python throughout, a driver script can inspect simulator state directly. The `wolfpine run` CLI switches a tt-metal build between simulated Wormhole, simulated Blackhole and real silicon. Not cycle accurate by design. Formerly tt-sim; renamed to Wolfpine in 2026 and unrelated to Tenstorrent's official `ttsim`.
libtt
communityA Bazel-built PJRT plugin (libtt.so) providing an XLA backend for Tenstorrent devices. Bundles the tt-xla PJRT implementation with tt-mlir and tt-metal into a single shared object so JAX code runs on Tenstorrent hardware, with patches so sglang-jax works out of the box.
Qwen3.8-27B on two Blackhole P150A
communityAn optimisation campaign for single-stream coding inference of `Qwen/Qwen3.8-27B` on two P150A cards linked by QSFP-DD (TP2), using DSpark speculative drafting, fused MLP and custom Tensix kernels, with CI workflows that replay each experiment on hardware and on `ttsim`. The author reports 118 committed tok/s at 4K context and 50 tok/s at 64K, and states plainly that the 200 tok/s target has not been reached. These are offline runtime tests, not a serving benchmark, and reproducing them depends on a Docker image that is not published to a registry. The docs include a Blackhole tuning playbook, a gotchas list and a record of fixes contributed upstream to tt-metal.
TT-GoL
community
Conway's Game of Life implemented on Tenstorrent hardware using TT-Metal kernels.
tenstorrent.nix
communityNix flake packaging the Tenstorrent software stack for NixOS and Nix users. Reproducible, declarative installation of TT drivers and tools.
Tenstorrent Simulator Playground
community
A web playground that runs real TTNN operations on the ttsim hardware simulator — no card required. Switch between Wormhole and Blackhole, run elementwise/activation/matmul ops or a small MLP, draw a digit and classify it with a trained MNIST net, then sweep parameters in 1D or 2D and read latency, throughput, and memory back as line charts, 3D surfaces, and heatmaps.
📋 Changelog
# Changelog

All notable changes to the Tenstorrent Simulator Playground will be documented in this file.

The format is based on [Keep a Changelog](https://keepachangelog.com/en/1.1.0/),
and this project adheres to [Semantic Versioning](https://semver.org/spec/v2.0.0.html).

## [1.4.0] - 2026-01-27

### Added

- **Updated Demo Assets**
  - New digit recognition demo GIF with improved visualization

### Fixed

- **Docker Desktop Compatibility**
  - Fixed 500 Internal Server Error when running digit recognition in Docker containers
  - Implemented native Docker inference that runs Python directly instead of attempting WSL calls
  - Proper environment variable handling for containerized ttsim execution
  - Automatic SOC descriptor selection for Wormhole/Blackhole chips in Docker

## [1.3.0] - 2026-01-27

### Added

- **Enhanced Network Visualization**
  - 28×28 pixel grid visualization for input layer displaying the actual drawn digit
  - Vertical output column showing all 10 digit classes (0-9) with labels
  - Green ring highlight indicator for the predicted digit
  - Pixel data pass-through from drawing canvas to network visualization

### Changed

- **Performance Statistics Display**
  - Average throughput now displays with 2 decimal places for precision

## [1.2.0] - 2026-01-27

### Added

- **Digit Recognition Page**
  - Interactive drawing canvas for handwritten digit input (0-9)
  - Real-time MNIST neural network inference on Tenstorrent simulator
  - Network architecture visualization showing layer activations and connections
  - Performance statistics tracking (average latency and throughput)
  - Confidence display with horizontal bar chart for all 10 digit classes
  - Trained 2-layer MLP model (784→128→10) achieving ~98% accuracy
  - New digit recognition API endpoints (`/api/digit/predict`, `/api/digit/model-info`)

- **Simple 2-Layer MLP Operation**
  - Configurable neural network architecture editor
  - Interactive network diagram showing input, hidden, and output layers
  - Configurable sizes: input (32/64), hidden (32/64), output (16/32/64), batch (16/32/64)
  - Parameter count display with real-time updates
  - Visual representation of layer connections and ReLU activation

- **Matrix Multiplication Operation**
  - Support for 32×32 and 64×64 matrix operations
  - Optimized for TTNN performance benchmarking
  - Added matrix multiply icon to operation selector

- **React Router Integration**
  - Separate pages for Digit Recognition (/) and Mathematical Operations (/math-operations)
  - Clean URL structure with browser navigation support
  - Navigation sidebar with page links

### Changed

- **UI Redesign**
  - Non-collapsible sidebar with fixed width (256px) for better text display
  - Simplified branding: "TTSim Playground" with chip icon
  - Mathematical Operations page header now matches Digit Recognition style
  - Operation selector reorganized into 4×3 grid by category
  - Updated icons for subtract (circle with line) and matrix
ttMandelbrot
communityMandelbrot Set fractal renderer running on Tenstorrent hardware. A classic demo showcasing parallel compute on Tensix cores.
tt-tutorial (HPC)
communityTutorial on Tenstorrent hardware for HPC researchers from the RISC-V Testbed project at Edinburgh/EPCC. Covers Wormhole from an HPC parallel-computing perspective.
TT-Metal Mini Template
communityMinimal working CMake project template for starting a new TT-Metal project from scratch. Good starting point for community kernel development.
tenstorrent-cli
communityA TypeScript/Bun terminal client for console.tenstorrent.com. Opens a chat REPL across DeepSeek-R1, Qwen3-32B, Qwen3-VL, and Gemma, with slash commands that submit image, Wan 2.2 video, TTS, and STT jobs, poll them, and save the results under ./output. Reads its API key only from the TENSTORRENT_KEY environment variable — never from disk.
ttPEAK
communityclpeak-style peak-performance benchmark for Tenstorrent devices using TT-Metalium. Measures theoretical peak throughput across operations — useful for hardware characterization.
Unofficial Blackhole Documentation
communityUnofficial documentation for the Blackhole P100A / P150, assembled from reverse-engineering, disassembly, and hands-on experiment. Walks from a self-contained intro through chip architecture (NoC, Tensix tiles, RISC-V cores, L1, memory map), the 3-kernel matmul model, SFPI kernel writing, circular-buffer dataflow, the JIT build and dispatch pipeline, firmware boot sequence, and multi-host scaling. The author notes most pages were drafted by coding agents, with a `human/` folder that is explicitly hand-written.
bhx
community★ featuredBoot stock Linux cloud images on the SiFive X280 RISC-V cores inside Tenstorrent Blackhole AI accelerators. Per-card Rust daemon with virtio-mmio block/net/console and U-Boot/EFI support.
📋 Changelog
# Changelog

Notable changes per release. Format loosely follows
[Keep a Changelog](https://keepachangelog.com/en/1.1.0/);
this project does not yet promise SemVer compatibility on the RPC
wire format or library API surface (we're not 1.0).

## Unreleased

V2 virtio-dispatch redesign. The kick ring + completion ring + host-
side throttle that grew up around #184 are gone; in their place is a
per-(slot, queue) dirty bitmap in BRISC L1. The bitmap is level-
sensitive — guest QUEUE_NOTIFY storms coalesce into a single set
byte, so the dispatch path can't fall behind under any burst. Wire
incompatible with 0.9.0; `TENSIX_PROTOCOL_VERSION` bumped 4 → 5.

### Added

- **V2 dirty-bitmap dispatch** (`#187` / `#188` / `#189`). BRISC
  writes 1 to `CTRL_OFF_DIRTY[slot][queue]` on every guest
  QUEUE_NOTIFY; the daemon's `Dispatcher` clears the byte and
  dispatches each pass. Replaces V1's 2048-entry kick ring +
  daemon-side `consume_kick_ring_pass` consumer.
- **V2 processed-cursor table** at `CTRL_OFF_PROCESSED`. Daemon
  publishes `used.idx` after each successful dispatch so
  warm-resume reads cursors directly without re-probing guest
  DRAM.
- **`bhx_notify_events_total`, `bhx_dispatch_passes_total`,
  `bhx_dispatch_queues_drained`** Prometheus counters surface the
  new dispatch path. The burst regression test (`scripts/
  soak_virtio_burst.py`) asserts `dispatch_passes_total > 0` to
  confirm the workload reached the new path.
- **`scripts/soak_virtio_burst.py`** — multi-queue burst regression
  test. Sustains 16-job direct=1 fio randwrite + a tight
  `printf` loop to `/dev/console`, samples `/metrics` every 1 s,
  and verifies the daemon log contains zero
  `kick.*drop|rescue|throttle.*ENGAGE` matches.
- **`DaemonState.chip_reset_this_session`** flag — gates
  `maybe_opportunistic_reset_board` so 4-way parallel cold boots
  reset the chip exactly once, not once per L2CPU. Without this
  the second-and-later resets blip the chip while earlier-booted
  L2CPUs hold mmap pages, SIGBUSing their workers.
- **`Dispatcher` (was `KickPoller`)** with documented testability
  seam (`CtrlL1Access` trait); `drain_dirty_bitmap` is unit-tested
  against an in-memory L1 fake covering all five visit/clear
  semantics cases plus the address-formula pins.

### Changed

- **`KickPoller` → `Dispatcher`**, plus `kick_poller` → `dispatcher`
  field on `DaemonState`, `tensix-kick-poller` → `tensix-dispatcher`
  thread name, `[kick-poller]` → `[dispatcher]` log tag,
  `kicks_consumed` → `dispatches_total`,
  `last_kick_slot_queue` → `last_dispatch_slot_queue`. Pure
  rename; no behavior change. V1 vocabulary scrubbed throughout
  the codebase (firmware, daemon, scripts, docs).
- **`CTRL_SIZE` shrinks 36 KiB → 4 KiB**. V2 footprint is ~1.5 KiB;
  the rest is reserved for future fields.
- **Stats-page offsets repacked** — V1 `STATS_OFF_KICK_DROPS`,
  `STATS_OFF_COMPL_EVENTS`, `STATS_OFF_LAST_COMPL` retired with
  V1 (#190); deprecated PRECAP / BLINDCAP / POSTCAP slots dropp
MuseGlimmer
communityA TTNN bring-up of `meta-models/Muse-Glimmer-30B` for batch-1 inference on a single Blackhole P150, with 2,048-token chunked prefill into a paged KV cache, the checkpoint's native DFlash drafter for speculative decoding, and an OpenAI-compatible server with streaming and tool calls. The author reports 119.99 AR tok/s at short context and 1,549 prompt tok/s on a 128,000-token prefill, and defines `ar_decode_tokens_per_second` narrowly: it excludes tokenization, prefill and tool parsing, and DFlash rate varies with draft acceptance. Weights are BFP8 for attention and BFP4 for MLPs, decode replays three captured device traces, and parity tests compare against the Transformers reference. Its custom `packed_kv_update` kernel was upstreamed into TTNN as `ttnn.experimental.indexed_fused_update_cache`.
tt-rl
community
Reinforcement learning trained natively on TT-NN: the networks, gradients, Adam step and device trace all run on the chip, while environments and replay buffers stay on the host. Ships DQN, PPO and SAC with Atari and MuJoCo configs, measured Blackhole results (Pong 17.8, Breakout 144.8, Hopper 3604), data-parallel training with one replica per chip, and export of trained policies to numpy or ONNX so they run on any CPU. Developed on a TT-QuietBox with four Blackhole chips; trained weights are published on Hugging Face.
ttperf
communityA CLI wrapper that turns TT-Metal performance profiling into one command. Runs a pytest target under Tenstorrent's profiler, streams progress live, then parses the resulting CSV and reports total device kernel duration. Supports profiling by operation name (`ttperf add`) as well as by test path, and installs from PyPI.
📋 Changelog
# Changelog

All notable changes to this project will be documented in this file.

The format is based on [Keep a Changelog](https://keepachangelog.com/en/1.0.0/),
and this project adheres to [Semantic Versioning](https://semver.org/spec/v2.0.0.html).

## [0.1.6] - 2025-01-14

### Added
- **Memory Configuration Support**: New command-line options for tensor memory configuration
- `--memory-config CONFIG`: General option with choices `[dram, l1]`
- `--dram`: Shortcut flag for DRAM memory (default)
- `--l1`: Shortcut flag for L1 memory
- Memory configuration extraction from CSV profiler output
- Memory config display in test result summaries

### Changed
- **Default tensor shape reduced from `[1, 1, 1024, 1024]` to `[1, 1, 32, 32]` for better performance**
- Enhanced `create_test_tensor()` function to accept memory_config parameter
- Updated all `ttnn.from_torch()` calls to use memory_config parameter
- Improved CSV extraction to read memory configuration from profiler output
- Enhanced debug output to show memory configuration

### Technical
- Added `validate_memory_config()` function with alias support
- Extended environment variable system with `TTPERF_CUSTOM_MEMORY_CONFIG`
- Updated operation_configs.json to include memory_config field
- Enhanced test file configuration parsing to handle memory settings
- Improved result reporting to include memory configuration details

## [0.1.4] - 2025-01-14

### Changed
- **Major Improvement**: Configuration extraction now reads from CSV profiler output instead of parsing text with regex
- Replaced 50+ complex regex patterns with structured CSV data parsing
- Enhanced `extract_test_config_and_status()` function to prioritize CSV data over text parsing
- Added new `extract_config_from_csv()` function for reliable configuration extraction

### Fixed
- More accurate shape, dtype, and layout detection from profiler results
- Improved reliability of configuration reporting in test summaries
- Better handling of tensor dimension parsing (e.g., "32[32]" format)

### Technical
- CSV-based extraction provides structured, consistent data vs. unreliable text parsing
- Maintains backward compatibility with text parsing as fallback
- Cleaner, more maintainable codebase with reduced complexity

## [0.1.0] - 2025-07-14

### Added
- Initial release of ttperf CLI tool
- Support for profiling TT-Metal tests with pytest
- Automatic CSV path extraction from profiler output
- Device kernel duration calculation
- Real-time output streaming
- Flexible command-line argument parsing
- Support for named profiles
- Comprehensive error handling

### Features
- Simple CLI interface: `ttperf [name] [pytest] <test_path>`
- Automatic detection of test files and paths
- Integration with TT-Metal profiler tools
- CSV parsing for performance metrics
- Real-time progress monitoring

### Dependencies
- pandas for CSV processing
- Python 3.7+ support
- TT-Metal development environment

## [Unreleased]

### Planned
- Enhanced error messages

##
current
communityHigh-level parallel programming framework for Tenstorrent accelerators, abstracting TT-Metal into a research-oriented programming model for parallel computation.
ttVecAdd
communityMinimal vector-addition example on Tenstorrent devices using TT-Metalium. A clean hello-world for the TT-Metal kernel programming model in C++.
tt-finetune
communityParameter-efficient fine-tuning — LoRA, rsLoRA, LoRA+, DoRA, and IA3 — on a single Blackhole P150a, behind a Hugging Face/PEFT-style trainer API. Ships as a self-contained Linux wheel bundling the TT-XLA/PJRT plugin, TTNN, and TT-Metal user-space libraries, so no source checkout, Docker, or PYTHONPATH setup is required. Includes a static planner that reports memory admission before you compile, deterministic checkpoint/resume, and standard PEFT adapter export.
2 previous releases
tt-model-bringup
communityDirect TT-Metal bringup of modern open-weight LLMs on Blackhole P150 — hand-written compute graphs with no PJRT and no JAX. Covers Qwen3.6-27B, Qwen3.6-35B-A3B MoE, Gemma 4 12B, and Nemotron-3 Nano 30B-A3B, plus a zoo of single-chip Llama / Qwen2.5 / SmolLM ports, backed by custom fused `owned_*` kernels, a continuous-batching engine, an OpenAI-compatible HTTP server, and a wiki documenting each design decision.
ttas
communityttas is a hacker-friendly assembler/disassembler for Tensix on Wormhole. It turns assembly into the exact 32-bit words the hardware runs, and turns binaries back into readable instructions using the same shared instruction table.
tt-tutorial (Korean)
communityComprehensive tutorials for the Tenstorrent software stack in Korean. Jupyter notebooks covering the full developer path from hardware setup to model inference.
ttRoPE
communityA GGML-formatted rotary positional embedding (RoPE) implementation for Tenstorrent hardware — one of the operator building blocks behind the community effort to give llama.cpp a Metalium backend.
Collective Operations on Wormhole n150 (Sapienza University of Rome)
communityMaster's thesis implementing and benchmarking five allreduce algorithms (Swing, Recursive Doubling, Bandwidth Optimal, Latency Optimal, Shared Memory) on the Wormhole n150. Bandwidth Optimal achieved best performance, approaching within 2× of theoretical optimal.
libtt-metal-cxx
communityRust crate that exposes the TT-Metal host API through a C++ bridge via cxx.rs — covering device management, program/kernel creation (from source file or inline string), circular buffers, semaphores, runtime arguments, sharded buffers, and MeshDevice workflows, with hardware-backed integration tests.
tt-bh-win (Blackhole Windows fan driver)
communityA minimal Windows KMDF driver that stops a Blackhole PCIe card's fan running at 100% on Windows hosts, where no in-box driver exists. On `D0Entry` it maps BAR0 (ported from `blackhole_init()` in tt-kmd), programs a kernel TLB window to the ARC NOC node, and sends the `ASIC_STATE0` (0xA0) ARC message that hands fan control to the on-die firmware; it also parses the telemetry table for debug output. It has no compute path and no user-mode interface. Confirmed on p100a and expected to work on p150a/p150b; builds with Visual Studio and the WDK and needs test signing to install.
ttWKV7
communityA standalone tt-metal demo and test bench for the RWKV-7 (WKV7) state recurrence on Wormhole, built with a GGML backend in mind. Two compute kernels cover the domain: a chunked-parallel DPLR matmul path for any sequence length with on-chip chunk carry, and a sequential per-token decode path for L <= 32 that is faster for large-batch token generation. The host runner validates both against a CPU oracle by PCC/NMSE and benchmarks them over a sequence/batch grid.
Kimi-Linear on Wormhole
communityA correctness-first bring-up of Kimi-Linear-48B-A3B on four n300 cards (8 Wormhole chips). Each hot layer type (KDA, MoE, MLA) is one fused program built from Python through `ttnn.generic_op` and a `ProgramDescriptor`, with no tt-metal fork or C++ rebuild. Per-layer gates check each kernel against an fp32 torch oracle before a full load. Decode went from 1.44 tok/s eager to 13.5 tok/s at 16K context once it moved to paged flash-MLA on the compressed latent. The author notes that chunked prefill is 28x faster but wrong, so it is disabled. `FINDINGS.md` lists 15 faults, three of them silent, and how each was found.
tt-monitor
community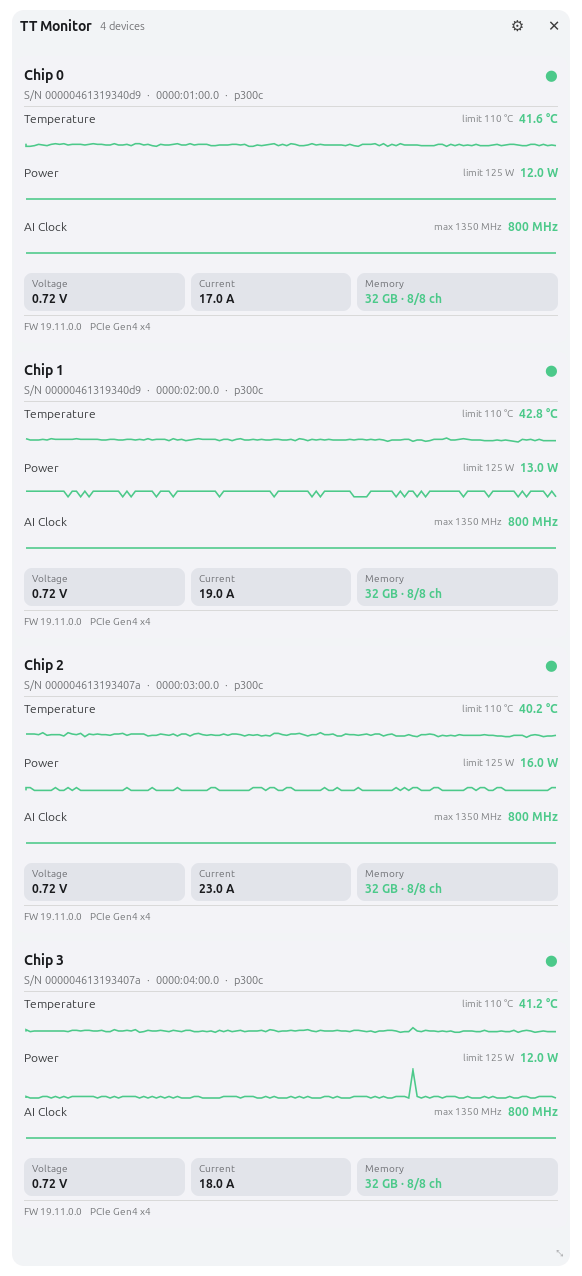
A translucent, undecorated desktop widget showing live per-chip telemetry for Tenstorrent accelerators: temperature and power sparklines against the card's thermal and TDP limits, AI clock, voltage, current, DRAM channel training and ECC error counts, PCIe link generation/width, and board identity. Reads hardware directly through luwen over /dev/tenstorrent — no Python, no tt-smi subprocess, and no root.
tetsuh/tt-metal-community-distro-matrix
community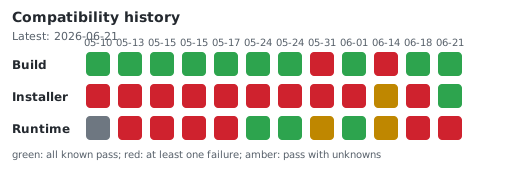
A compatibility guardrail that continuously monitors whether [tt-metal](https://github.com/tenstorrent/tt-metal) and the official [tt-installer](https://github.com/tenstorrent/tt-installer) build successfully on community Linux distributions that are not part of Tenstorrent's official CI.
metalium-rs
communityA native-Rust stack for Tenstorrent Blackhole with no Python, C++ or TT-Metalium dependency: bare-metal firmware for the baby RISC-V cores, host device access through tt-kmd, Tensix kernels, host tilize/detilize, and a Burn deep-learning backend. Burn MLP and small transformer models train on the card, with ResNet-18, ViT-Tiny and SmolLM2 inference checked against a reference backend. Developed bit-exact against ttsim and run on p150a cards, including two- and four-card meshes over Ethernet; Burn's own backend conformance suite runs on silicon, with the failing cases (matmul rounding, F64, BF16 resolution) listed with reasons.
tt-ldpc-qb2-sim
community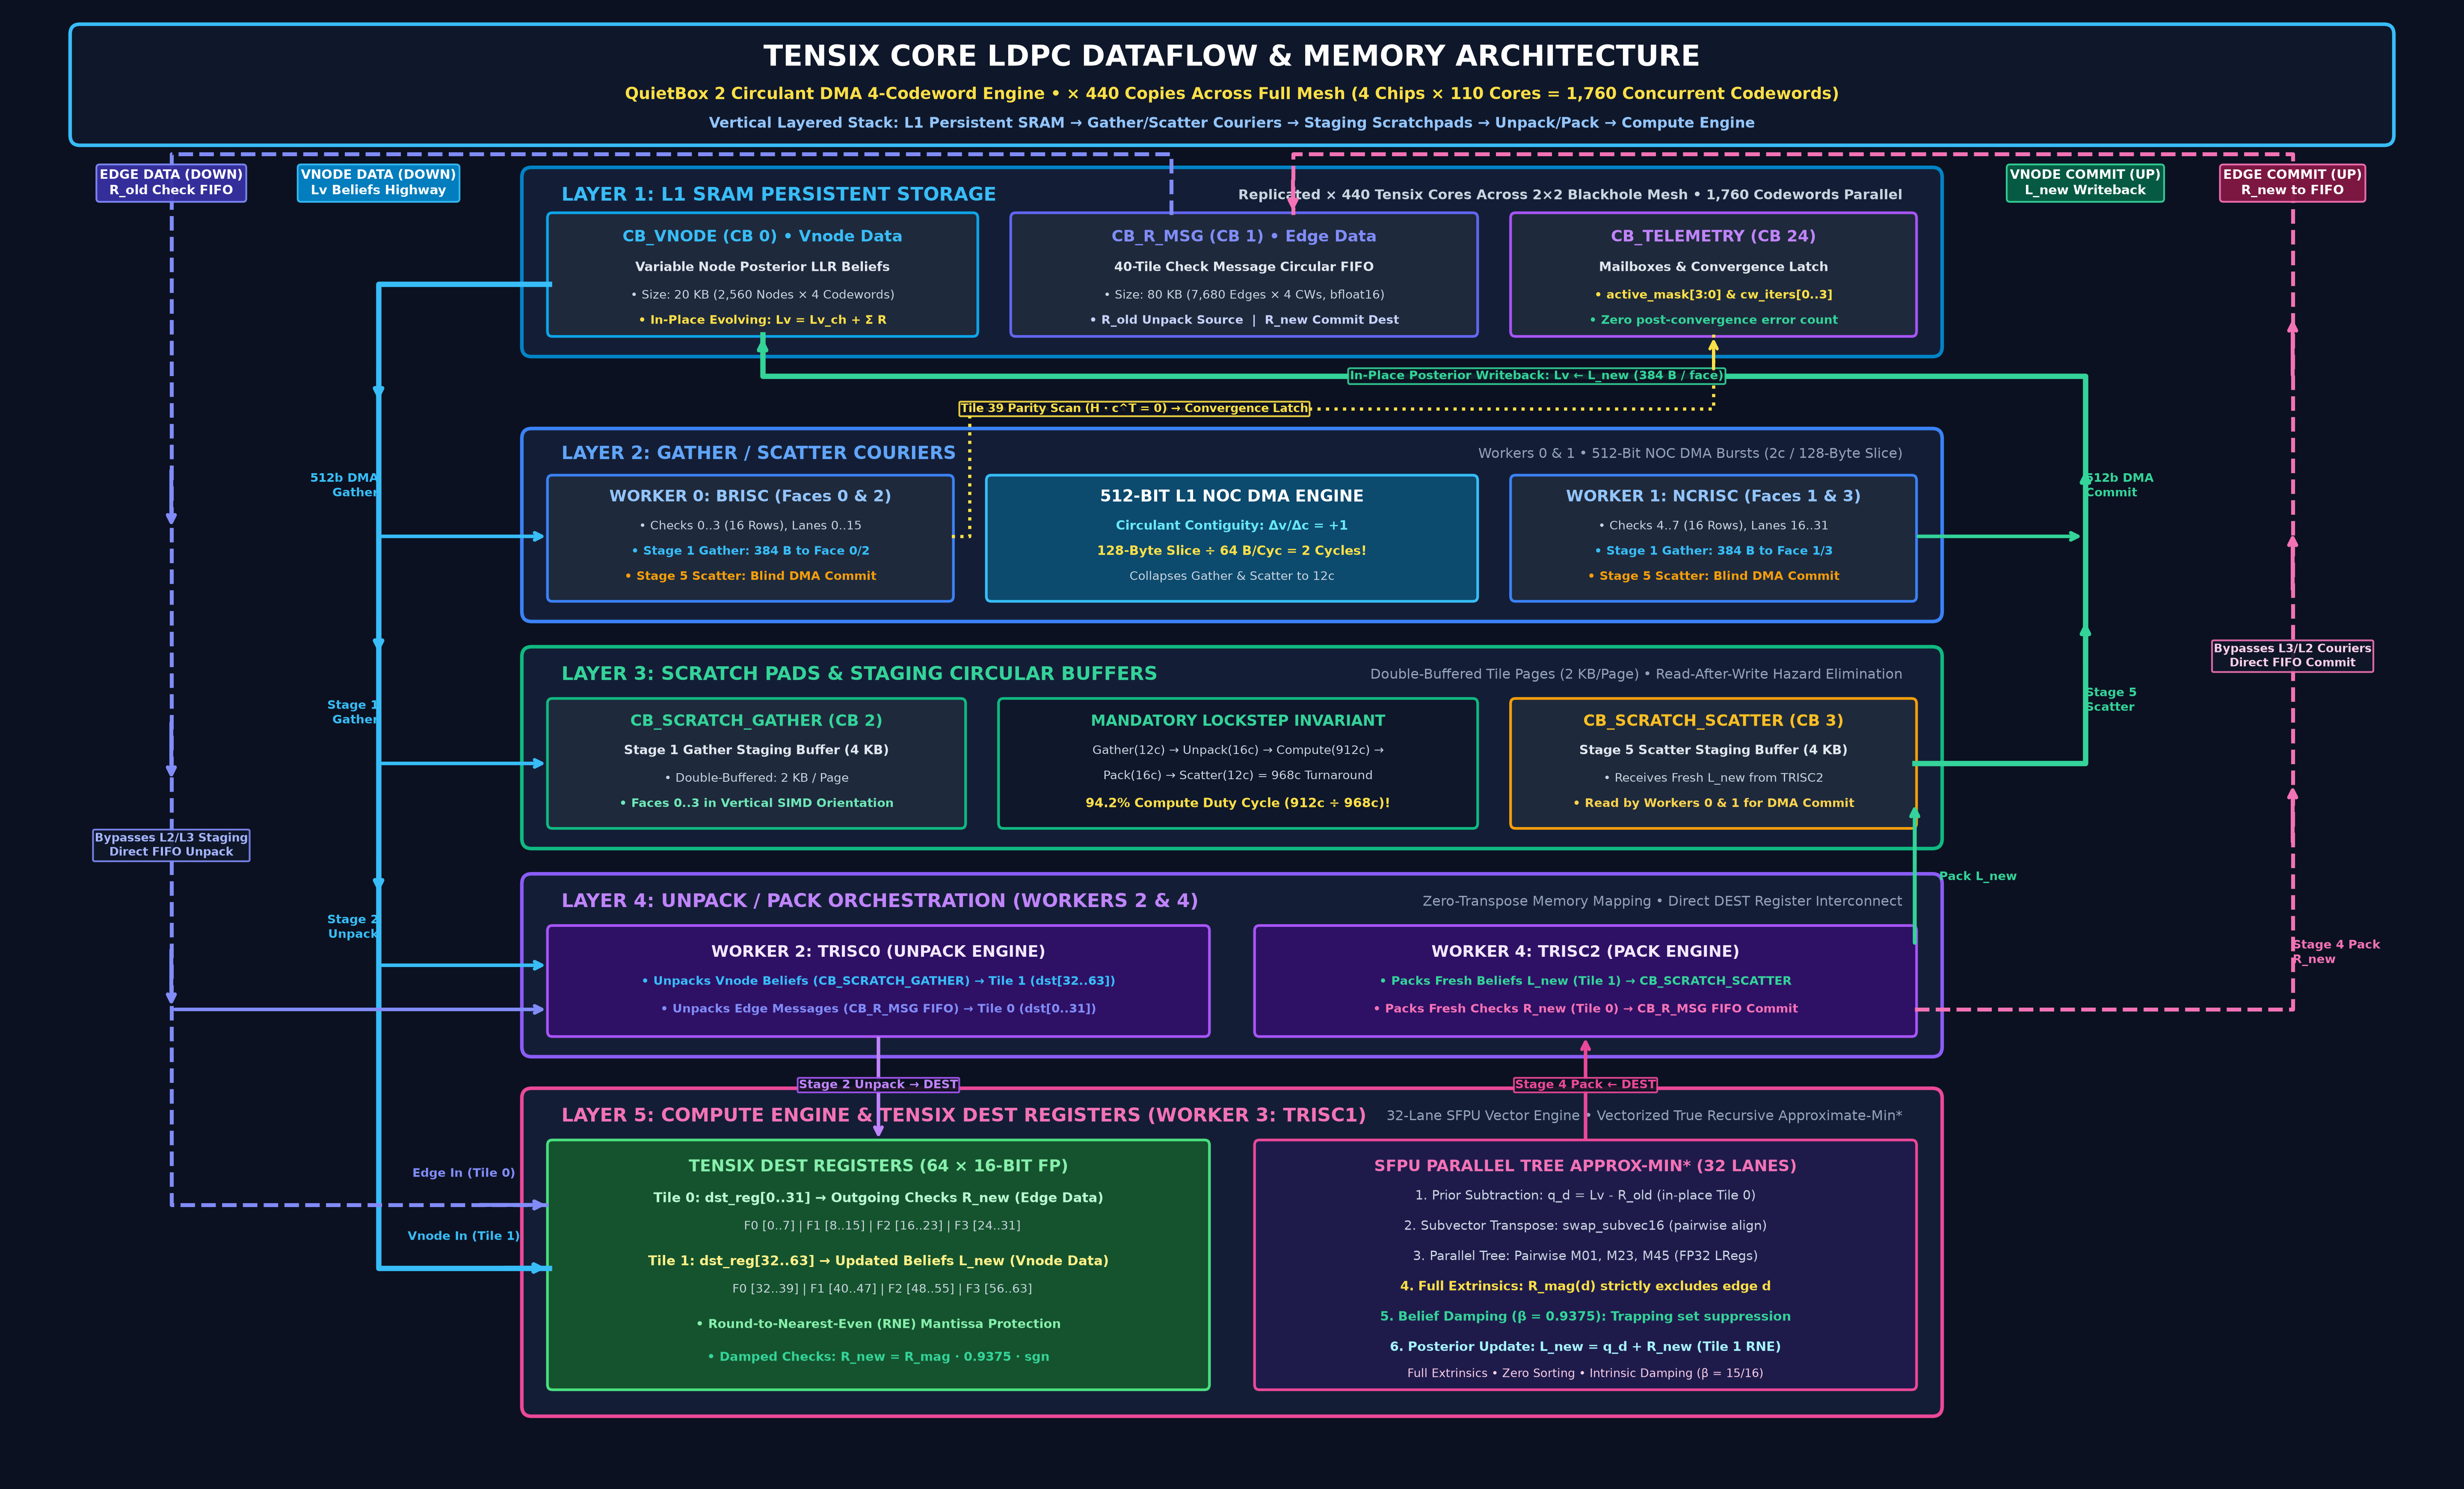
High-performance, multi-chip Monte Carlo LDPC (Low-Density Parity-Check) simulation framework targeting the Tenstorrent QuietBox 2 (QB2) equipped with 4 Blackhole processors in a 2x2 mesh topology (440 Tensix compute cores). The simulator features a hardware-optimized implementation of the Approximate-Min* constraint node updating algorithm developed by Christopher R. Jones et al., delivering full Belief Propagation (BP) error-correction performance at the execution speed of Min-Sum. The architecture can be mapping to any number of Tensix cores. The build is configured by default for a QB2.
tt-splat — matrix-native 3D Gaussian Splatting on Blackhole
community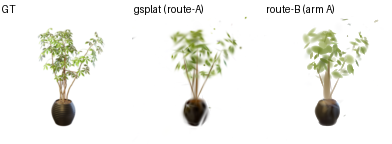
3D Gaussian Splatting rewritten to run on the matrix engine: a polynomial splat and order-independent weighted-sum blending replace exp and depth-sorted alpha, so the pipeline becomes GEMM → activation → GEMM. Renderer + trainer, trained device-resident on a Blackhole p150a.
tt-wavelet
communityOne-level FP32 lifting wavelet transforms (LWT) on Wormhole and Blackhole, shipped as a TTNN-linked op library plus standalone `lwt`, `ilwt`, `lwt_2d`, and `ilwt_2d` binaries and a benchmark harness. Builds the whole local stack — TT-Metal, the TTNN Python bindings, and ttnn-wavelet — against the TT-Metal revision pinned in its submodule.
ttPseudoRowMajor
communityA small TTNN-facing C++ library (ttprm) for running view-shaped tensor work without first materializing the view in DRAM. Targets Tenstorrent TILE tensors and uses cached device operations to gather/scatter through layout views.
DeepSeek-V4.1-Flash on Wormhole
communityA correctness-first bring-up of DeepSeek-V4.1-Flash (552B plus a 196B Engram) on four n300 cards (8 Wormhole chips). Every model FLOP runs on device, and the host serves as a 449 GB expert store of pre-packed `.tensorbin` tiles behind an on-device LRU pool. Every stage is gated against DeepSeek's official `model.py` run on the CPU, reaching 0.985 decisive top-1 over a 2048-token prefill, with traced decode, 128K context, persistent prefix state and vision input. Speeds are stated honestly: decode is 1.68 tok/s (1.42 served), prefill is 95 tok/s, and DSpark speculation measured 0.48x so it is off. `CEILING.md` attributes the gap to about 7,200 ops per token of device-side dispatch, and `FINDINGS.md` lists 20 traps.
Tenstorrent Kubernetes DRA driver
communityA Kubernetes 1.34 Dynamic Resource Allocation driver that publishes each node's Tenstorrent cards as exclusive whole-card devices, mixing Wormhole and Blackhole on one node. Ships a Helm chart with a node DaemonSet, a leader-elected controller that validates the cluster fabric graph, DeviceClasses, CRDs, health and metrics endpoints, and a TenstorrentWorkload resource that places distributed rank Pods on connected rings. Inventory comes from tt-kmd and PCI sysfs, and the ttsim QEMU VM is the validation target.
tt-tinygrad
communityA Tenstorrent backend for tinygrad that targets TT-Lang rather than raw tt-metal: a Renderer classifies each UOp kernel graph as matmul, reduce, or elementwise and emits ttl.math.* Python source, and a Compiled device parses the rendered kernel's contract, materializes ttnn tensors from host buffers, and calls it in-process. Proof of concept — 110 pass / 13 xfail across 125 cases on a QuietBox, covering fused matmul, reductions, softmax, layernorm, and attention chains, on top of a three-line patch to upstream tinygrad.
TTNN Eltwise Performance Tracker
communityDay-by-day performance dashboard for TT-Metal TTNN elementwise operations. Tracks kernel timings per operation across dates with baseline comparison, trend indicators, thirteen operation categories, and links from performance changes to the tt-metal commits that caused them. Deployed as a live site and updated by a bot.
Tensix Field Guide
communityA ten-chapter, plain-English tour of Tenstorrent's Tensix architecture written for someone who knows what a CPU and a GPU are and nothing else: the chip-level grid and NoC, the five RISC-V baby cores, the matrix engine and its LoFi/HiFi fidelity trade-off, the SFPU, L1 and circular buffers, and why everything is 32x32 tile-shaped. The goal is to get a newcomer to the point of reading tt-metal kernel code in one sitting. Self-described draft; every claim traces back to tt-metal tech reports, tt-llk docs, or METALIUM_GUIDE.
Minicurso SSCAD 2026: Tenstorrent com TT-Metalium
communityCode for the SSCAD 2026 short course "Arquitetura Tenstorrent e programação com TT-Metalium" (in Portuguese). The chapter's listings are extracted straight from this repository, and everything runs on the ttsim Wormhole simulator inside a Docker Compose setup, so no hardware is needed to follow along.
TensixFuse
communityFused and block-float ML kernels for Tensix cores, written in TT-Lang and by hand in TT-Metalium C++, measured on Tenstorrent's simulators. Quantifies how much DRAM traffic kernel fusion and data reuse save on a fused matmul-bias-ReLU, and how far GPT-2 MLP weights can be pushed into bfloat8_b and bfloat4_b before accuracy drops, with an analytic traffic model that matches the simulator tile for tile. CI runs the studies on simulated Wormhole and Blackhole on every change.
autoresearch-tenstorrent
communityA single-device TT-XLA port of karpathy/autoresearch: an AI agent edits a small GPT training script, trains for a fixed five minutes on a Wormhole card, keeps the change if validation bits-per-byte improves, and repeats overnight. Adds device glue so the code never branches on CUDA.
cjllm-harness
communityA lightweight, single-file, zero-framework Python CLI inference and search-augmented generation harness ([cjllm.py](https://github.com/palisurf/cjllm-harness/blob/main/cjllm.py)) built for OpenAI-compatible vLLM endpoints running on local AI workstations and accelerator appliances (including Tenstorrent QuietBox 2 (p300x2 Blackhole)
DFloat11-TT
communityDFloat11 lossless LLM weight compression ported to Blackhole. Huffman-codes only the exponent field of BFloat16 weights, cutting them to about 70% of their size with bit-for-bit identical outputs, with a C++ extension built against tt-metal, a compressor and an on-device evaluation path.
granite-4.1-tt-metal
communityA community port of IBM Granite 4.1-8B to Wormhole through tt-metal and the Tenstorrent vLLM plugin, with the porting code, a verification harness and measured performance results. The author states the project is not affiliated with IBM, Tenstorrent or Networld.
TT-Granite
communityA TTNN port of IBM's Granite-4.0-H hybrid Mamba2/attention/MoE models (tiny and small) to Wormhole, written as a UCL thesis project and run on submeshes of a Galaxy. Includes two custom TT-Metal kernels, `ssm_update` and `conv1d_decode`, that fuse the Mamba2 decode step, plus decode trace capture and benchmark scripts against HuggingFace CPU/CUDA baselines. With trace enabled the author reports 10.65–10.69 tok/s for tiny on 4 chips (about 18% above an A100) and 5.84–5.89 tok/s for small on 8 chips (about 20% below the A100); all numbers are batch 1, and the fused kernels add only about 1–2%. The thesis PDF documents the porting challenges: quantization, SSM state across chunked prefill, and expert-parallel sharding.
M-Stack
communityMultiCoreWare's declarative Python SDK for building AI inference platforms on Kubernetes, from bare machines to a served model. Tenstorrent is a first-class accelerator type: the Helm layer installs the tt-operator chart and the serving layer exposes OpenAI-compatible endpoints over vLLM.
tt-metrics-exporter
communityA Kubernetes metrics exporter for Tenstorrent Wormhole and Blackhole clusters, written in Python. Runs as a node-local DaemonSet, reads telemetry through sysfs and the tt-kmd device paths, and optionally reports DRA state. Includes a QEMU ttsim VM setup for testing without hardware.
Annotation-Driven CUDA to Tenstorrent Migration
communityArtifact for a paper on an MLIR-based compiler pipeline that migrates a statically shaped affine subset of CUDA to Tenstorrent Blackhole. Processor assignment, guard realization and buffer streaming are given as declarative annotations the compiler checks and lowers through tt-mlir. Holds the intermediate representations at every stage, the compiled programs for Gaussian elimination, a 2D Jacobi stencil and SYRK on a 10x10 core grid, and scripts that reproduce each timing and accuracy number, including the A100 comparison.
ferrite
communityA from-scratch userspace software stack for Tenstorrent Blackhole in about 1,900 lines of Python. It talks to the card over PCIe, loads firmware onto Tensix cores, compiles tensor expressions to Tensix instructions, and runs and serves GPT-2, SmolLM and Llama-family models, with tinygrad integration and training examples. It does not use the Tenstorrent kernel driver, tt-umd, tt-metal or LLK beyond the card firmware, and can run against the TTSIM simulator.
bhtop
communityA top for the Blackhole network-on-chip: live NoC telemetry read straight from the per-tile NIU hardware performance counters, drawn as a die floorplan in the terminal, plus a web cockpit with a device tree, a code editor and a live engine pane for bare-metal L2CPU x280 work.
SimBricks component-tenstorrent
communitySimBricks integration for Tenstorrent's ttsim chip model, from MPI-SWS. About 700 lines of C++ present libttsim as a SimBricks PCIe device, so a simulated host can boot Linux, load the real tt-kmd driver and run a PyTorch workload on a simulated Wormhole or Blackhole. The chip model is loaded at runtime and left unmodified.
torpedo
communityA persistent HTTP telemetry server for Tenstorrent cards. It keeps one device-discovery context alive, samples `tt-smi` 6.3.0 telemetry on a background thread, and serves the latest snapshot as JSON at `/v1/devices` with a `/healthz` check, rediscovering devices with exponential backoff after a reset. It marks a device as held when other processes appear in `/proc/driver/tenstorrent/<n>/pids`, and reads allocated GDDR passively from tt-metal's `/dev/shm` allocator region without opening a Metal context. Written in Python with `luwen` (default) and `umd` backends and a systemd unit; the repo also includes `watchgpu`, a shell script that shows CUDA, Tenstorrent and Apple Silicon hosts side by side over SSH.
TTNN Ops Coverage Matrix
communityInteractive dashboard of the TTNN operation test matrix: every elementwise op across eight dtypes, two layouts and five memory configurations, with scalar, row and column broadcast modes for binary ops, classified as pass, PCC failure or hard error, with the PCC and ULP error against a torch golden for each cell. The data comes from a published probe script, and the zero-dependency front end works offline.
xpustat
communityA unified accelerator stat tool in the style of gpustat that covers every vendor it can find a CLI for. Tenstorrent Wormhole and Blackhole cards are read through tt-smi alongside NVIDIA, AMD, Intel, Huawei, AWS Neuron and TPU backends.
Inside the Tenstorrent Chips: Grayskull, Wormhole, Blackhole, and Galaxy
communityA long third-party walkthrough of the Tenstorrent lineup — core architecture, per-product specs and pricing, and what the published benchmarks against NVIDIA and AMD actually support. Notable for its candour: it states plainly that independent third-party benchmarks remain sparse and flags firmware changes that reduced earlier performance claims. Part 4 of a six-part series on inference hardware.
A Gentle Guide: Tenstorrent Card on Arch Linux with Metalium
communityStep-by-step guide to getting a Tenstorrent card running on Arch Linux with the full Metalium stack. Practical troubleshooting from someone who did it the hard way first.
Thoughts and Logs After Messing with Tenstorrent Grayskull
communityHonest field notes from getting a Grayskull card running and writing first Metalium kernels. Covers setup pitfalls, processor hangs, memory protection quirks, and what makes Metalium compelling despite early rough edges.
Programming Tenstorrent Processors
community★ featuredDeep-dive into the Tenstorrent architecture and Metalium programming model — circular buffers, kernel synchronization, NoC routing, and where the footguns are. The honest guide to thinking in Tensix.
Tenstorrent Architecture — W&M CSCI654 Advanced Computer Architecture
communityLecture 20 from William & Mary's graduate Computer Architecture course. Frames Tenstorrent in the landscape between GPUs and TPUs, draws comparisons to Cerebras and SambaNova, then dives deep into the Wormhole chip and Tensix core: the 5 RISC-V core design, SFPU, NoC, and dataflow execution model.
QuietBox 2 vs DGX Spark
communityJustin Garrison's benchmark harness and results page comparing a Tenstorrent QuietBox 2 against one and two NVIDIA DGX Sparks on open-weight models: time to first token, decode speed per user, total throughput, wall power and running cost under coding-agent-shaped traffic, with quality scores from the Artificial Analysis index.
baretile
communityA compiler and runtime for Tenstorrent Blackhole written in about 2,700 lines of standard-library Python. You write tensor operations and it compiles them to Tensix instructions, loads its own worker firmware and drives the card over PCIe from userspace, with no dependency on tt-metal, tt-umd or LLK. Developed against the ttsim simulator; untested on a card so far.
Tenstorrent SFPU Kernel Series — Jason Davies
community★ featuredSponsored series of deep technical articles on implementing optimal SFPU kernels for the Tenstorrent Wormhole and Blackhole vector units. Covers where, typecasting, 16/32-bit integer multiplication, cube root, and accurate sin/cos/tan — with cycle counts, assembly walkthroughs, and Blackhole vs Wormhole comparisons throughout.
tt-rqm-kernels
communityStructured quaternion, rotor, and phase-aware tensor kernels on ordinary floating-point tensors, plus StructuredBench. Includes CPU/PyTorch references, simulator and emulator paths, and reproducible Wormhole/N300 evidence for quaternion multiply (`qmul`), fused SU(2) composition, and H2A Hamiltonian lowering.
stable-diffusion.cpp on Tenstorrent
communityA fork of stable-diffusion.cpp whose tt-support branch runs Z-Image Turbo and Qwen Image 2.1 on a Blackhole card through the community ggml Metalium backend, adding the operators those models need, routing flash attention to TTNN prefill SDPA and emitting ttnn-visualizer memory reports.
3D Jacobi Stencil on Blackhole (CARLA 2026)
communityReference implementation for the CARLA 2026 paper "Shift Matrices and Single-Batch Halos: Optimizing 3D Stencils on Tenstorrent Blackhole Architecture". A TT-Metalium 3D Jacobi stencil kernel for the p150a that uses shift matrices and single-batch halo exchange, with build and run scripts for reproducing the paper's results.
HPCCG on Tenstorrent (Daisytuner)
communityDaisytuner's case study porting the HPCCG conjugate-gradient mini-app to Wormhole and Blackhole: the SPMV, WAXPBY and DDOT kernels run on Tensix cores over an ELLPACK matrix layout, with the Daisytuner Optimizing Compiler Collection (DOCC) handling parallelisation and offload.
OpenFOAM-TT
communityDaisytuner's build of OpenFOAM's core libOpenFOAM as a standalone CMake project, with symbol-equivalent replacements that offload its sparse matrix operations to Tenstorrent hardware. The result drops into the original OpenFOAM driver via LD_LIBRARY_PATH, so offloading strategies can be explored without touching the solvers.
Attention in SRAM on Tenstorrent Grayskull
communityA fused kernel for the Grayskull architecture implementing Transformer self-attention entirely within SRAM. Combines matrix multiply, attention score scaling, and Softmax without DRAM accesses, achieving significant speedups over non-fused implementations.
Exploring Fast Fourier Transforms on the Tenstorrent Wormhole
communityPorts the Cooley-Tukey FFT algorithm to the Wormhole n300 RISC-V accelerator. The Wormhole draws 8× less power and consumes 2.8× less energy than a 24-core Xeon Platinum for a 2D FFT. ISC 2025.
Assessing Tenstorrent Grayskull RISC-V MatMul Acceleration for LLMs
communityEvaluates the Tenstorrent Grayskull e75 RISC-V accelerator for matrix multiplication at reduced numerical precision (BFP8 and LoFi), a fundamental kernel in LLM inference computation.
Porting Strategies for Gravitational N-Body Simulations on Tenstorrent Wormhole
communityEvaluates three strategies for scaling an N-body code across multiple Tenstorrent Wormhole accelerators. Builds on the established performance of single-card N-body work to explore parallelism via the on-chip NoC and multi-accelerator configurations.
Accelerating Gravitational N-Body Simulations on Tenstorrent Wormhole
communityAccelerates an astrophysical N-body simulation on the Wormhole n300. Achieves 2× speedup and 2× energy savings over a highly optimized CPU implementation. SC '25 Workshop.
Numerical Kernels on a Spatial Accelerator: Tenstorrent Wormhole
communityImplements three numerical kernels and composes them into a conjugate gradient solver on Wormhole. Demonstrates AI accelerators merit consideration for HPC workloads traditionally dominated by CPUs and GPUs. 2026.
Accelerating Stencils on the Tenstorrent Grayskull RISC-V Accelerator
communityExplores stencil computation on the Grayskull PCIe RISC-V accelerator. Early academic work examining TT hardware for HPC stencil workloads. 2024.
Stencil Computations on Tenstorrent Wormhole
communityMaps 2D 5-point stencil computations onto the Tenstorrent Wormhole RISC-V AI dataflow accelerator via two implementations: element-wise decomposition (Axpy) and matrix-multiplication reformulation (MatMul). Profiling shows the isolated Wormhole kernel is competitive with CPU execution, with PCIe transfers and initialization driving end-to-end overhead; Axpy achieves lower energy than the CPU baseline at large scales. Identifies architectural and software directions for making AI accelerators viable for HPC stencil workloads. 2025.
SwiftNPU: Scalable Shape-Flexible Allocation for Inter-Core Connected NPUs
communityMakes multi-tenant NPU sharing practical for Blackhole-class hardware using polynomial-time allocation algorithms. Delivers up to 1.37× higher utilization and 1.14× faster workload completion. Up to 890,000× faster than NP-hard baselines.
TileLoom: Automatic Dataflow Planning for Spatial Dataflow Accelerators
communityCompiler system that automatically generates efficient dataflow plans for tile-based languages on spatial accelerators including Tenstorrent Wormhole. Exploits on-chip network forwarding between processing elements to reduce DRAM pressure.
Rewriting TTS Inference Economics: Lightning V2 on Tenstorrent vs. NVIDIA L40S
communityShows that Text-to-Speech inference on Tenstorrent Lightning V2 achieves 4× lower cost than NVIDIA L40S. Applies BlockFloat8 (BFP8) and low-fidelity (LoFi) precision strategies to TTS despite their greater numerical fragility compared to LLMs.
Block-Sparse Linear Algebra on Tenstorrent Wormhole
communityArtifact for the paper "Leveraging Network-on-Chip Architecture for Block-Sparse Linear Algebra on Tenstorrent": block-sparse SpMM and SDDMM kernels for the Wormhole n150 in several data-movement variants, plus scripts that reproduce every n150 figure and table. Builds as a submodule inside a tt-metal checkout.
Tenstorrent Blackhole Architecture Guide
community★ featuredA 6,500-word community deep dive into the Blackhole p100a architecture: the tile model (Tensix, DRAM, SiFive x280 L2CPU, Ethernet, PCIe, NoC arc), firmware startup sequence, MOP micro-op processor, replay buffer, FPU/SFPU sync, and the anatomy of a kernel. From the author of blackhole-py.
Tenstorrent Wormhole Series (corsix.org)
communityPeter Cawley's eight-part reverse-engineering series on Wormhole: physical layout and disabled rows, NoC propagation delay, Ethernet, the insides of a Tensix tile, the vector instruction set, bits of the matmul unit and a closing reference. The companion repo is a functional description of the vector instructions.
All in RISC-V, RISC-V All in AI — FOSDEM 2026
communityMartin Chang and Danfeng Zhang on solving real AI compute problems with open hardware, spanning AI PC / edge devices and AI servers: pairing high-performance RISC-V CPUs with NPUs, and Tenstorrent's RISC-V cores and scalable mesh for AI workloads. The speaker's companion write-up covers the Tensix programming model in depth — the five RISC-V cores per tile, Dst register double-buffering, and the macro-recording hardware that lets control cores run ahead of the math engine.
WebNN and WebLLM on RISC-V — FOSDEM 2026
communityYuning Liang and Petr Penzin on closing the AI acceleration gap in the browser on RISC-V: how WebNN and WebLLM can reach efficient on-device inference using the RVV 1.0 variable-length vector ISA and Tenstorrent hardware underneath.