-
7.75.1 Sep 10, 2026
We reverted the Wormhole RAW hazard mitigation from 7.75.0 after finding it imposed unacceptable performance penalties—your kernels should see measurable speedup on Wormhole devices.
-
7.75.0 Sep 9, 2026
The compiler now compares ordering and equality more efficiently across architectures—using dedicated comparison instructions where available and bitwise equality on Quasar to handle infinities correctly—while tackling a hazard on Quasar where
sfpstorefollowed by immediatesfploadreads stale data through load merging andsfpnopinsertion. Wormhole's read-after-write hazard avoidance also improved to catch additional cases, and the compiler can now elide redundantsfploadinstructions that simply retrieve a value written moments before, reducing unnecessary register traffic on all architectures.
A hidden dimension of Tenstorrent awesomeness
A curated directory of projects, tools, models, and research for Tenstorrent hardware — contributed by the community and our team. Browse by category or search across all entries.
Planet Tenstorrent is the ecosystem's live feed — new releases, articles, papers, talks, and community posts from across the Tenstorrent world, gathered in one place and updated daily. The latest five:
This release primarily fixes errors and modernizes lessons about the TT-QuietBox 2 and working with ttsim.
The visualizer can now expose performance triage to an agent over MCP with four bounded tools—load, top operations, zone timings, and diff—letting you interrogate a 10⁴–10⁵-row report without flooding context, which matters when you're debugging a training run and need answers fast. Layer-aware grouping now folds attention, feed-forward, expert routing, and other semantic blocks automatically, surfacing one-off operations like embeddings and output heads that were previously buried; weight-loading fans collapse to single nodes so they stop dominating the screen on dense models like sentence_bert and bge_m3. The performance table now reads CSV columns by name instead of position, stays in sync with tt-perf-report 1.3.0's Sub Device and Available Cores fields, and core-count colouring respects Blaze's actual available cores—plus a fix for report linking when nested operations come back out of order, and event logging now works on the hosted app with per-session privacy and rate limits.
tt-smi v6.5.0 updates the underlying tt-umd dependency to 0.9.10, bringing fixes and improvements from the UMD layer that support more stable device monitoring and management. If you're using tt-smi to inspect or manage Tenstorrent hardware, this release ensures you're working with the latest driver improvements.
This release pulls in tt-bio 0.7.3's fix for ragged-token padding, addressing a correctness issue that could affect tokenization pipelines with variable-length sequences. Literature updates too.
This site is two old traditions sharing one orbit: an awesome list and a planet. Open source is an ecosystem the way space is — moonshot projects igniting into galaxies of forks and stars, and planet sites keeping the whole universe in view. (Around here the metaphor is load-bearing: we ship hardware called Galaxy.) Both traditions are gifts from decades of that culture, and both deserve some tribute.
🕶 The awesome list
Humans curating links for other humans is the oldest genre on the web —
Yahoo! began life in 1994 as "Jerry and David's Guide to the World
Wide Web", and the volunteer-run
DMOZ / Open Directory Project
kept hand-sorted order for two decades. In 2014, Sindre Sorhus distilled
that instinct into a GitHub-native microformat with
sindresorhus/awesome:
one README, a ruthless curation bar ("only awesome things"), and pull
requests as the editorial process. The
awesome manifesto
turned list-making into a commons — thousands of lists,
lists of lists,
and giants like
awesome-python,
awesome-selfhosted, and
awesome-go.
Synth heads are gloriously covered too:
awesome-musicdsp,
awesome-audio-dsp,
awesome-webaudio, and
awesome-supercollider.
Because the format is halfway to being a database, people have long
rendered lists into websites — tt-awesome just commits to the bit:
every entry is a JSON file, and the README, this site,
data.json, and the feeds are all built from the same source.
🪐 The planet
In the early 2000s, Jeff Waugh and Scott James Remnant wrote Planet, a little Python feed aggregator that river-merged a community's blogs into one page — and free software communities never looked back. Planet GNOME, Planet KDE, Planet Debian, Planet Gentoo, Planet Ubuntu, Planet Fedora (the Red Hat family), and Planet Mozilla are all still ticking decades later, many having passed through Sam Ruby's Planet Venus rewrite along the way. The lineage runs deeper still: before planets there were blogrolls, and before blogrolls, web rings — WebRing was built in 1995 by a teenaged Sage Weil, who grew up to create Ceph, which is about as open-source-full-circle as a story gets. Planet Tenstorrent carries that torch for this ecosystem.
⚡ Why we bother
Curated commons like these only exist because communities keep them alive in the open. That's not nostalgia to us — it's the plan. Open source is our past, present, and future.
No entries match the current filters.
Select an entry to see details
tt-metal
official
TT-NN operator library and TT-Metalium low-level kernel programming model. The primary SDK for developing on Tenstorrent hardware — from high-level tensor ops to bare-metal RISC-V kernels.
5 previous releases
tt-forge
official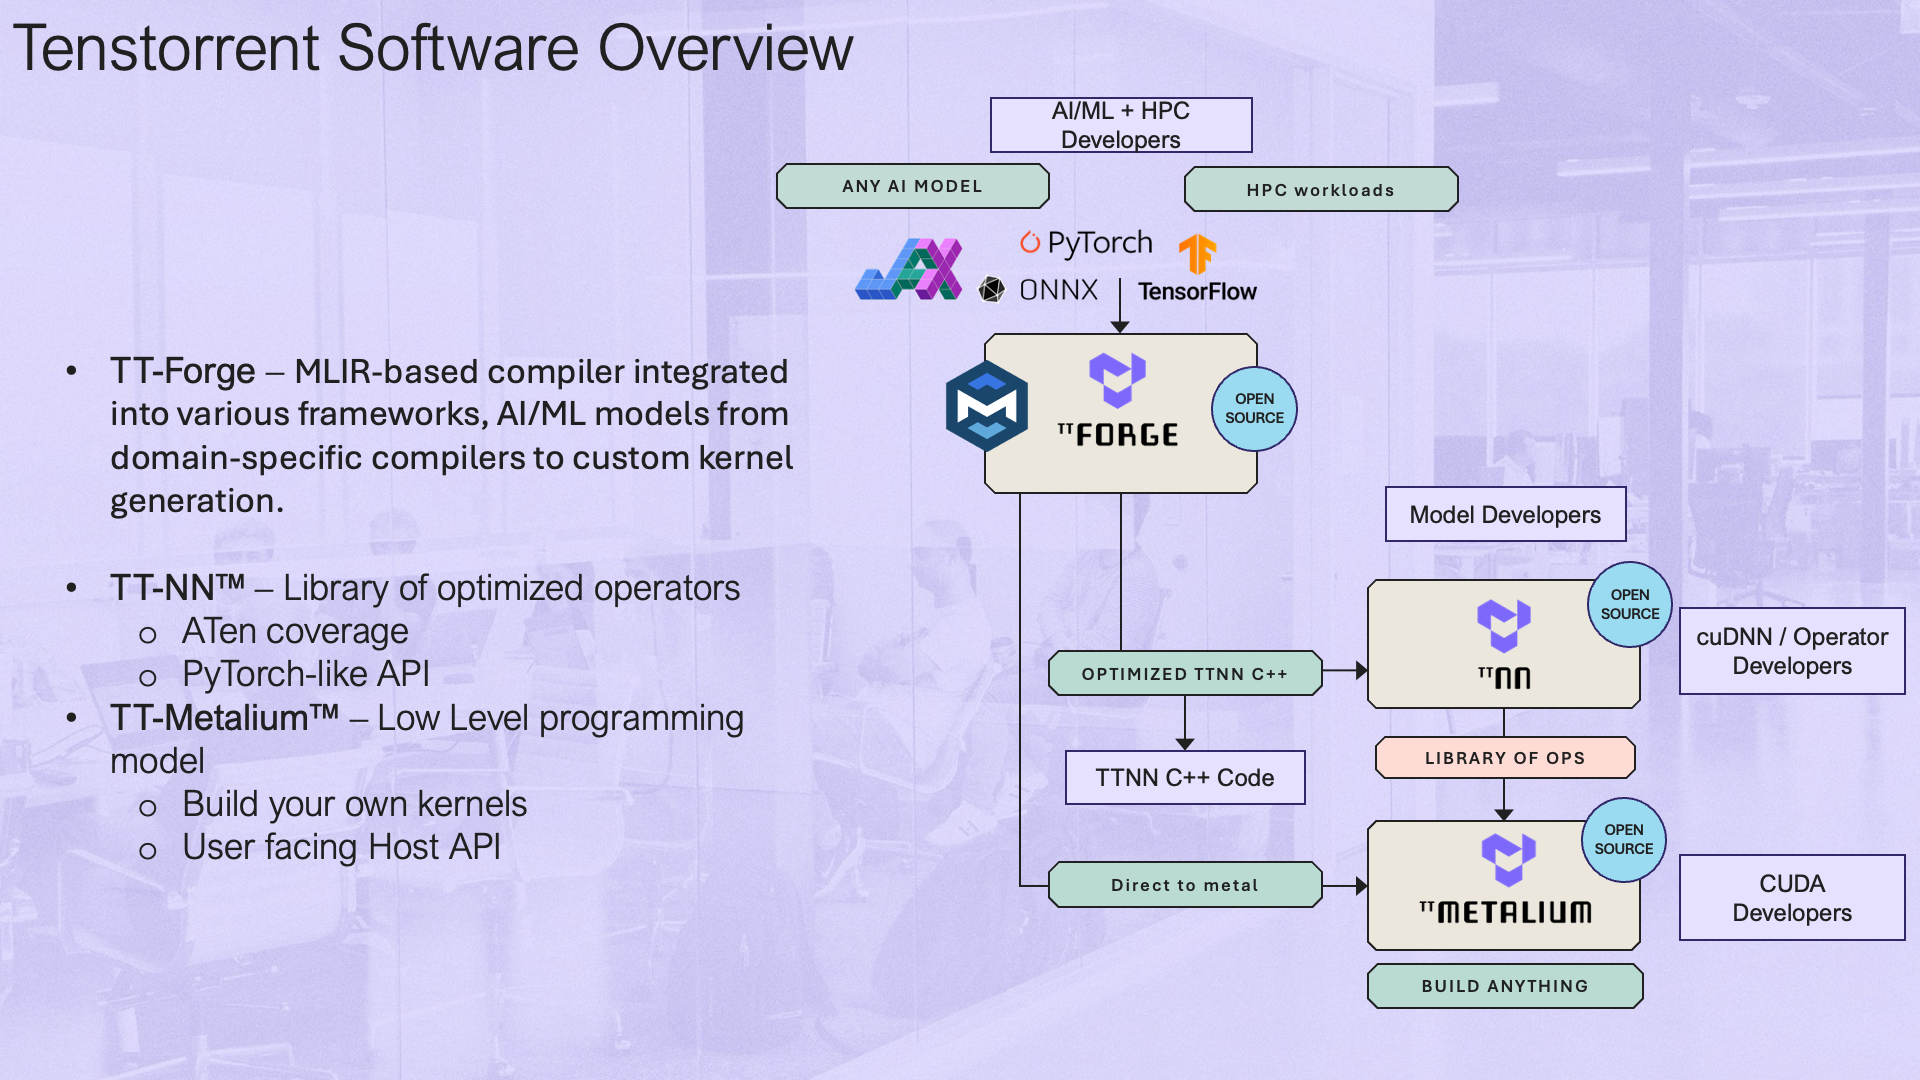
Tenstorrent's MLIR-based compiler frontend. Enables running AI workloads from PyTorch, ONNX, and other frameworks on all Tenstorrent hardware configurations through an open-source, general, and performant compiler.
5 previous releases
tt-buda
officialTT-BUDA: Tenstorrent's original Python compiler and runtime for AI workloads. Legacy stack — tt-forge is the recommended successor, but tt-buda has the largest model demo library.
4 previous releases
tt-mlir
officialTenstorrent MLIR compiler — the core compiler infrastructure shared by tt-forge and other frontends. Handles graph optimization, lowering, and code generation for Tensix hardware.
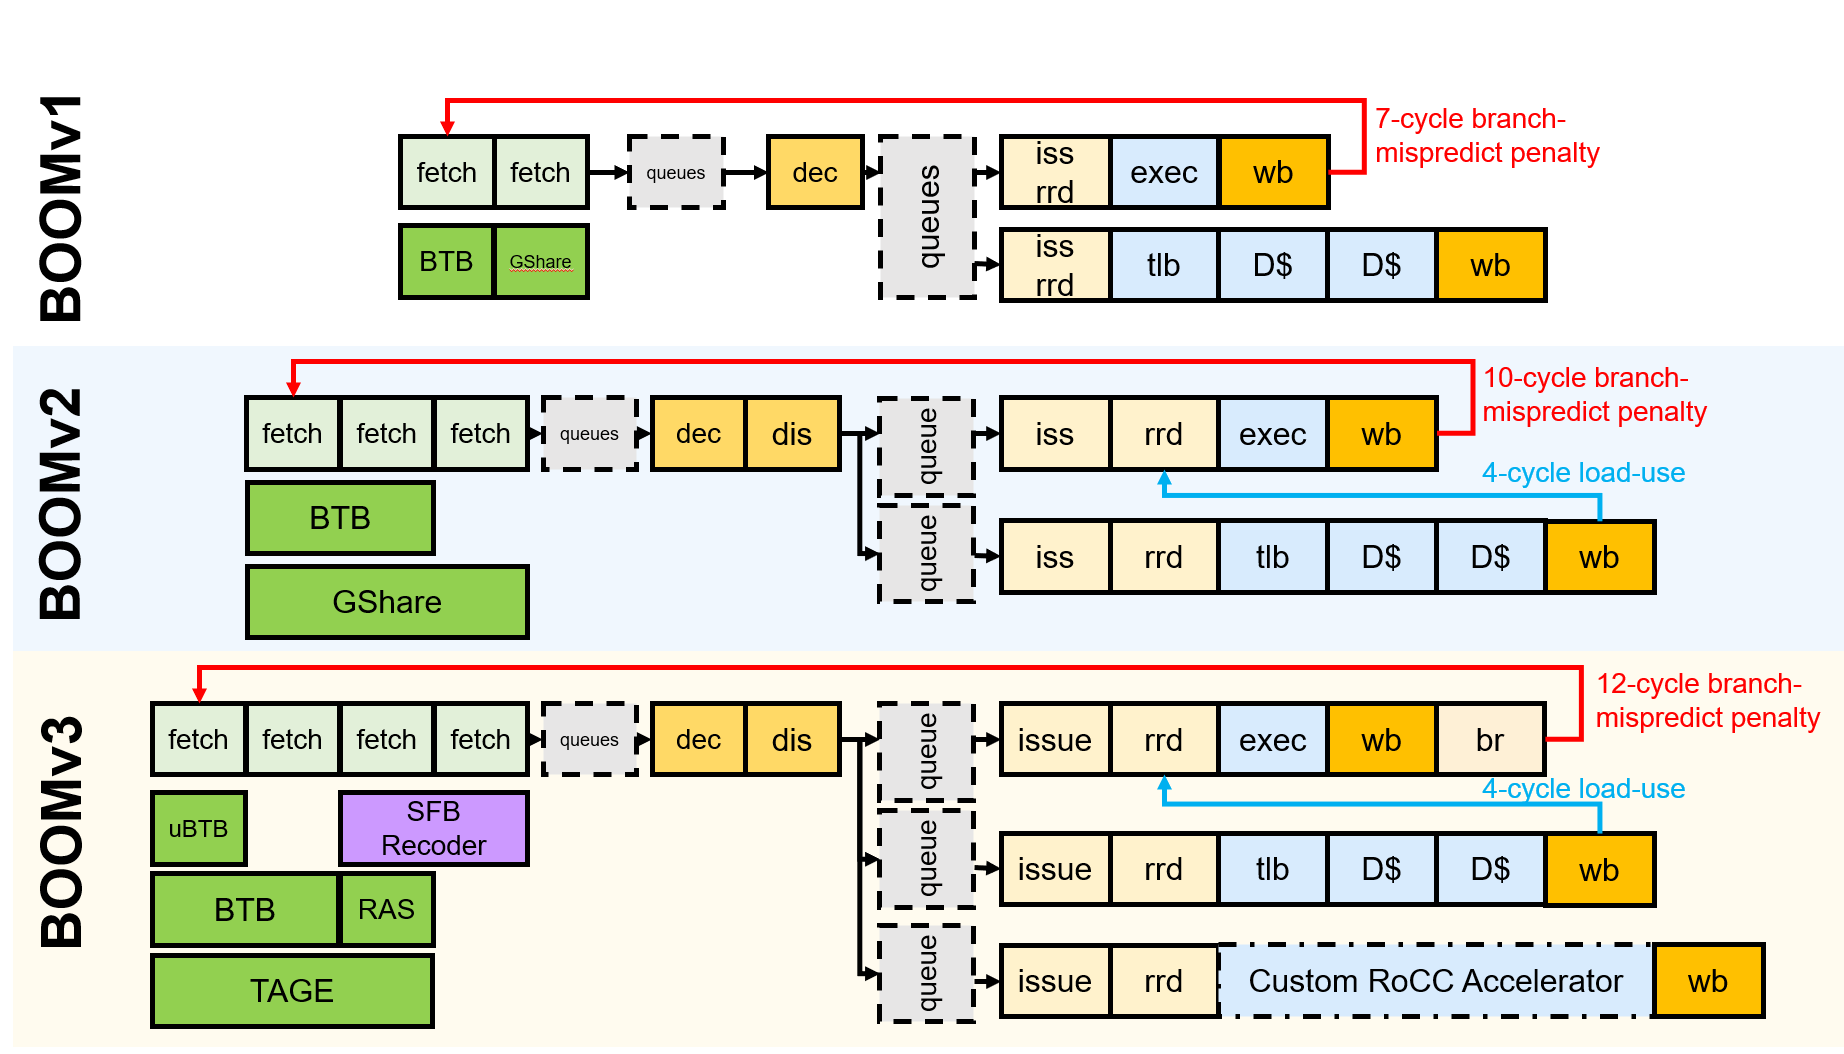
The Berkeley Out-of-Order Machine with V-EXT (RISC-V Vector Extension) support. Tenstorrent's research-grade out-of-order RISC-V core with vector extension.
ttsim
officialFast full-system simulator of Tenstorrent Wormhole and Blackhole hardware. Runs TT-Metalium workloads on any Linux/x86_64 system without physical silicon. Bit-exact results relative to hardware.
tt-isa-documentation
officialLow-level ISA and microarchitecture documentation for Tenstorrent AI architectures (Grayskull, Wormhole, Blackhole) — the authoritative hardware reference beneath the tt-forge / tt-metal software stack.
riscv_arch_tests
officialRISC-V architectural self-checking directed tests — randomly-generated register operands and data with low-level OS code for test scheduling and self-checking, runnable on a RISC-V design or an ISS such as Whisper or Spike. Generated by an internal Tenstorrent tool from the official RISC-V ISA spec.
RISC-V Instruction Set Simulator (ISS) used by Tenstorrent for processor verification. Powers the co-simulation architecture checker.
tt-xla
officialPJRT device plugin for Tenstorrent hardware. Enables JAX, PyTorch/XLA, and other XLA-based frameworks to target TT accelerators.
5 previous releases
tt-kmd
officialTenstorrent kernel module driver. The Linux kernel module required to interface with Tenstorrent PCIe accelerator cards.
4 previous releases
tt-inference-server
officialProduction-ready model serving for Tenstorrent hardware with OpenAI-compatible REST API. Supports continuous batching, multiple models, and all TT hardware configurations.
RiESCUE
officialRISC-V Directed Test Framework and Compliance Suite. Comprehensive test infrastructure for verifying RISC-V processor implementations against the specification.
tt-forge-onnx
official
ONNX graph compiler for Tenstorrent hardware. Optimizes and transforms ONNX model graphs for efficient execution on Tensix accelerators. Used as a backend by tt-forge for ONNX model ingestion.
5 previous releases
tt-smi
official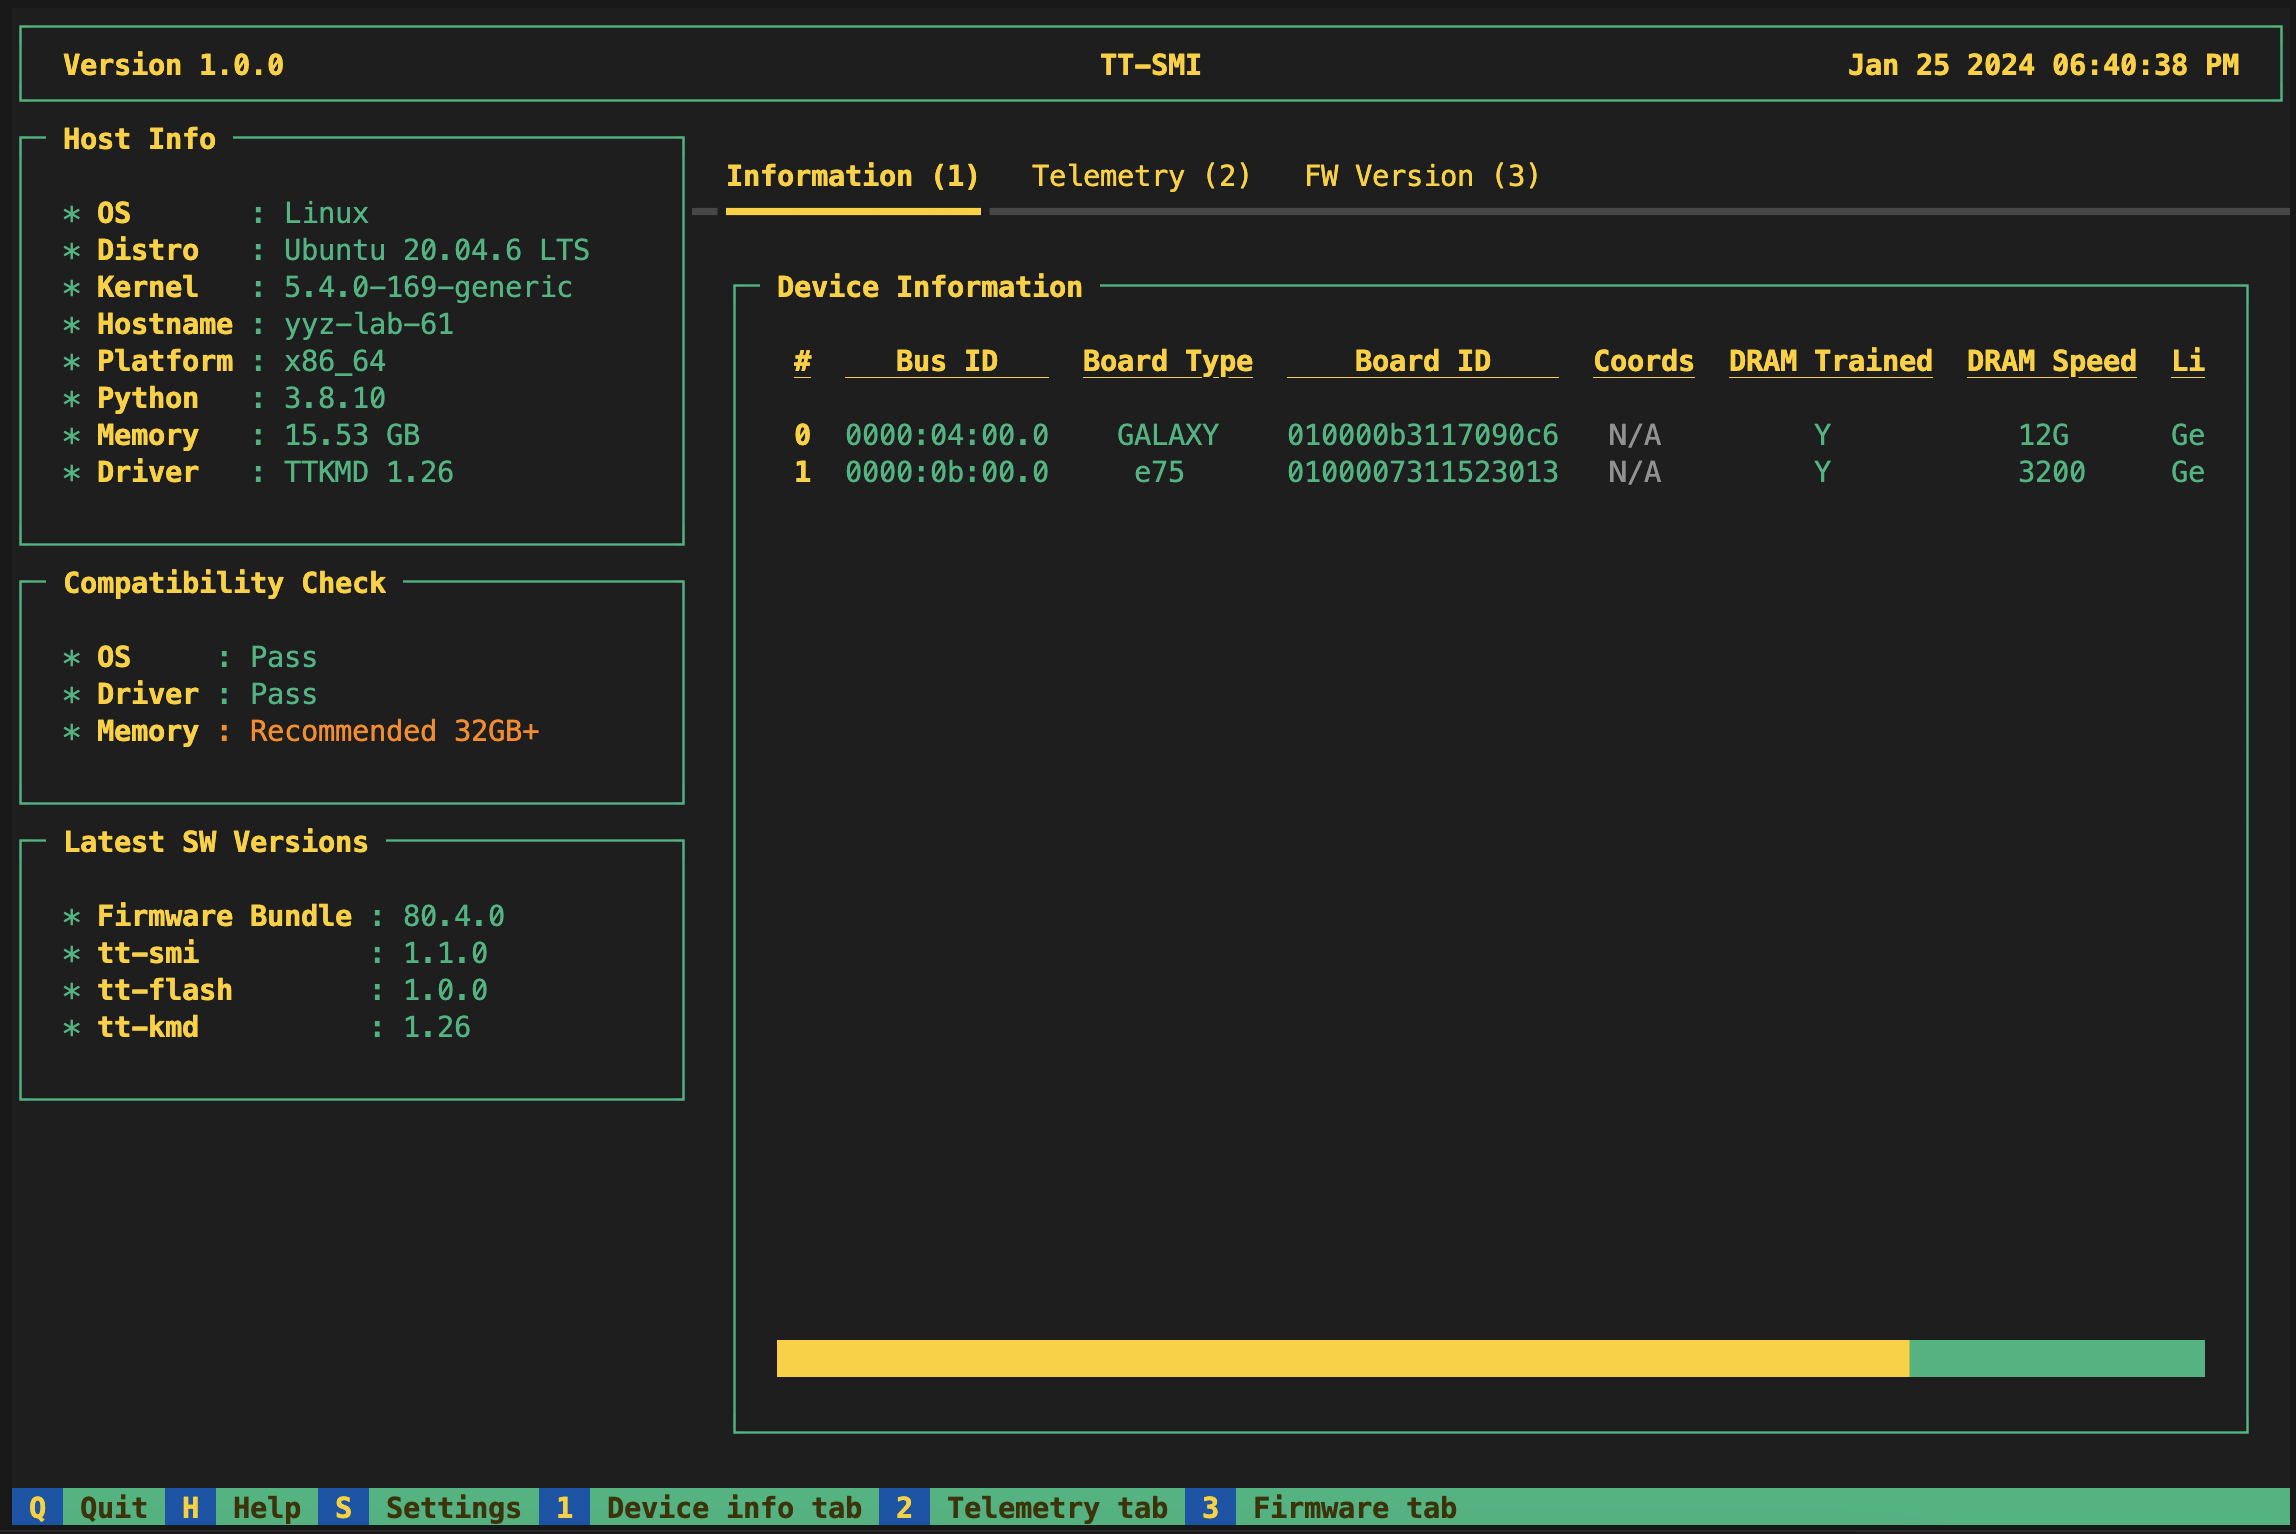
Tenstorrent System Management Interface — monitor device telemetry, issue board-level resets, and inspect hardware health. The nvidia-smi equivalent for Tenstorrent hardware.
📋 Changelog
# Changelog

All notable changes to this project will be documented in this file.

The format is based on [Keep a Changelog](https://keepachangelog.com/en/1.0.0/),
and this project adheres to [Semantic Versioning](https://semver.org/spec/v2.0.0.html).

## 3.0.26 - 29/07/25
- Added single tray galaxy reset option
- Bumped luwen from 0.7.5 -> 0.7.10
  - Chip detect now doesn't wait for eth to train for the 6U galaxy's, allowing multi tray resets to happen independently
- Updated readme with the new reset option

## 3.0.25 - 29/07/25
- Added packaging

## 3.0.24 - 04/07/25
- Now users have 2 galay reset modes available
  - glx_reset: resets the galaxy, informs users if there has been an eth failure
  - glx_reset_auto: resets the galaxy upto 3 times if eth failures are detected

## 3.0.23 - 03/07/25
- Bumped luwen 0.7.3 -> 0.7.5 to fix cargo lock compatibilty issue

## 3.0.22 - 02/07/25
- Bumped tt-tools-common 1.4.16 -> 1.4.17
- Bumped luwen 0.7.2 -> 0.7.3
- Bumped smi 3.0.21 -> 3.0.22

## 3.0.21 - 26/06/25

- Added option to not re-init chips after reset
- Updated galaxy 6u reset option from --ubb_reset to -glx_reset
- Removed the a3 arc message before doing a 6u reset, meaning we can reset even when chips are not pcie accessible
- Added eth link check and return failure if any of the eth links have a LINK_INACTIVE_FAIL_DUMMY_PACKET failure

## 3.0.20 - 04/06/25

- Chore - bumped tt-tools-common version to fix driver version check for compatability with tt-kmd 2.0.0

## 3.0.19 - 30/04/25

- Fixed an issue preventing the telemetry thread from being dispatched when the user clicked tab 2

## 3.0.18 - 22/05/25

- Added BH and WH UBB board type support
- Removed the dependency on tt-tools-common for this info

## 3.0.17 - 13/05/25

- Added proper telemetry heartbeat checks for Grayskull

## 3.0.16 - 12/05/25

- Used new ResetTypes from tools-common to simplify reset code
- Added a heartbeat spinner to the telemetry pane. We expect this spinner to update about twice per second. If the spinner is not moving, this indicates new telemetry is not being fetched.

## 3.0.15 - 24/04/25

- Patch for the ubb_reset to just discover local only post reset. Looks like eth port status 2 has been re-used to mean connected and pyluwen waits for it to clear, leading to eth timeout.

## 3.0.14 - 21/04/25

- Added wh ubb reset via command line `tt-smi --ubb_reset`. Intention is that this command line option will be removed and integrated into `tt-smi -r` after we update board detection with the correct external naming.
- Removed some unused imports and code - no functional changes

## 3.0.13 - 21/03/25

- Removed get\_sw\_versions

## 3.0.12 - 21/03/25

- Chore - bumped luwen version to include eth fw version check fix

## 3.0.11 - 13/03/25

- Chore - bumped luwen version to include enable chips with external connections but no routing

## 3.0.10 - 10/03/25

- Chore - bumped luwen version to include protoc lib detection check

## 3.0.9 - 07/03/25

- Chore - bumped luwen v
tt-buda-demos
officialRepository of model demos using TT-Buda. The largest collection of pre-compiled model examples for Tenstorrent hardware — BERT, ResNet, YOLO, GPT-2, Whisper, and many more.
tt-lang
official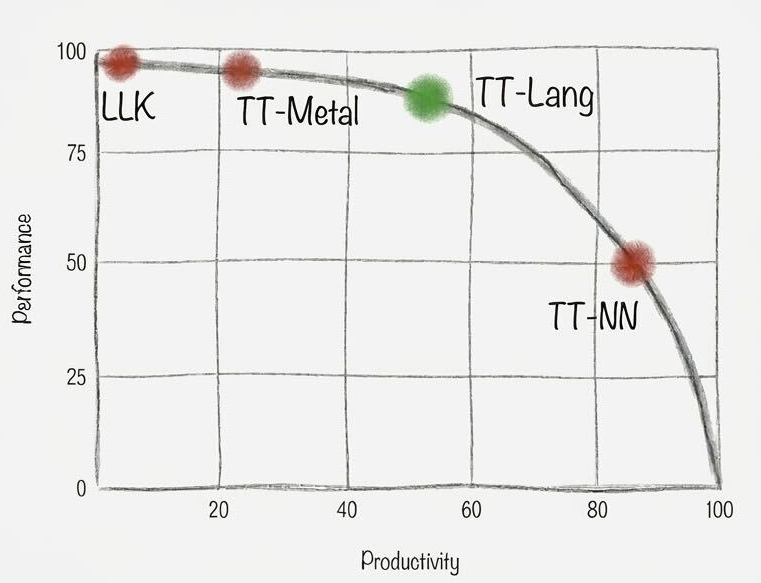
Python-based DSL that sits between TT-NN and TT-Metalium — expresses custom fused kernels with progressive disclosure, compiling directly to Tensix. Ships an integrated functional simulator (no hardware needed), line-by-line performance metrics, and AI-agent-friendly tooling. Two packages: tt-lang (compiler + hardware, requires ttnn) and tt-lang-sim (simulator only, works on Linux/macOS without Tenstorrent hardware).
📋 Changelog
# Changelog

All notable changes to TT-Lang will be documented in this file.

The format is based on [Keep a Changelog](https://keepachangelog.com/en/1.0.0/),
and this project adheres to [Semantic Versioning](https://semver.org/spec/v2.0.0.html).

## Version 1.1.1

### Compiler

- Fix for live-interval boundary computation (issue [#536](../../issues/536))
- Fix for all-zero results in FP32 reductions (issue # [#533](../../issues/533))
- Fix for inferred `pop` and `push` (issues [#536](../../issues/536), [#554](../../issues/554))
- Fix for write pointer tracking on pipe sender accross iterations (issue [#578](../../issues/578))
- Fix to report data type mismatch error
- Fix to report DFB over allocation error (issue [#511](../../issues/511))
- Support for pipenet predicates `is_src`, `is_dst` and `is_active` (issue [#541](../../issues/541))
- Support for `ttl.math.typecast`

### Simulator

- Support for inferred `pop`, `push` and `copy`'s transfer handle `wait`
- Support for pipenet predicates `is_src`, `is_dst` and `is_active`
- Support `all_gather`
- Support `bfloat8_b`
- Improved/actionable error messages
- Improved performance by simulating math in FP32

### Infrastructure

- TT-Lang installable with `pip install tt-lang` for full installation and `pip install tt-lang-sim` for simulator only
- [Matmul benchmarks](benchmarks/matmul/README.md)

## Version 1.0.0

### Compiler

- Support `+=` syntax in conjunction with dot product (`@`) lowered to packer L1 accumulation
- Support implicit temporary compute-kernel-local DFBs
- Support `ttl.Pipenet`
- Support implicit `ttl.Block.push` and `ttl.Block.pop`
- Support implicit `ttl.Transfer.wait`
- Support for `expm1`, `exp2`, `ceil`, `sign`, `gelu`, `silu`, `hardsigmoid`, `square`, `softsign`, `signbit`, `frac`, `trunc` in `ttl.math`

### Simulator

- Support for `ttl.GroupTransfer`
- SPMD and mesh device simulation support
- Support for `ttnn.all_reduce` CCLs
- Use tracing to report statistics with `tt-lang-sim-stats`
- Remote L1 reads/writes statistics

### Examples and documentation
- Matmul tutorial

## Version 0.1.8

### Compiler

- Support for dot product operator (`@`) with lowering to [`ckernel::matmul_block`](https://docs.tenstorrent.com/tt-metal/v0.55.0/tt-metalium/tt_metal/apis/kernel_apis/compute/matmul_block.html)
- Support for fusing matmul and certain elementwise operations
- Support lowering to `pack_tile_block`
- Support for `ttl.math.fill`, `ttl.math.reduce_sum`, `ttl.math.reduce_max`, and `ttl.math.transpose`
- Support for arbitrary sub-blocking including dot product K-dimension to allow maximizing L1 usage and reuse
- Support for `sin`, `cos`, `tan`, `asin`, `acos`, `atan` in `ttl.math`
- Support for L1 sharded tensors
- Support for tensors with BF8 data type
- SPMD support (`ttnn.open_mesh_device`)

### Simulator

- Track L1 space and number of DFBs usage and warn when exceeded
- Support for tensors with row-major layout
- Support for L1 sharded tensors

### Examples and documentat
tt-bh-linux
official★ featured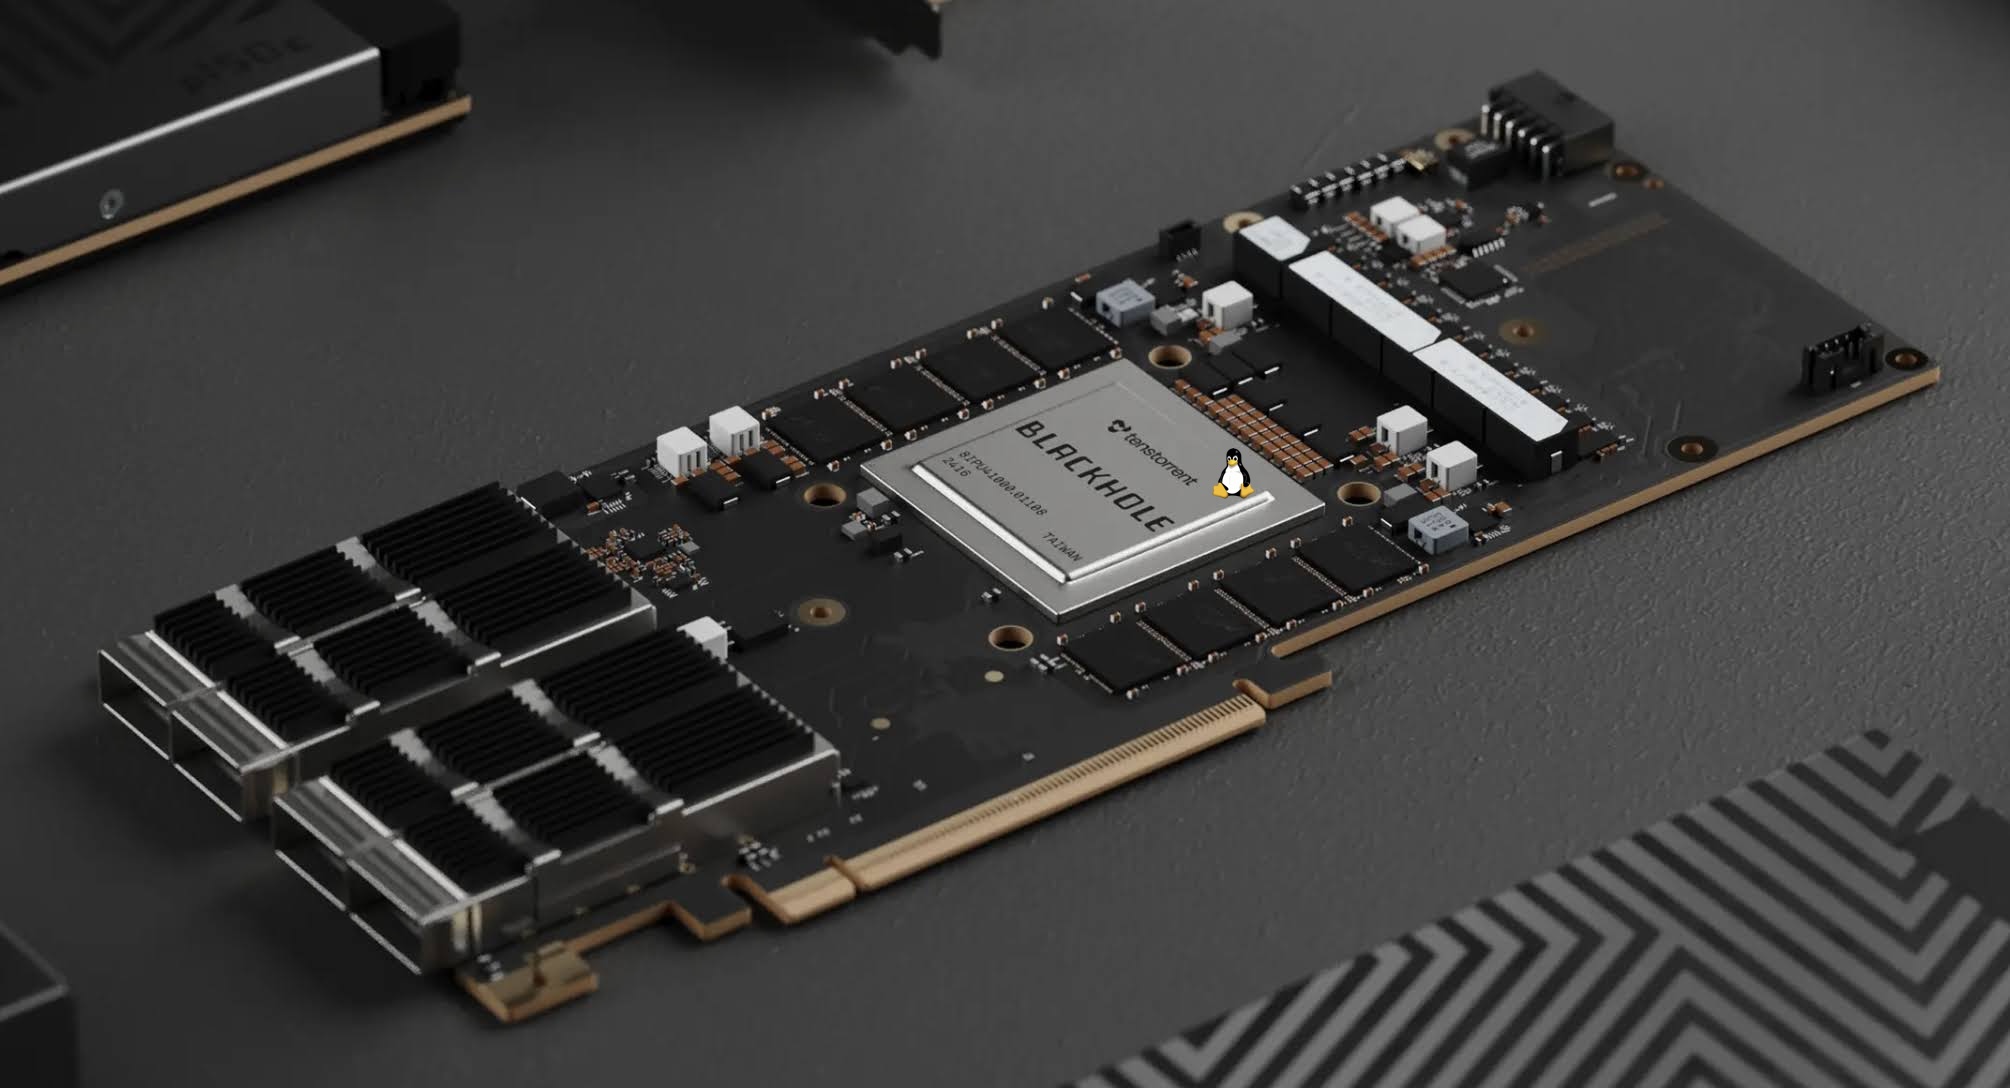
Linux demo for the Tenstorrent Blackhole P100/P150 card RISC-V cores. Boot a real Linux kernel on the 16 high-performance RISC-V cores built into the Blackhole chip.
ttnn-visualizer
official
Comprehensive tool for visualizing and analyzing model execution on Tenstorrent hardware. Interactive graphs, memory plots, tensor details, buffer overviews, operation flow graphs, and multi-instance support.
tt-llk
officialTenstorrent Low-Level Kernels: the C++ library that directly programs the RISC-V cores inside each Tensix compute engine. TRISC0 (unpack), TRISC1 (math/FPU/SFPU), and TRISC2 (pack) are all programmed through this layer — it is the interface between TT-Metal kernel code and bare silicon.
WallaBMC
official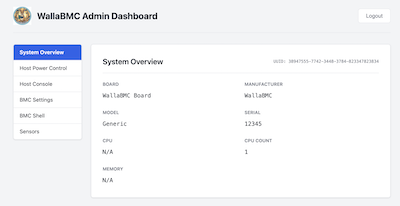
Lightweight BMC (Baseboard Management Controller) for STM32 and similar MCUs, with Web UI, Redfish API, and HTTPS support. Built on Zephyr RTOS. Used in Tenstorrent systems.
TT-Studio
officialWeb-based GUI for deploying and chatting with AI models on Tenstorrent hardware. Handles all technical setup automatically — deploy models, run inference, and explore capabilities through a simple browser interface.
tt-umd
officialUser-mode driver for Tenstorrent hardware. The userspace layer that sits between the kernel module and higher-level SDKs.
4 previous releases
📋 Changelog
# Changelog

## [0.9.5] - 2026-05-12

### Changed

Hardware hang detection for NOC and PCIe.
Tracy profiler integration with instrumentation across TLB, PCIe and sysmem paths.
DeviceProtocol ported to TTDevice, including DMA migration.
SocDescriptor split into static (SocArchDescriptor) and runtime parts.
LITERAL coordinate system in CoreCoord.
Multicast to all TENSIX cores.
SMN support.
SWEmuleChip software emulation chip and Quasar simulation support (incl. 4GB TLB).
Unified UmdException/UMD_ASSERT/UMD_THROW error handling across the codebase.

## [0.9.4] - 2026-03-18

### Changed

TopologyDiscoveryOptions refactoring.
TopologyDiscoveryOption to retrain ETH links on 6u.
TLBs for TTsim.
DRAM retrain support.
DeviceProtocol changes.
Simulator in TTDevice changes.
ETH heartbeat check.

## [0.9.3] - 2026-02-24

### Changed

Sigbus safe read write API.
Remove 4U related code.
Implement BH SPI as well, so full SPI support.
P150 expects harvested cores.
TT_VISIBLE_DEVICES uses logical IDs.

## [0.9.2] - 2026-02-09

### Changed

SPI interface for Wormhole.
PCI BDF based sorting and filtering.
Multicast PCI DMA.
Support Blackhole loudbox.
Many code fixes and test enhancements.

## [0.9.1] - 2026-01-23

### Changed

Started publishing to pypi.

## [0.9.0] - 2026-01-23

### Changed

Warm reset notification and callback implementation.

## [0.8.6] - 2026-01-20

### Changed

Make predicting ETH FW from CMFW optional in TopologyDiscovery.

## [0.8.4] - 2026-01-16

### Changed

Use older manylinux image

## [0.8.3] - 2026-01-15

### Changed

Reverted remote discovery issue

## [0.8.2] - 2026-01-15

### Changed

Support warm reset without secondary bus reset.
Expose subsystem vendor id.

## [0.8.1] - 2026-01-15

### Changed

Support dma functions on TTDevice layer

## [0.8.0] - 2026-01-14

### Changed

Many functional fixes and minor changes.
Final fixes needed for integration into tt-smi.
Also contains adjustments needed for integration into exalens.

## [0.7.0] - 2025-11-29

### Changed

Changed to a more generic arc_msg API.

## [0.6.0] - 2025-11-24

### Changed

Change the usage of TLBs such that KMD is in control of TLB allocation instead of UMD.
TLBs are now allocated using KMD's dedicated API.

## [0.5.3] - 2025-11-14

### Changed

Added generation of .deb and .rpm packages.
Added three separate packages (runtime, development and python).

## [0.5.1] - 2025-11-12

### Changed

Manylinux builds and Pypi test publishing.
Many smaller fixes and improvements.

## [0.4.0] - 2025-10-18

### Changed

Removed old type names.

## [0.3.0] - 2025-10-17

### Changed

Many smaller fixes and improvements.
TTsim support improvements.
JTAG support improvement.
Fixing CMake install path.
Further work on integrating new KMD TLBs.

## [0.2.0] - 2025-09-15

### Changed

A couple of smaller fixes and improvements, including L2CPU harvesting, fixes for new FW. Better TTSim support. Further JTAG support.
Introduced new soft reset API.
Introduced lite fabric initial version.
tt-system-firmware
official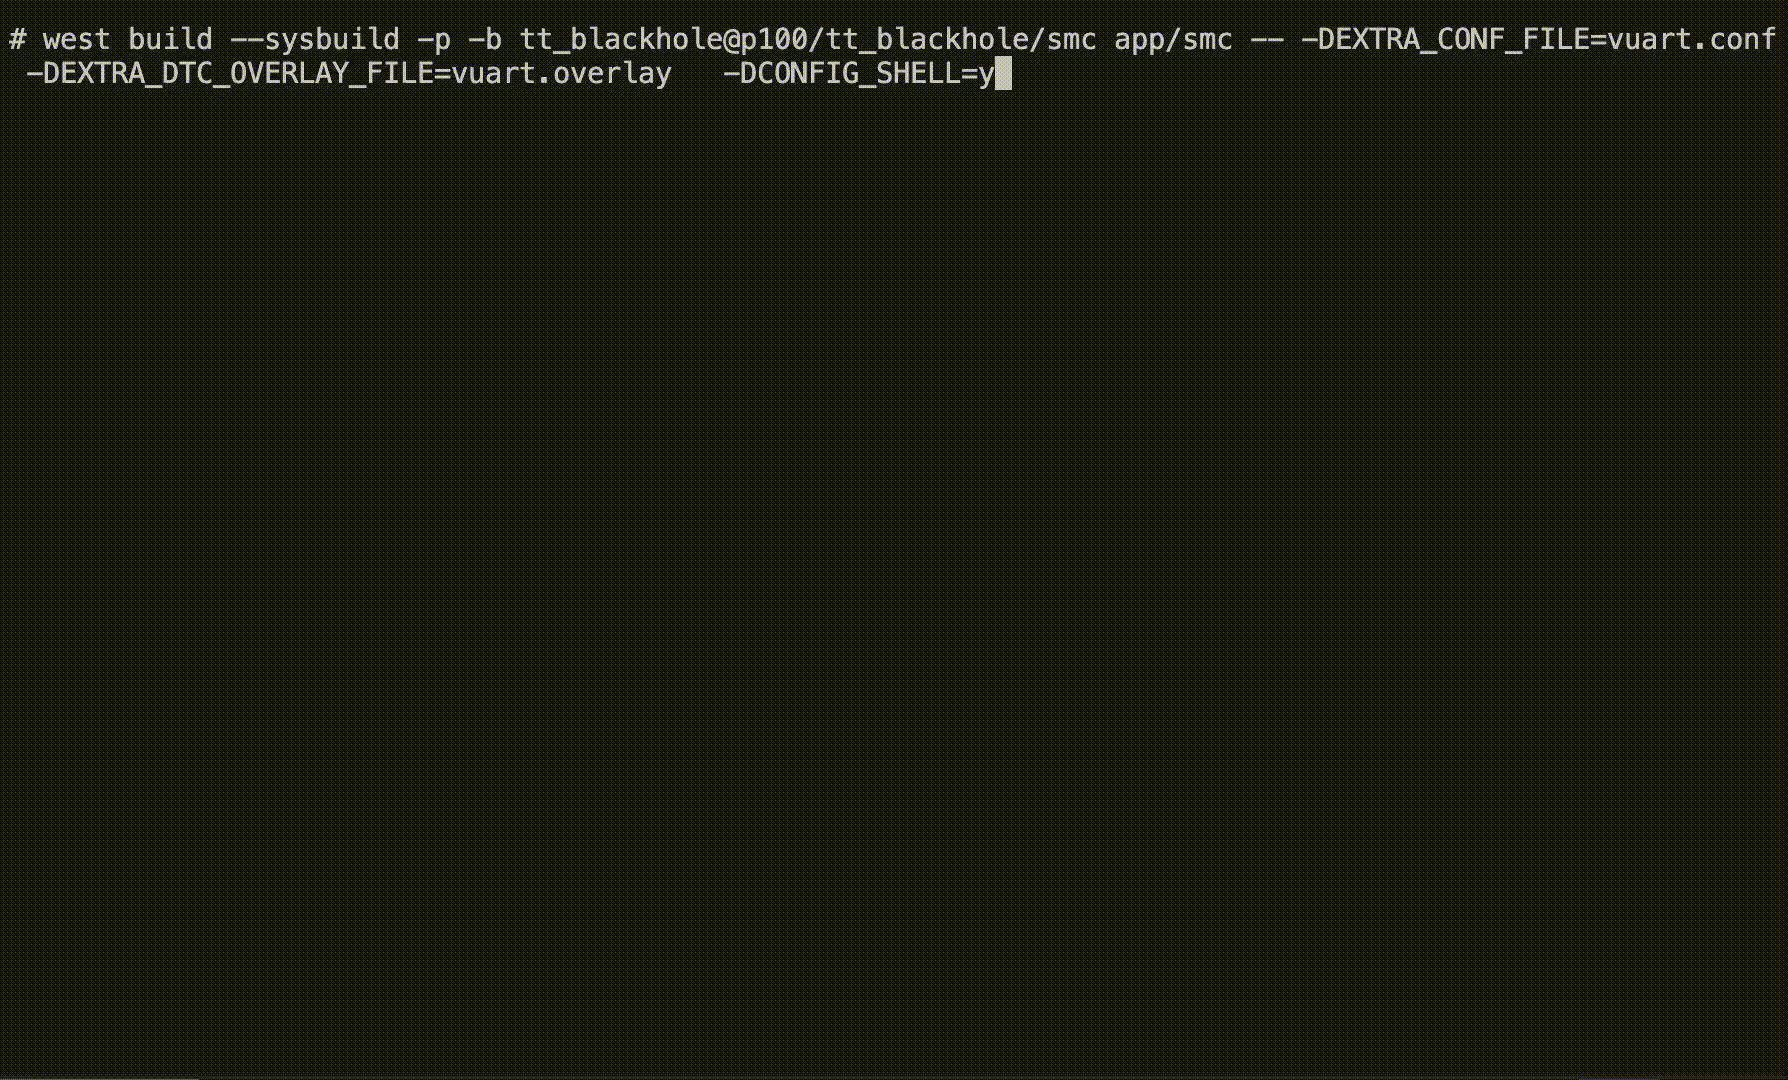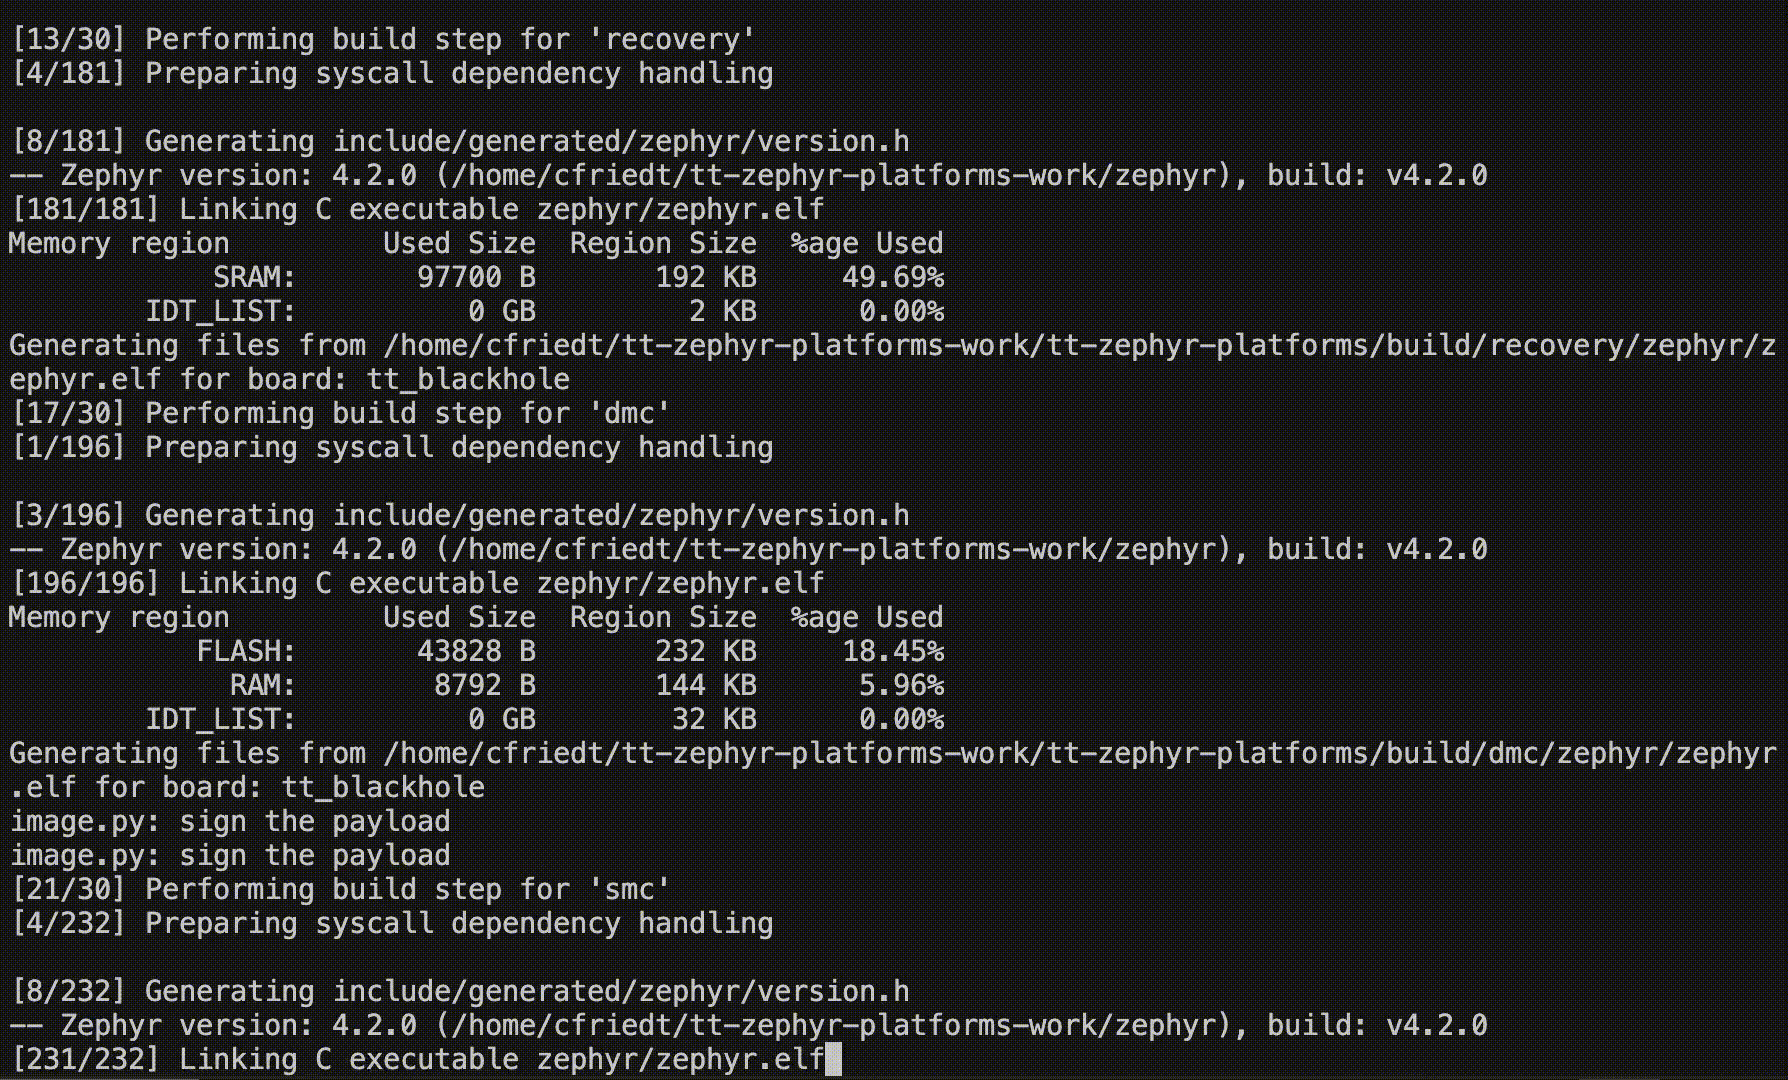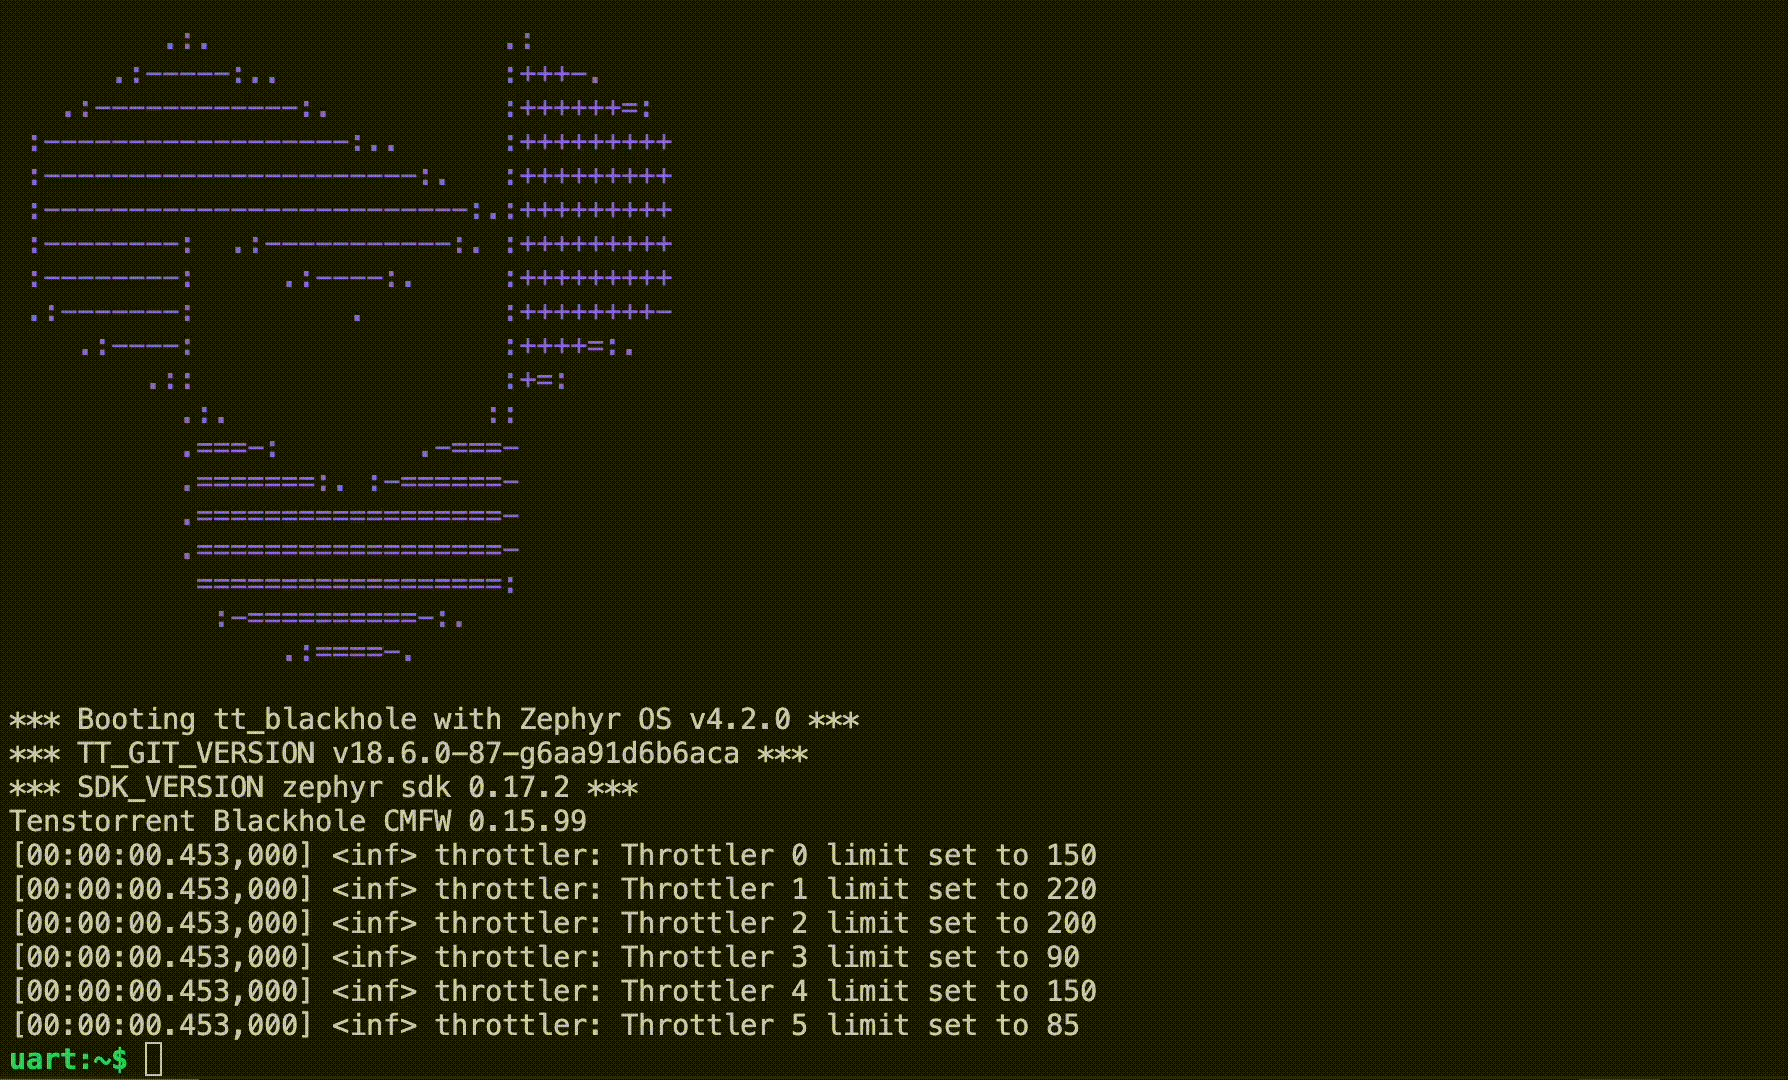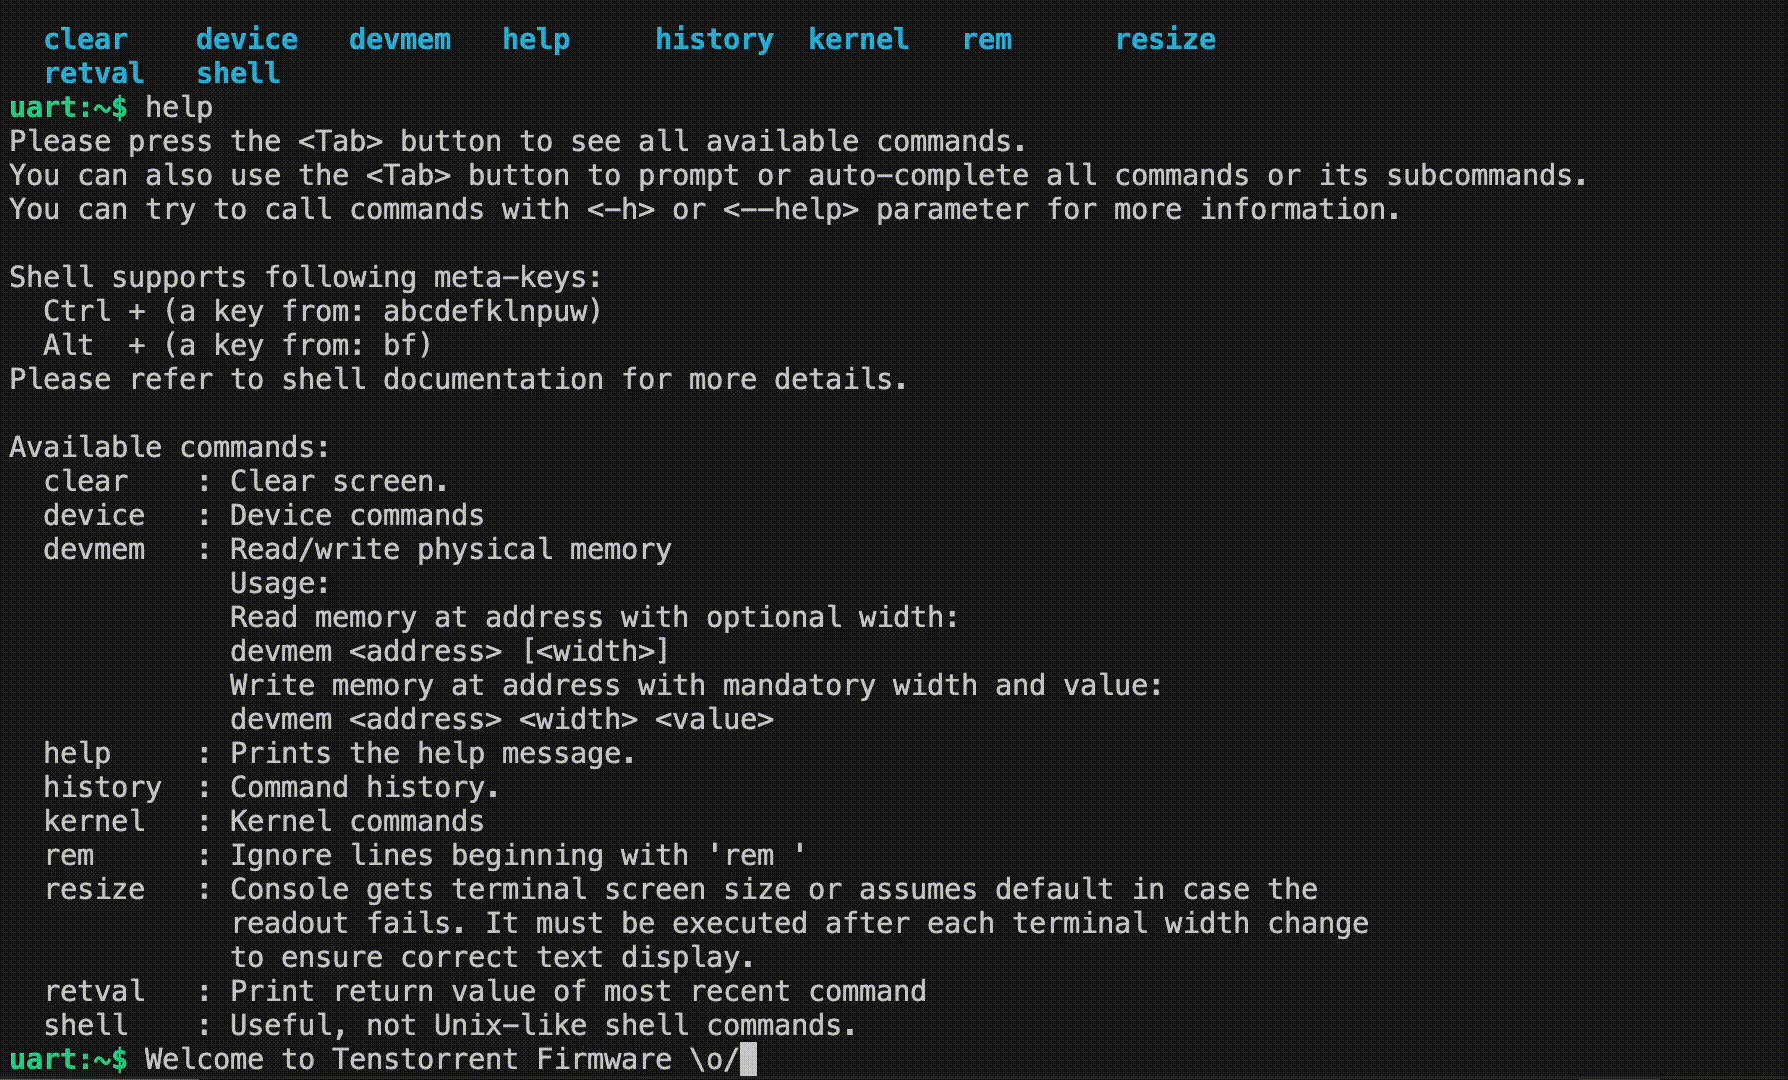
System firmware for Tenstorrent hardware. Low-level system initialization and control firmware that runs on-device.
polaris
officialA high-level AI simulator from Tenstorrent for modeling and exploring AI accelerator and workload performance.
luwen
officialTenstorrent system interface library written in Rust. Low-level Rust bindings for communicating with and managing TT hardware.
4 previous releases
tt-tvm
officialTVM for Tenstorrent ASICs. Brings the Apache TVM compiler stack to Tenstorrent hardware, enabling model compilation from TensorFlow, PyTorch, ONNX, and more.
tensix-isa-simulator
officialISA-level simulator for the Tensix compute engine. Simulates the matrix, vector, and scalar units inside each Tensix core.
tt-torch
officialFrontend integration for PyTorch with tt-mlir. Compile PyTorch models directly to Tenstorrent hardware via torch.compile integration.
tt-firmware
officialTenstorrent firmware repository. Board management and control firmware for Tenstorrent accelerator cards.
tt-installer
officialInstall the complete Tenstorrent software stack with one command. Handles drivers, firmware, Python environment, and SDK setup automatically.
tt-exalens
officialLow-level hardware debugger for Tenstorrent devices. Inspect register state, memory contents, and kernel execution at the hardware level.
4 previous releases
tt-blacksmith
officialOptimized training recipes for a variety of ML models on Tenstorrent hardware, powered by the TT-Forge compiler stack. Reference implementations for fine-tuning and training from scratch.
tt-npe
official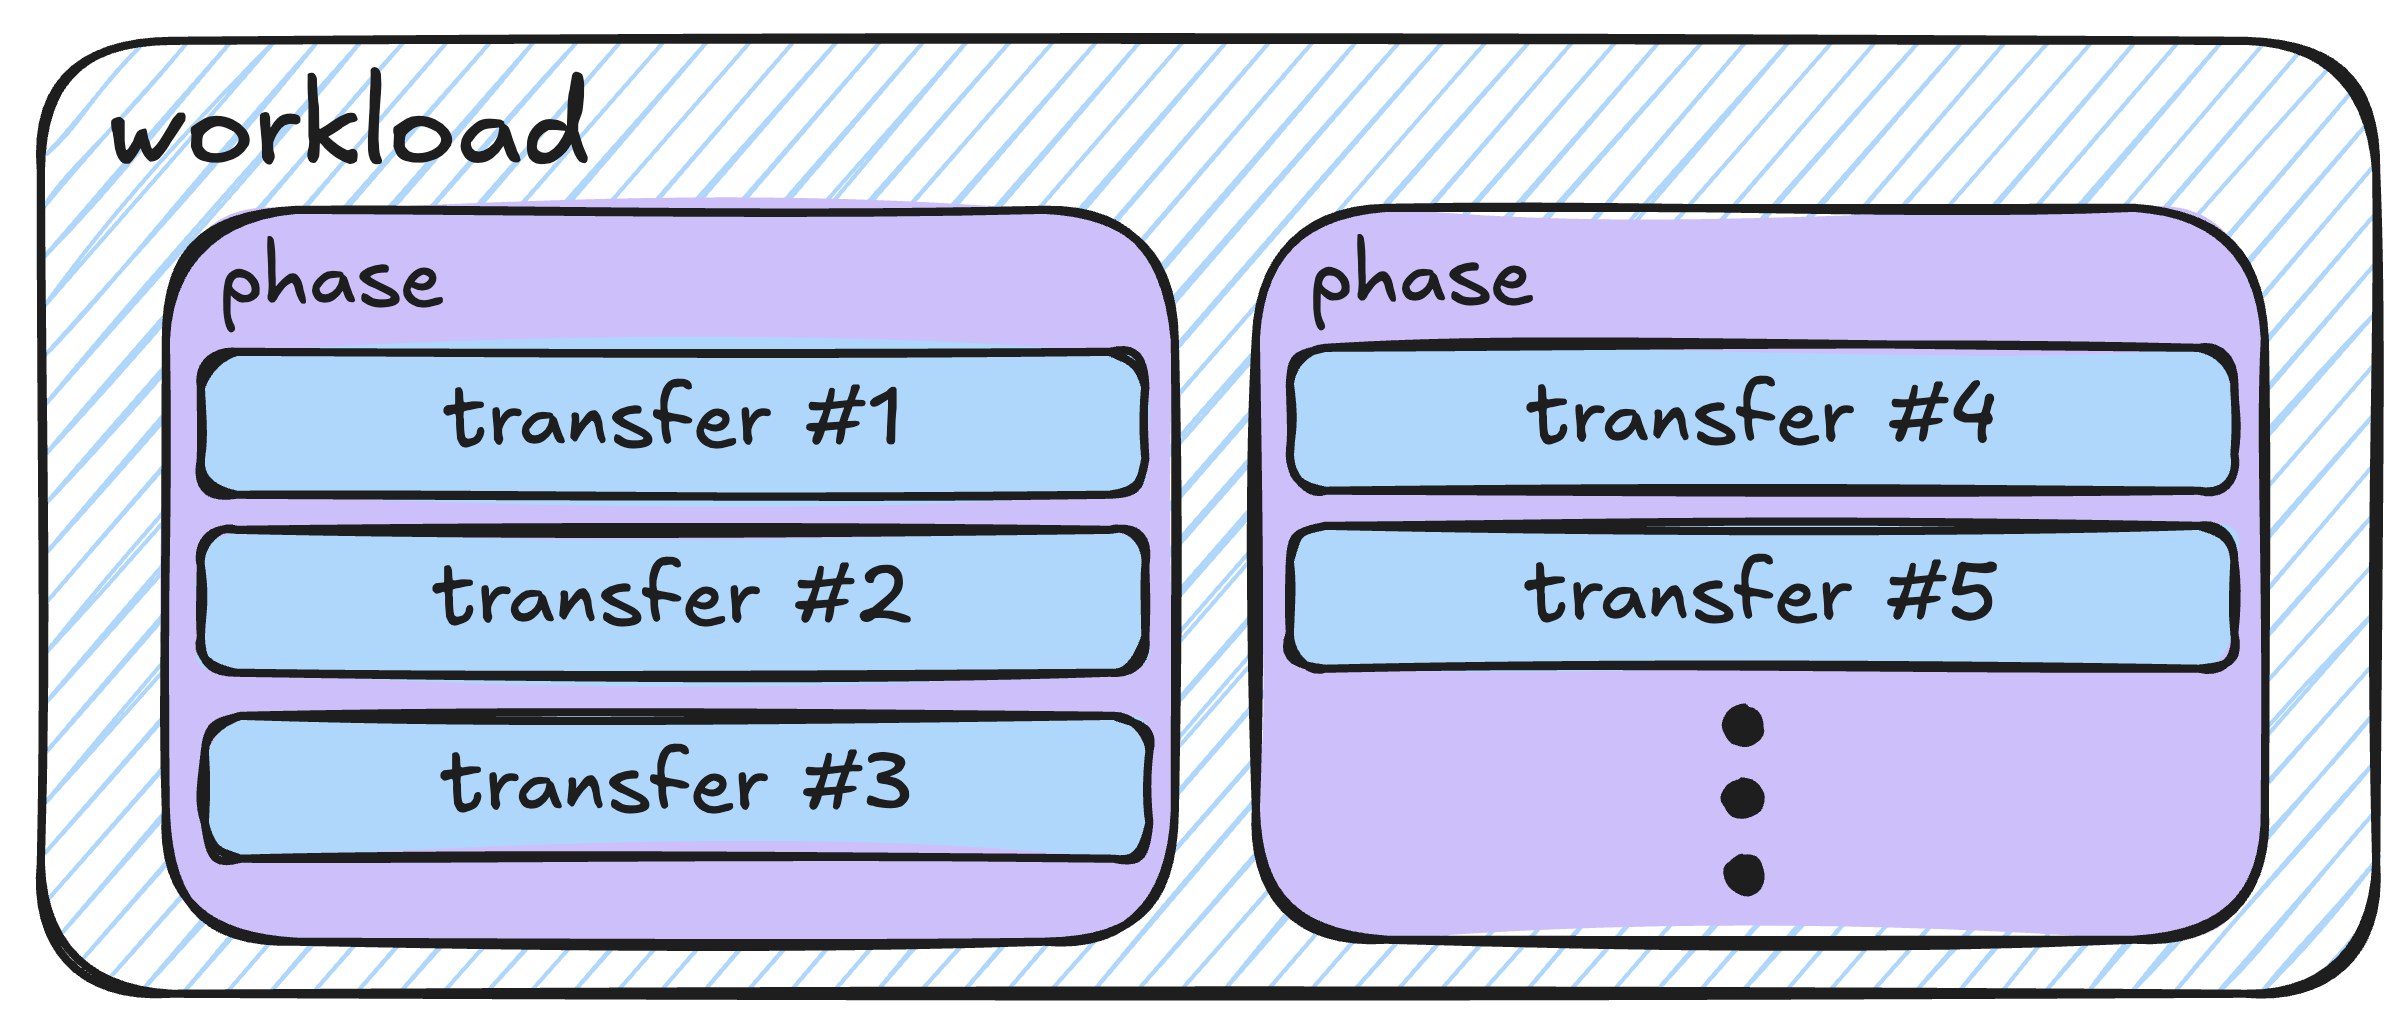
Network-on-chip Performance Estimator for Tenstorrent Tensix-based devices. Model and estimate NoC utilization before running kernels on hardware.
tt-topology
official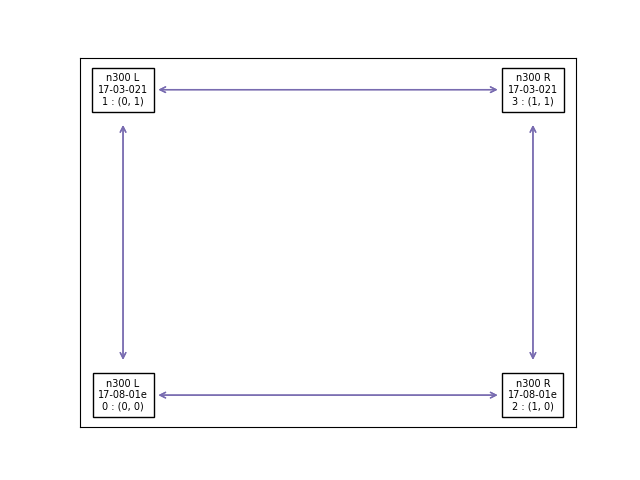
Configure Ethernet routing on multi-card Tenstorrent systems. Flash NB cards to use specific ETH routing configurations for scale-out deployments.
4 previous releases
📋 Changelog
# Changelog

All notable changes to this project will be documented in this file.

The format is based on [Keep a Changelog](https://keepachangelog.com/en/1.0.0/),
and this project adheres to [Semantic Versioning](https://semver.org/spec/v2.0.0.html).

## 1.2.11 - 17/06/2025

### Updated

- Updated mesh coord generation to be connection type agnostic
- Added failure and exit if mesh type detected, but not enough connections
- Added warning in README about lack of supoort for BH and 6U boards

## 1.2.10 - 05/06/2025

### Updated

- Bumped tt-tools-common version to fix driver version check for compatability with tt-kmd 2.0.0

## 1.2.9 - 30/05/2025

### Updated

- Bug fix for https://github.com/tenstorrent/tt-topology/issues/39. Now the tool will use a DFS longest path to determine a linear layout if its not a fully connected graph.
- Updated initial device detection - now it needs full noc access for octopus and list options

## 1.2.8 - 08/05/2025

### Updated

- Fixed issue where tool would fail when PCI interfaces don't start from ID 0
- Now using actual PCI interface IDs from devices instead of assuming sequential numbering

## 1.2.7 - 07/05/2025

### Updated

- Use tools-common 1.4.15
- Use type checking in octopus reset

## 1.2.6 - 05/05/2025

### Updated

- Bug fix: added "ignore-eth" flag to first chip detect to avoid eth training loops forever and truly detect pcie only chips
- Chore: bumped luwen

## 1.2.5 - 15/04/2025

### Updated

- When flashing to isolated mode, we now flash the WH ethernet ports to a disabled state,
  in order to prevent their use.

## 1.2.4 - 02/04/2025

### Updated

- You can now run `tt-topology -l isolated` to flash cards to the default (non-connected) state
- Users are now warned about missing or loose cables

## 1.2.3 - 21/03/2025

### Fixed

- Bumped luwen (0.6.2 -> 0.6.3) to include eth version check bug for TG setup

## 1.2.2 - 13/03/2025

### Fixed

- Bumped luwen version to make it more robust against eth fw updates

## 1.2.1 - 13/03/2025

### Fixed

- Moved the spi reads after the reset to increase stability during M3 L2R copy
- Bumped luwen version

## 1.2.0 - 06/03/2025

### Fixed

- Updated how local eth board info is calculated to make it agnostic to eth fw version
- bumped tt-tools-common version
- Added traceback printing when catching exceptions in main.

## 1.1.5 - 14/05/2024

### Updated

- Bumped luwen (0.3.8) and tt_tools_common (1.4.3) lib versions
- Removed unused python libraries

## 1.1.4 - 25/03/2024

### Fixed
- Changed detect_chips with detect_chips_with_callback to enable detailed debug info.

## 1.1.3 - 22/03/2024

### Fixed
- Bumped tt-tools-common version to avoid pip discrepancy.

## 1.1.2 - 22/03/2024

### Fixed
- Fixed command line bug when no args are provided.

## 1.1.1 - 21/03/2024

### Fixed
- Fixed reference to pyluwen lib

## 1.1.0 - 12/03/2024

### Added
- Octopus Configuration (4 n150s connected to 1 galaxy)


## 1.0.2 - 12/03/2024

### Fixed
- Dependency bug with tt_tools
SFPI
officialTenstorrent SFPU programming interface — TT-enhanced RISC-V GCC and binutils plus header files for programming the Tensix SFPU (vector engine) from kernel code. The compiler toolchain underneath TT-Metalium's SFPU ops.
4 previous releases
tt-forge-models
officialA shared repository of model implementations used across TT-Forge frontends — a single source of truth for the models used in testing and benchmarking, rather than duplicating them across frontend repos.
tt-flash
officialTenstorrent firmware update utility. Flash new firmware onto Tenstorrent accelerator cards from the command line.
4 previous releases
📋 Changelog
# Changelog

All notable changes to this project will be documented in this file.

The format is based on [Keep a Changelog](https://keepachangelog.com/en/1.0.0/),
and this project adheres to [Semantic Versioning](https://semver.org/spec/v2.0.0.html).

## Unreleased

### Added

- `flash`: `--update-boot-images` writes the bundle's bootloader and recovery
  images even when the board already holds the same ones, for provisioning and
  board recovery.

### Changed

- `flash`: the boot-critical images (`cmfw`, `safeimg`, `safetail`, `failover`)
  and the ROM and failover descriptor tables are now left alone when the board
  already holds the same content, so a routine update no longer opens a
  power-loss window on the path by which a board boots at all. Whether an image
  is the same is decided by the SHA-256 and key hash that `imgtool` records in
  it, because signing is not reproducible: two builds of the same source differ
  only in the trailing signature. Pass `--update-boot-images` for the previous
  behaviour of writing them unconditionally.

### Fixed

- `flash`: a P300 chip running recovery firmware publishes no board id, so the
  pairing check filed it as not a P300, left its sibling alone in a group of
  one, and dropped both halves of the card from the flash list -- refusing the
  board because of the chip that most needed flashing. Such a chip is now
  identified by its PCI subsystem id, which carries the same UPI whatever the
  chip is running.
- `boot_fs`: `tt_boot_fs_fd.image_tag_str()` compared each `c_uint8` tag byte
  against the string `"\0"`, which never matched, so NUL padding was included in
  the decoded tag. Tags shorter than 8 bytes (e.g. `cmfw`) now compare correctly.
  This makes `read_tag` robust across the multi-table boot filesystem layout
  (ROM, failover, and mutable descriptor tables).

## 3.4.0 - 30/07/25

- Bump pyyaml 6.0.1 -> 6.0.2
- Improve error message formatting
- No longer have to use --force for flashing BH cards

## 3.3.5 - 03/07/25

- Bump luwen 0.7.3 -> 0.7.5

## 3.3.4 - 02/07/25

- Bump tt-tools-common 1.4.16 -> 1.4.17
- Bump luwen 0.6.4 -> 0.7.3

## 3.3.3 - 05/06/2025

- Bumped tt-tools-common version to fix driver version check for compatability with tt-kmd 2.0.0

## 3.3.2 - 14/05/2025

- Bump tt-tools-common version to latest

## 3.2.0 - 12/03/2025

### Updated

- luwen version bump to bring inline with tt-smi; provides stability fixes

## 3.1.3 - 06/03/2025

### Added

- luwen version bump to include bh arc init checks

## 3.1.2 - 28/02/2025

### Added

- Support for more BH cards: p100a, p150, and p150c

## 3.1.1 - 06/01/2025

### Updated

- Bumped luwen version to accomodate Maturin updates

## 3.1.0 - 29/10/2024

### Added

- Support for flashing the BH tt-boot-fs file format
- Bumped luwen version to 0.4.6 to allow resets when chip is inaccessible

## 3.0.2 - 17/10/2024

### Fixed
- Unbound variable when exception is thrown when getting current fw-version

## 3.0.1 - 16/10/2024

### Changed
- B
tt-example-apps
officialEnd-to-end AI applications running on Tenstorrent AI accelerators. Complete application examples from retrieval-augmented generation to image generation pipelines.
tt-perf-report
official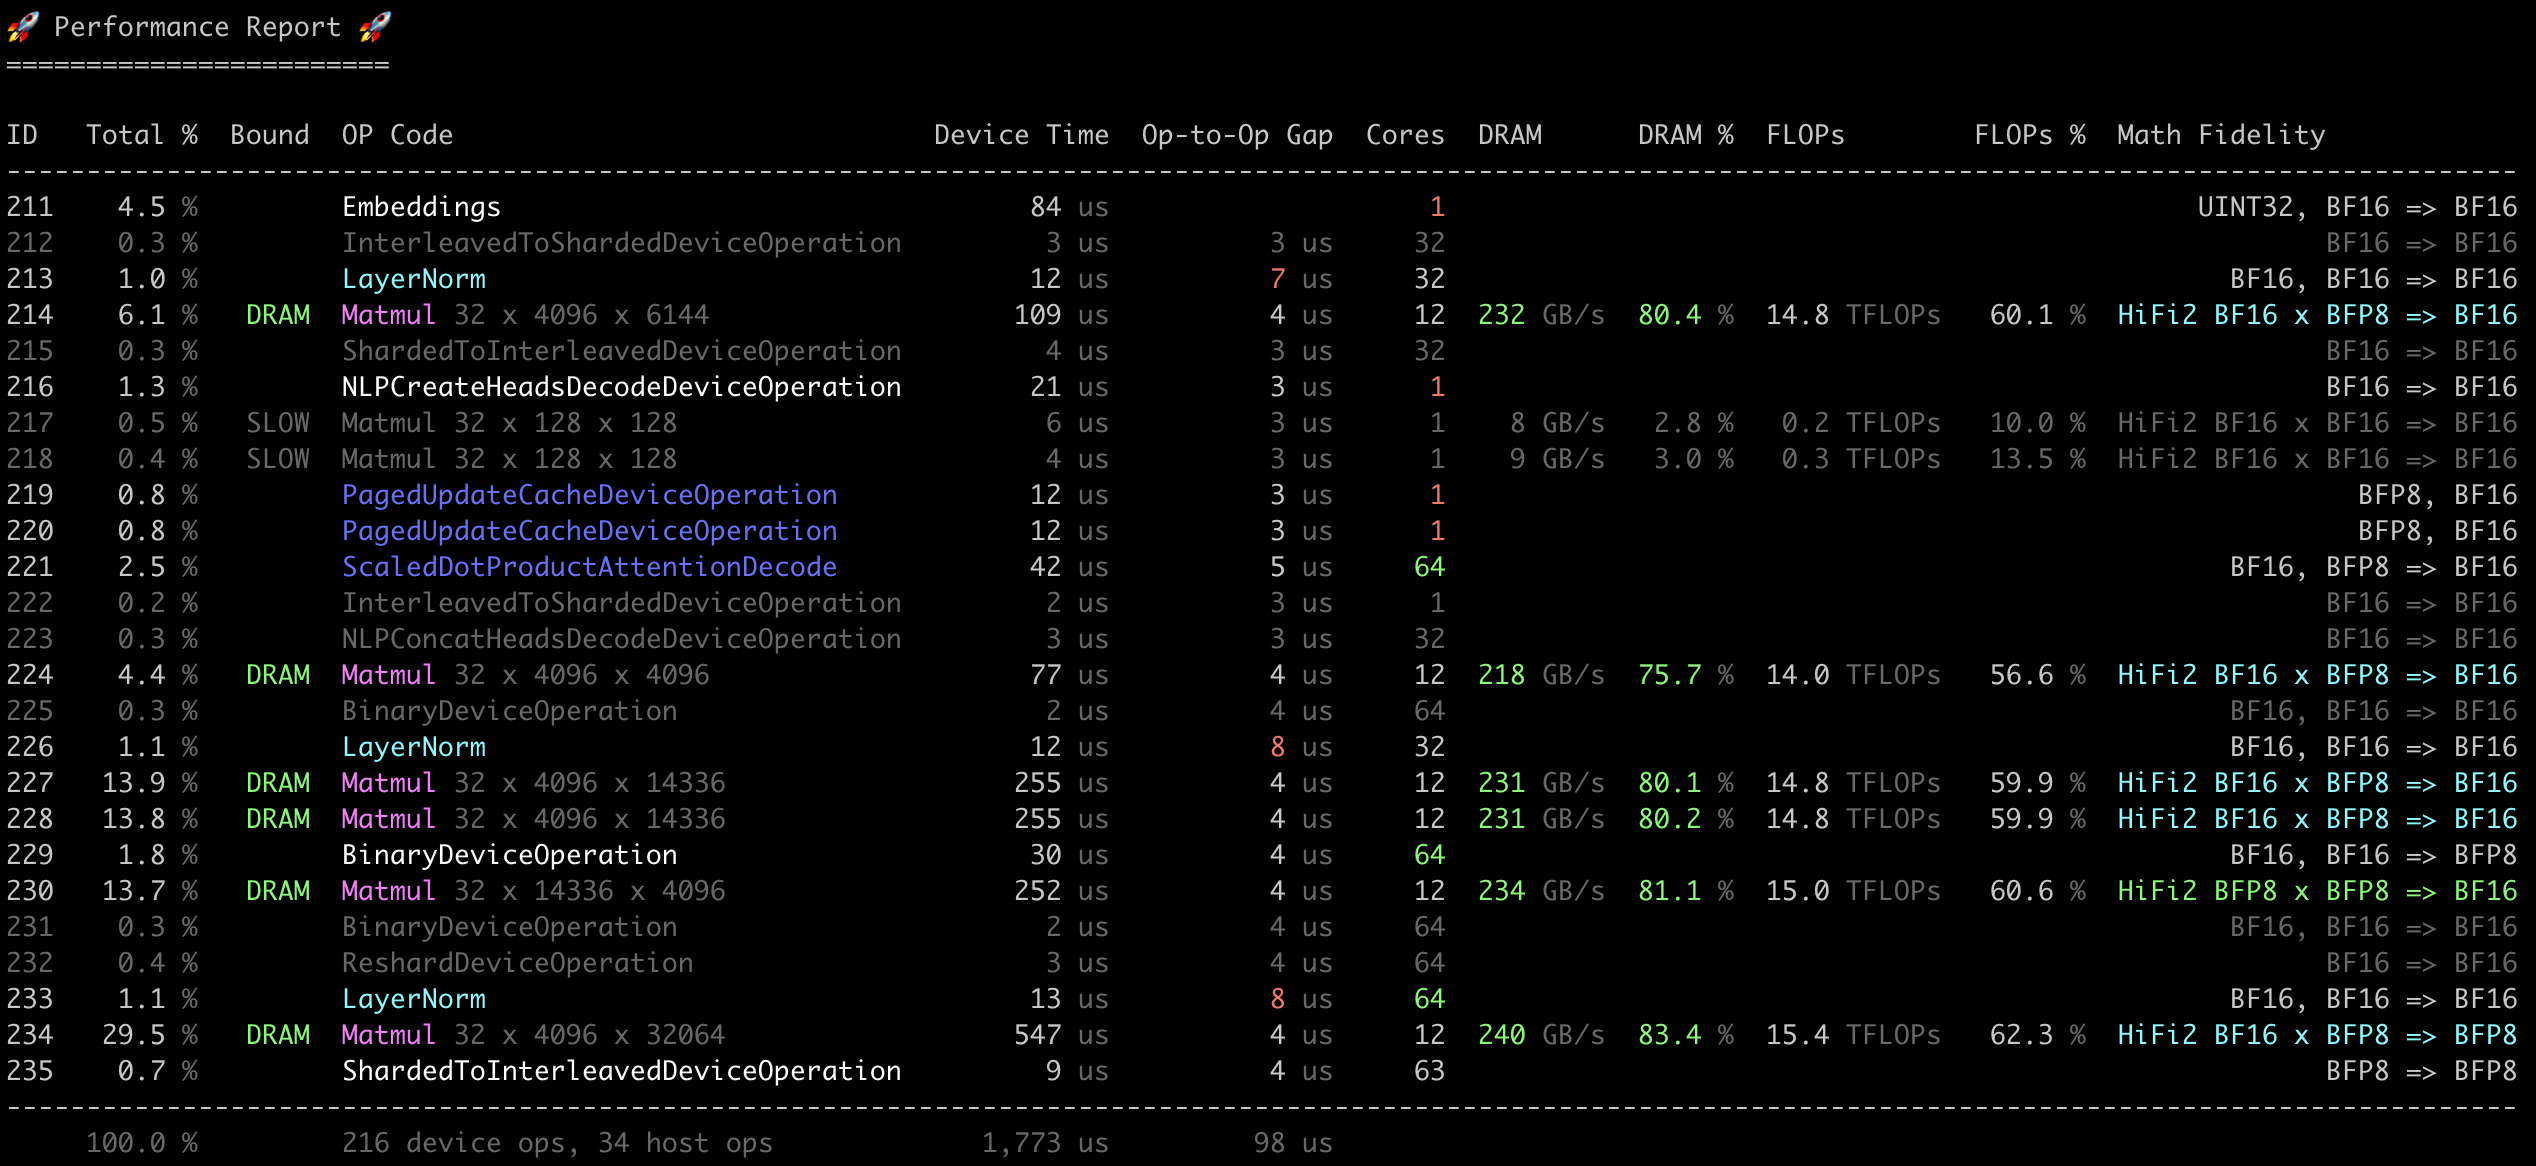
Performance report analysis tool for Tenstorrent Metal operations — analyzes perf traces to surface throughput, bottlenecks, and optimization opportunities.
vllm-tt-plugin
officialTenstorrent backend for vLLM, built on vLLM's standard plugin mechanism — install it alongside vLLM and TT hardware registers itself as a platform whenever `ttnn` is importable. Self-contained: model registration, platform detection, scheduling, worker execution, model loading, async decode, and data-parallel/multi-lane execution all live in the plugin, so nothing Tenstorrent-specific has to land in vLLM core.
tt-vscode-toolkit
official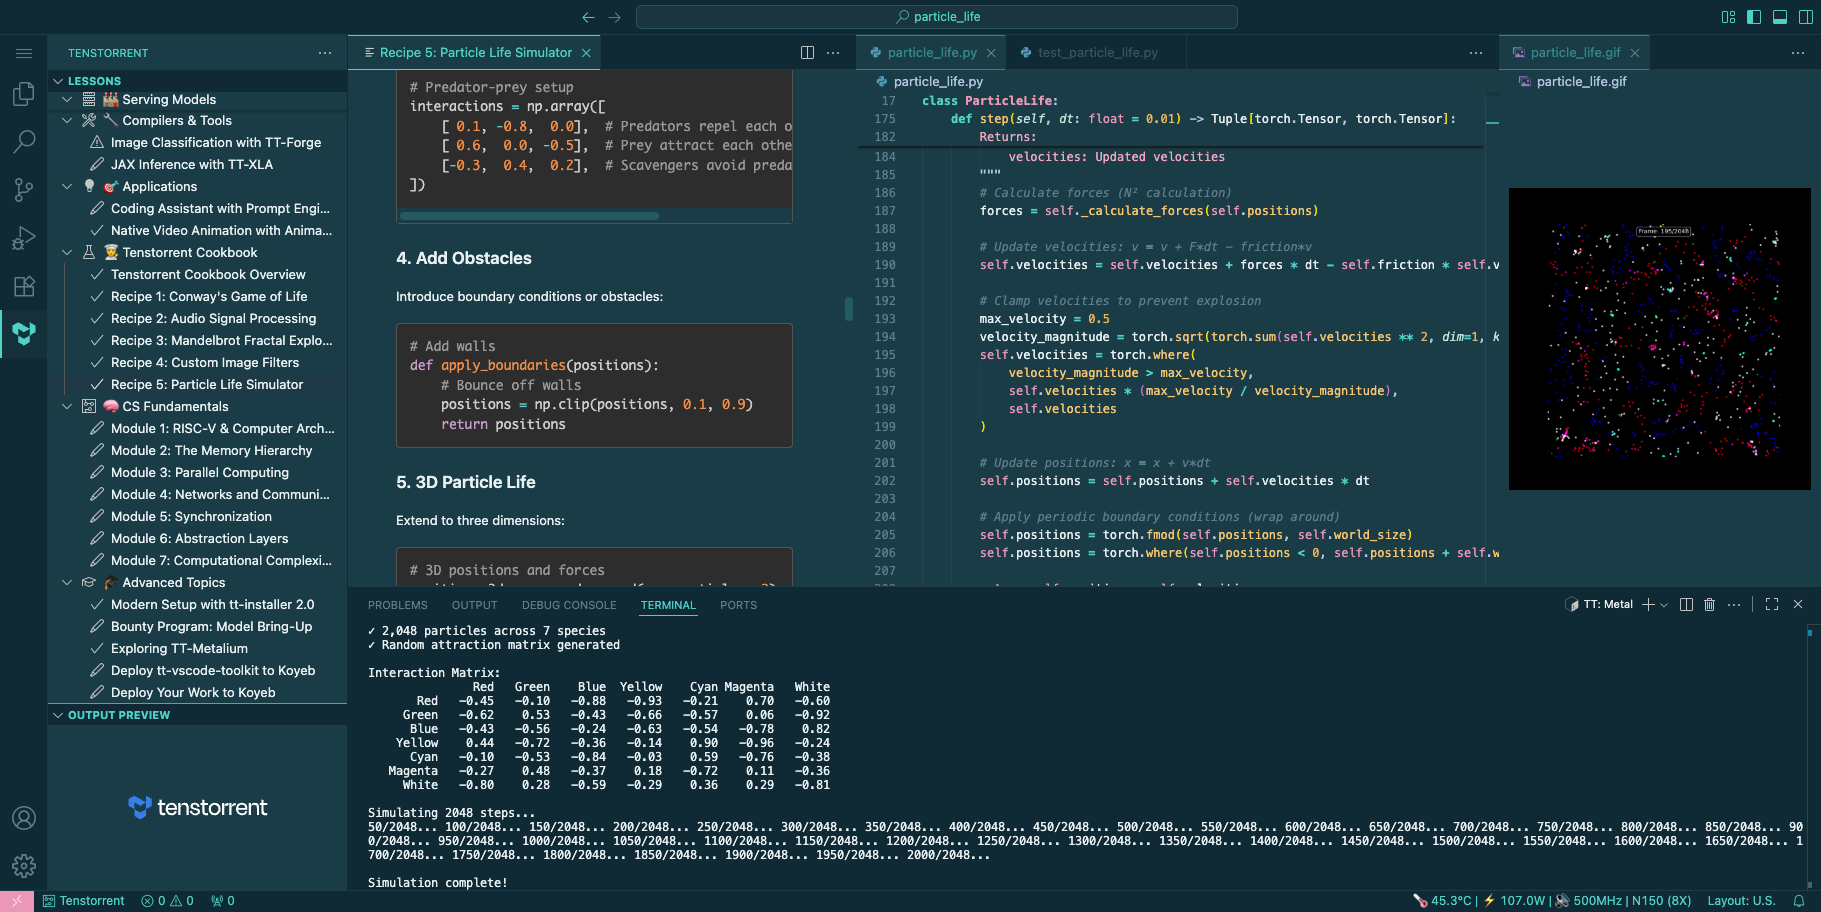
48 interactive lessons covering the full Tenstorrent developer path — from hardware detection to custom training — with click-to-run commands and hardware auto-detection. Available in VSCode and code-server.
📋 Changelog
# Changelog

All notable changes to the TT-VSCode-Toolkit will be documented in this file.

The format is based on [Keep a Changelog](https://keepachangelog.com/en/1.0.0/),
and this project adheres to [Semantic Versioning](https://semver.org/spec/v2.0.0.html).

---

## [0.1.29] - 2026-09-07

Correctness pass on what a TT-QuietBox 2 actually ships. The three-path venv
activation blocks added in 0.1.25 offered `~/.tenstorrent-venv` as the "QB2
pre-installed" environment for TT-NN and vLLM, and described a QB2 as "4
independent single-chip devices". Neither claim is true, and this release
corrects both everywhere they were found — including in this repo's own
`CLAUDE.md`, `llms.txt`, and two lessons outside the original diff
(`content/pages/FAQ.md`, `monkeypatch-ttnn.md`) that had never been touched
by the earlier topology/venv corrections this built on.

Verified against `tt-installer`'s `install.m4`, the published `tt-metalium`/
`tt-metalium-models` GHCR image configs, `tt-inference-server`'s `run.py`,
and tt-metal `main` — plus live end-to-end testing on a QB2-equivalent
board — rather than other Tenstorrent docs, which largely descend from the
same stale source note this release supersedes.

### Fixed

**`~/.tenstorrent-venv` is not a TT-NN or vLLM environment.** `tt-installer`
only ever installs `tt-smi`, `tt-flash` and (opt-in) `tt-topology` into it, so
`import ttnn` and `import vllm` both fail there. TT-NN lives **only** inside
the TT-Metalium container (`tt-metalium`, where `python3` is
`/opt/venv/bin/python3`); vLLM runs in a container `tt-inference-server`
launches. Corrected everywhere this was asserted or assumed:
- The "QB2 pre-installed image" activation line in all 11 TT-NN blocks across
  `explore-metalium`, `video-generation-ttmetal`, `animatediff-video-generation`,
  `cookbook-game-of-life`, `cookbook-mandelbrot`, `cookbook-particle-life`,
  `cookbook-image-filters`, `cookbook-audio-processor`, and the four lessons
  that used it as a premise (`lfs-00-intro`, `lfs-05-train-and-run`,
  `ct1-understanding-training`, `ct4-finetuning-basics` — their `ttml`-needs-a-
  source-tree conclusions were already correct; only the premise changed).
- `tt-installer`'s own "may not include the container wrapper" framing —
  backwards: a QB2 *has* the wrapper (it's the only way to reach TT-NN) and
  has no host-side TT-NN. Its "Test TT-Metalium" button and pytest demo
  example were also broken independent of this: missing `-c` (so `bash` tried
  to run the whole command string as a filename), a bare `ttnn.__version__`
  that doesn't exist on the built package (now `getattr(ttnn, "__version__",
  "import OK")`), and — for the demo — the wrong container and a Blackhole
  demo path that moved in tt-metal's January 2026 reorg (now
  `tt-metalium-models` + `models/demos/vision/segmentation/ufld_v2/blackhole`,
  with `--install-metalium-models-container` named as off-by-default).
- `vllm-production`'s new "On a QB2 — read this first" section (pointing a
tt-toplike
official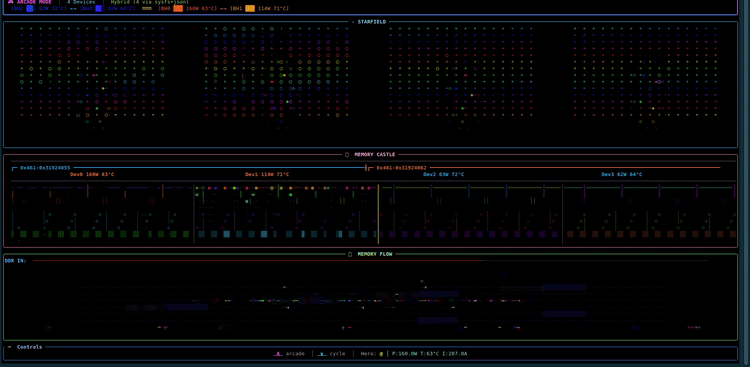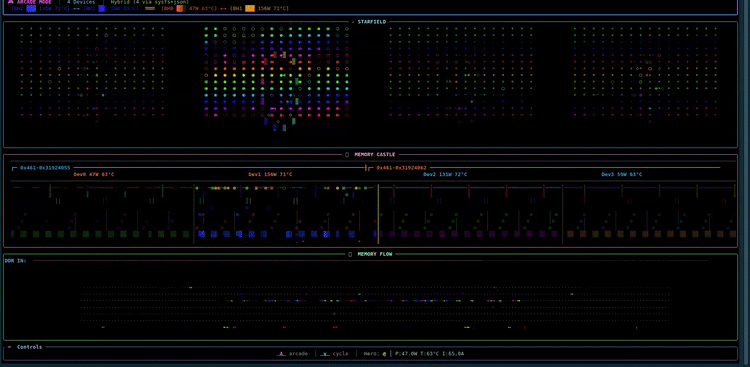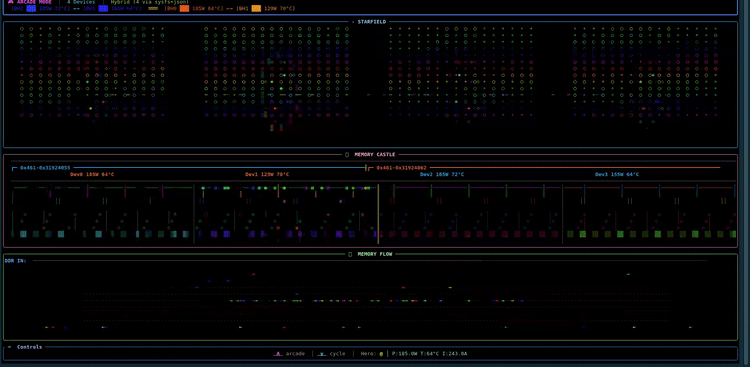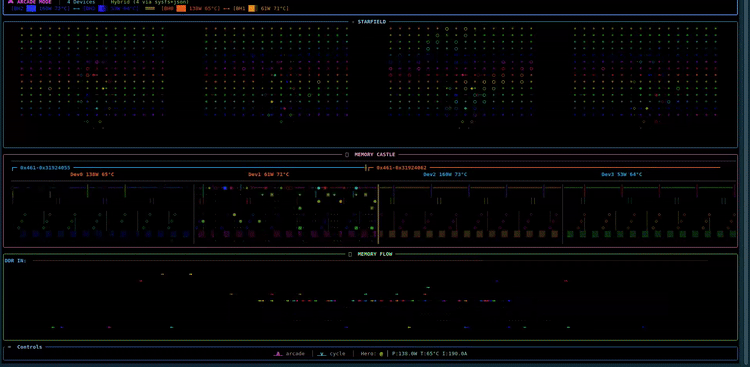
A vibrant htop-style visualizer for Tenstorrent hardware written in Rust. Real-time process and utilization view for TT accelerators.
4 previous releases
📋 Changelog
# Changelog

The **canonical, complete release log lives in [`debian/changelog`](debian/changelog)** —
that's the file the `.deb` packages are built from and where every release is
recorded in full. This file is a friendly pointer plus a summary of the most
recent releases; it deliberately does not duplicate the whole history.

To see everything:

```bash
less debian/changelog          # full history
git tag                        # released versions
```

## Recent releases

### 0.11.0
- **Add**: Training view (`t`) — a full-screen visualization of a live
  tt-train run, drawn as the network it is: a character grid of transformer
  blocks and attention heads fed by token particles, a loss "mountain range"
  under a twinkling aurora nightscape that opens up as the model converges,
  plus chip telemetry alongside it.
- **Auto-attaches with no command**: scans running processes for a tt-train
  example binary (`nano_gpt`, `mnist_mlp`, `linear_regression`), then resolves
  `/proc/<pid>/fd/1` to find and tail that process's log. Checkpoint saves
  are detected by mtime on the run's rolling checkpoint file.
- **Honest limitation**: tt-train's per-step stream can only be tailed if its
  stdout was redirected to a real file at launch (`> train.log`). If fd 1 is
  a pipe or tty, retroactively reading it is an OS-level impossibility, not a
  gap in this tool — the view says so and falls back to what it can still
  see (process liveness, chip telemetry, and checkpoint mtime) rather than
  drawing a fake loss curve. Gradient norms, MFU, and throughput counters
  aren't emitted live either, so the view derives tokens/sec and ETA only
  from what it can actually read.
- Nine independent color channels (loss magnitude, run-history timeline,
  loss-delta direction, forward/backward sweep cadence, cache compile/steady
  state, checkpoint bursts, plus chip temp/power) — see the new legend and
  explain overlays.

### 0.10.3
- **Security fix**: a direct-vLLM host process's own `PATH` was forwarded
  onto the `sh` the monitor spawns to probe it — a bare `Command::new("sh")`
  lookup resolves via whatever `PATH` ends up on the builder, so an
  attacker-controlled process (gated only by `MESH_DEVICE`/`TT_METAL_HOME`,
  which the process itself controls) could have redirected the root-run
  monitor into executing a planted binary. Fixed by invoking the interpreter
  via an absolute path and never forwarding the target's own `PATH`.
- **Fix**: four GDDR-telemetry correctness gaps — a stale 8-channel cap
  dropping real fault data for Blackhole's channels 8–11, Starfield's DDR
  planets missing an `enabled` check present in every other memory
  visualization, the Insights GDDR temp/ECC rows silently disappearing
  instead of falling back on partially-usable real data, and a missing ECC
  counter parsing as a genuine zero instead of "not reported".
- **Perf**: a host-keyed service's per-tick probe redundantly re-read
  `/proc/<pid>/environ` up to four times and re-walked
tt-tools-common
officialShared helper library of common utilities used across Tenstorrent system tools such as tt-smi, tt-flash, and tt-topology. A dependency rather than a standalone tool.
4 previous releases
📋 Changelog
# Changelog

All notable changes to this project will be documented in this file.

The format is based on [Keep a Changelog](https://keepachangelog.com/en/1.0.0/),
and this project adheres to [Semantic Versioning](https://semver.org/spec/v2.0.0.html).

## 1.4.17 - 02/07/2025

### Changed
- Loosened requirements on pyproject.toml to make it more compatible in different venvs

## 1.4.15 - 05/05/2025

### Changed
- parse\_reset\_json now returns a ResetInput with stricter typing

## 1.4.14 - 04/02/2025

### Added
- New flags in reset config file generation to disable sw\_version reporting

## 1.4.13 - 23/1/2025

- Removed nr\_hugepages count from compatibility, as hugepages allocation is tricky
  and deserves its own widget elsewhere.

## 1.4.12 - 16/1/2025

- Added TTHostCompatibilityMenu to replace Host Info and Compatibility boxes
- Added a count of nr\_hugepages to the TTHostCompatibilityMenu

## 1.4.11 - 30/12/2025

- Updated Luwen version to fix Maturin issue

## 1.4.10 - 16/12/2024

### Changed
- detect\_chips\_with\_callback now takes a print\_status arg

## 1.4.9 - 11/12/2024

### Changed
- A failed reset now results in a fail exit code on BH

## 1.4.8 - 11/10/2024

### Changed
- Updated reset completion logic to handle the case where the bmfw needs to upgrade itself

## 1.4.7 - 11/10/2024

### Added
- Implemented m3 reset option for Blackhole

### Fixed
- Fixed crash during driver version dection when the "extraversion" field is used
    - i.e. 1.28-bh

## 1.4.6 - 17/07/2024

### Added
- Reset support of Blackhole

## 1.4.5 - 11/07/2024

### Added
- Bump pyluwen library version (v0.3.8 -> v0.3.11)
- Moved pyluwen v0.3.11 to optional dependencies in pyproject.toml

## 1.4.4 - 21/06/2024

### Added
- Version bump of python dependencies in pyproject.toml (dependabot)
    - requests (2.31.0 -> 2.32.0)
    - tqdm (4.66.1 -> 4.66.3)
- Pydantic library version bump (1.* -> >=1.2) to resolve: [TT-SMI issue #27](https://github.com/tenstorrent/tt-smi/issues/27)

## 1.4.3 - 14/05/2024

### Added
- Arm platform check and warning for WH device resets in compatibility menu
- Added check for WH device init after reset and prompt user to reboot host if chips are still non recoverable
- Bumped textual (0.59.0) and luwen (0.3.8) lib versions

## 1.4.2 - 04/04/2024

### Added
- Added "silent" flag to WH and GS resets to make them more versatile for use in other tools

## 1.4.1 - 22/03/2024

### Fixed
- removed pyluwen version to avoid dependency issues in other repos

## 1.4.0 - 19/03/2024

### Added
- detect_device_fallible that will provide feedback about chip state during init

### Fixed
- Update min driver version to 1.26 to perform lds reset
- Reset config file uses dev/tenstorrent id
- Catch JSON errors in reset config parsing
- Make nested dirs when initializing reset config path

## 1.3.0 - 06/03/2024

### Added
- Migrated GS Tensix reset to tools_common
- Migrated all related GS data files
- Functions to fetch arc and eth fw versions from telemetry
tt-kernel
officialDistributes models over the Hugging Face Hub and serves them on Tenstorrent hardware — `tt-kernel serve <namespace>/<model>` pulls a bundle, registers it with the Tenstorrent vLLM plugin, and launches an OpenAI-compatible server. A vLLM bundle ships only adapter code and metadata (weights stay referenced by HF repo id), while legacy kernel-cache bundles package precompiled tt-metal kernel binaries so a model's first run is a cache hit instead of a slow JIT recompile. Explicitly experimental — the bundle format and APIs may change without notice.
tt-rpm
officialCycle-level, execution-driven RISC-V CPU performance model built on Sparta (MAP) with Whisper supplying functional execution, so it runs real ELF binaries — CoreMark, Dhrystone — to completion. The pipeline is YAML-configurable across in-order/out-of-order execution, issue policy, execute granularity, write-port arbitration, and bypass paths, with a modeled L1 I$/D$ plus optional unified L2, per-unit logging, stats reports, and Konata pipeline visualization.
tt-emule
officialA C++ software emulator of the Tenstorrent device-level kernel and host APIs. Run tt-metal kernel and host code on a standard x86-64 Linux machine — no Tenstorrent hardware required.
tt-low-level-documentation
officialDocumentation for the low-level layer of tt-metal: compute LLK APIs and data movement APIs. The data movement side covers the NOC and overlay on Wormhole and Blackhole; the compute side covers Tensix hardware and expected usage of the LLK APIs. Aimed at op and model writers who need to know what the APIs do and how the hardware behaves underneath them.
tt-system-tools
officialSystem setup and support utilities for Tenstorrent hardware — hugepages-setup configures the 1GB hugepages TT ASICs need, and tt-oops collects diagnostic data for troubleshooting. Ships as the tenstorrent-tools deb/rpm.
4 previous releases
tt-local-generator
official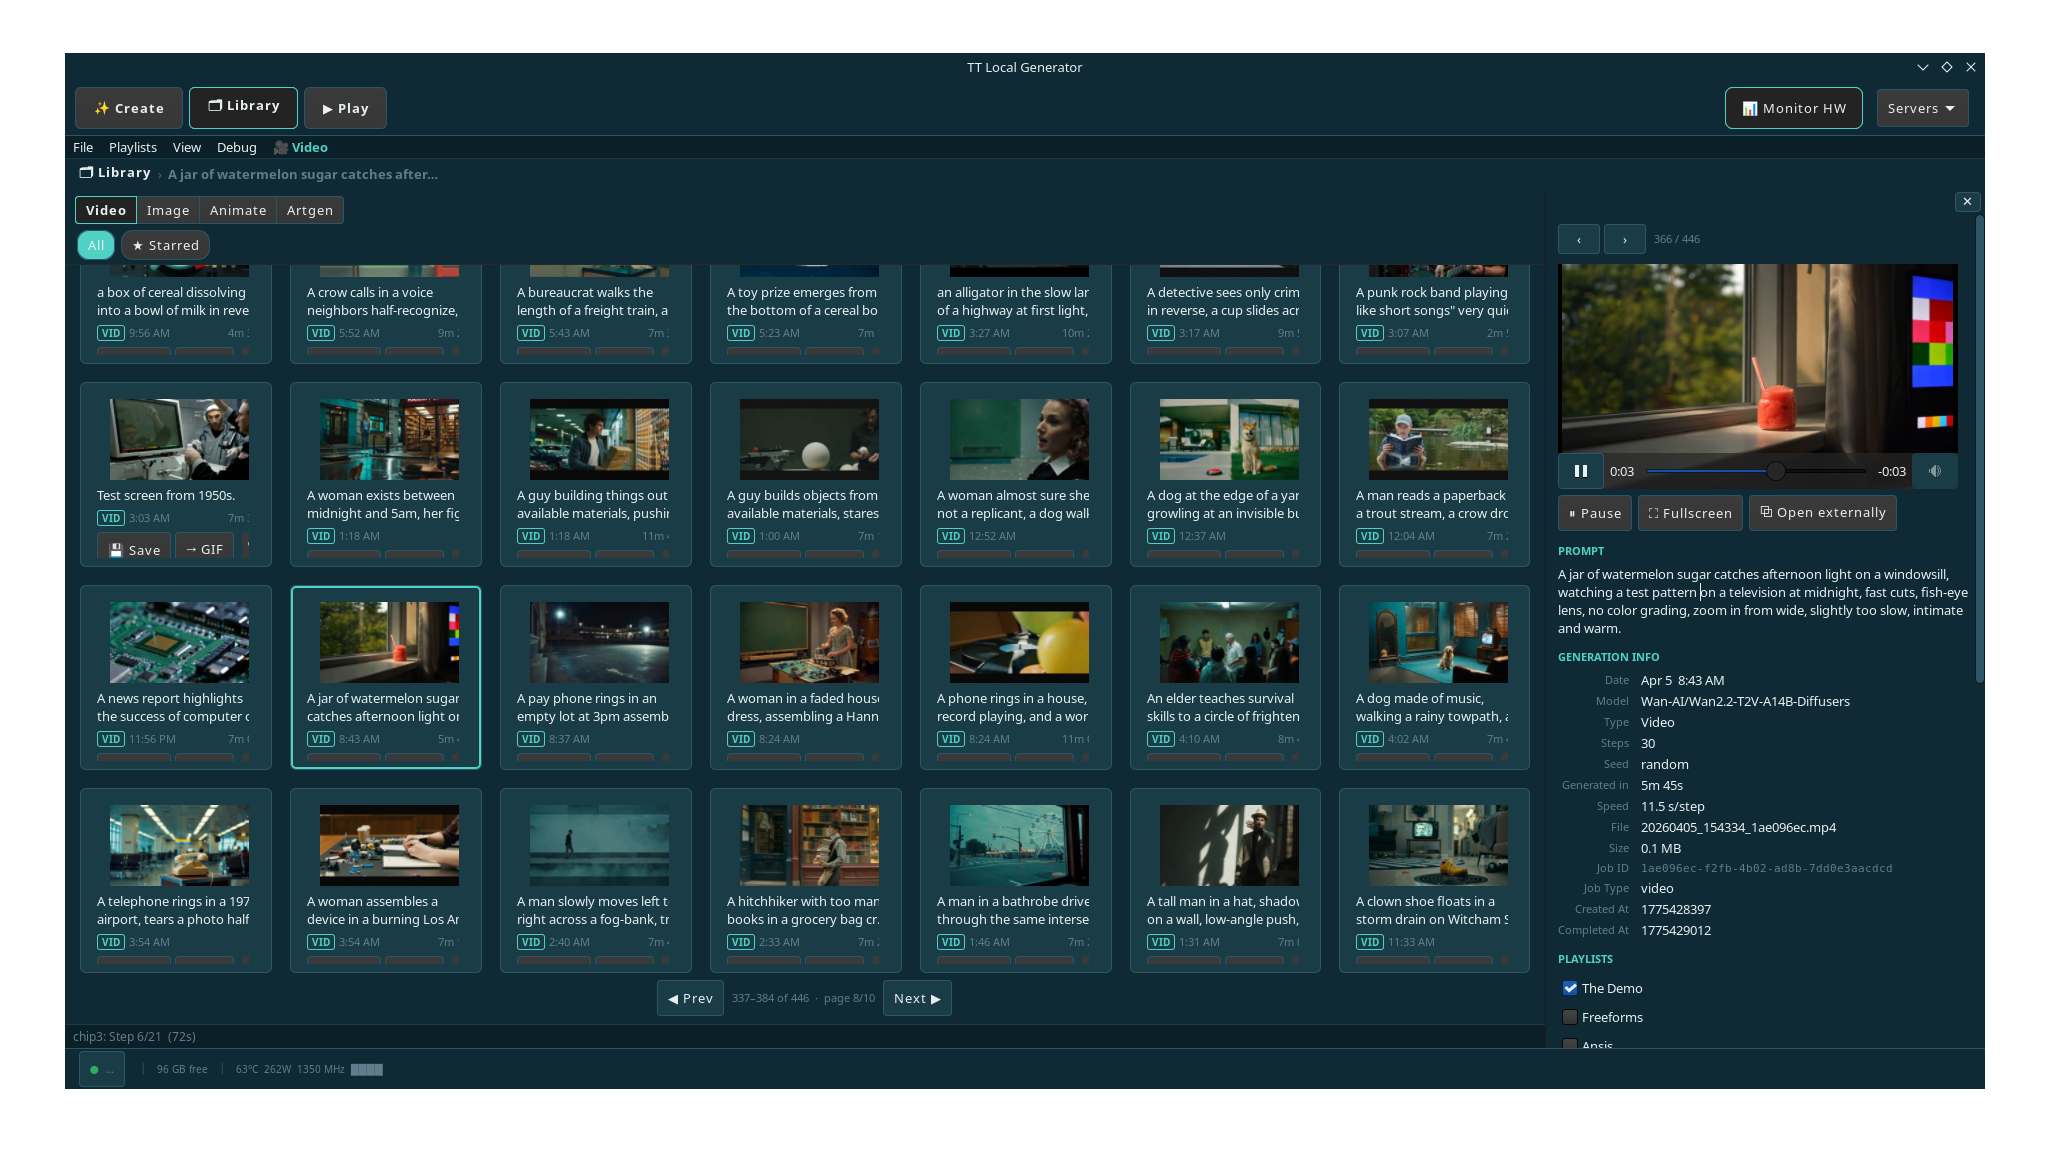
GTK4 desktop app for generating video, images, and generative art locally on Tenstorrent hardware — Wan2.2 text-to-video and character animation, SkyReels-V2, Mochi-1, FLUX.1 text-to-image, and AnimateDiff, plus a three-tier prompt generator (algorithmic, Markov, Qwen3-0.6B) to inspire them. Installs from the Tenstorrent PPA; model weights ship as separate tt-model-* packages, and an MCP server exposes every generator as a tool to Claude Code and other clients.
4 previous releases
tt-burnin
officialCommand-line utility that runs a high power-consumption workload on Tenstorrent devices — used for chip testing, burn-in, and validating a system's power delivery and cooling under sustained load.
4 previous releases
📋 Changelog
# Changelog

All notable changes to this project will be documented in this file.

The format is based on [Keep a Changelog](https://keepachangelog.com/en/1.0.0/),
and this project adheres to [Semantic Versioning](https://semver.org/spec/v2.0.0.html).

## 0.2.2 - 31/07/2024

### Added
- Added glx reset support
- Threaded start and end of burnin to increase burnin speed
- Added prints to indicate which chip we are currently running on
- Added support for bh harvesting

## 0.2.1 - 16/01/2024

### Bug fix
- Fix for https://github.com/tenstorrent/tt-burnin/issues/6
- BH reports asic temperature as a signed 16_16 int unlike GS and WH
- Added missing support to report BH asic temperatre

## 0.2.0 - 29/10/2024

### Added
- BH burnin support

## 0.1.1 - 14/05/2024

### Updated

- Bumped luwen (0.3.8) and tt_tools_common (1.4.3) lib versions

## 0.1.0 - 04/04/2024

First release of opensource tt-burnin

### Added
- GS and WH burnin support
tt-CableGen
official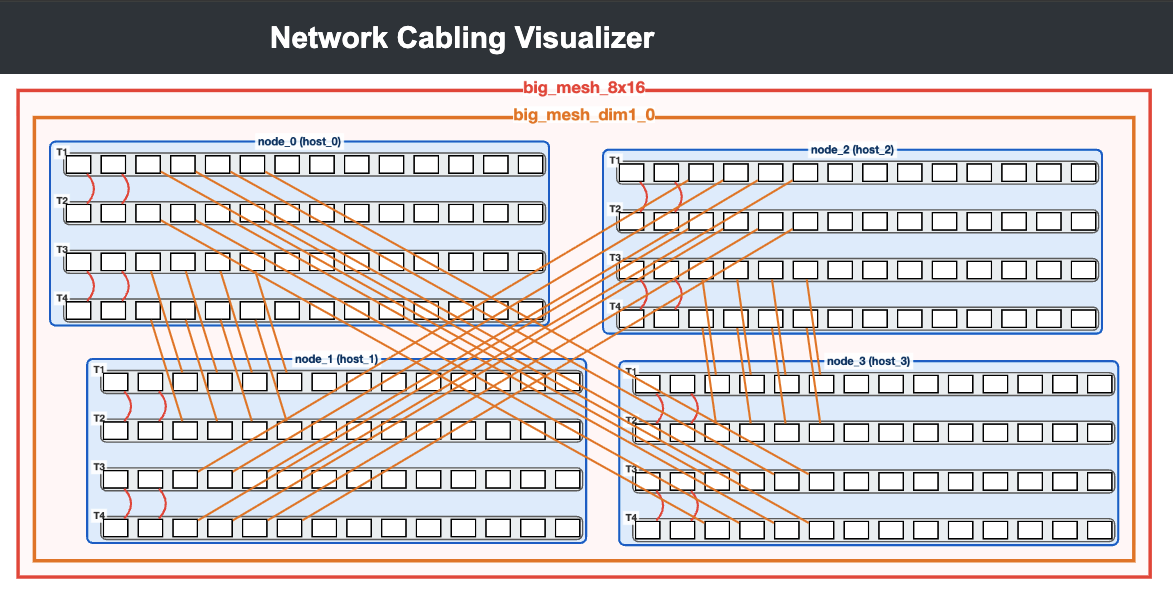
Network cabling visualizer for Tenstorrent scale-out deployments: describe a target topology and it generates and renders how to physically cable multiple Wormhole or Blackhole systems together. Works in a physical-deployment mode with racking information and a logical-hierarchy mode for clustering/pod groupings, with topology import/export and a Docker deployment path.
tt-animatediff
official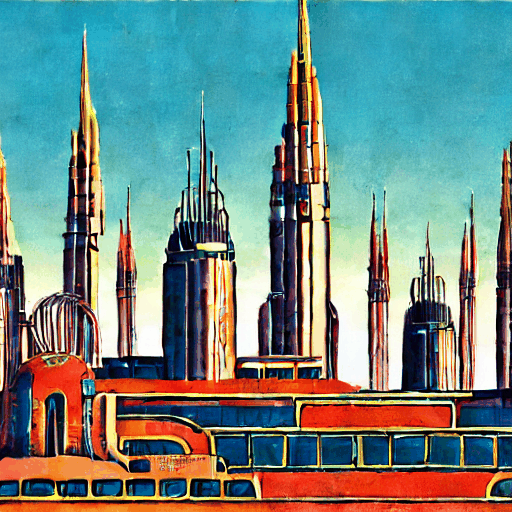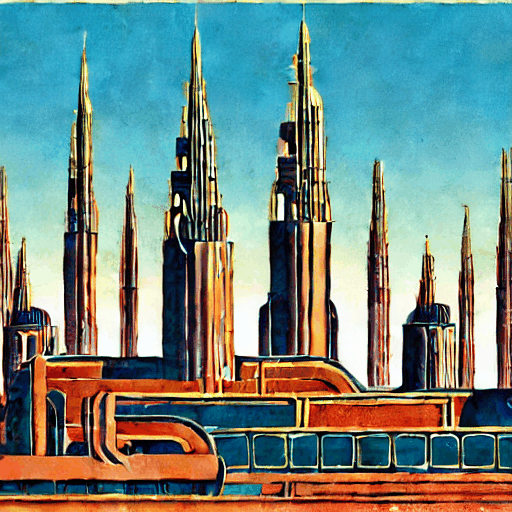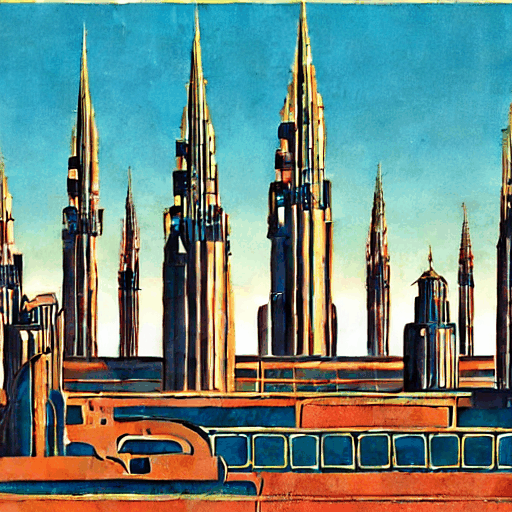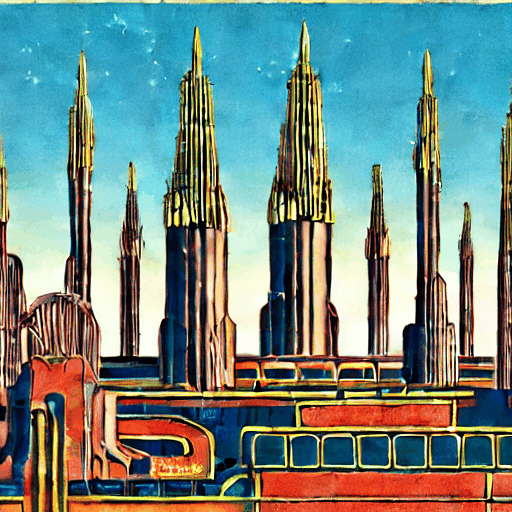
Generates short, temporally coherent animated GIFs using the AnimateDiff model on Tenstorrent hardware. Phase 1 runs the correct SD 1.4 + MotionAdapter architecture on CPU; Phase 2 accelerates spatial denoising on Blackhole using the TTNN UNet. Produces vibrant 8-frame animations in ~15 s/frame on a P300C.
tt-cli
officialSingle entry point to the Tenstorrent software stack: `tt update` converges a machine onto the CI-tested "golden" version set, `tt device` covers status/info/reset, and `tt model`/`tt serve` pull weights and bring up tt-inference-server. Commands either run natively or delegate to tt-smi, tt-flash, and tt-installer behind a stable interface, with `--json` output and documented exit codes on every command. Beta software — breaking changes are expected — installed from PyPI as `tenstorrent` (`uv tool install tenstorrent`, or any pip-compatible tool). Usage telemetry is opt-in.
Cloud-Native Support
officialOfficial documentation hub for running Tenstorrent accelerators on Kubernetes. Centers on tt-operator (the umbrella Helm chart) and covers Node Feature Discovery, kernel-mode driver (tt-kmd) management, firmware flashing, Prometheus telemetry, Fabric Manager topology resolution, Dynamic Resource Allocation, and multi-node scheduling via JobSet and PMIx.
TT Console
official★ featuredBrowser-based cloud console for exploring AI on Tenstorrent hardware. Run LLM inference, image and video generation, and browse the supported model catalog in-browser — backed by Tenstorrent accelerators. Cloud hardware access and advanced workflows (deployments, agents) available in staged rollout.
TenGEMM
officialTensix GEMM performance estimator and visualizer. A React app that models matrix-multiplication workloads on a Tensix core, estimates the resulting performance, and shows how the work maps onto the hardware — useful for reasoning about a matmul's shape and fidelity choices before writing the kernel.
TT-QuietBox 2 Guide
officialOfficial setup and onboarding guide for the TT-QuietBox 2 — a compact, liquid-cooled AI workstation with four Blackhole accelerators, an AMD Ryzen CPU, 256GB RAM, and 4TB NVMe. Covers hardware specs, first-boot setup, and hands-on learning paths for running pre-loaded models like Qwen3-32B and serving text, image, video, and speech models via tt-inference-server.
Tenstorrent's fork of QEMU that provides the full-system emulation layer behind ttsim. Models the RISC-V cores and system devices of Wormhole and Blackhole so TT-Metalium workloads can boot and run without physical silicon.
tt-bio
affiliated★ featuredBoltz-2 biomolecular model for drug discovery on Tenstorrent Blackhole. Supports single-card and multi-card configurations — QuietBox (4×) and Galaxy (32×). Approaches physics-based FEP accuracy at 1000× the speed.
📋 Changelog
# Changelog

All notable changes to TT-Bio are recorded here. Versioning is [SemVer](https://semver.org);
releases are cut from a commit that has passed the on-hardware test suite (see `RELEASING.md`).

## [Unreleased]

### Added

- **`modifications:`, `templates:` and `--max_msa_seqs` reach the models that were dropping
  them.** The capability pass below refused these rather than let them be dropped silently;
  three of them are now honoured instead. A `modifications:` block folds as the modified
  chemistry on protenix-v1/v2, opendde, opendde-abag, openfold3 and openbind: Protenix and
  OpenDDE tokenize the modified residue per atom from its CCD component (AF3 SI 2.6), the OF3
  family passes it as upstream's own `non_canonical_residues`. Folding a 53 aa chain with
  `{position: 13, ccd: SEP}` writes a real phosphoserine, 10 atoms and one phosphorus, against
  a plain fold with no phosphorus at all. `templates:` now builds real template features for
  protenix-v2, opendde and opendde-abag, whose trained 2-block template pairformer stack had
  only ever been handed all-gap dummy features; it takes the same precomputed alignment `.npz`
  OpenFold3 already reads, so one template file works on all five. On upstream's own 1y57 case
  a templated fold lands 5.52 A from the template against 21.69 A templateless (opendde) and
  11.11 A against 19.26 A (protenix-v2). It stays refused on protenix-v1, whose v0.5.0
  checkpoint ships an empty template stack and can only drop one. `--max_msa_seqs` caps the
  alignment on protenix-v1/v2, opendde, opendde-abag and rf3, and on openfold3/openbind, which
  read an env var and never the flag. Every MSA fold now writes the depth it actually used
  (`msa_depth`) into `results.json`, where `msa: true` used to say only that an alignment
  existed.

### Fixed

- **`--output_format pdb` no longer fails on a chain id longer than one character.** A FASTA
  with bare `>sample_03` headers folded to completion on device and then died in the writer with
  "Some chain IDs exceed 1 character", after the whole fold had been paid for. The PDB chain
  column is one character wide, and the three writers disagreed about that: the esmfold2 path
  raised, while the boltz2 and BoltzGen writers dropped a long name into a one-wide field, which
  pads but never truncates, and shifted every column after it without an error. Chain ids are now
  rewritten `A`, `B`, `C`... in first-appearance order, a residue name longer than three
  characters (a five-character CCD code, 1512 of them exist) is cut to three, and everything
  renamed is listed in a `REMARK 999` block at the top of the file. A structure whose names
  already fit is written exactly as before and carries no remark, and `cif` output does not
  change at all: it has no width limit and keeps the names you submitted. Past 62 chains a PDB
  cannot hold the ids at all, and the writer now says so and names `cif` instead of failing
  inside biotite.

- **A fold stopped by a signal now
grayskull-attention
affiliatedFlashAttention-style attention kernel implemented entirely in on-chip SRAM on the Tenstorrent Grayskull chip using TT-Metalium. Pioneering work in low-level attention on TT hardware.
tt-atom
affiliated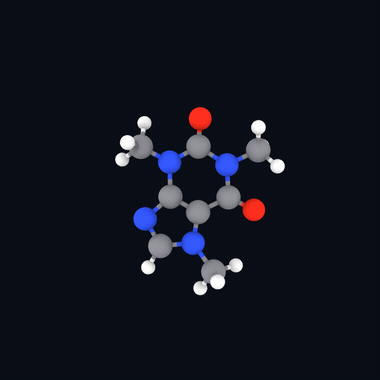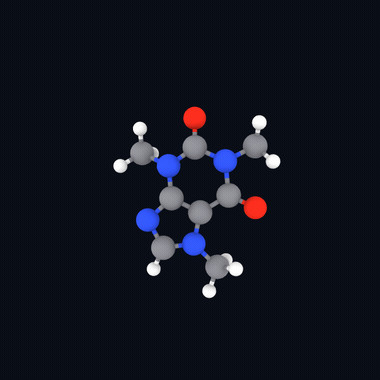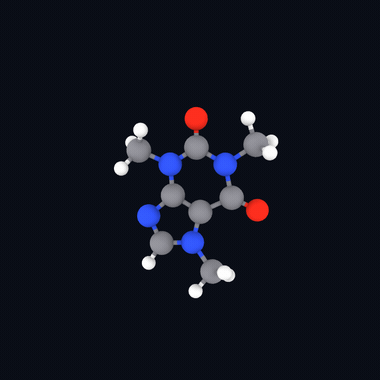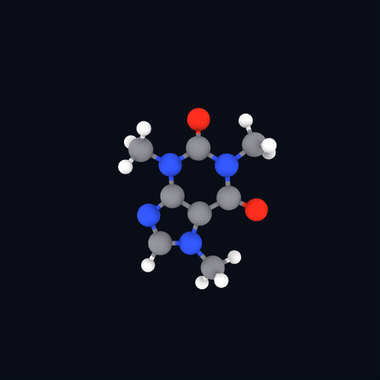
Meta's UMA interatomic potential running on Tenstorrent Blackhole — energy, forces, and stress for molecules and periodic materials behind an ASE calculator. Its per-edge Wigner rotation runs as a custom tt-metal kernel for a highest-performance uma-s build.
📋 Changelog
# Changelog

All notable changes to TT-Atom are recorded here. Versioning is [SemVer](https://semver.org);
releases are cut only from a commit that has passed the on-hardware release gate — accuracy
parity, no OOM across the supported size range, no perf or UX regression, and a clean install
smoke (see `RELEASING.md`).

## [Unreleased]

Behaviour changes are all in the knobs and the caches, not in the models: every numeric path is
byte-identical to 0.3.0.

### Fixed
- `TT_ATOM_FUSED_GATE=1` on a stock `ttnn` wheel now falls back to the ordinary path instead of
  crashing mid-forward with `AttributeError: ... has no attribute 'fused_gate'`. The flag is
  capability-probed like every other custom-kernel knob; it stays off by default.
- An interrupted weight export or golden generation can no longer leave a truncated `.npz` at the
  final name, which the consumers read as a present-but-corrupt fixture. All seven exporters and
  the gate's own performance baselines write a sidecar and rename it on success.
- `TTATOM_GOLDEN_DIR` now relocates every real-weight golden, for the benchmarks and the
  noise-floor diagnostic as well as the tests and the gate. It used to move two of them, and four
  test modules plus three dev scripts hardcoded the default with no override at all.
- Three Orb benchmarks passed `TT_VISIBLE_DEVICES` straight through as a logical device id.
  The visible set is re-indexed from zero, so anything but `0` asked for a card that was not
  there.

### Changed
- `TT_ATOM_CACHE` means the cache root everywhere. `TT_ATOM_CACHE=/data/c` now gives
  `/data/c/bundles` and `/data/c/orb_weights`; the UMA half used to treat the override as the
  bundles directory itself, and the bucketing parity module and three benchmarks read the default
  root whatever the override said — so a relocated cache silently skipped the bit-exactness
  module. Default paths are unchanged.
- Every boolean `TT_ATOM_*` knob reads the same way: `=1` on, `=0` off, anything else the
  documented default. Three mutually inconsistent readings were in use, so `TT_ATOM_NORM_FLAT=true`
  silently turned a default-on path off while `TT_ATOM_ORB_SCATTER_RM=false` silently left one on.
  All ten knobs are documented in `custom_kernels/README.md`.
- Internal consolidation: one implementation each for the cache root, the atomic `.npz` write,
  Orb's per-atom neighbour cap, Orb's reverse pass, the gate's subprocess environment, the golden
  directory the gate and its tests share, and the host-to-device transfer (`tt_atom.device.to_dev`,
  which five modules each defined privately and five more imported across module boundaries).
  `benchmarks/_harness.py` is the one home for the benchmark-side concerns: timing, fixture and
  weight locations, and the fleet discipline (lease flock, quiet-host wait, sandbox child
  environment) that three subprocess benchmarks each carried a drifting copy of. `tests/util.py`
  likewise for the parity helpers the test modules shared by copy.
- Every
tt-lang-models
affiliated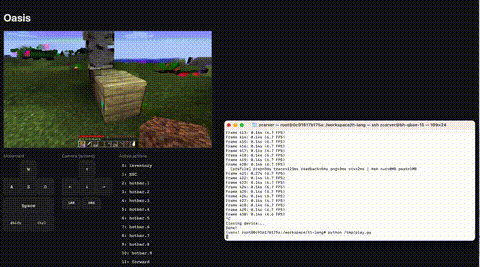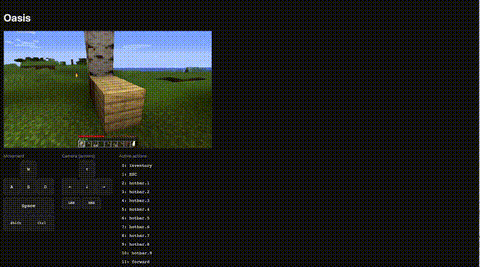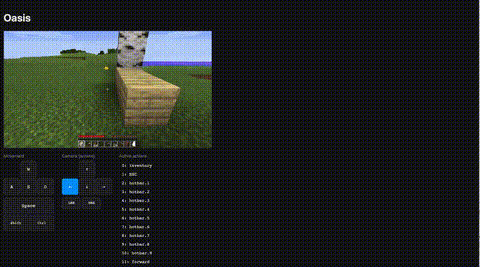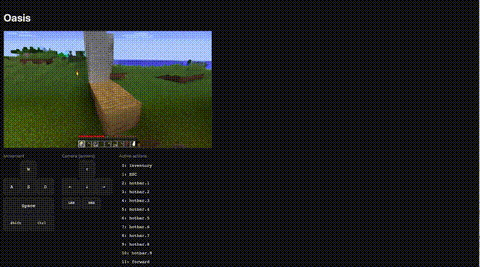
A growing collection of models that use tt-lang for some or all of their implementation. Reference implementations for bringing modern models to the tt-lang DSL.
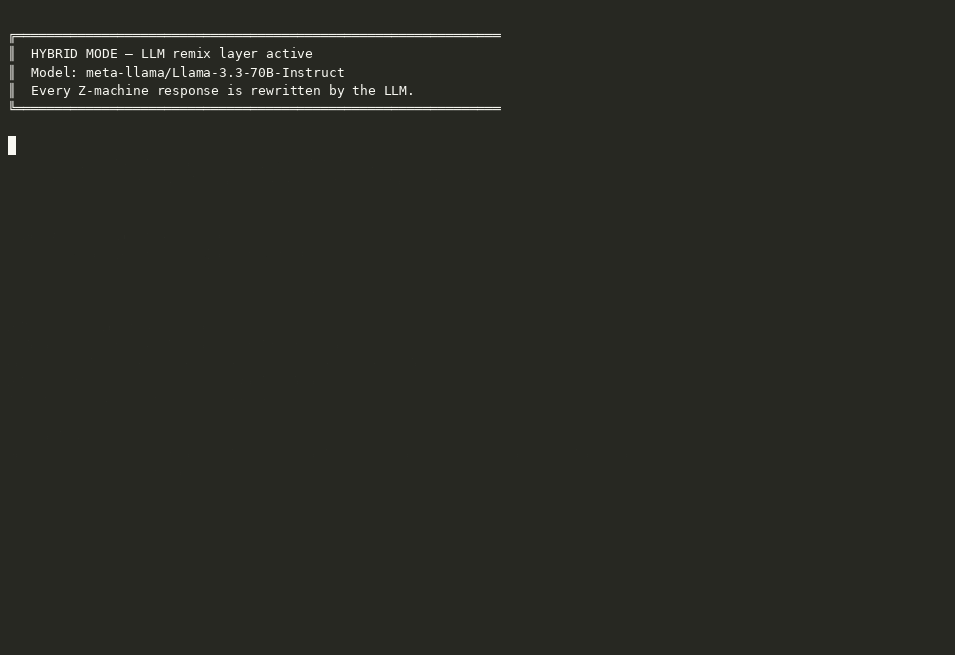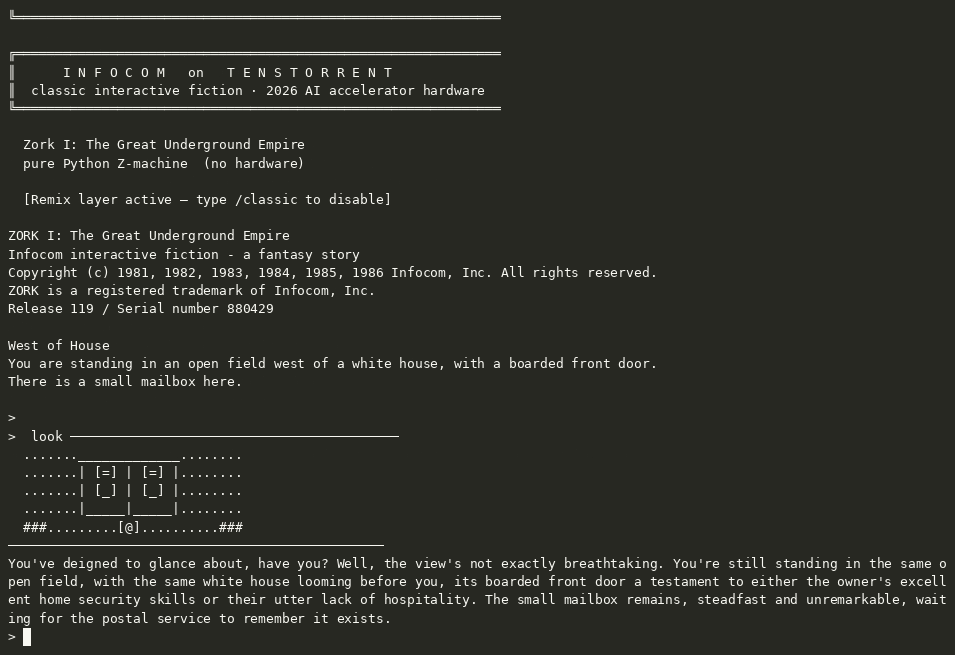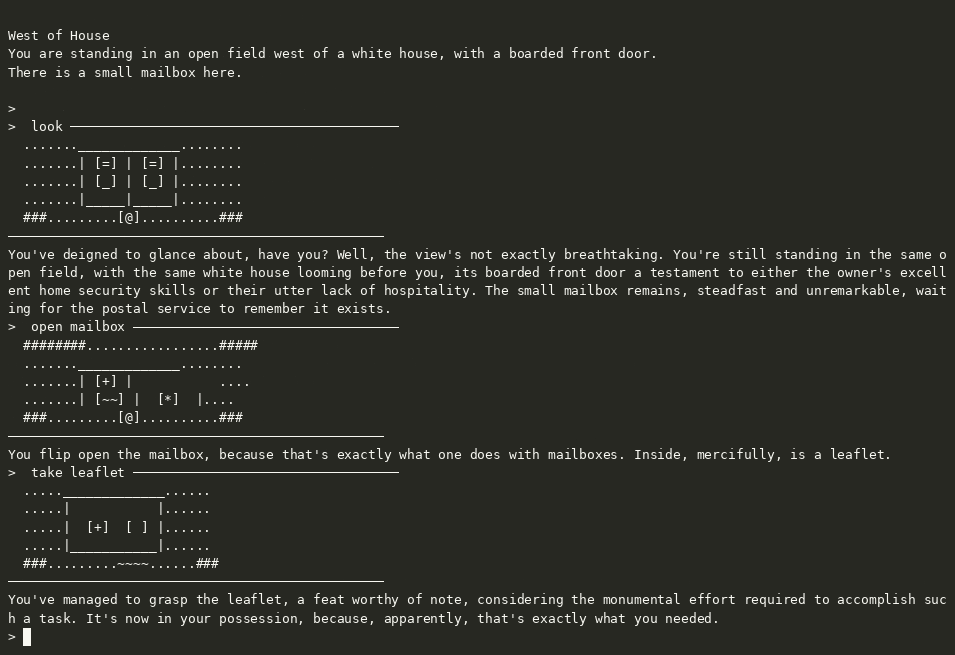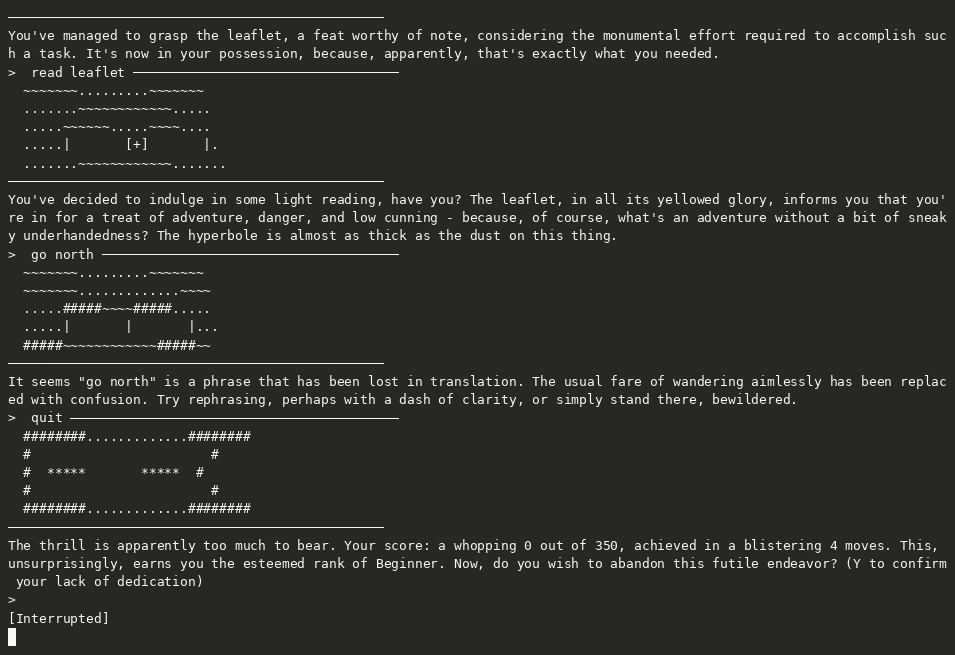
A Tenstorrent fork of Infocom's Zork I (and more!), running a Z-machine interpreter at least four different ways on TT hardware. The most fun you can have with an AI accelerator.
tt-qb-lights
affiliatedSync your Tenstorrent Quietbox's RGB lighting to accelerator utilization status. Visual feedback for hardware activity in real time.
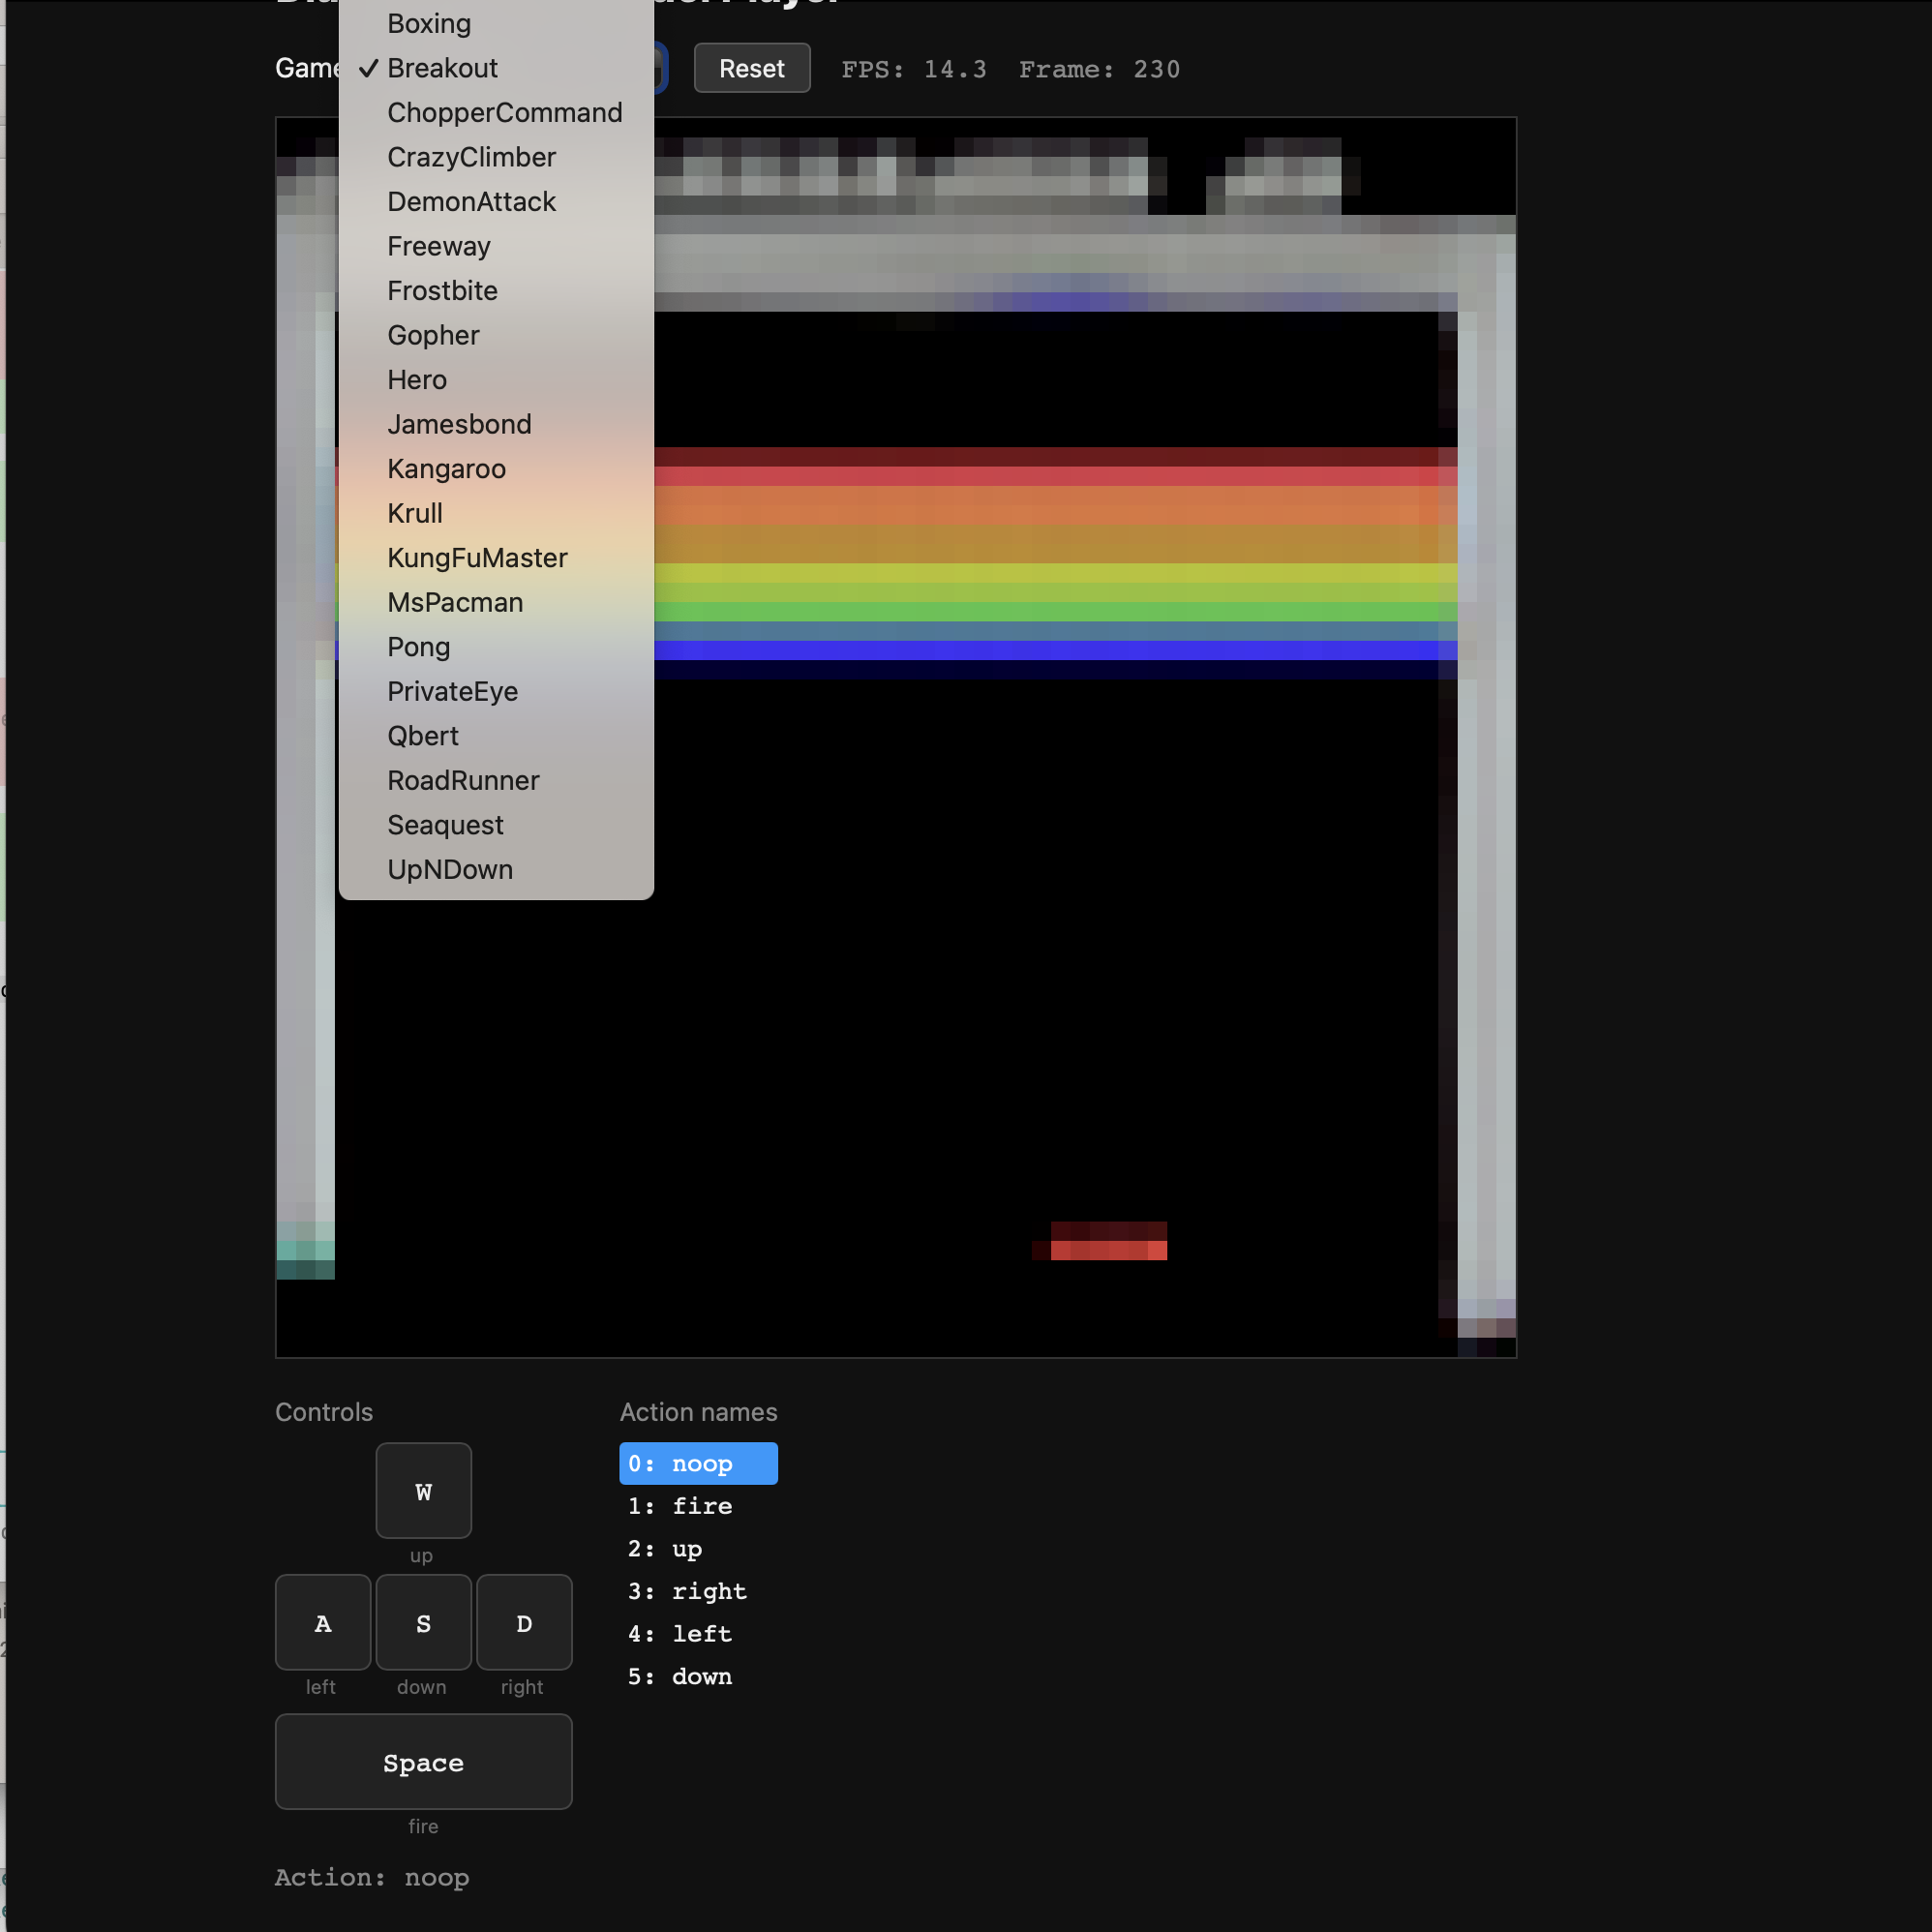
DIAMOND: Atari game-playing agent implemented on Tenstorrent hardware via tt-lang. Diffusion-based world model for reinforcement learning.
gemma4
affiliatedGemma 4 language model implemented in tt-lang (e4b variant) for direct execution on Tenstorrent hardware.
tt-lang inference script for Oasis 500M — an interactive video world model running on Tenstorrent hardware via the tt-lang DSL.
tt-model-runner
affiliatedDiscover, load, and benchmark models with a GUI and TUI for tt-inference-server. Makes exploring available models on Tenstorrent hardware as easy as browsing a catalog.
tt-bio-demo
affiliated★ featured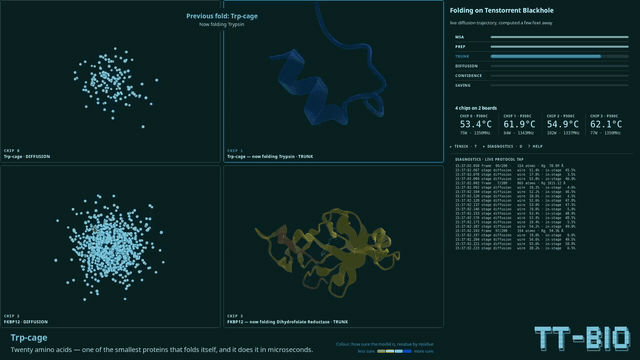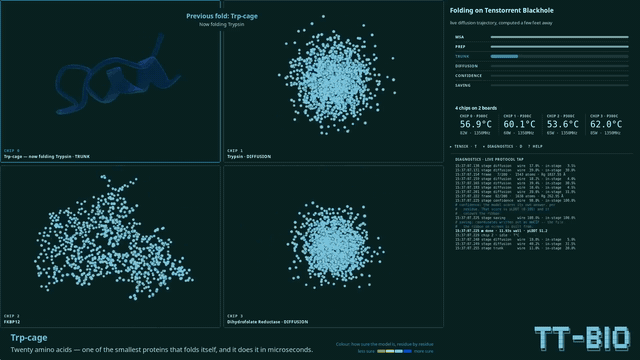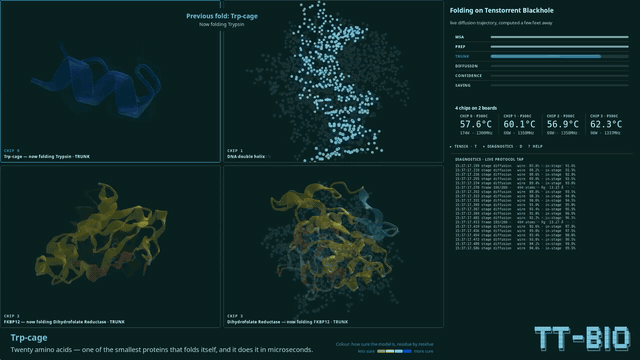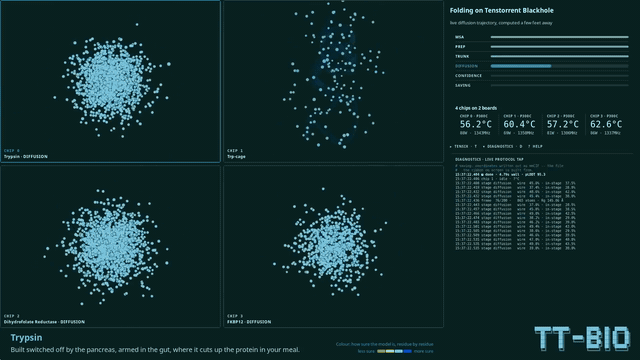
A turnkey conference-booth demo for tt-bio: watch a protein condense out of noise into its folded structure in real time, computed on the Blackhole chips a few feet away. Native GTK4 and OpenGL, with a cartoon renderer, live per-residue confidence colouring, a Tensix core grid, and a 2×2 quad view running four independent folds on four chips at once.
4 previous releases
tt-claw
affiliatedA Tenstorrent-powered claw machine that rewards players with real prizes. The QuietBox 2 runs local AI inference to act as an agent controlling the claw hardware — the OpenClaw AI assistant lesson builds directly on this project.
Local AI Agents on Tenstorrent
affiliated★ featuredThree agentic projects running fully on-device: local AI agents on QuietBox 2, a coding assistant powered by Aider against a local inference server, and the OpenClaw AI assistant on QuietBox 2. No cloud APIs — all inference runs on TT hardware.
DFlash: Block Diffusion for Flash Speculative Decoding on Tenstorrent hardware using tt-lang. Combines block diffusion with speculative decoding for faster inference.
A Tenstorrent port of the DeepSeek Engram model using tt-lang. Brings DeepSeek's memory-efficient architecture to TT hardware.
gsplat_tt
affiliatedPort of Gaussian Splatting (3D scene reconstruction from 2D images) to Tenstorrent hardware.
Stable Diffusion XL on Tenstorrent
affiliatedOn-device image generation with Stable Diffusion XL running entirely on Tenstorrent hardware. Full inference pipeline with no cloud dependency.
Video Generation on Tenstorrent
affiliated★ featuredThree lesson-projects covering on-device video synthesis: frame-by-frame diffusion with tt-local-generator, native AnimateDiff video animation, and video generation on QuietBox 2. All run entirely on TT hardware with no cloud dependency.
dev.to/mando222 — Tenstorrent & AI Blog
affiliatedEric Zietlow's blog covering Tenstorrent hardware, Metalium programming, and AI topics, sharing practical experience with Blackhole and the broader TT ecosystem from our developer relations team.
tt-forge-compiletron
affiliated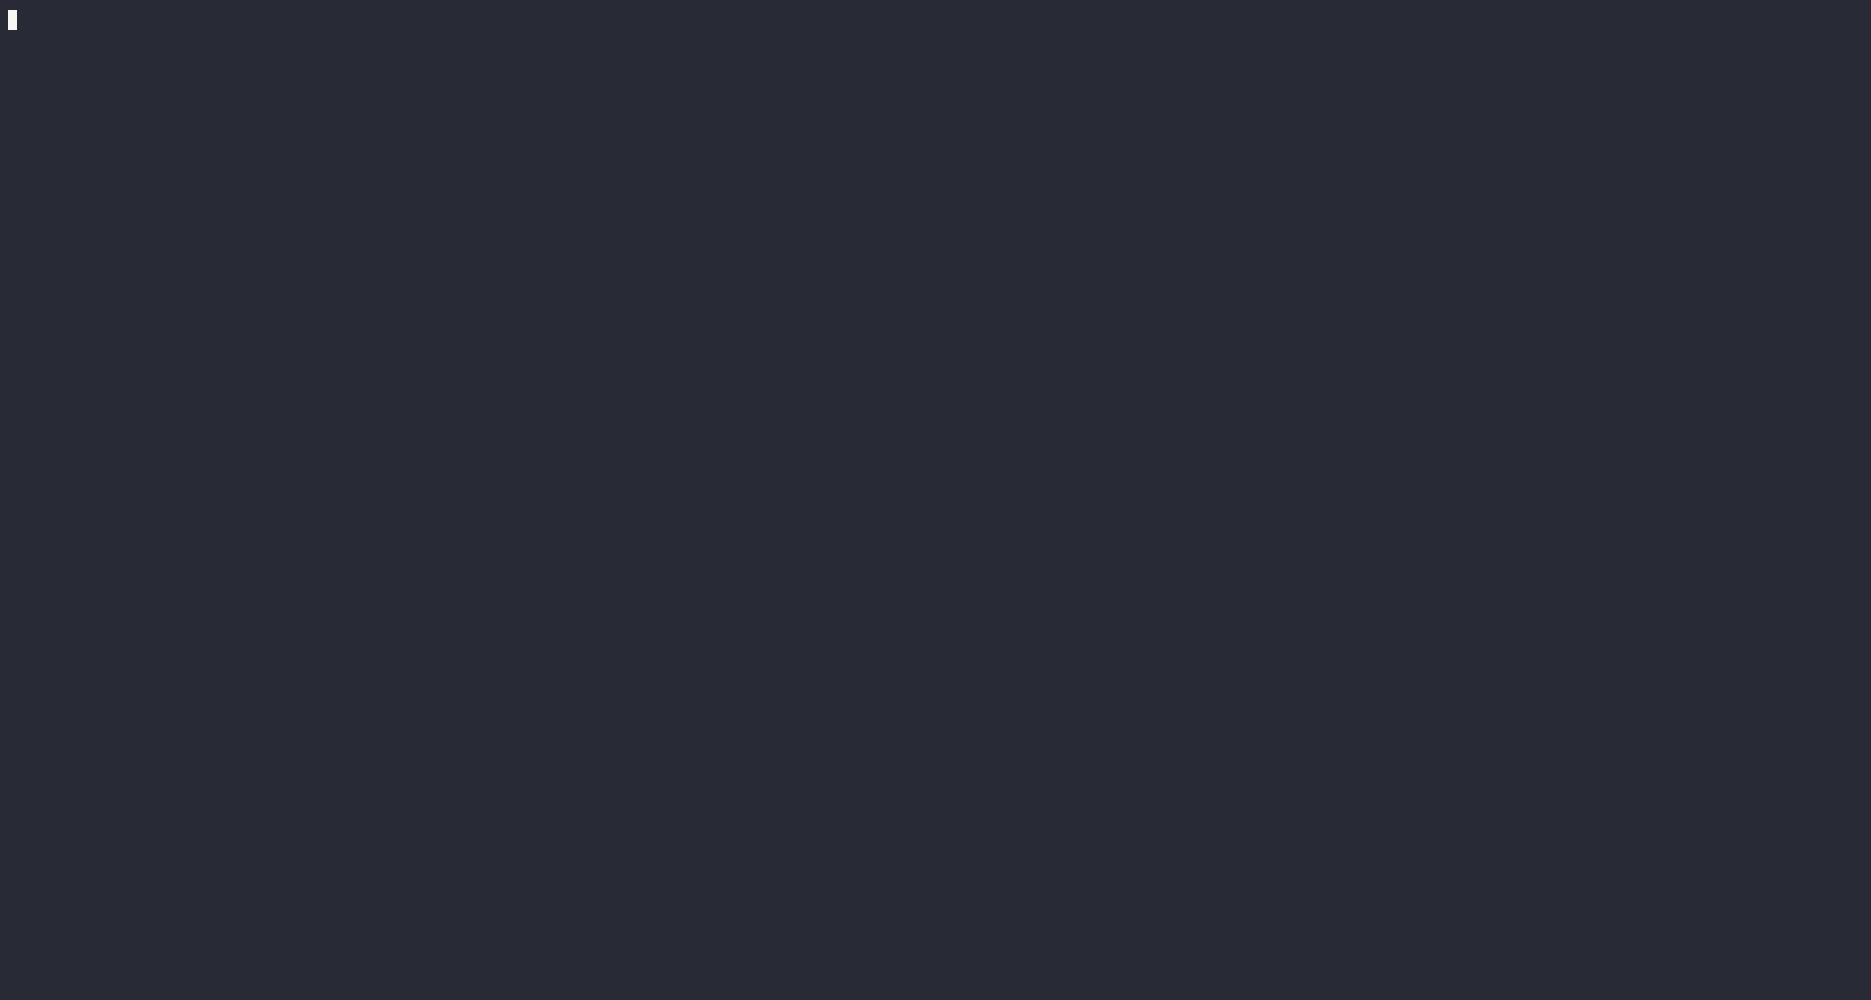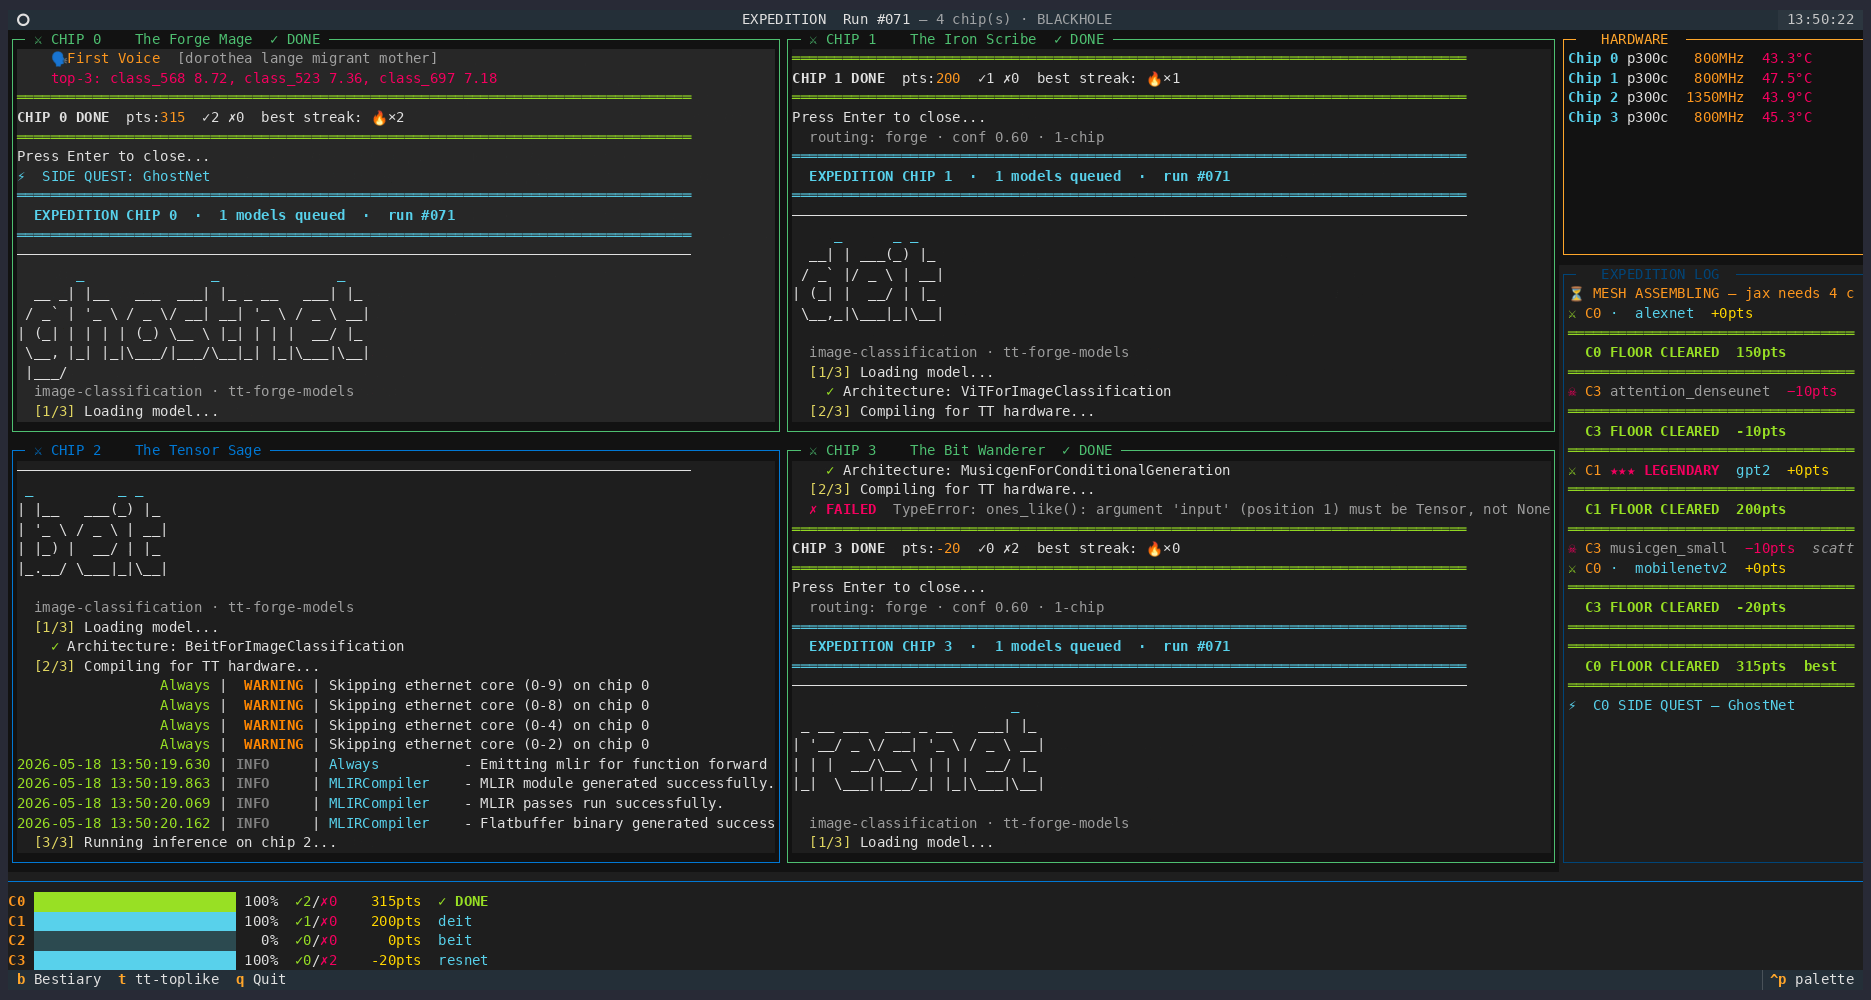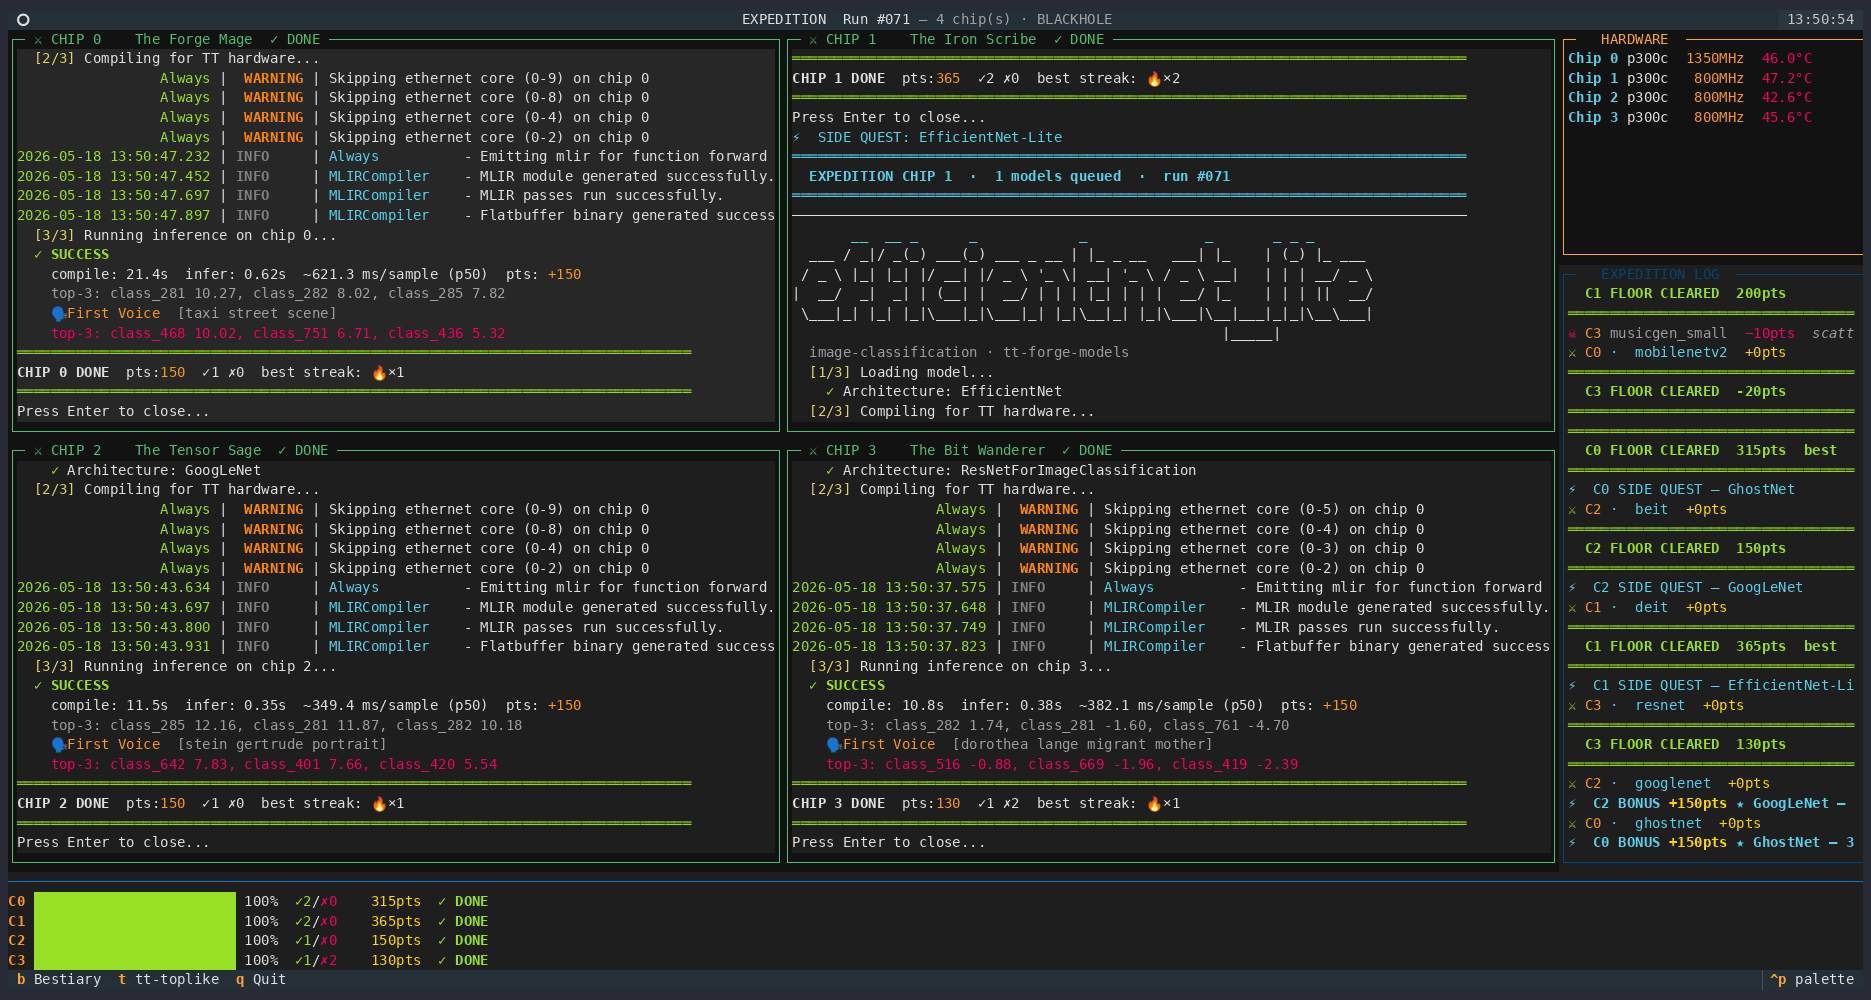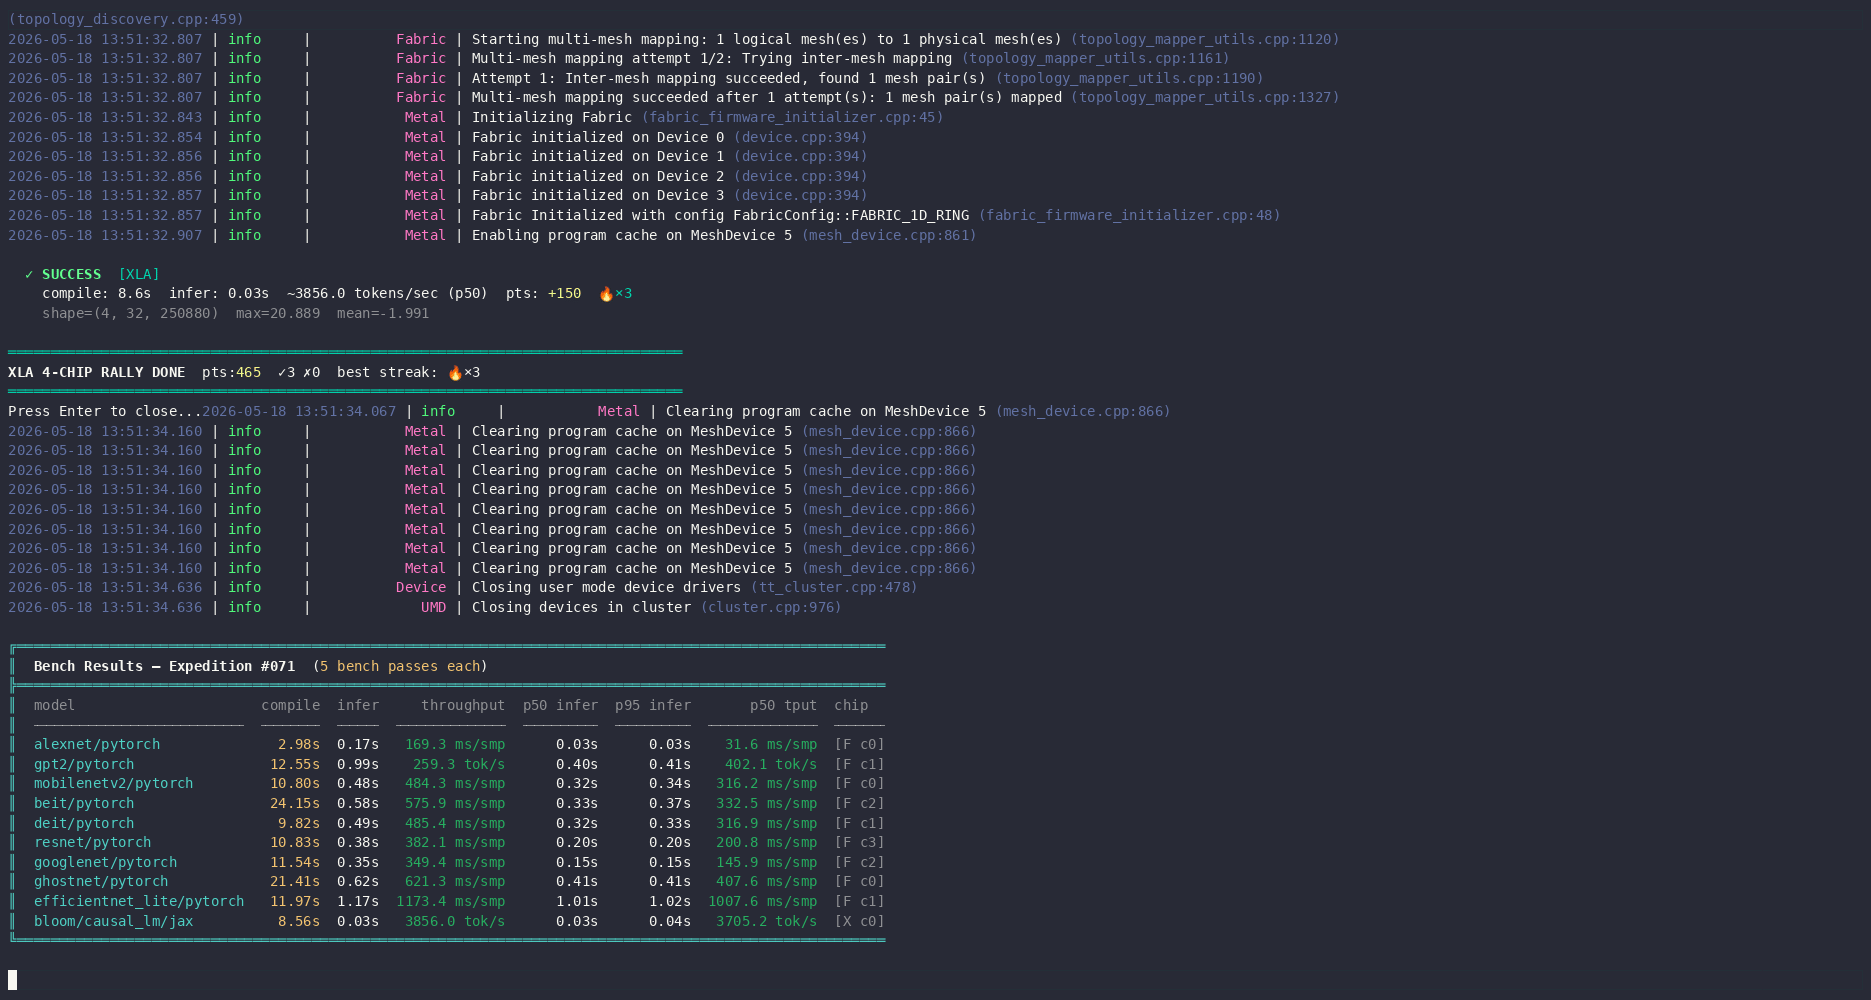
Compile more than 100 models on tt-forge in a display format suitable for demos. Comprehensive showcase of tt-forge model compatibility.
📋 Changelog
# Changelog

All notable changes to tt-forge-compiletron are documented here.

## [Unreleased]

### Added
- `docs/kv-cache-bench.md` — teaching companion for the StaticCache KV cache
  benchmark, explaining the two-graph pattern and why static shapes matter

---

## [1.6.0] — 2026-06-30

### Added
- **StaticCache KV cache decode benchmarking** — `bench_decode.py` now compiles
  a second forge graph for the decode step using `transformers.StaticCache`.
  The StaticCache is embedded in `KVDecodeWrapper` as a submodule so forge
  traces K/V tensors as model state and emits `FillCache`/`UpdateCache` ops.
  Falls back to full-recompute for models that don't support `cache_position`.
- `_try_kv_decode()` function — detects model dtype to avoid bfloat16/float32
  mismatches, resolves tokenizer from loader or AutoTokenizer, pre-fills cache
  on CPU before forge compilation.
- Bestiary `decode_note` field now records the method used per model
  ("StaticCache KV cache" vs "no KV cache — full recompute per step").

### Changed
- Decode results updated for all 5 stages — GPT-2 2.30→5.52 tok/s, OPT
  3.98→5.05 tok/s, Phi-2 1.48 tok/s (new), Falcon 3.30 tok/s (new),
  LLaMA-LoRA 2.86 tok/s (new), Gemma-LoRA 2.40 tok/s (new), and more.

---

## [1.5.0] — 2026-06-30

### Added
- **`scripts/bench_decode.py`** — dedicated LLM decode benchmark measuring
  TTFT, prefill tok/s, and decode tok/s for all compiled causal LMs.
  Subprocess isolation + tt-smi health check prevent hardware lockups.
- **Leaderboard columns** — TTFT, Prefill tok/s, Decode tok/s, Params (M)
  replace the old Infer p50 / Throughput columns in `docs/leaderboard.html`.
- 5 benchmark stages: Stage 1 (GPT-2, OPT), Stage 2 (Phi-2, BLOOM, CodeGen),
  Stage 3 (Falcon, Allam, LLaMA-LoRA, Gemma-LoRA), Stage 4 (Qwen 2.5,
  Phi-1 LoRA), Stage 5 (DeepCogito, DeepSeek Coder, frontier models).
- `params_m` field added to all benchmarked bestiary entries.
- `hf:` loader prefix for frontier HuggingFace models loaded without a
  tt-forge-models seed loader.

### Changed
- Bestiary `throughput_unit` relabeled from generic `tok/s` → `prefill_tok/s`
  for all 54 causal LM entries to prevent confusion with decode throughput.

---

## [1.4.0] — 2026-06-29

### Added
- **`scripts/install.sh`** — turn-key smart installer: hardware pre-check,
  hugepages, disk space, forge venv, XLA venv, mesh descriptor probe,
  tt-forge-models clone, stale-shm cleanup. Outputs color-coded summary table.
- **RAM/DRAM budget calculator** — skips models whose weights exceed available
  system RAM + per-chip DRAM; prevents OOM crashes at load time.
- **`scripts/setup-venvs.sh`** — minimal venv setup script for clean Ubuntu
  24.04 installs on Tenstorrent Blackhole hardware.
- Self-contained patches directory — tt-forge-models fixes applied at
  expedition startup without modifying upstream.
- `--ephemeral` / `--evict-failures` flags — evict HF weight cache after
  each model to reclaim disk space on small-storage machines.

### Changed
Image Classification with TT-Forge
affiliatedEnd-to-end image classification project using TT-Forge — compile and run a PyTorch classification model on Tenstorrent hardware with no kernel authoring required.
tensix-viz
affiliated★ featured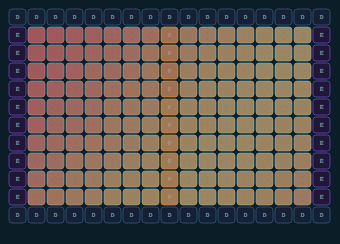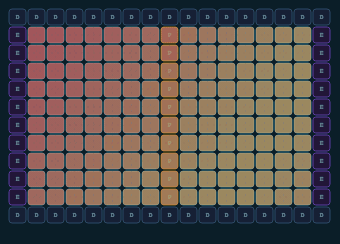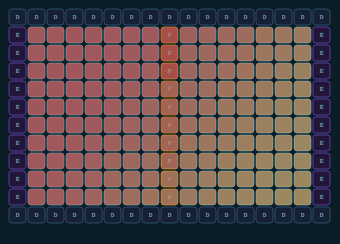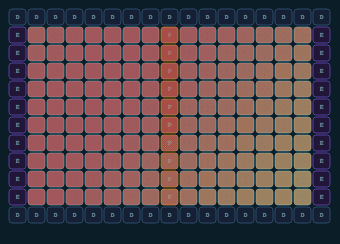
Hardware topology visualizer for Tenstorrent chips — from individual chip to full cluster. Interactive JavaScript visualization of Tensix core layout and NoC connections.
📋 Changelog
# Changelog

All notable changes to tensix-viz are documented here.

## [1.2.1] - 2026-08-20

### Fixed

- **The chip grid is centered within its canvas** (`src/chip.js`, `_computeLayout`).
  `_cellW`/`_cellH` are floored, so `cols * _cellW` is usually smaller than the
  drawable width; drawing from a fixed top-left `pad` piled all that leftover on
  the right and bottom, making the grid look shoved toward the top-left corner
  (visible in small multi-chip layouts). `_padX`/`_padY` now split the leftover
  slack evenly — `max(pad, floor((w - cellW*cols) / 2))` — so the grid sits
  centered, never narrower than the base pad on any edge. 86 tests green.

- **Idle rendering no longer flickers and is frame-rate independent** (`src/chip.js`, `_drawHeatmap`, `activate()` idle).
  Heatmap normalization now uses a floored, slowly-decaying reference scale, and the idle decay/pop maths use elapsed time so behavior is consistent across refresh rates.
  slack evenly — `max(pad, floor((w - cellW*cols) / 2))` — so the grid sits
  centered, never narrower than the base pad on any edge. 86 tests green.

## [1.1.2] - 2026-06-29

### Fixed

- **`TensixViz.autoInit()` is idempotent for `.tensix-viz-container` elements** (`src/chip.js`)
  1.1.1 made the `[data-viz]` path idempotent but left the legacy single-chip path unguarded. When
  `autoInit()` ran twice (the bundle's self-init plus an explicit host-page call), each
  `.tensix-viz-container` canvas received a second `TensixViz` instance — two animation loops drawing
  on one canvas, which renders as a doubled/overlapping grid. `TensixViz.autoInit()` now skips any
  container already initialized (`container._tensixViz`) and records the instance on it.

### Added

- **Responsive multi-chip canvas** (`tensix-viz.css`)
  `.tv-chip-wrapper canvas { max-width: 100%; height: auto; }` — card/system canvases (created
  without the `.tensix-viz-canvas` class) now scale to fit a narrow column instead of being clipped
  by `.tv-card`'s overflow. Previously this rule had to be patched in by downstream consumers.

## [1.1.1] - 2026-06-25

### Fixed

- **Animation player accepts both script schemas** (`src/chip.js` `_execStep`)
  The player dispatched on `step.step` and read `step.cores` only, so scripts authored with the
  alternate `{ action, coords }` schema ran zero steps — the Play button (and auto-play) appeared
  dead. `_execStep` now dispatches on `step.step || step.action` and falls back `coords → cores`,
  so blocks written in either schema animate.

- **`autoInit()` is idempotent for `[data-viz]` elements** (`src/index.js`)
  `autoInit()` can run more than once (the bundle's self-init plus an explicit call). For `card`
  and `system` vizzes — which append their render into the host element — the second run appended
  a duplicate set of chips. `autoInit()` now skips any element already initialized (`el._tensixViz`).

## [1.1.0] - 2026-06-09

### Fixed

- **Heatmap: non-tensix cells no longer painted by heat overlay**
tt-demo-maker
affiliated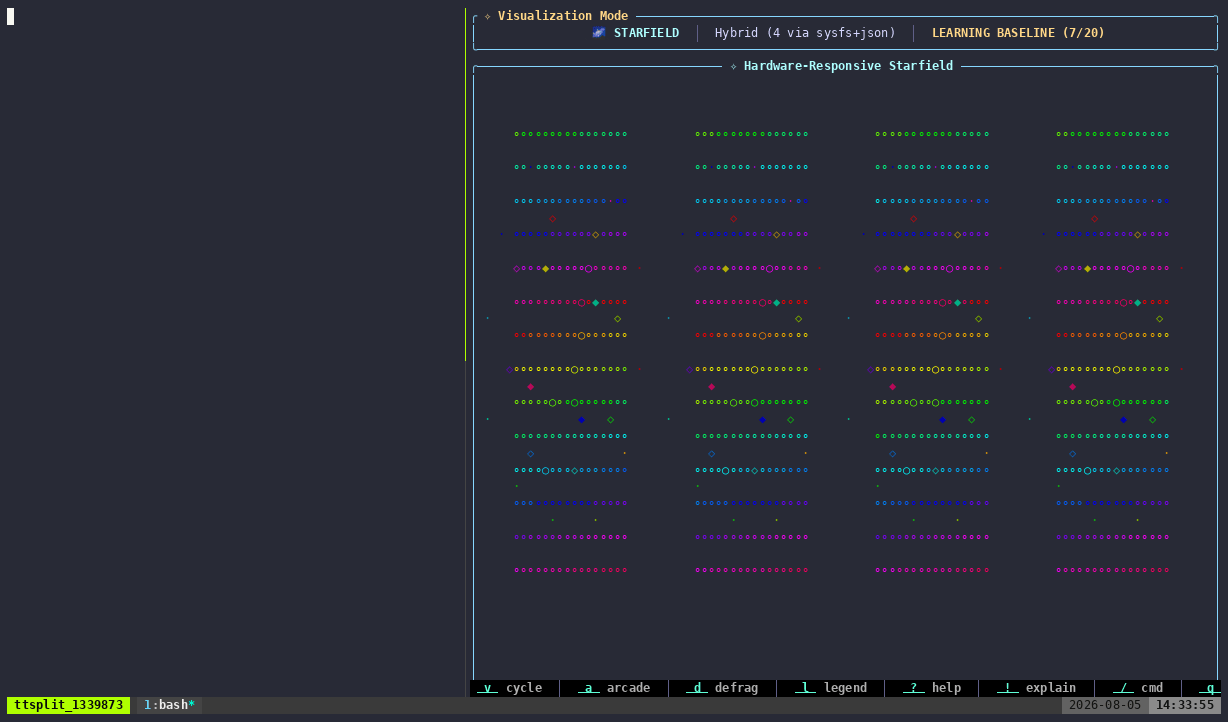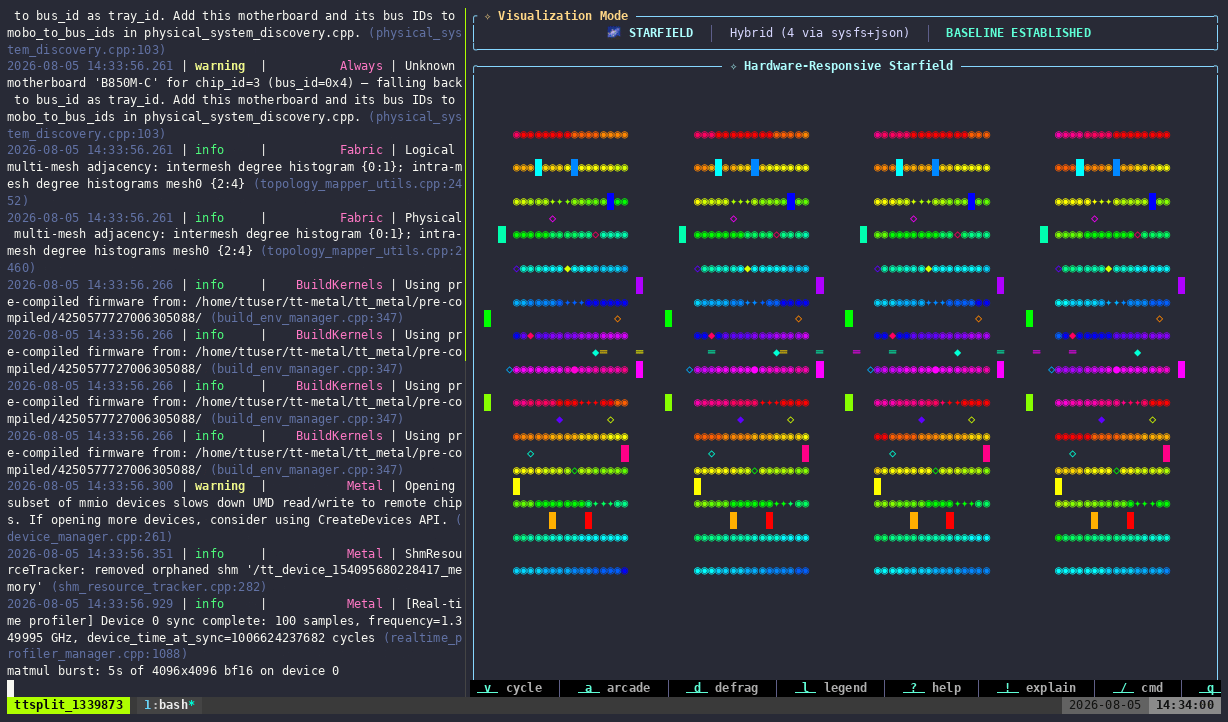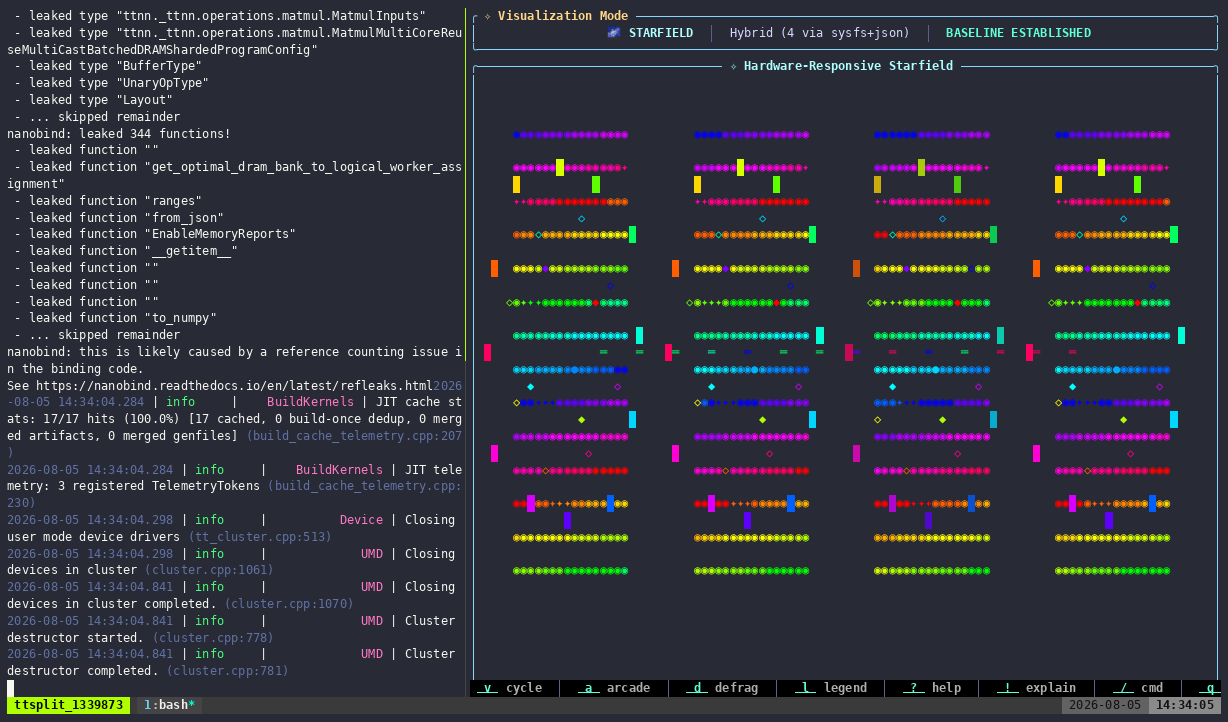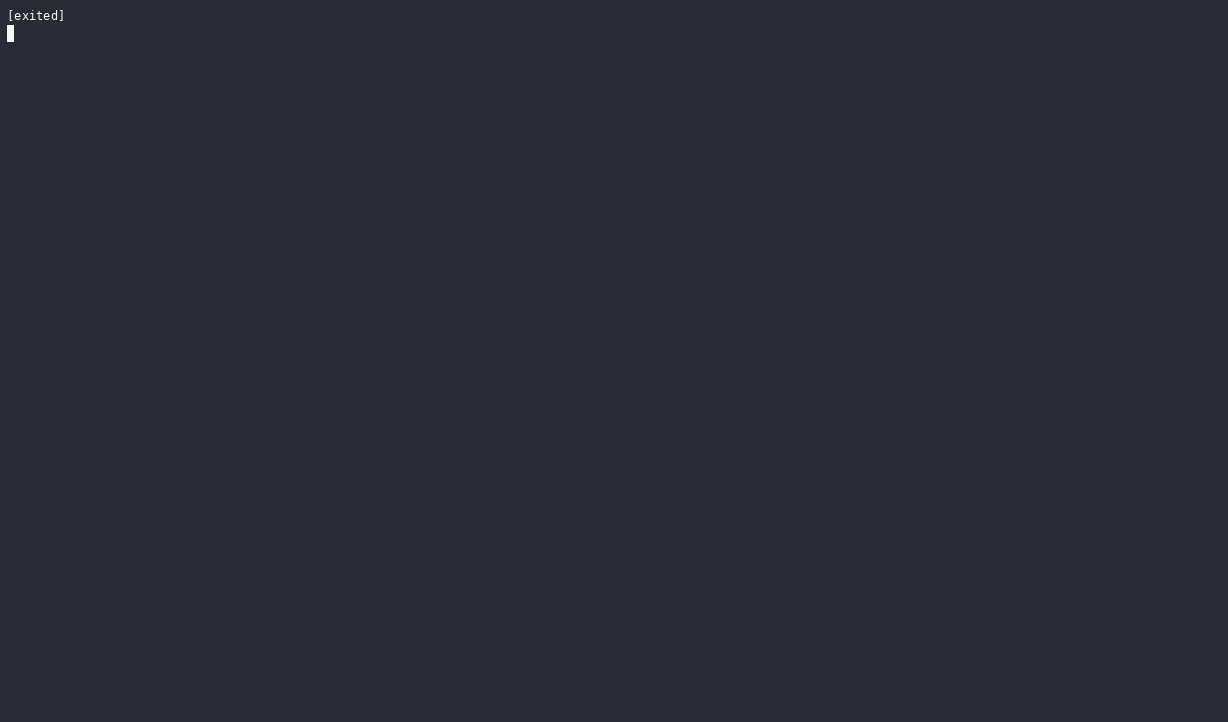
A project-agnostic toolkit for authoring demo recordings and draft posts from inside any project. Describe scenes in a small YAML manifest and it drives the terminal ballet — tmux, asciinema, VHS, ffmpeg and agg — into asciicast/GIF/MP4 footage plus a first-draft Markdown post pairing each directive with the reaction it caused. Rust orchestrator over bash capture primitives, with idle trimming, readiness gating, and a /tt-demo Claude skill that writes the manifest for you.
tt-gozer
affiliatedCooperative chip leasing for Tenstorrent boxes, so several agents — Claude Code sessions, aider, shell scripts, cron jobs — can share one machine without corrupting each other's runs. A lease records who is using which chips and why; the kernel's view of the devices is the tiebreaker when the two disagree. Standard-library Python, board-grain leases by default, and it ships Claude Code skills that teach agents to lease before they run.
tt-warp
affiliatedWarp terminal plugin for Tenstorrent — integrates hardware status, model management, and developer workflows directly into the Warp terminal.
Tensix Grid Playground
affiliatedInteractive browser-based visualizer of the Tenstorrent Tensix grid architecture. Explore the NoC, core layout, and dataflow patterns without hardware — a great companion for learning kernel programming.
Tenstorrent Cookbook: Conway's Game of Life
affiliatedTT-Metalium implementation of Conway's Game of Life as a cookbook recipe. Each generation is a full parallel kernel dispatch over the grid — a clean introduction to stateful compute on Tensix cores.
Tenstorrent Cookbook: Particle Life Simulator
affiliated★ featuredParticle Life simulation on Tenstorrent hardware — an emergent-behavior N-body system where simple attraction/repulsion rules between species produce complex lifelike patterns. Cookbook recipe demonstrating parallel N-body compute on Tensix.
tt-sim Lab
affiliatedA university teaching lab for TT-Metalium kernel programming on a virtual Tenstorrent chip — one-click GitHub Codespace, no silicon and nothing installed locally. The primary track (labs 00-06) points tt-metal straight at libttsim via TT_METAL_SIMULATOR and walks from elementwise add through NoC multicast to multi-core and multicast matmul, backed by a source-level matmul guide. An optional advanced track (labs 10-16) boots an Ubuntu guest under ttsim-qemu, loads tt-kmd, surfaces /dev/tenstorrent/0, and runs tt-metal through the full PCIe path.
CS Fundamentals on Tenstorrent Hardware
affiliated★ featuredSeven-module computer science curriculum taught on real Tenstorrent hardware. Covers RISC-V architecture, memory hierarchy, parallel computing, networks and NoC, synchronization, abstraction layers, and computational complexity — all grounded in what is physically happening on the chip.
Custom Model Training on Tenstorrent
affiliatedEight-lesson series covering the full custom training workflow on TT hardware: dataset fundamentals, configuration patterns, fine-tuning, multi-device distributed training, experiment tracking, model architecture basics, and training from scratch.
Tenstorrent Cookbook: Core Recipes
affiliatedThree hands-on TT-Metalium kernel recipes: a Mandelbrot fractal explorer, real-time audio signal processing pipeline, and custom image filter stack. Each recipe is a complete kernel project with full source in the lesson.
Exploring spectral element methods on the Tenstorrent RISC-V accelerator
affiliatedThe growing availability of commodity RISC-V hardware has sparked interest in its use for High Performance Computing (HPC), with PCIe accelerator cards offering a practical near-term pathway to adoption. The Tenstorrent Wormhole is one example, with dedicated vector and matrix units across 128 Tensix cores, and is widely available. In this paper, we explore porting the AX kernel of Nekbone, a widely used HPC mini-application derived from the Gordon Bell Prize-winning Nek5000 spectral element solver, onto the Wormhole accelerator.
nvtop
community★ featured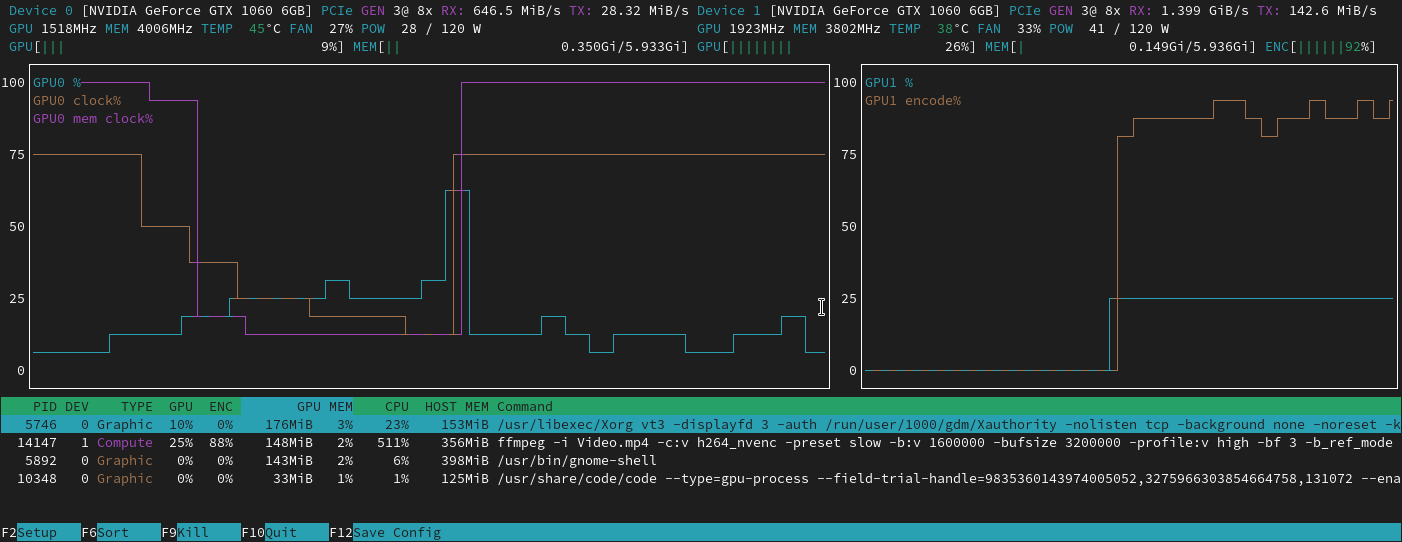
htop-style process monitor for GPUs and AI accelerators. Supports AMD, Apple, Huawei, Intel, NVIDIA, Qualcomm — and Tenstorrent. Real-time utilization, memory, and process info in a terminal UI.
dstack
community★ featured
Vendor-agnostic orchestration for training, inference, and agentic workloads across NVIDIA, AMD, TPU, and Tenstorrent on clouds, Kubernetes, and bare metal.
Booth
community★ featuredAn open-source CUDA, HIP, and Triton compiler with no LLVM anywhere in the path. Takes the same sources you would hand to nvcc, ROCm, or Triton's JIT and emits AMD RDNA 2/3/4 binaries, NVIDIA PTX, Tenstorrent Metalium C++, native RV32IM, or plain x86-64 — so a Triton matmul can run on a laptop that has never seen a GPU. Also reads a deliberate subset of MLIR (`func.func` plus the `arith` dialect) and Fortran `do concurrent` kernels via LFortran. Formerly BarraCUDA; renamed to honour Kathleen Booth.
📋 Changelog
Booth — Changelog
=================

## Booth 0.5.3

### Runtime

- #169: the runtime is split by where it runs, the `BC_ERR_*` codes no
  longer collide, and the examples and NVIDIA harness are built
  (Zane Hambly, 2026-08-23)


### Frontend

- variadic template parameter packs, several `.cu` files as separate
  translation units, `mma.sync` and `mfma` lowering, and an i1 that no
  longer strides by zero (Zane Hambly, 2026-09-03)

- `(a) + (b)` adds again; the parser treated any parenthesised identifier as a
  type name without asking whether it named one, so the left operand vanished
  into a cast with no diagnostic (Zane Hambly, 2026-09-03)

- the cast test is now the type name registry, so the registry has to be
  complete. Template type parameters, `using X = T` aliases and the type names
  sema resolves without a typedef (`size_t`, `uint32_t`, `float4` and the rest)
  all reach it. A compound literal through a typedef, `(pair){1, 2}`, parses
  for the first time, and `sizeof(name)` where the name is a type reads as a
  type rather than an expression (Zane Hambly, 2026-09-03)

- llama.cpp's ggml-cuda preprocesses, all 67 files; `#pragma once` is
  honoured, variadic and multi-line macro invocations expand, and an
  expansion too big for the output buffer is E053 rather than an
  unterminated buffer the lexer reads past (Zane Hambly, 2026-09-03)

- `kath --mlir` reads MLIR text, no LLVM in the path. Čertík's pure-C
  reader vendored under `src/mlir/vendor` (mlir 826b69c9, corec a160199d),
  reached only through `src/mlir/mlir_fe.c` (Zane Hambly, 2026-08-11)

- `src/mlir/lower.c` walks the parsed module into BIR: `func.func`, `return`,
  `arith.constant` and every arith binop, compare and conversion the reader
  classifies. From there it is the pipeline CUDA and Triton already use, and
  MLIR reaches all four backends. `--mlir --pp` reprints instead
  (Zane Hambly, 2026-08-11)

- an op outside the subset stops the lowering and names itself. Skipping it
  would leave a function that compiles and computes something else
  (Zane Hambly, 2026-08-11)

- five fixes to the vendored reader, all worth upstreaming, and four of them
  are `func.func` being unfinished where `tt.func` is not: `parser_init`
  renamed off Booth's own, `parser_error`'s `exit(1)` replaced by a
  `mlir_parse_fail()` the linker supplies, `func.func` binding its arguments
  before parsing the body rather than after, `func.func` accepting the
  `attributes` clause where MLIR actually writes it, and `arith.xori`,
  `shli` and `shrsi` added to `op_string_to_type`, which the printer could
  already write but the parser could not read back
  (Zane Hambly, 2026-08-11)

- `ml_parse` resets the reader's process-wide type interning, which upstream
  assumes one context per process. Without it a closed context left the next
  parse in freed memory (Zane Hambly, 2026-08-11)

- the Triton lowering records pool overflow through `bir_pfull`, which the C99
  one already did and it never has. I
tt-tiny
community★ featuredMinimal Python code to access and program the Tenstorrent Blackhole chip directly — George Hotz's exploration of TT hardware programmability with pointed commentary on the architecture.
zyx
community
A complete ML library and compiler in Rust — "from assembly to neural networks" — with a native Tenstorrent backend (src/backend/tenstorrent), autograd, custom kernels, multi-backend support, and Python bindings.
tt-twitch
communityA Tenstorrent Grayskull kernel written live on Twitch by George Hotz. 120-core grid demonstration of live kernel programming.
koyeb/tenstorrent-examples
communityExample applications and deployment configurations for running AI workloads on Tenstorrent hardware via Koyeb's cloud platform.
blackhole-py
communityPure Python driver for Tenstorrent Blackhole cards providing direct low-level hardware access without going through the full TT-Metal stack.
Tenstorrent Console Skill
communityAn agent skill (SKILL.md) that teaches Claude Code, Codex, and the Agent SDK how to drive the console.tenstorrent.com inference API: OpenAI-compatible chat with DeepSeek-R1 and Qwen3, async image jobs, and Wan 2.2 text-to-video. Ships runnable curl examples and a mock-curl test harness; documentation is bilingual Korean/English.
tenstorrent-tiny-examples
communitySimple C++ kernel experiments on a GraySkull e75 chip. Hands-on examples for learning the TT-Metal programming model at the metal level.
ttnn-helloworld-cpp
communityMinimal working example of using Tenstorrent TTNN in C++. The simplest possible starting point for C++ developers targeting TT hardware with TTNN.
tt-sim
community★ featuredCommunity-built Tenstorrent architecture simulator written in Python. Runs without hardware — useful for researchers and developers exploring the Tensix architecture offline.
triton-tenstorrent
community★ featuredOpenAI Triton compiler plugin for Tenstorrent hardware. Write Triton kernels and target Tensix cores — brings the Triton ML kernel ecosystem to TT devices.
tt-iree
community★ featuredIREE (Intermediate Representation Execution Environment) ML compiler ported to Tenstorrent AI accelerators. Brings the IREE compiler ecosystem to TT hardware.
TT-GoL
community
Conway's Game of Life implemented on Tenstorrent hardware using TT-Metal kernels.
tenstorrent.nix
communityNix flake packaging the Tenstorrent software stack for NixOS and Nix users. Reproducible, declarative installation of TT drivers and tools.
Tenstorrent Simulator Playground
community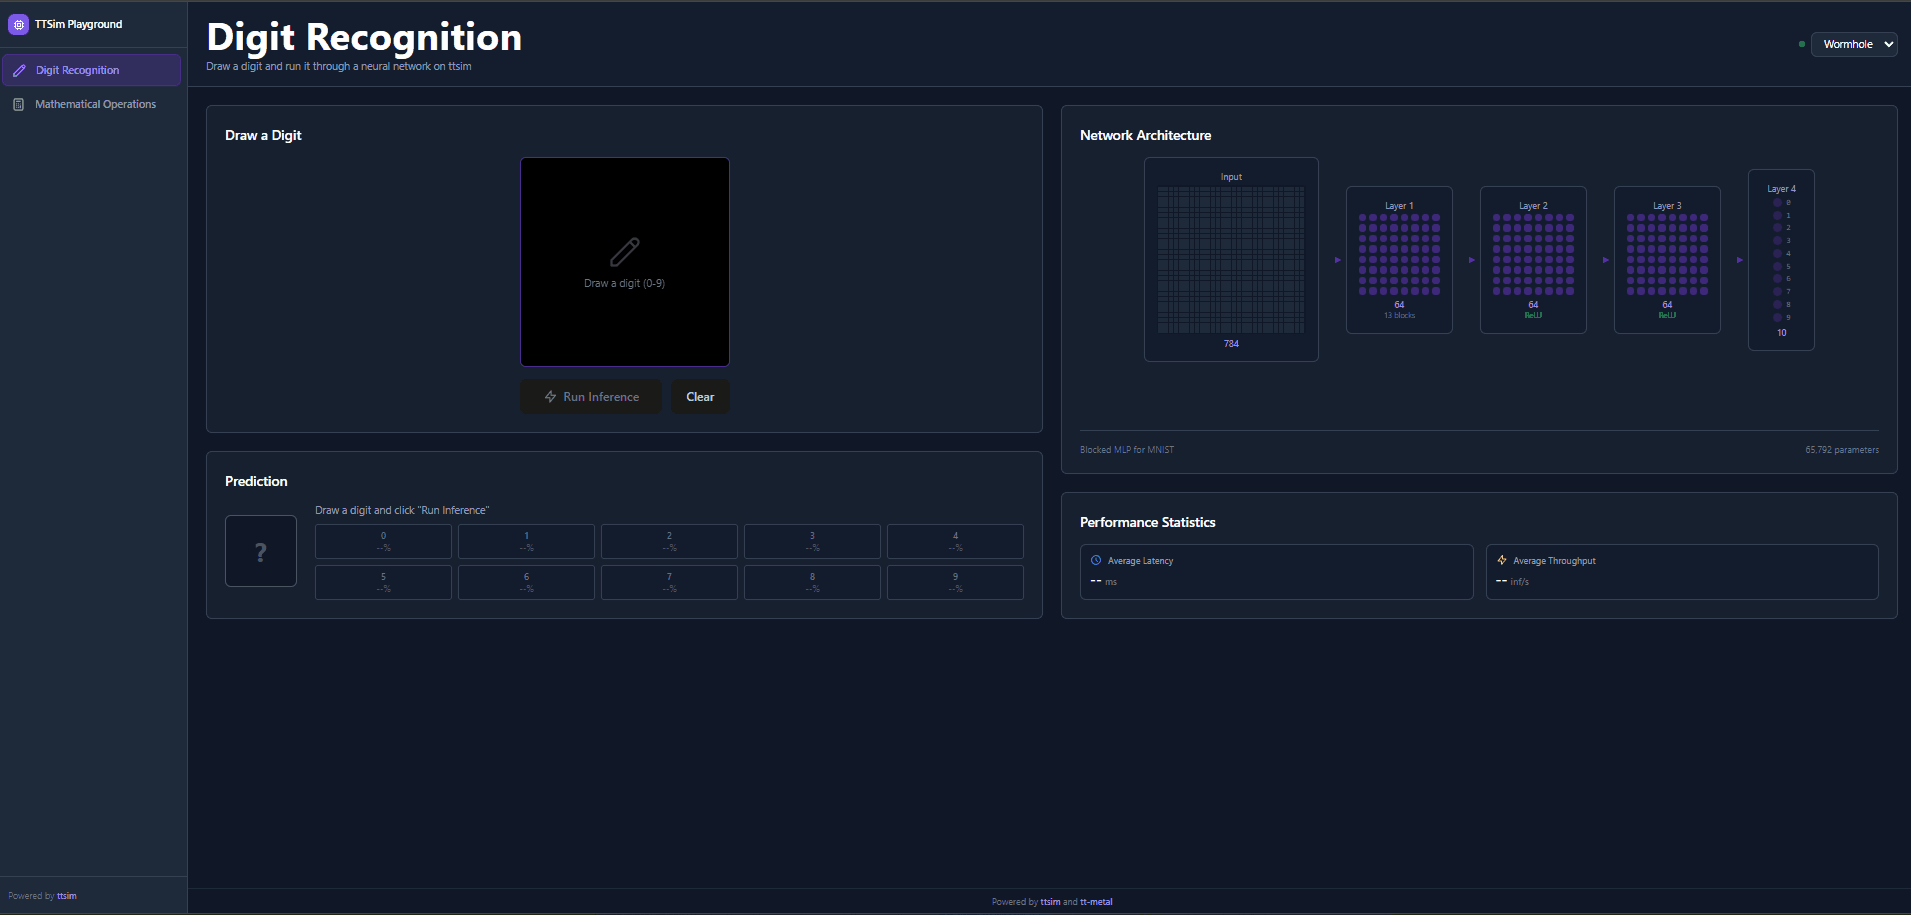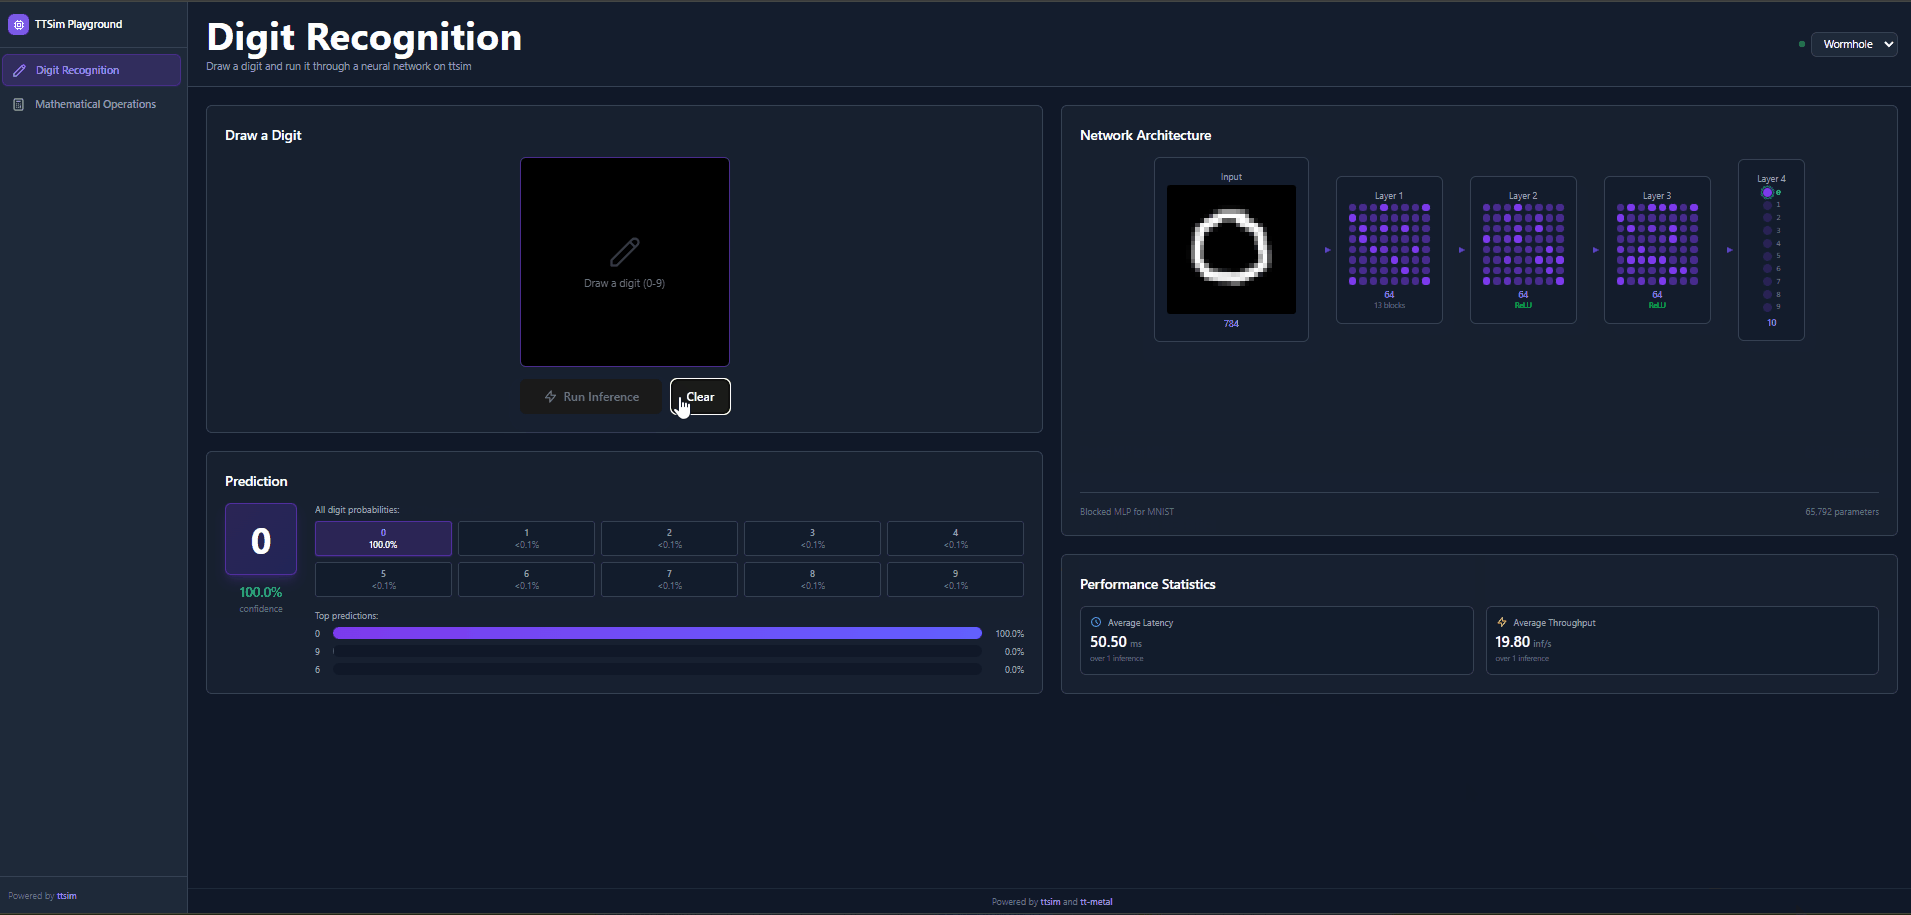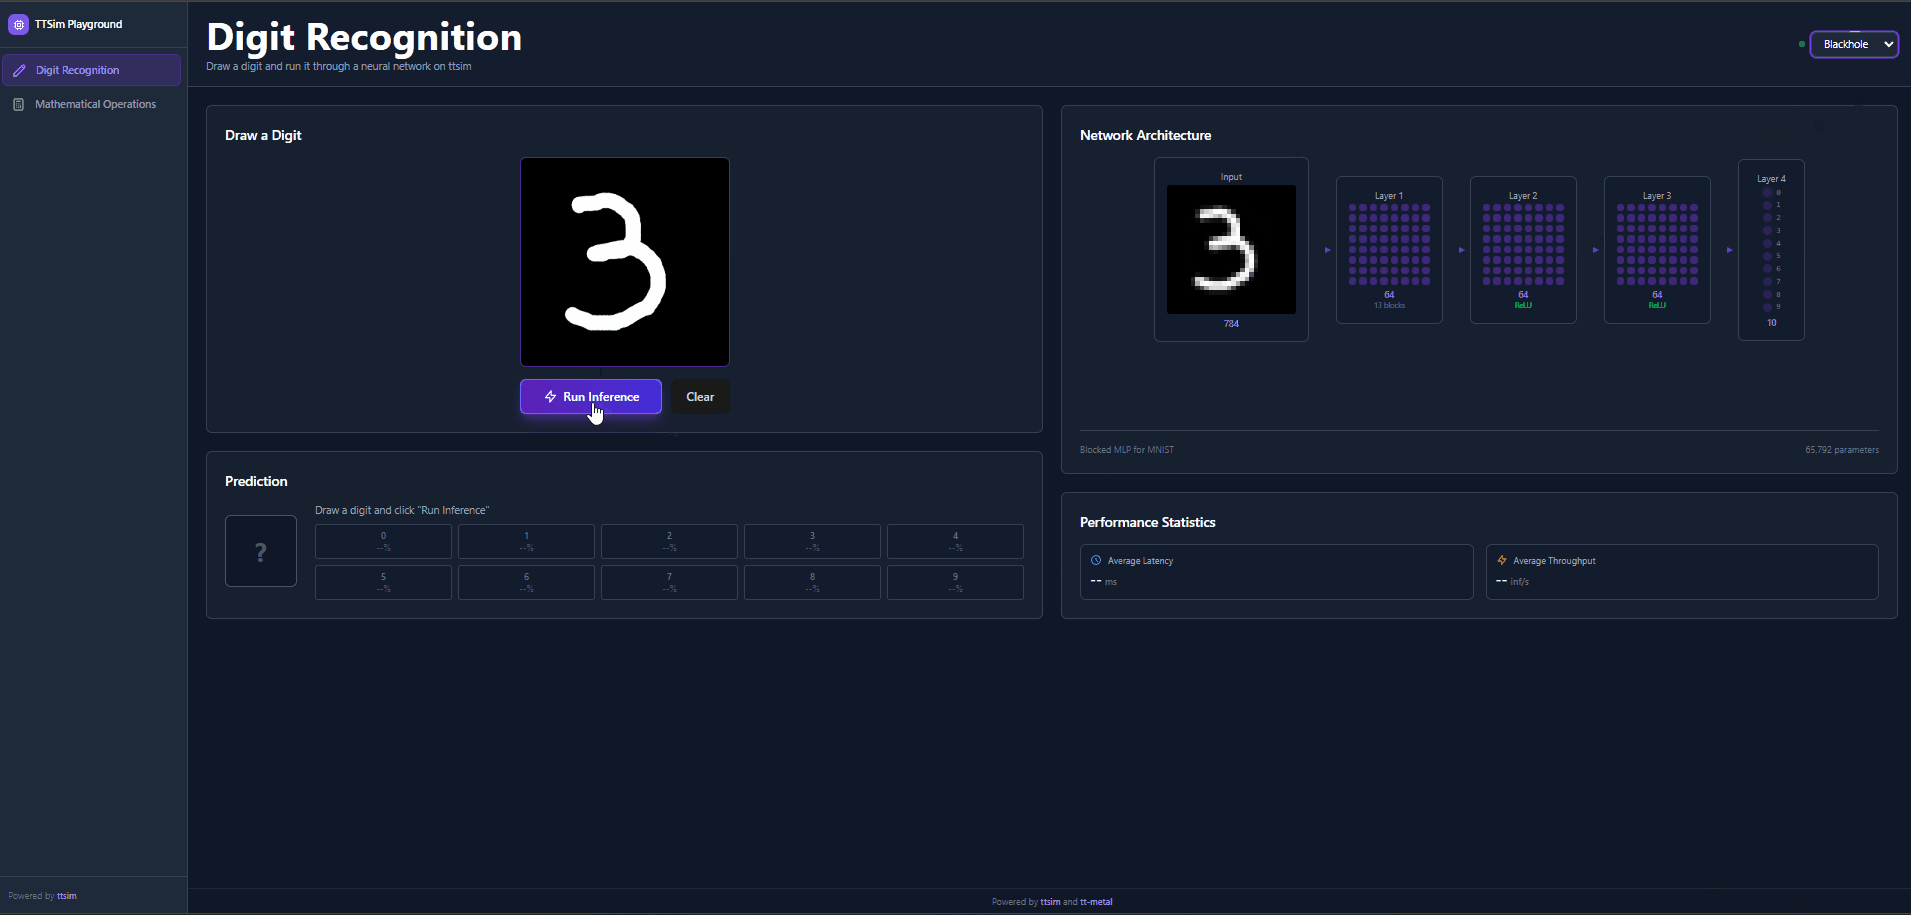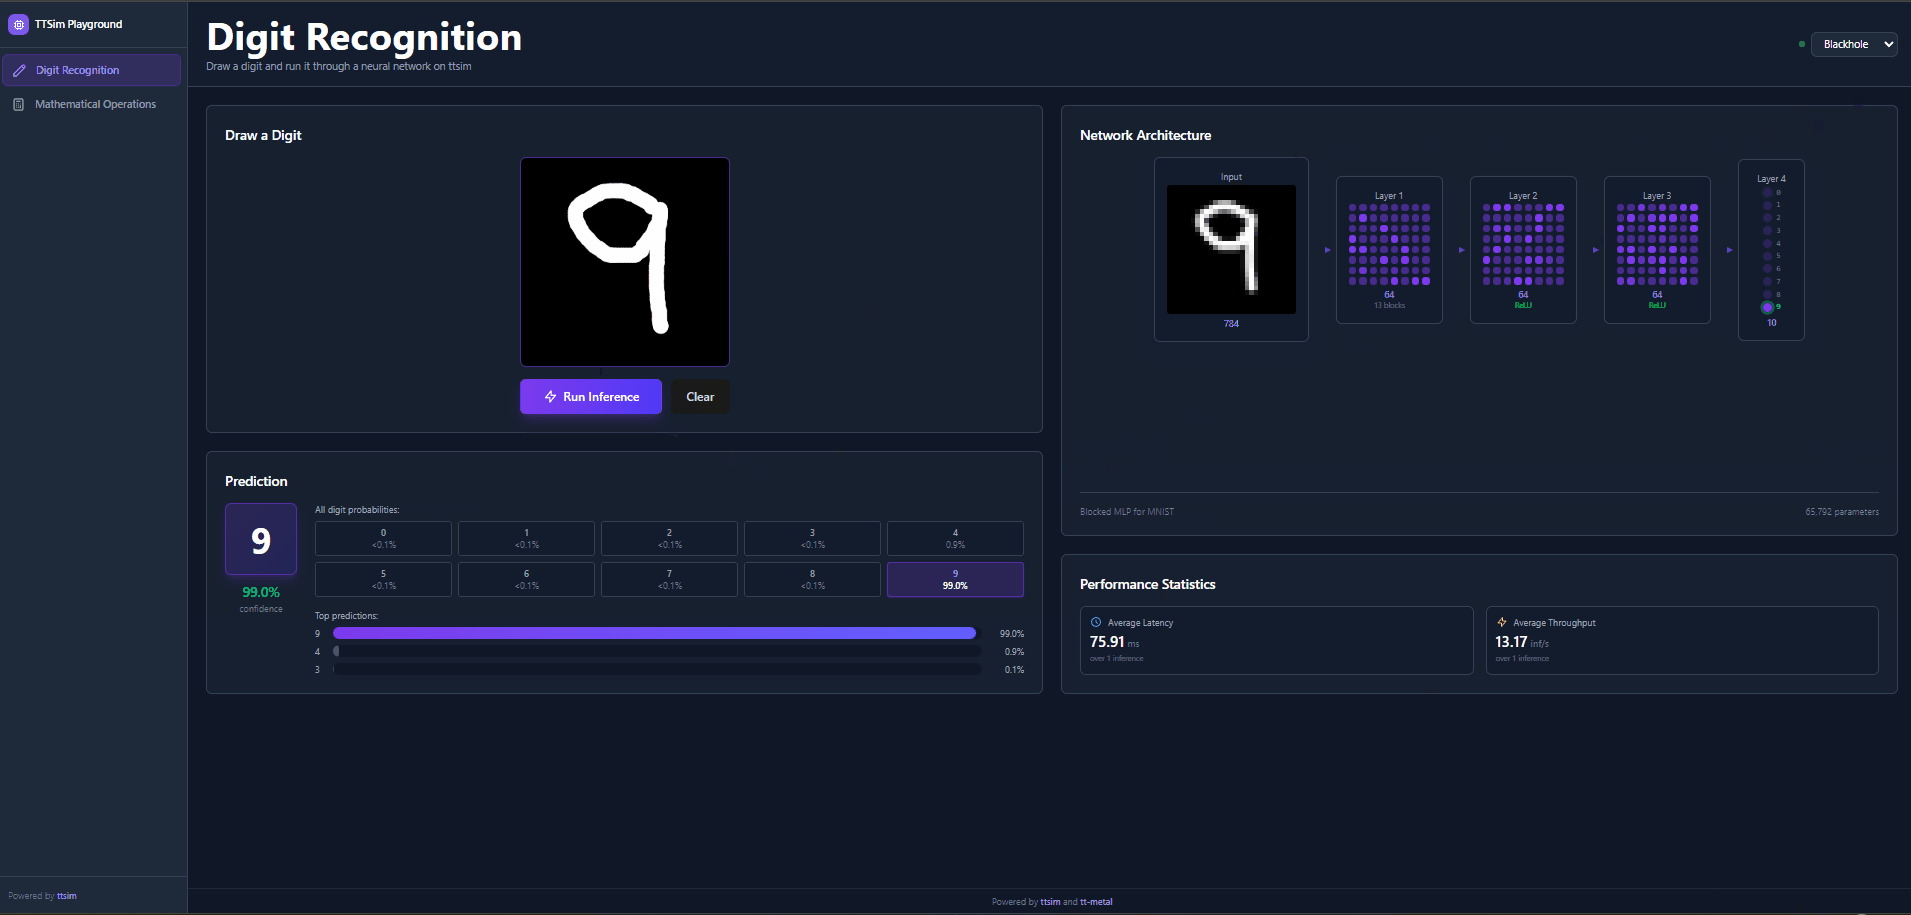
A web playground that runs real TTNN operations on the ttsim hardware simulator — no card required. Switch between Wormhole and Blackhole, run elementwise/activation/matmul ops or a small MLP, draw a digit and classify it with a trained MNIST net, then sweep parameters in 1D or 2D and read latency, throughput, and memory back as line charts, 3D surfaces, and heatmaps.
📋 Changelog
# Changelog

All notable changes to the Tenstorrent Simulator Playground will be documented in this file.

The format is based on [Keep a Changelog](https://keepachangelog.com/en/1.1.0/),
and this project adheres to [Semantic Versioning](https://semver.org/spec/v2.0.0.html).

## [1.4.0] - 2026-01-27

### Added

- **Updated Demo Assets**
  - New digit recognition demo GIF with improved visualization

### Fixed

- **Docker Desktop Compatibility**
  - Fixed 500 Internal Server Error when running digit recognition in Docker containers
  - Implemented native Docker inference that runs Python directly instead of attempting WSL calls
  - Proper environment variable handling for containerized ttsim execution
  - Automatic SOC descriptor selection for Wormhole/Blackhole chips in Docker

## [1.3.0] - 2026-01-27

### Added

- **Enhanced Network Visualization**
  - 28×28 pixel grid visualization for input layer displaying the actual drawn digit
  - Vertical output column showing all 10 digit classes (0-9) with labels
  - Green ring highlight indicator for the predicted digit
  - Pixel data pass-through from drawing canvas to network visualization

### Changed

- **Performance Statistics Display**
  - Average throughput now displays with 2 decimal places for precision

## [1.2.0] - 2026-01-27

### Added

- **Digit Recognition Page**
  - Interactive drawing canvas for handwritten digit input (0-9)
  - Real-time MNIST neural network inference on Tenstorrent simulator
  - Network architecture visualization showing layer activations and connections
  - Performance statistics tracking (average latency and throughput)
  - Confidence display with horizontal bar chart for all 10 digit classes
  - Trained 2-layer MLP model (784→128→10) achieving ~98% accuracy
  - New digit recognition API endpoints (`/api/digit/predict`, `/api/digit/model-info`)

- **Simple 2-Layer MLP Operation**
  - Configurable neural network architecture editor
  - Interactive network diagram showing input, hidden, and output layers
  - Configurable sizes: input (32/64), hidden (32/64), output (16/32/64), batch (16/32/64)
  - Parameter count display with real-time updates
  - Visual representation of layer connections and ReLU activation

- **Matrix Multiplication Operation**
  - Support for 32×32 and 64×64 matrix operations
  - Optimized for TTNN performance benchmarking
  - Added matrix multiply icon to operation selector

- **React Router Integration**
  - Separate pages for Digit Recognition (/) and Mathematical Operations (/math-operations)
  - Clean URL structure with browser navigation support
  - Navigation sidebar with page links

### Changed

- **UI Redesign**
  - Non-collapsible sidebar with fixed width (256px) for better text display
  - Simplified branding: "TTSim Playground" with chip icon
  - Mathematical Operations page header now matches Digit Recognition style
  - Operation selector reorganized into 4×3 grid by category
  - Updated icons for subtract (circle with line) and matrix
ttMandelbrot
communityMandelbrot Set fractal renderer running on Tenstorrent hardware. A classic demo showcasing parallel compute on Tensix cores.
tt-tutorial (HPC)
communityTutorial on Tenstorrent hardware for HPC researchers from the RISC-V Testbed project at Edinburgh/EPCC. Covers Wormhole from an HPC parallel-computing perspective.
TT-Metal Mini Template
communityMinimal working CMake project template for starting a new TT-Metal project from scratch. Good starting point for community kernel development.
tenstorrent-cli
communityA TypeScript/Bun terminal client for console.tenstorrent.com. Opens a chat REPL across DeepSeek-R1, Qwen3-32B, Qwen3-VL, and Gemma, with slash commands that submit image, Wan 2.2 video, TTS, and STT jobs, poll them, and save the results under ./output. Reads its API key only from the TENSTORRENT_KEY environment variable — never from disk.
ttPEAK
communityclpeak-style peak-performance benchmark for Tenstorrent devices using TT-Metalium. Measures theoretical peak throughput across operations — useful for hardware characterization.
Unofficial Blackhole Documentation
communityUnofficial documentation for the Blackhole P100A / P150, assembled from reverse-engineering, disassembly, and hands-on experiment. Walks from a self-contained intro through chip architecture (NoC, Tensix tiles, RISC-V cores, L1, memory map), the 3-kernel matmul model, SFPI kernel writing, circular-buffer dataflow, the JIT build and dispatch pipeline, firmware boot sequence, and multi-host scaling. The author notes most pages were drafted by coding agents, with a `human/` folder that is explicitly hand-written.
current
communityHigh-level parallel programming framework for Tenstorrent accelerators, abstracting TT-Metal into a research-oriented programming model for parallel computation.
ttVecAdd
communityMinimal vector-addition example on Tenstorrent devices using TT-Metalium. A clean hello-world for the TT-Metal kernel programming model in C++.
bhx
community★ featuredBoot stock Linux cloud images on the SiFive X280 RISC-V cores inside Tenstorrent Blackhole AI accelerators. Per-card Rust daemon with virtio-mmio block/net/console and U-Boot/EFI support.
📋 Changelog
# Changelog

Notable changes per release. Format loosely follows
[Keep a Changelog](https://keepachangelog.com/en/1.1.0/);
this project does not yet promise SemVer compatibility on the RPC
wire format or library API surface (we're not 1.0).

## Unreleased

V2 virtio-dispatch redesign. The kick ring + completion ring + host-
side throttle that grew up around #184 are gone; in their place is a
per-(slot, queue) dirty bitmap in BRISC L1. The bitmap is level-
sensitive — guest QUEUE_NOTIFY storms coalesce into a single set
byte, so the dispatch path can't fall behind under any burst. Wire
incompatible with 0.9.0; `TENSIX_PROTOCOL_VERSION` bumped 4 → 5.

### Added

- **V2 dirty-bitmap dispatch** (`#187` / `#188` / `#189`). BRISC
  writes 1 to `CTRL_OFF_DIRTY[slot][queue]` on every guest
  QUEUE_NOTIFY; the daemon's `Dispatcher` clears the byte and
  dispatches each pass. Replaces V1's 2048-entry kick ring +
  daemon-side `consume_kick_ring_pass` consumer.
- **V2 processed-cursor table** at `CTRL_OFF_PROCESSED`. Daemon
  publishes `used.idx` after each successful dispatch so
  warm-resume reads cursors directly without re-probing guest
  DRAM.
- **`bhx_notify_events_total`, `bhx_dispatch_passes_total`,
  `bhx_dispatch_queues_drained`** Prometheus counters surface the
  new dispatch path. The burst regression test (`scripts/
  soak_virtio_burst.py`) asserts `dispatch_passes_total > 0` to
  confirm the workload reached the new path.
- **`scripts/soak_virtio_burst.py`** — multi-queue burst regression
  test. Sustains 16-job direct=1 fio randwrite + a tight
  `printf` loop to `/dev/console`, samples `/metrics` every 1 s,
  and verifies the daemon log contains zero
  `kick.*drop|rescue|throttle.*ENGAGE` matches.
- **`DaemonState.chip_reset_this_session`** flag — gates
  `maybe_opportunistic_reset_board` so 4-way parallel cold boots
  reset the chip exactly once, not once per L2CPU. Without this
  the second-and-later resets blip the chip while earlier-booted
  L2CPUs hold mmap pages, SIGBUSing their workers.
- **`Dispatcher` (was `KickPoller`)** with documented testability
  seam (`CtrlL1Access` trait); `drain_dirty_bitmap` is unit-tested
  against an in-memory L1 fake covering all five visit/clear
  semantics cases plus the address-formula pins.

### Changed

- **`KickPoller` → `Dispatcher`**, plus `kick_poller` → `dispatcher`
  field on `DaemonState`, `tensix-kick-poller` → `tensix-dispatcher`
  thread name, `[kick-poller]` → `[dispatcher]` log tag,
  `kicks_consumed` → `dispatches_total`,
  `last_kick_slot_queue` → `last_dispatch_slot_queue`. Pure
  rename; no behavior change. V1 vocabulary scrubbed throughout
  the codebase (firmware, daemon, scripts, docs).
- **`CTRL_SIZE` shrinks 36 KiB → 4 KiB**. V2 footprint is ~1.5 KiB;
  the rest is reserved for future fields.
- **Stats-page offsets repacked** — V1 `STATS_OFF_KICK_DROPS`,
  `STATS_OFF_COMPL_EVENTS`, `STATS_OFF_LAST_COMPL` retired with
  V1 (#190); deprecated PRECAP / BLINDCAP / POSTCAP slots dropp
tt-model-bringup
communityDirect TT-Metal bringup of modern open-weight LLMs on Blackhole P150 — hand-written compute graphs with no PJRT and no JAX. Covers Qwen3.6-27B, Qwen3.6-35B-A3B MoE, Gemma 4 12B, and Nemotron-3 Nano 30B-A3B, plus a zoo of single-chip Llama / Qwen2.5 / SmolLM ports, backed by custom fused `owned_*` kernels, a continuous-batching engine, an OpenAI-compatible HTTP server, and a wiki documenting each design decision.
ttas
communityttas is a hacker-friendly assembler/disassembler for Tensix on Wormhole. It turns assembly into the exact 32-bit words the hardware runs, and turns binaries back into readable instructions using the same shared instruction table.
ttperf
communityA CLI wrapper that turns TT-Metal performance profiling into one command. Runs a pytest target under Tenstorrent's profiler, streams progress live, then parses the resulting CSV and reports total device kernel duration. Supports profiling by operation name (`ttperf add`) as well as by test path, and installs from PyPI.
📋 Changelog
# Changelog

All notable changes to this project will be documented in this file.

The format is based on [Keep a Changelog](https://keepachangelog.com/en/1.0.0/),
and this project adheres to [Semantic Versioning](https://semver.org/spec/v2.0.0.html).

## [0.1.6] - 2025-01-14

### Added
- **Memory Configuration Support**: New command-line options for tensor memory configuration
- `--memory-config CONFIG`: General option with choices `[dram, l1]`
- `--dram`: Shortcut flag for DRAM memory (default)
- `--l1`: Shortcut flag for L1 memory
- Memory configuration extraction from CSV profiler output
- Memory config display in test result summaries

### Changed
- **Default tensor shape reduced from `[1, 1, 1024, 1024]` to `[1, 1, 32, 32]` for better performance**
- Enhanced `create_test_tensor()` function to accept memory_config parameter
- Updated all `ttnn.from_torch()` calls to use memory_config parameter
- Improved CSV extraction to read memory configuration from profiler output
- Enhanced debug output to show memory configuration

### Technical
- Added `validate_memory_config()` function with alias support
- Extended environment variable system with `TTPERF_CUSTOM_MEMORY_CONFIG`
- Updated operation_configs.json to include memory_config field
- Enhanced test file configuration parsing to handle memory settings
- Improved result reporting to include memory configuration details

## [0.1.4] - 2025-01-14

### Changed
- **Major Improvement**: Configuration extraction now reads from CSV profiler output instead of parsing text with regex
- Replaced 50+ complex regex patterns with structured CSV data parsing
- Enhanced `extract_test_config_and_status()` function to prioritize CSV data over text parsing
- Added new `extract_config_from_csv()` function for reliable configuration extraction

### Fixed
- More accurate shape, dtype, and layout detection from profiler results
- Improved reliability of configuration reporting in test summaries
- Better handling of tensor dimension parsing (e.g., "32[32]" format)

### Technical
- CSV-based extraction provides structured, consistent data vs. unreliable text parsing
- Maintains backward compatibility with text parsing as fallback
- Cleaner, more maintainable codebase with reduced complexity

## [0.1.0] - 2025-07-14

### Added
- Initial release of ttperf CLI tool
- Support for profiling TT-Metal tests with pytest
- Automatic CSV path extraction from profiler output
- Device kernel duration calculation
- Real-time output streaming
- Flexible command-line argument parsing
- Support for named profiles
- Comprehensive error handling

### Features
- Simple CLI interface: `ttperf [name] [pytest] <test_path>`
- Automatic detection of test files and paths
- Integration with TT-Metal profiler tools
- CSV parsing for performance metrics
- Real-time progress monitoring

### Dependencies
- pandas for CSV processing
- Python 3.7+ support
- TT-Metal development environment

## [Unreleased]

### Planned
- Enhanced error messages

##
tt-tutorial (Korean)
communityComprehensive tutorials for the Tenstorrent software stack in Korean. Jupyter notebooks covering the full developer path from hardware setup to model inference.
ttRoPE
communityA GGML-formatted rotary positional embedding (RoPE) implementation for Tenstorrent hardware — one of the operator building blocks behind the community effort to give llama.cpp a Metalium backend.
Collective Operations on Wormhole n150 (Sapienza University of Rome)
communityMaster's thesis implementing and benchmarking five allreduce algorithms (Swing, Recursive Doubling, Bandwidth Optimal, Latency Optimal, Shared Memory) on the Wormhole n150. Bandwidth Optimal achieved best performance, approaching within 2× of theoretical optimal.
libtt-metal-cxx
communityRust crate that exposes the TT-Metal host API through a C++ bridge via cxx.rs — covering device management, program/kernel creation (from source file or inline string), circular buffers, semaphores, runtime arguments, sharded buffers, and MeshDevice workflows, with hardware-backed integration tests.
ttWKV7
communityA standalone tt-metal demo and test bench for the RWKV-7 (WKV7) state recurrence on Wormhole, built with a GGML backend in mind. Two compute kernels cover the domain: a chunked-parallel DPLR matmul path for any sequence length with on-chip chunk carry, and a sequential per-token decode path for L <= 32 that is faster for large-batch token generation. The host runner validates both against a CPU oracle by PCC/NMSE and benchmarks them over a sequence/batch grid.
tt-monitor
community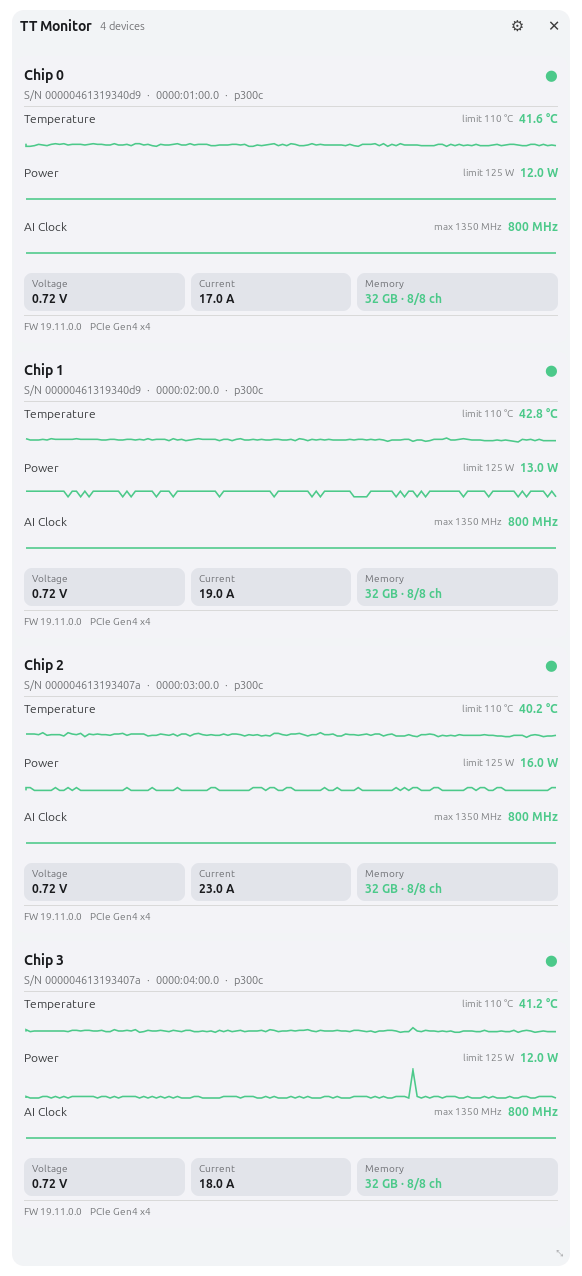
A translucent, undecorated desktop widget showing live per-chip telemetry for Tenstorrent accelerators: temperature and power sparklines against the card's thermal and TDP limits, AI clock, voltage, current, DRAM channel training and ECC error counts, PCIe link generation/width, and board identity. Reads hardware directly through luwen over /dev/tenstorrent — no Python, no tt-smi subprocess, and no root.
tetsuh/tt-metal-community-distro-matrix
community
A compatibility guardrail that continuously monitors whether [tt-metal](https://github.com/tenstorrent/tt-metal) and the official [tt-installer](https://github.com/tenstorrent/tt-installer) build successfully on community Linux distributions that are not part of Tenstorrent's official CI.
tt-splat — matrix-native 3D Gaussian Splatting on Blackhole
community
3D Gaussian Splatting rewritten to run on the matrix engine: a polynomial splat and order-independent weighted-sum blending replace exp and depth-sorted alpha, so the pipeline becomes GEMM → activation → GEMM. Renderer + trainer, trained device-resident on a Blackhole p150a.
ttPseudoRowMajor
communityA small TTNN-facing C++ library (ttprm) for running view-shaped tensor work without first materializing the view in DRAM. Targets Tenstorrent TILE tensors and uses cached device operations to gather/scatter through layout views.
tt-finetune
communityParameter-efficient fine-tuning — LoRA, rsLoRA, LoRA+, DoRA, and IA3 — on a single Blackhole P150a, behind a Hugging Face/PEFT-style trainer API. Ships as a self-contained Linux wheel bundling the TT-XLA/PJRT plugin, TTNN, and TT-Metal user-space libraries, so no source checkout, Docker, or PYTHONPATH setup is required. Includes a static planner that reports memory admission before you compile, deterministic checkpoint/resume, and standard PEFT adapter export.
2 previous releases
libtt
communityA Bazel-built PJRT plugin (libtt.so) providing an XLA backend for Tenstorrent devices. Bundles the tt-xla PJRT implementation with tt-mlir and tt-metal into a single shared object so JAX code runs on Tenstorrent hardware, with patches so sglang-jax works out of the box.
tt-tinygrad
communityA Tenstorrent backend for tinygrad that targets TT-Lang rather than raw tt-metal: a Renderer classifies each UOp kernel graph as matmul, reduce, or elementwise and emits ttl.math.* Python source, and a Compiled device parses the rendered kernel's contract, materializes ttnn tensors from host buffers, and calls it in-process. Proof of concept — 110 pass / 13 xfail across 125 cases on a QuietBox, covering fused matmul, reductions, softmax, layernorm, and attention chains, on top of a three-line patch to upstream tinygrad.
Inside the Tenstorrent Chips: Grayskull, Wormhole, Blackhole, and Galaxy
communityA long third-party walkthrough of the Tenstorrent lineup — core architecture, per-product specs and pricing, and what the published benchmarks against NVIDIA and AMD actually support. Notable for its candour: it states plainly that independent third-party benchmarks remain sparse and flags firmware changes that reduced earlier performance claims. Part 4 of a six-part series on inference hardware.
A Gentle Guide: Tenstorrent Card on Arch Linux with Metalium
communityStep-by-step guide to getting a Tenstorrent card running on Arch Linux with the full Metalium stack. Practical troubleshooting from someone who did it the hard way first.
Thoughts and Logs After Messing with Tenstorrent Grayskull
communityHonest field notes from getting a Grayskull card running and writing first Metalium kernels. Covers setup pitfalls, processor hangs, memory protection quirks, and what makes Metalium compelling despite early rough edges.
Programming Tenstorrent Processors
community★ featuredDeep-dive into the Tenstorrent architecture and Metalium programming model — circular buffers, kernel synchronization, NoC routing, and where the footguns are. The honest guide to thinking in Tensix.
Tenstorrent Architecture — W&M CSCI654 Advanced Computer Architecture
communityLecture 20 from William & Mary's graduate Computer Architecture course. Frames Tenstorrent in the landscape between GPUs and TPUs, draws comparisons to Cerebras and SambaNova, then dives deep into the Wormhole chip and Tensix core: the 5 RISC-V core design, SFPU, NoC, and dataflow execution model.
Tensix Field Guide
communityA ten-chapter, plain-English tour of Tenstorrent's Tensix architecture written for someone who knows what a CPU and a GPU are and nothing else: the chip-level grid and NoC, the five RISC-V baby cores, the matrix engine and its LoFi/HiFi fidelity trade-off, the SFPU, L1 and circular buffers, and why everything is 32x32 tile-shaped. The goal is to get a newcomer to the point of reading tt-metal kernel code in one sitting. Self-described draft; every claim traces back to tt-metal tech reports, tt-llk docs, or METALIUM_GUIDE.
Tenstorrent SFPU Kernel Series — Jason Davies
community★ featuredSponsored series of deep technical articles on implementing optimal SFPU kernels for the Tenstorrent Wormhole and Blackhole vector units. Covers where, typecasting, 16/32-bit integer multiplication, cube root, and accurate sin/cos/tan — with cycle counts, assembly walkthroughs, and Blackhole vs Wormhole comparisons throughout.
tt-rqm-kernels
communityStructured quaternion, rotor, and phase-aware tensor kernels on ordinary floating-point tensors, plus StructuredBench. Includes CPU/PyTorch references, simulator and emulator paths, and reproducible Wormhole/N300 evidence for quaternion multiply (`qmul`), fused SU(2) composition, and H2A Hamiltonian lowering.
tt-wavelet
communityOne-level FP32 lifting wavelet transforms (LWT) on Wormhole and Blackhole, shipped as a TTNN-linked op library plus standalone `lwt`, `ilwt`, `lwt_2d`, and `ilwt_2d` binaries and a benchmark harness. Builds the whole local stack — TT-Metal, the TTNN Python bindings, and ttnn-wavelet — against the TT-Metal revision pinned in its submodule.
Attention in SRAM on Tenstorrent Grayskull
communityA fused kernel for the Grayskull architecture implementing Transformer self-attention entirely within SRAM. Combines matrix multiply, attention score scaling, and Softmax without DRAM accesses, achieving significant speedups over non-fused implementations.
Exploring Fast Fourier Transforms on the Tenstorrent Wormhole
communityPorts the Cooley-Tukey FFT algorithm to the Wormhole n300 RISC-V accelerator. The Wormhole draws 8× less power and consumes 2.8× less energy than a 24-core Xeon Platinum for a 2D FFT. ISC 2025.
Assessing Tenstorrent Grayskull RISC-V MatMul Acceleration for LLMs
communityEvaluates the Tenstorrent Grayskull e75 RISC-V accelerator for matrix multiplication at reduced numerical precision (BFP8 and LoFi), a fundamental kernel in LLM inference computation.
Porting Strategies for Gravitational N-Body Simulations on Tenstorrent Wormhole
communityEvaluates three strategies for scaling an N-body code across multiple Tenstorrent Wormhole accelerators. Builds on the established performance of single-card N-body work to explore parallelism via the on-chip NoC and multi-accelerator configurations.
Accelerating Gravitational N-Body Simulations on Tenstorrent Wormhole
communityAccelerates an astrophysical N-body simulation on the Wormhole n300. Achieves 2× speedup and 2× energy savings over a highly optimized CPU implementation. SC '25 Workshop.
Numerical Kernels on a Spatial Accelerator: Tenstorrent Wormhole
communityImplements three numerical kernels and composes them into a conjugate gradient solver on Wormhole. Demonstrates AI accelerators merit consideration for HPC workloads traditionally dominated by CPUs and GPUs. 2026.
Accelerating Stencils on the Tenstorrent Grayskull RISC-V Accelerator
communityExplores stencil computation on the Grayskull PCIe RISC-V accelerator. Early academic work examining TT hardware for HPC stencil workloads. 2024.
Stencil Computations on Tenstorrent Wormhole
communityMaps 2D 5-point stencil computations onto the Tenstorrent Wormhole RISC-V AI dataflow accelerator via two implementations: element-wise decomposition (Axpy) and matrix-multiplication reformulation (MatMul). Profiling shows the isolated Wormhole kernel is competitive with CPU execution, with PCIe transfers and initialization driving end-to-end overhead; Axpy achieves lower energy than the CPU baseline at large scales. Identifies architectural and software directions for making AI accelerators viable for HPC stencil workloads. 2025.
SwiftNPU: Scalable Shape-Flexible Allocation for Inter-Core Connected NPUs
communityMakes multi-tenant NPU sharing practical for Blackhole-class hardware using polynomial-time allocation algorithms. Delivers up to 1.37× higher utilization and 1.14× faster workload completion. Up to 890,000× faster than NP-hard baselines.
TileLoom: Automatic Dataflow Planning for Spatial Dataflow Accelerators
communityCompiler system that automatically generates efficient dataflow plans for tile-based languages on spatial accelerators including Tenstorrent Wormhole. Exploits on-chip network forwarding between processing elements to reduce DRAM pressure.
Rewriting TTS Inference Economics: Lightning V2 on Tenstorrent vs. NVIDIA L40S
communityShows that Text-to-Speech inference on Tenstorrent Lightning V2 achieves 4× lower cost than NVIDIA L40S. Applies BlockFloat8 (BFP8) and low-fidelity (LoFi) precision strategies to TTS despite their greater numerical fragility compared to LLMs.
Tenstorrent Blackhole Architecture Guide
community★ featuredA 6,500-word community deep dive into the Blackhole p100a architecture: the tile model (Tensix, DRAM, SiFive x280 L2CPU, Ethernet, PCIe, NoC arc), firmware startup sequence, MOP micro-op processor, replay buffer, FPU/SFPU sync, and the anatomy of a kernel. From the author of blackhole-py.
All in RISC-V, RISC-V All in AI — FOSDEM 2026
communityMartin Chang and Danfeng Zhang on solving real AI compute problems with open hardware, spanning AI PC / edge devices and AI servers: pairing high-performance RISC-V CPUs with NPUs, and Tenstorrent's RISC-V cores and scalable mesh for AI workloads. The speaker's companion write-up covers the Tensix programming model in depth — the five RISC-V cores per tile, Dst register double-buffering, and the macro-recording hardware that lets control cores run ahead of the math engine.
WebNN and WebLLM on RISC-V — FOSDEM 2026
communityYuning Liang and Petr Penzin on closing the AI acceleration gap in the browser on RISC-V: how WebNN and WebLLM can reach efficient on-device inference using the RVV 1.0 variable-length vector ISA and Tenstorrent hardware underneath.